What You Actually Need to Know
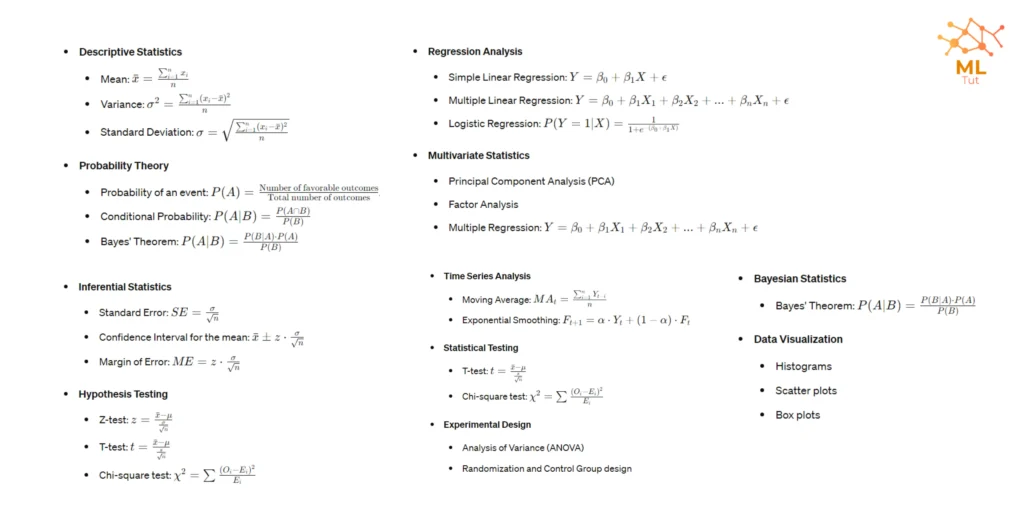
Most people asking this question are staring at a job posting that says "strong statistics background preferred" and wondering if they need to go back to university for another two years. The answer is more boring than either camp wants to admit. You need enough statistics to not embarrass yourself in front of an engineer who actually went to grad school, and enough machine learning to get things done. The ratio shifts depending on what kind of data science you're doing, and I've seen both extremes burn out equally fast. Let me give you a breakdown that isn't theoretical. Bayesian inference, probability theory, linear algebra fundamentals, and regression analysis — that's the core four. If you can derive the ordinary least squares estimator from first principles and explain to a product manager why their A/B test result isn't statistically significant after three days of running, you're already ahead of half the people calling themselves data scientists. Hypothesis testing shows up in literally every email chain at a real company. Confidence intervals, p-values, power analysis. The routine stuff that takes up 90 percent of actual work time. The deeper topics matter too, but less frequently. Time series decomposition, Markov chains, hierarchical modeling, causal inference with structural equation models. I once spent three weeks building a causal model to determine whether a pricing change actually moved demand or whether it was just seasonality doing the heavy lifting. Propensity score matching got me close, but the endline solution was a difference-in-differences approach with staggered adoption. The statistician on the team suggested it. I would not have figured that out from any online course.
Here's the thing nobody tells beginners: you don't need to memorize proofs. I've been doing this long enough to know that the people who memorized every derivation ended up struggling the most when reality didn't match the textbook assumptions. What you need is an intuitive grasp of what's happening under the hood. When does a t-test break down? Why does multicollinearity inflate your standard errors without changing your coefficients? When should you reach for a nonparametric test instead of just running whatever your default library gives you? Linear algebra is the quiet prerequisite that trips people up. Eigendecomposition, matrix factorization, the geometry behind PCA — it shows up everywhere once you start touching dimensionality reduction or regularization. Ridge regression is just a constrained least squares problem. LASSO introduces sparsity through an L1 penalty. Understanding what that means geometrically saves you from tuning hyperparameters by guessing. I've seen people waste months on grid search because they couldn't visualize what they were actually optimizing. Probability distributions deserve their own section because most people learn them in isolation and then forget them until something goes wrong in production. The normal distribution is a crutch. Real data is rarely normal. Poisson for counts. Binomial for conversions. Negative binomial when your overdispersion makes the Poisson look naive. Exponential and Weibull for survival analysis, which is just another name for time-to-event modeling that pops up in churn prediction and hardware failure. Knowing which distribution to fit to your data rather than just defaulting to Gaussian is what separates people who ship models from people who ship excuses.
Machine learning sits on top of all of this, and the overlap between statistics and ML is where the confusion lives. Regularization is just Bayesian priors with a different name. Gradient boosting is an ensemble method grounded in bias-variance tradeoffs. Neural networks are function approximators that happen to benefit from the same regularization principles statisticians developed decades ago. The separation is mostly historical and marketing-driven now. Causal inference is the frontier right now. Most data science work is correlational, which is fine for recommendation engines and fraud detection. But the moment someone asks "did our intervention cause the outcome," you're in causal land. Potential outcomes framework, instrumental variables, regression discontinuity designs. These aren't academic curiosities. They're what you use when the VP of Product wants to know whether the new onboarding flow actually improved retention instead of just riding a holiday traffic wave. I learned this the hard way after a colleague confidently presented a 23 percent lift from a feature rollout that turned out to be entirely explained by a concurrent marketing campaign targeting the same cohort. Software-wise, you should be comfortable with R and Python. R is still the better choice for pure statistical work — its model formula language and ecosystem for experimental design are unmatched. Python wins on production deployment and engineering integration. The best practitioners are bilingual. SQL is not optional. You will spend more time pulling data than analyzing it, and if you can't write a decent query, you're bottlenecked at step one.
Get the Full Details
Here's what I wish someone had told me earlier: statistics is a tool, not an identity. The people who get far are the ones who learn to ask the right questions and pick the right tool for the job, not the ones who try to force every problem through the most sophisticated method they've read about. A well-executed logistic regression beats a poorly tuned gradient boosting machine every single time. Simple models generalize better. They're easier to explain to stakeholders who don't have a statistics background. They fail more gracefully when assumptions are violated. The threshold for getting hired is lower than most tutorials make it seem. A solid undergrad statistics sequence covering probability, regression, and hypothesis testing plus hands-on project experience is enough for most entry-level roles. The people who struggle aren't the ones who took too few stats classes — they're the ones who can talk about techniques but can't execute them on messy real-world data. A project where you cleaned a broken dataset, dealt with missing values properly instead of just dropping rows, and validated your model against a holdout set is worth more than another certificate. The areas where statistics matters most are decision-heavy environments: healthcare, finance, experimentation-driven product teams. In those spaces, a wrong conclusion has real consequences and someone needs to understand the uncertainty. On the other end, if you're doing computer vision or NLP at scale, the statistical depth you need is shallower because the problems are different. You're managing high-dimensional pattern recognition, not inferring treatment effects from observational data.
Keep your skills current. The field moves fast enough that what you learned three years ago may already be stale. Read papers when you can. Follow people who actually publish results, not just tutorials. And when someone tells you their model achieved 97 percent accuracy, ask them what the baseline was and whether the class distribution was balanced. That question alone will save you from a lot of bad decisions.


