The reality of using Python for data work
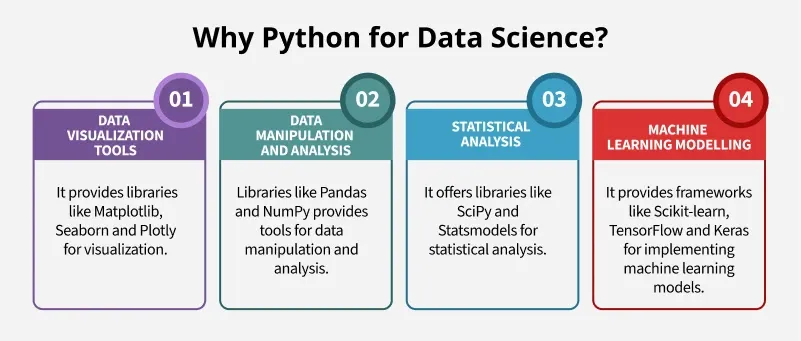
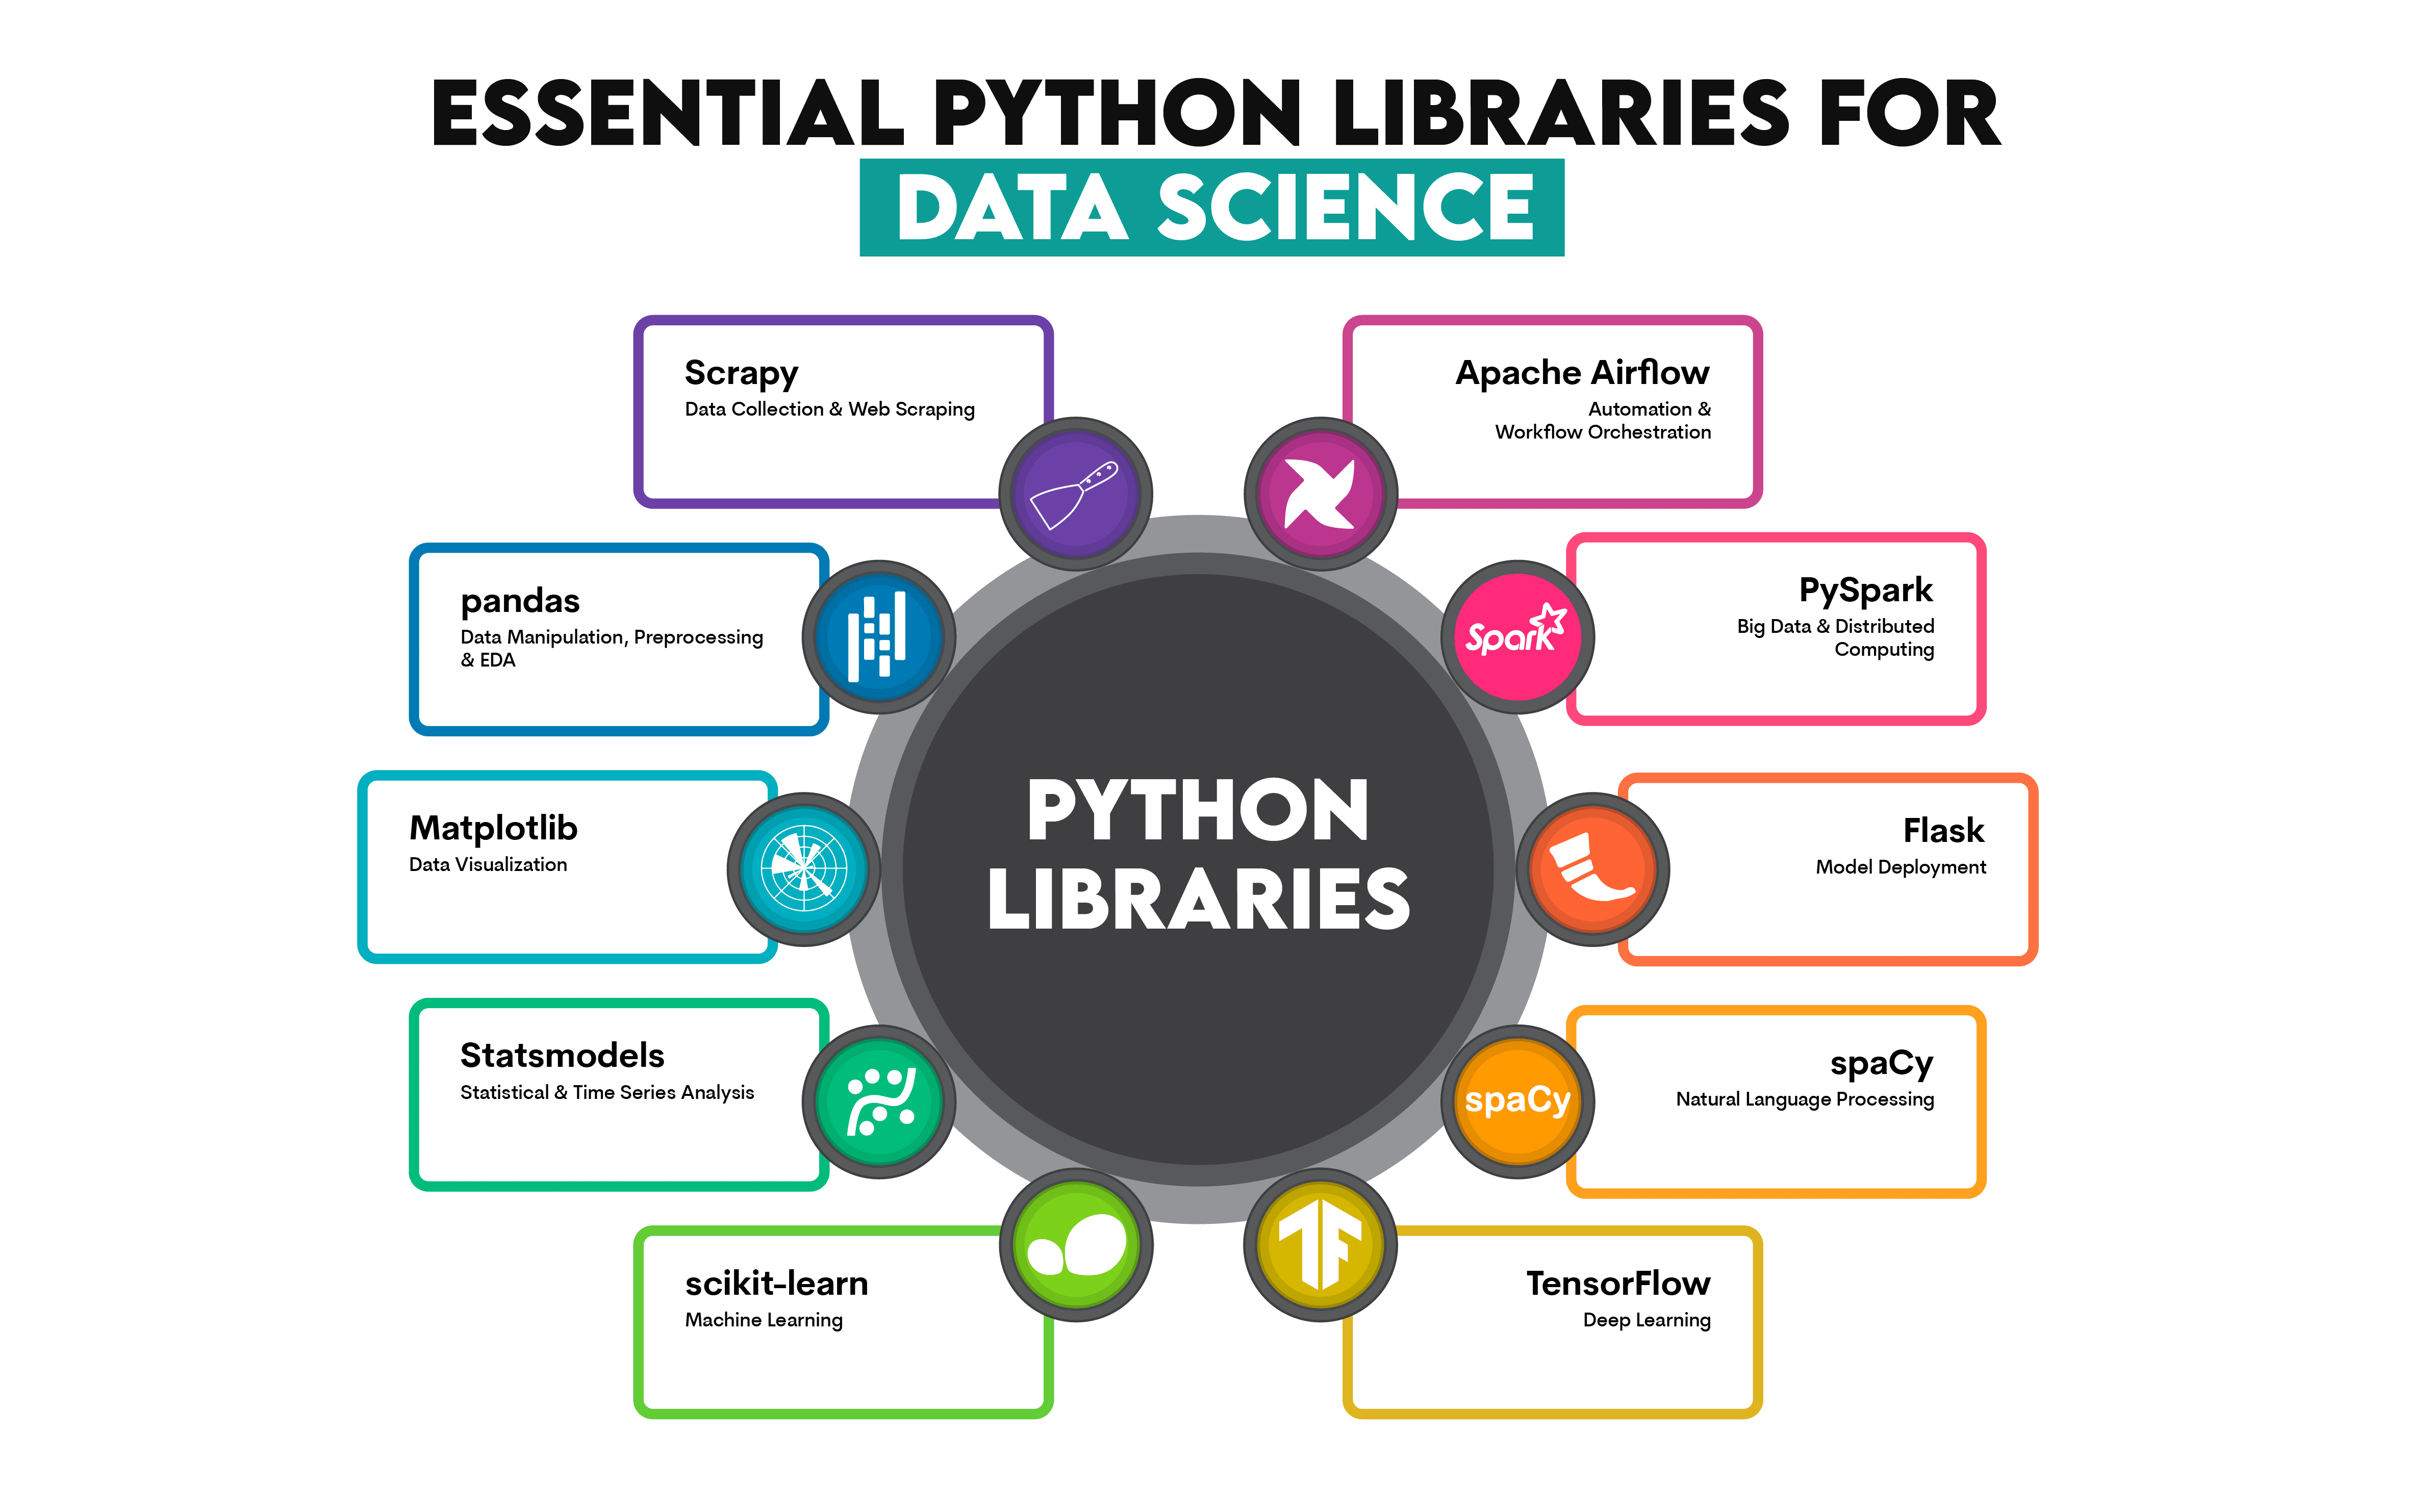
Python shows up everywhere in data science because the ecosystem around it is simply larger than any other language's. When you open a project, you're not just writing Python code — you're assembling a chain of libraries that handle everything from reading messy CSVs to deploying models into production. The work usually looks like pulling data from a database, cleaning it, training something, and then figuring out why the predictions are wrong. Most people skip the cleaning part in tutorials and move straight to the model, which is why beginners always get surprised when real data refuses to cooperate. At its core, Python in data science means combining a few specific libraries for different stages of a pipeline. You load data with pandas or polars, do numerical work with NumPy, build and evaluate models with scikit-learn or PyTorch, and visualize results with matplotlib or seaborn. That stack covers roughly 80 percent of what a data scientist touches on a daily basis. The remaining 20 percent involves Spark for distributed processing, SQL for data extraction, and sometimes some custom Python scripting to glue everything together. I once spent three days debugging a pipeline where a datetime column was parsed differently depending on whether it came from a SQLite query or a CSV file. One source returned strings in YYYY-MM-DD format and the other returned them as proper datetime objects. When I fed them into the same pandas merge, the comparison silently failed because the types didn't match. The fix was to run pd.to_datetime() on both columns immediately after loading them, before any merging happened. I haven't trusted automatic type inference since.
The most common pitfall people hit is assuming that more complex models always perform better. They don't. A well-tuned logistic regression or a gradient boosted tree often beats a randomly configured neural network on tabular data. I had a client who replaced a XGBoost model with a deep learning approach because it looked better on a dashboard. The accuracy dropped by four percentage points and the inference time went from 12 milliseconds to 340 milliseconds per prediction. We switched back to XGBoost within a week.
The practical workflow most people actually use
A typical project starts with data exploration, not modeling. You load the dataset into a pandas DataFrame and spend the first hour or two just looking at shapes, missing values, duplicates, and basic distributions. This step is not optional. I've seen teams skip it and build models on data where a column labeled "age" contained values like "unknown" and "-5." The model learned patterns from garbage and the stakeholders got confident about bad results. After exploration comes feature engineering. This is where you transform raw columns into inputs the model can use. Encoding categorical variables, scaling numerical features, creating interaction terms, and handling outliers all happen here. Scikit-learn's ColumnTransformer and Pipeline classes are useful because they let you define the entire preprocessing chain and apply it consistently to both training and test sets. Without them, you end up leaking information from the test set into your training data through scaling or encoding, which invalidates your evaluation. When it comes to modeling, the choice depends on the problem type. Classification tasks use algorithms like random forests, gradient boosting, or logistic regression. Regression tasks use similar families with different loss functions. Time series work requires specialized tools like statsmodels or prophet. Deep learning frameworks like PyTorch and TensorFlow become relevant when you're working with images, text, or very large datasets where traditional methods plateau.
Get the Full Details
One thing beginners consistently miss is proper train-test splitting. A random split works for most independent and identically distributed data, but it breaks completely for time-dependent data. If you're predicting sales and your training set includes data from December while your test set only has January data, the model might be learning seasonal patterns that won't generalize. Use TimeSeriesSplit from scikit-learn instead, or manually split by date to preserve the temporal order.
Deployment and the part nobody talks about
Getting a model to predict accurately is only half the job. The other half is making sure it runs reliably in an environment where someone actually uses it. Many data scientists build models in Jupyter notebooks and then struggle to move them into production because notebooks aren't designed for that. They contain hidden state, mixed concerns, and results that depend on the specific session they were run in. The workaround is to wrap your code in functions and modules from the start. Save your preprocessing logic in one file, your model training in another, and your inference pipeline in a third. Use joblib or pickle to serialize your trained model and load it at inference time. For web APIs, FastAPI is faster to set up than Flask and handles input validation with Pydantic automatically. A simple endpoint that takes JSON input and returns predictions can be built in under 30 lines. There are also scenarios where Python data science simply doesn't make sense. If you're processing billions of rows and need sub-second query times, you're better off using ClickHouse or DuckDB and calling them from Python rather than trying to load everything into memory with pandas. Pandas loads data into RAM and holds it there, which means your analysis is bounded by available memory. For datasets larger than what fits comfortably in RAM, consider polars, which uses a lazy execution engine and can handle much larger data without exhausting your machine. I switched a colleague's project from pandas to polars and reduced an 18-minute query to about 40 seconds on the same hardware.
Another hard limit is real-time systems requiring microsecond latency. Python's global interpreter lock and garbage collection pauses make it unsuitable for anything where response time needs to be consistently under a millisecond. In those cases, teams typically keep the model in Python during development and then rewrite the inference layer in Rust or C++ using tools like TorchScript or ONNX.
What actually moves a project forward
The libraries matter less than the habits around them. Version control your data transformations, not just your code. Pin your dependencies in a requirements.txt or pyproject.toml file and use virtual environments. Reproducibility is the difference between a model that works on your machine and one that works for everyone else too. Logging is equally important — I recommend MLflow for tracking experiments because it lets you compare model versions, hyperparameters, and metrics across runs without keeping a spreadsheet of results. Documentation doesn't need to be exhaustive. A short README explaining how to set up the environment, run the training script, and load a model for inference is enough for most internal projects. The moment you stop maintaining that README is the moment someone else will spend four hours figuring out why the script fails on their machine. Python dominates data science not because it's the fastest language or the most elegant one, but because it sits at the intersection of accessibility and capability. You can prototype an idea in a notebook in the morning and have a production-ready pipeline by Friday if you structure your code properly. The tradeoff is that the same flexibility means the project can easily spiral into unmanaged complexity if you don't impose some discipline early on.