Getting Your Data Plotted
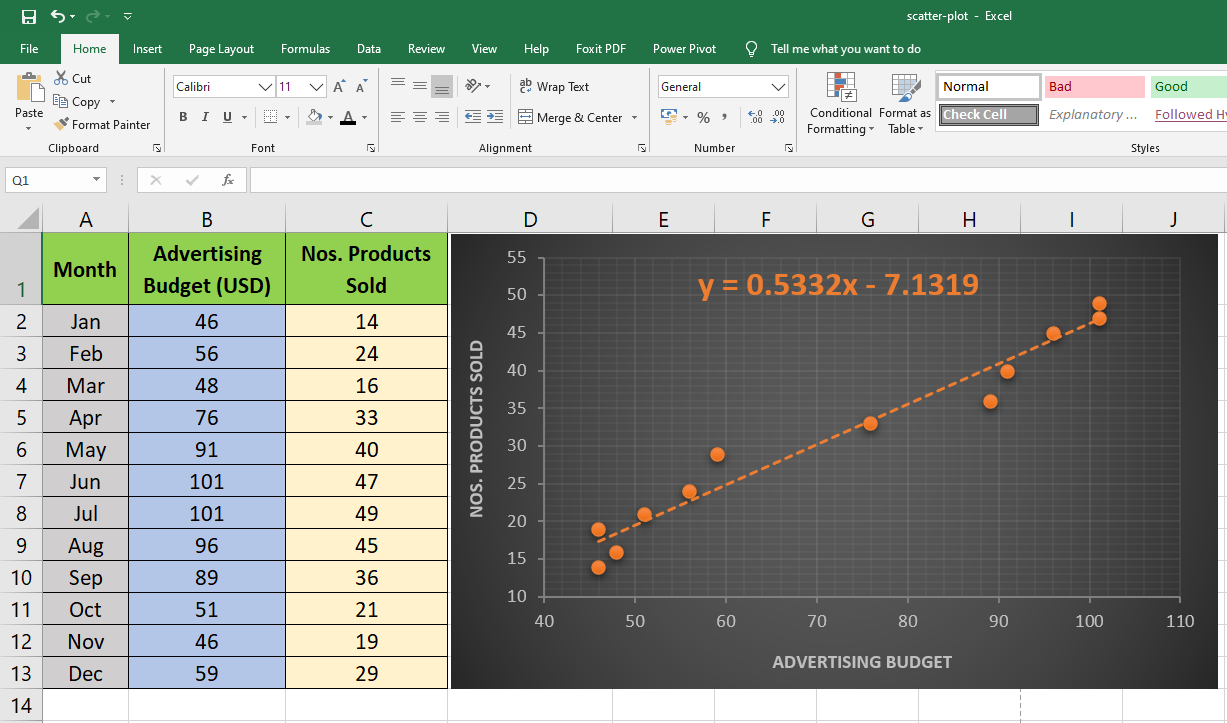
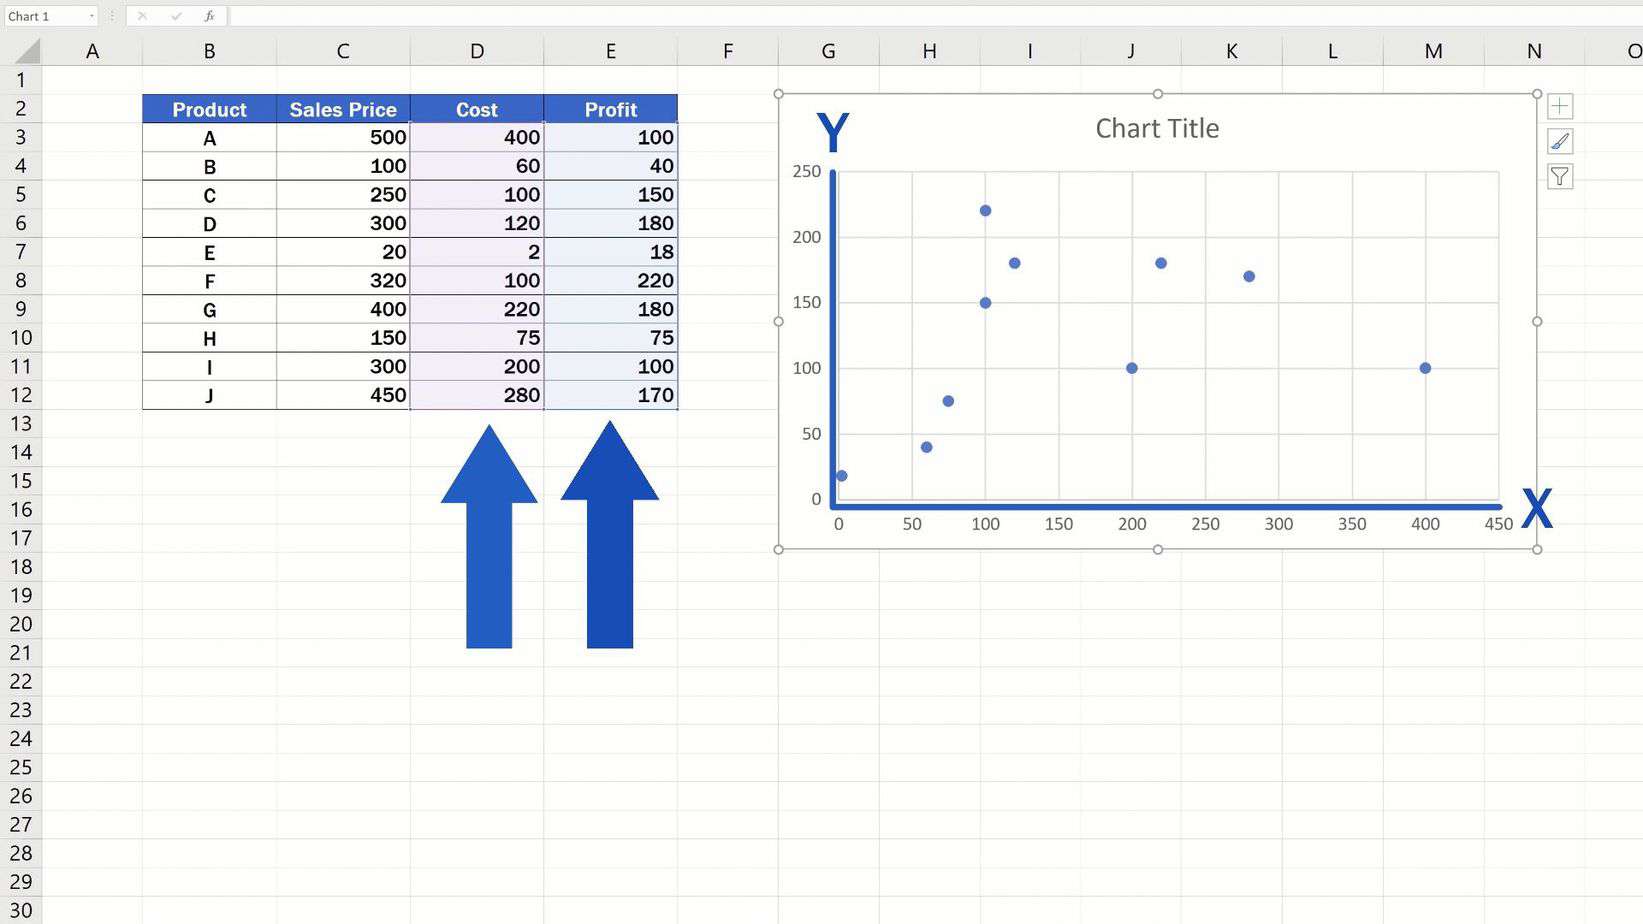
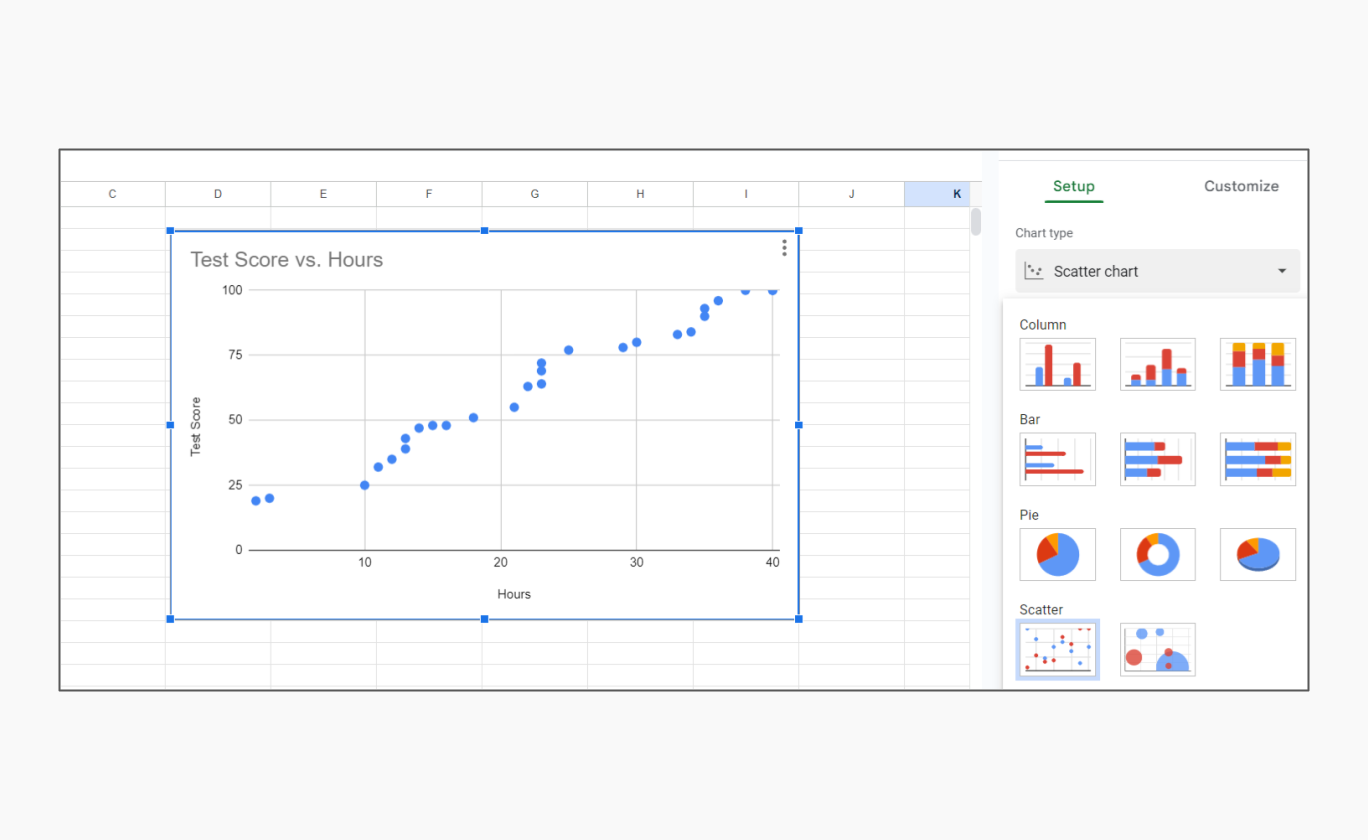
A scatter plot is just two quantitative variables placed on perpendicular axes, with each observation becoming a single point. Most people overcomplicate it because they focus on making it look pretty before making it legible. Start with the axis choice. If your x-axis runs from 0 to 1 and your y-axis runs from 0 to 10,000, you're going to drown most of your data near the bottom of the chart. I spent three hours once trying to debug what I thought was a data entry error, only to realize the y-axis was on a log scale and I hadn't noticed because the tick labels were cramped. The basic workflow in any tool, whether you're using Python with matplotlib, R with ggplot2, or Excel, follows the same pattern. You need a dataframe or worksheet with two columns of numerical data. You map one column to the x-axis and the other to the y-axis. You render the points. The hard part starts after that.
How To Build A Scatter Plot
Here is the practical code path I use when starting from scratch. This is Python, because it's what most people in my network actually use, but the logic transfers directly. Step one: load and inspect your data. import pandas as pd
import matplotlib.pyplot as plt
df = pd.read_csv("your_data.csv")
print(df[["variable_x", "variable_y"]].describe())
Check the describe output before you plot anything. If variable_x has a standard deviation of 0.001 while variable_y has a standard deviation of 500, you already know your points are going to collapse into a vertical line and you need to rethink the visualization or rescale the variables. Step two: render the plot. fig, ax = plt.subplots(figsize=(8, 6))
ax.scatter(df["variable_x"], df["variable_y"], alpha=0.6, s=20)
ax.set_xlabel("Variable X")
ax.set_ylabel("Variable Y")
ax.grid(True, linestyle="--", alpha=0.4)
plt.show()
Get the Full Details

The alpha parameter controls transparency. The s parameter controls point size in points squared. These two settings matter far more than people give them credit for. A scatter plot with 5,000 points and default settings looks like a solid blob. Alpha at 0.4 and s at 15 usually gets you readable overlap without turning the chart into an impressionist painting. Step three: add a trend line if it's meaningful. from scipy import stats
slope, intercept, r_value, p_value, std_err = stats.linregress(df["variable_x"], df["variable_y"])
ax.plot(df["variable_x"], intercept + slope * df["variable_x"], "r--", alpha=0.7)
I include the r-value calculation here because writing it out forces you to actually check whether the linear fit is reasonable. I've seen analysts slap a regression line onto a U-shaped relationship and present it as evidence of a strong positive correlation. The r-squared was 0.03. The relationship wasn't linear, it was quadratic, and the trend line was actively misleading the audience.
What Nobody Tells You About Overplotting
When you cross a few thousand points, the traditional scatter plot breaks down. Transparency helps but it has limits. Dark patches form where dozens of points stack on top of each other, and your eye reads those dark patches as higher density even though the darkness is just an artifact of alpha compositing, not actual data concentration. The workaround I reach for is 2D binning with a hexbin or kde contour overlay. In matplotlib, this looks like: ax.hexbin(df["variable_x"], df["variable_y"], gridsize=30, cmap="viridis", mincnt=1)
ax.set_xlabel("Variable X")
ax.set_ylabel("Variable Y")
plt.colorbar(label="Count per bin")
This collapses overlapping points into color-coded regions. Each hexagon represents a count. The color scale tells you where the density lives. It takes about 30 seconds to code and 2 minutes to explain to someone who hasn't seen it, but it prevents the chart from becoming unusable once you pass roughly 3,000 points. I hit this wall with a logistics dataset where I was plotting delivery distance against delivery time. The raw scatter had about 12,000 points and looked like a solid gray triangle. Hexbin turned it into something you could actually read. The outlier cluster at long distances with unexpectedly short times became visible, which led me to find a data pipeline bug where a subset of deliveries was being logged with the wrong timestamp column. The plot didn't just visualize the data. It caught the error.
Correlation Is Not What You Think It Is
People treat scatter plots as correlation detectors. They're not. A scatter plot shows the joint distribution of two variables. Correlation is a single number computed from that distribution, and it can be completely wrong depending on how you slice the data. The classic trap is aggregating across groups. I once had a dataset showing the relationship between employee training hours and productivity scores across five departments. The overall scatter plot showed a weak negative correlation. When I colored the points by department, three departments had strong positive relationships, one was flat, and one was negative. The aggregate line was a statistical artifact of the departments having different mean levels on both axes. This is Simpson's paradox and it shows up in scatter plots constantly. The fix is straightforward but requires discipline. Always check whether your data has natural grouping variables. Add color or shape encoding for those groups. If you don't have grouping variables, at least report the correlation coefficient alongside the plot instead of letting viewers infer it from the visual pattern alone.
Common Pitfalls That Waste Time
Using a categorical variable on a numerical axis. I see this in dashboards all the time. Someone maps a string column like "Q1", "Q2", "Q3", "Q4" directly to a numerical axis and wonders why the points are evenly spaced but the distances mean nothing. If your x or y values are categorical, use a bar chart or a grouped box plot instead. Scatter plots require interval or ratio data on both axes. Truncating an axis without labeling it clearly. Starting the y-axis at 50 instead of 0 can make a tiny difference look dramatic. This isn't always wrong. Sometimes you genuinely want to zoom in on a narrow range. But if you truncate, put a break symbol on the axis or state the range explicitly in the label. I've lost count of the number of slides where the axis went from 98 to 100 and the presenter claimed a 200 percent improvement. The baseline was just compressed. Plotting time series as a scatter. A line chart exists for a reason. If your x-axis is sequential time and you're connecting nothing, you're hiding the temporal structure. Use a line or area chart unless you have a specific reason to treat the points as independent observations, like when you're comparing discrete events rather than a continuous process.

When a Scatter Plot Is The Wrong Choice
If you have more than about 50,000 observations, even hexbin starts to look muddy. At that scale, a 2D histogram on a finer grid or a small multiple faceted by a third variable works better. If one of your variables is not quantitative, switch to a different chart type entirely. Scatter plots are not a universal default. They work when you have two numerical variables and you want to see the joint distribution, the presence or absence of a relationship, and any clustering or outliers. If any of those objectives don't apply, pick something else. The tooling around scatter plots has improved significantly in the last few years. Plotly and Bokeh let you build interactive versions where hovering over a point reveals the underlying row data. This is worth the extra setup time if your audience needs to inspect individual observations. A static PNG still loses information the moment you exceed a few hundred points. An interactive version with tooltips usually pays for itself after the first review cycle. I still default to matplotlib for quick analysis and Plotly for deliverables. The code overhead is slightly higher but the interactivity prevents five rounds of clarification emails. Building the chart takes about the same amount of time either way once you have a template. The template cost is real though. If you're writing scatter plots from scratch for every project, you're wasting time. Copy a working template, adjust the data mapping, and move on.