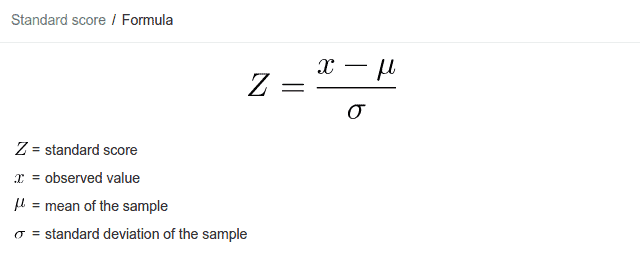Standard Scores and Why They Annoy Everyone
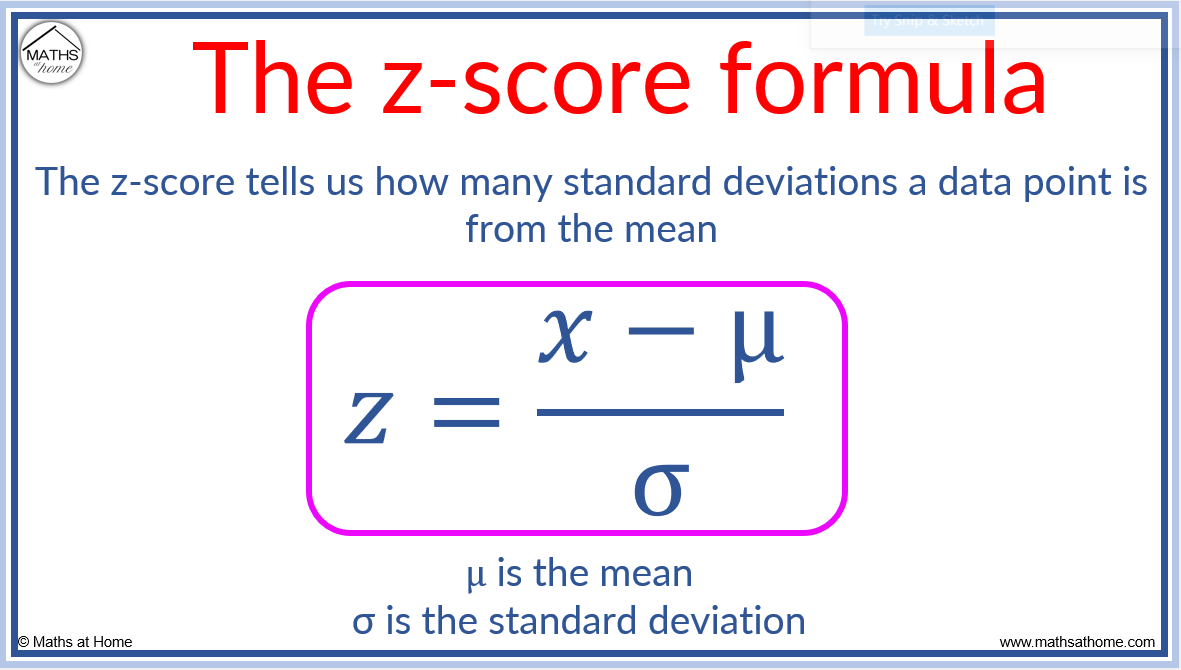
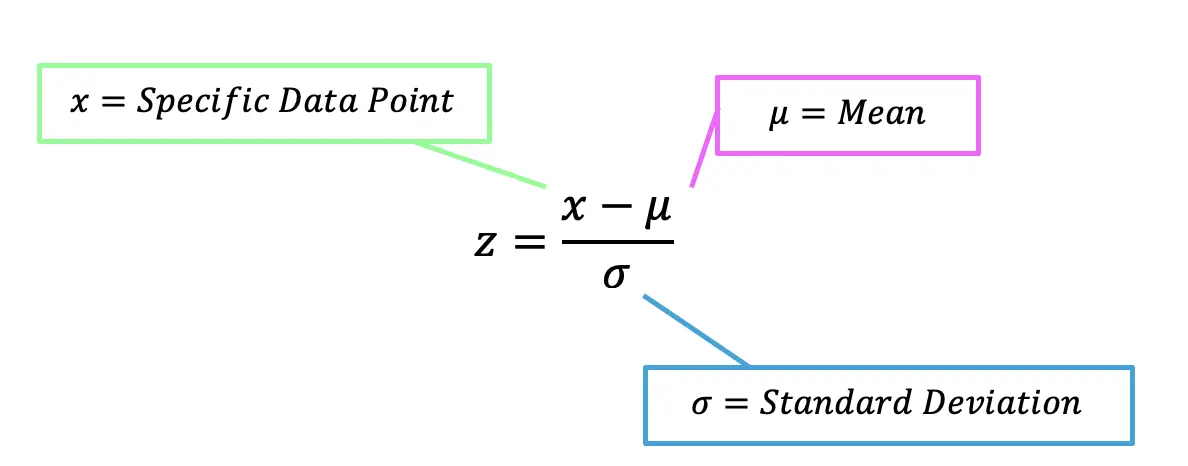
A z-score tells you how many standard deviations a data point sits from the mean. That is the textbook definition. In practice, people use them for outlier detection, standardized test scoring, and quality control. I have spent years cleaning datasets where someone tried to force z-scores onto data that clearly did not want them. The basic formula is straightforward. Subtract the mean from your value, then divide by the standard deviation. x minus , divided by . Nothing complicated there. But the complications start almost immediately after you calculate it.
How To Calculate A Z Score
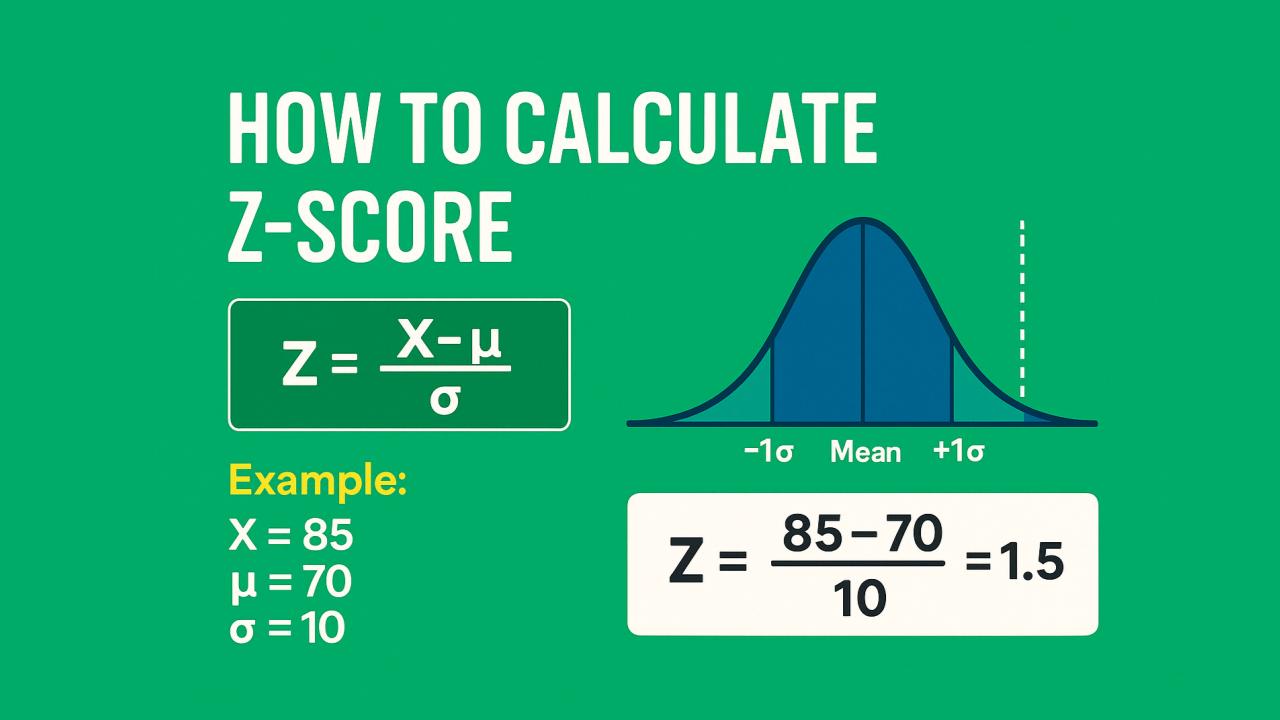
Here is the actual process. Take your dataset. Calculate the mean. Calculate the standard deviation using the population formula or the sample formula, depending on whether you have the entire population or just a sample. Then for each individual data point, subtract the mean and divide by the standard deviation. The result is your z-score. I used to do this by hand for small datasets. Then I started running into issues with large production datasets where the variance was sky-high because of a handful of extreme values. One specific project had customer transaction amounts where a few whales dragged the standard deviation up to something absurd. The z-scores for normal transactions came out as tiny decimals like 0.03 and 0.07. Meaningless for anything except knowing those values were roughly average. The workaround was to use the median and the median absolute deviation instead. Or apply a log transform first, then calculate z-scores on the transformed data. That usually stabilizes things enough to get scores you can actually interpret.
The formula itself looks like this: Z = (X - ) / Where X is your raw score, is the population mean, and is the population standard deviation. If you are working with a sample rather than a population, you use the sample mean and sample standard deviation. The formula does not change, but the interpretation of the result shifts slightly because you are estimating parameters rather than knowing them exactly.
Get the Full Details
Common Pitfalls That Waste Afternoon
The most common mistake I see is using z-scores on non-normal data without any transformation. A z-score assumes a roughly normal distribution for the standard interpretation to hold. If your data is heavily skewed, the z-score still exists mathematically. It just does not mean what people think it means. Another thing that catches people out is forgetting which standard deviation to use. The sample standard deviation divides by n minus one. The population standard deviation divides by n. Using the wrong one when you know you have the full population will introduce a small but unnecessary bias into your scores. I once had a situation where someone reported a z-score of negative 3.2 and claimed it was an extreme outlier. The dataset had been cleaned of actual outliers already. The remaining distribution was just wide and noisy. A z-score of negative 3.2 in a small sample from a non-normal distribution is not necessarily alarming. It might just be the tail of a distribution that never looked normal to begin with.
What the Numbers Actually Mean
A z-score of zero means the value equals the mean. A z-score of positive 1.5 means the value is one and a half standard deviations above the mean. A z-score of negative 2 means it is two standard deviations below the mean. Under a normal distribution, about sixty-eight percent of values fall within one standard deviation of the mean. About ninety-five percent fall within two standard deviations. About ninety-nine point seven percent fall within three standard deviations. These are the empirical rule numbers. They only apply when the data is actually normal or close to it. For non-normal distributions, Chebyshev's inequality gives you a floor. At least seventy-five percent of values fall within two standard deviations regardless of shape. At least eighty-eight point nine percent fall within three standard deviations. These bounds are much looser. They are correct for any distribution though, which is why they matter when you are working with messy real data.
When Z-Scores Break Down
Z-scores are not useful when your standard deviation is zero. This happens when every value in the dataset is identical. You cannot divide by zero. The calculation fails entirely. I have seen this in production when a feature had no variation because of a data collection bug. The feature recorded the same value for every row. Flagging that early saves a lot of debugging time later. They also become unreliable with very small sample sizes. A sample of five values can produce z-scores that look dramatic but are statistically meaningless. The sampling distribution of the mean does not stabilize until you have enough data. For rough screening purposes you can still compute them. For any formal inference, you need larger samples or a different approach entirely. Extreme skew is another hard limitation. Income data, web traffic counts, and response times often have long right tails. Z-scores on raw income data will label most people as near zero and the top one percent as extreme outliers. That is technically correct but not especially useful for segmentation or modeling. A log transform before calculating z-scores usually produces something more tractable.
Alternative Approaches
If z-scores are giving you trouble, consider the interquartile range method. Values outside one and a half times the IQR from the first or third quartile are flagged as outliers. This is more robust to skew and extreme values because it uses quartiles instead of mean and standard deviation. You can also use modified z-scores, which replace the mean and standard deviation with the median and median absolute deviation. This handles skew much better and is what I default to these days unless I have a clear reason to use the classical version. For time series data, rolling z-scores are often more appropriate than global ones. A value might look normal compared to the overall distribution but highly unusual compared to recent history. Computing the z-score against a rolling window captures that context. The choice of window length matters. Sixty to two hundred periods is typical for daily data. Longer windows smooth out short-term fluctuations but may miss genuine regime changes.
Quick Reference
Compute the mean and standard deviation of your dataset. Subtract the mean from each value. Divide each result by the standard deviation. Check whether your data is approximately normal before interpreting the scores using the empirical rule. If it is not, use Chebyshev's bounds or switch to a more robust method like the IQR approach or modified z-scores. Handle zero variance cases before they reach your analysis pipeline.