Calculating Allele Frequency in Population Genetics
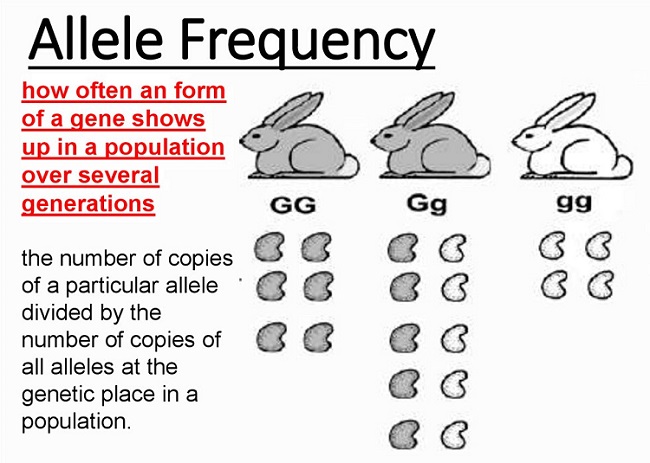
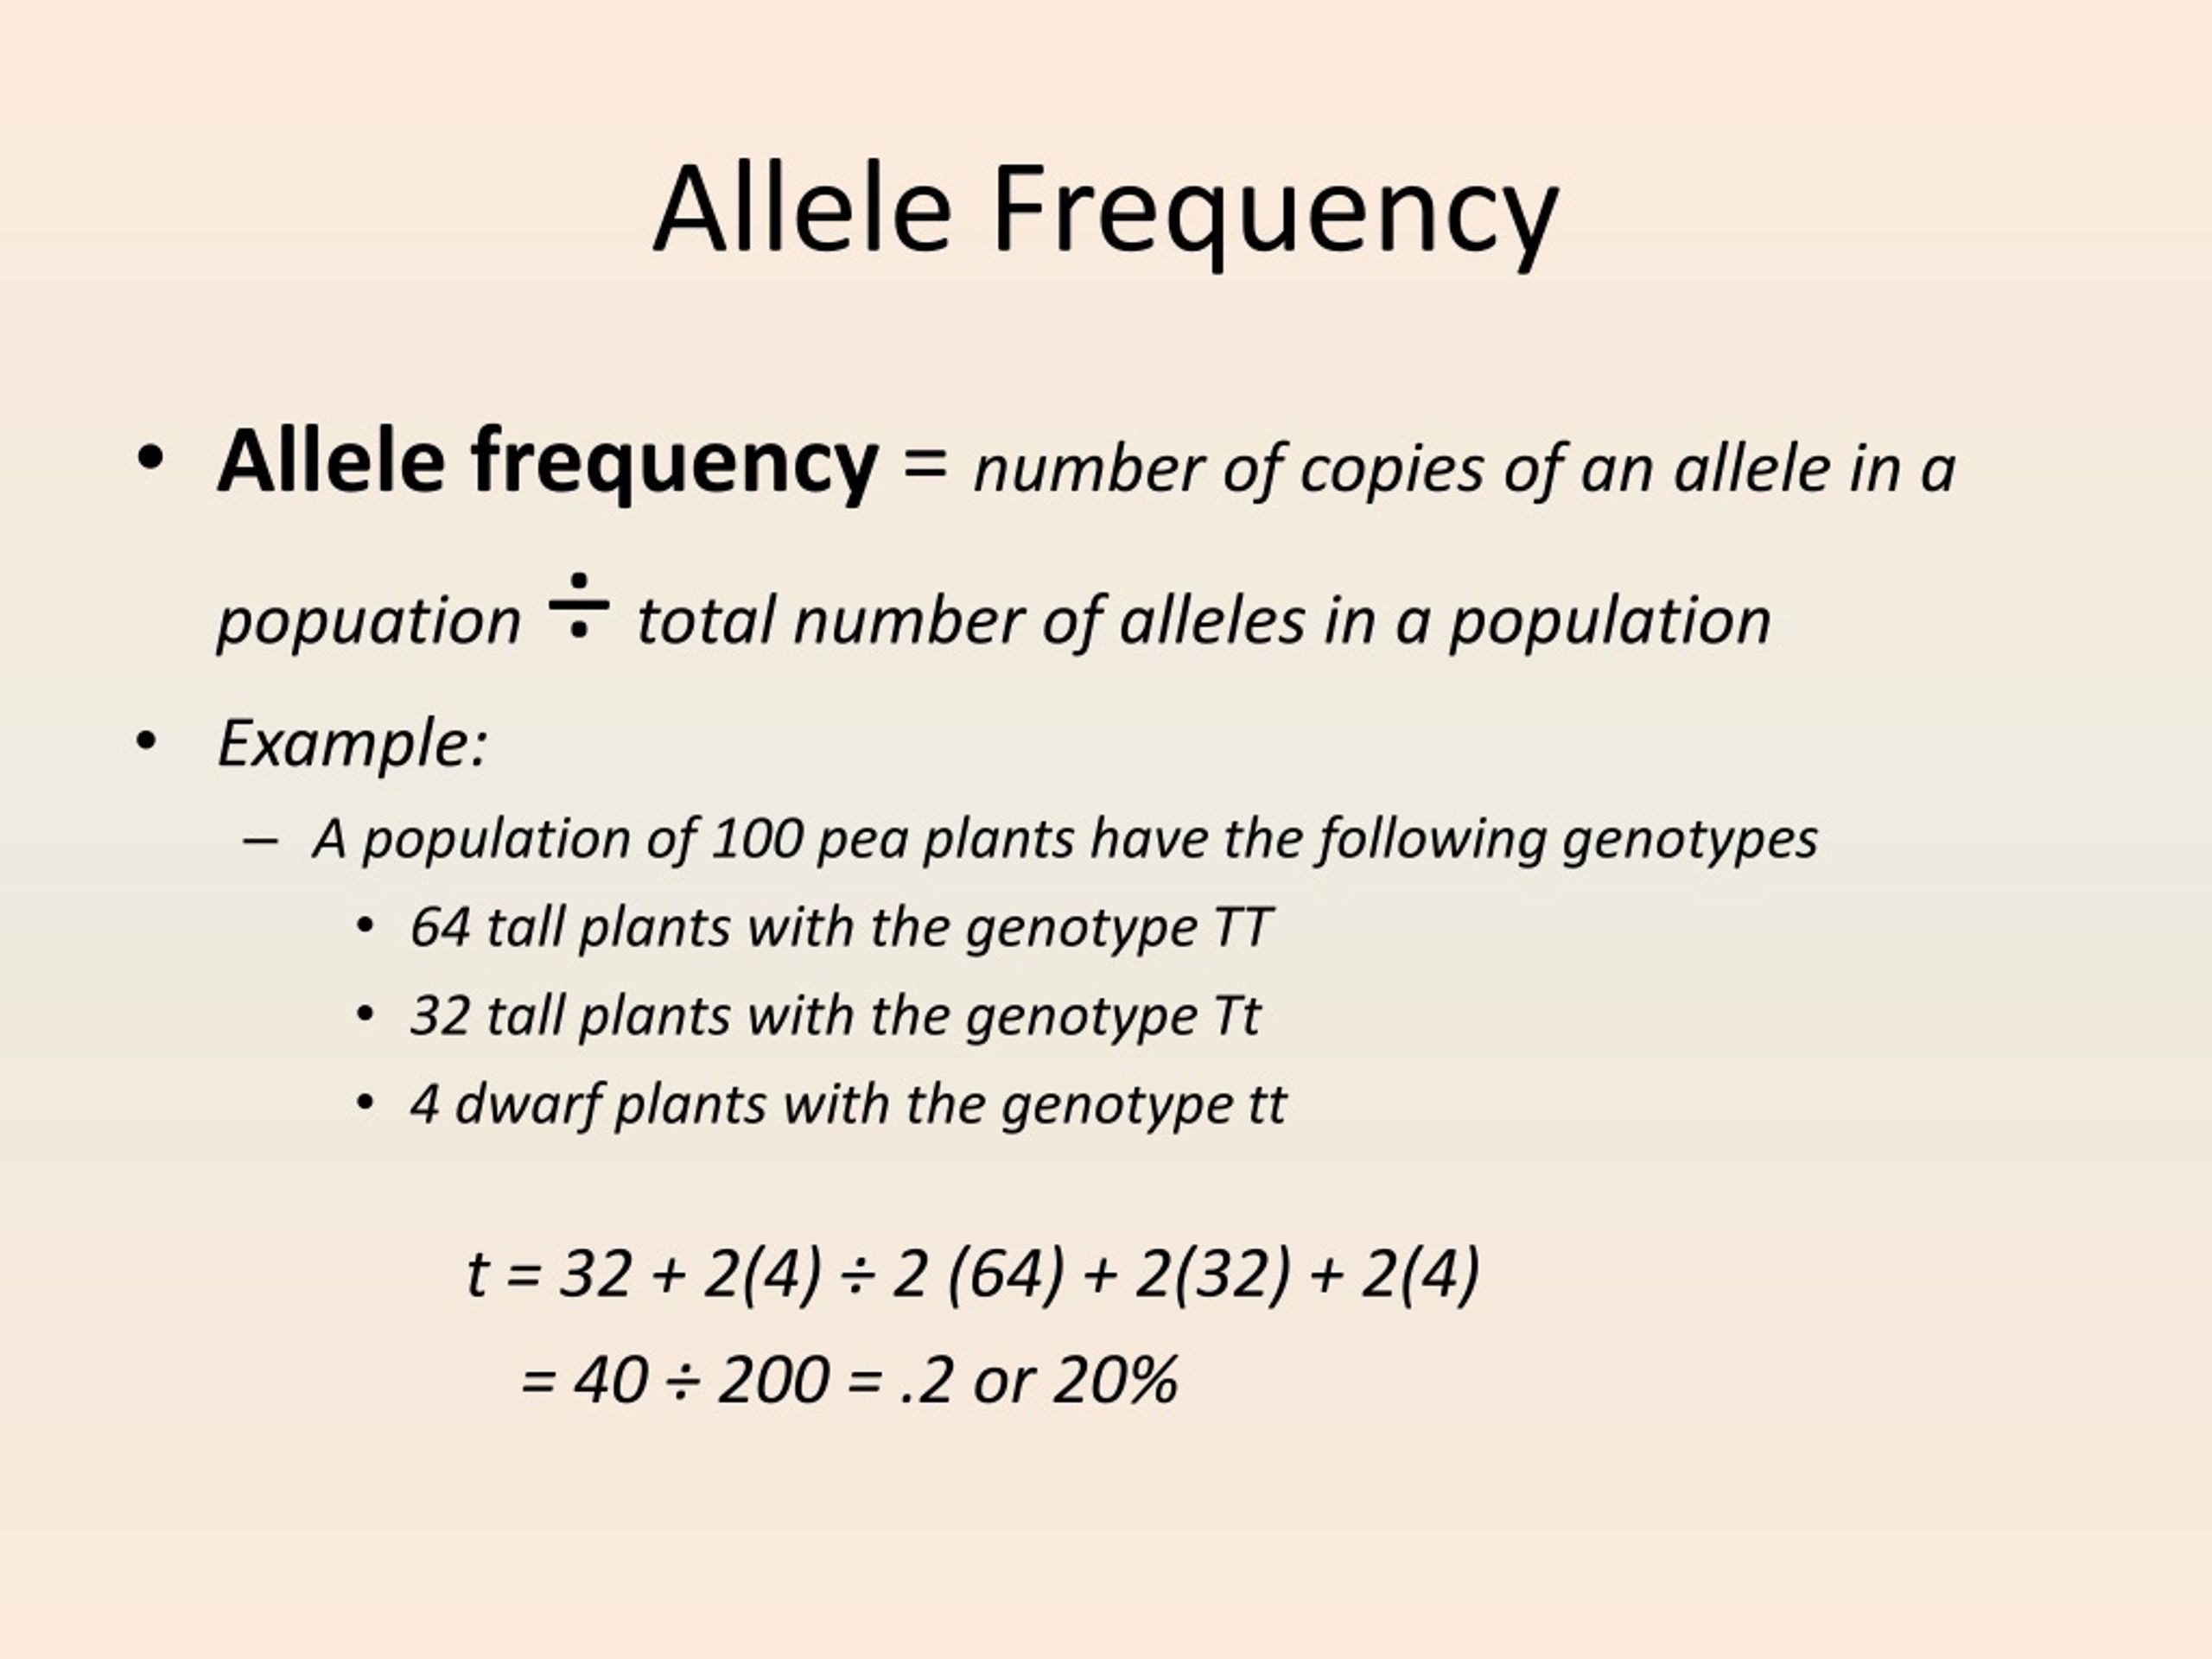
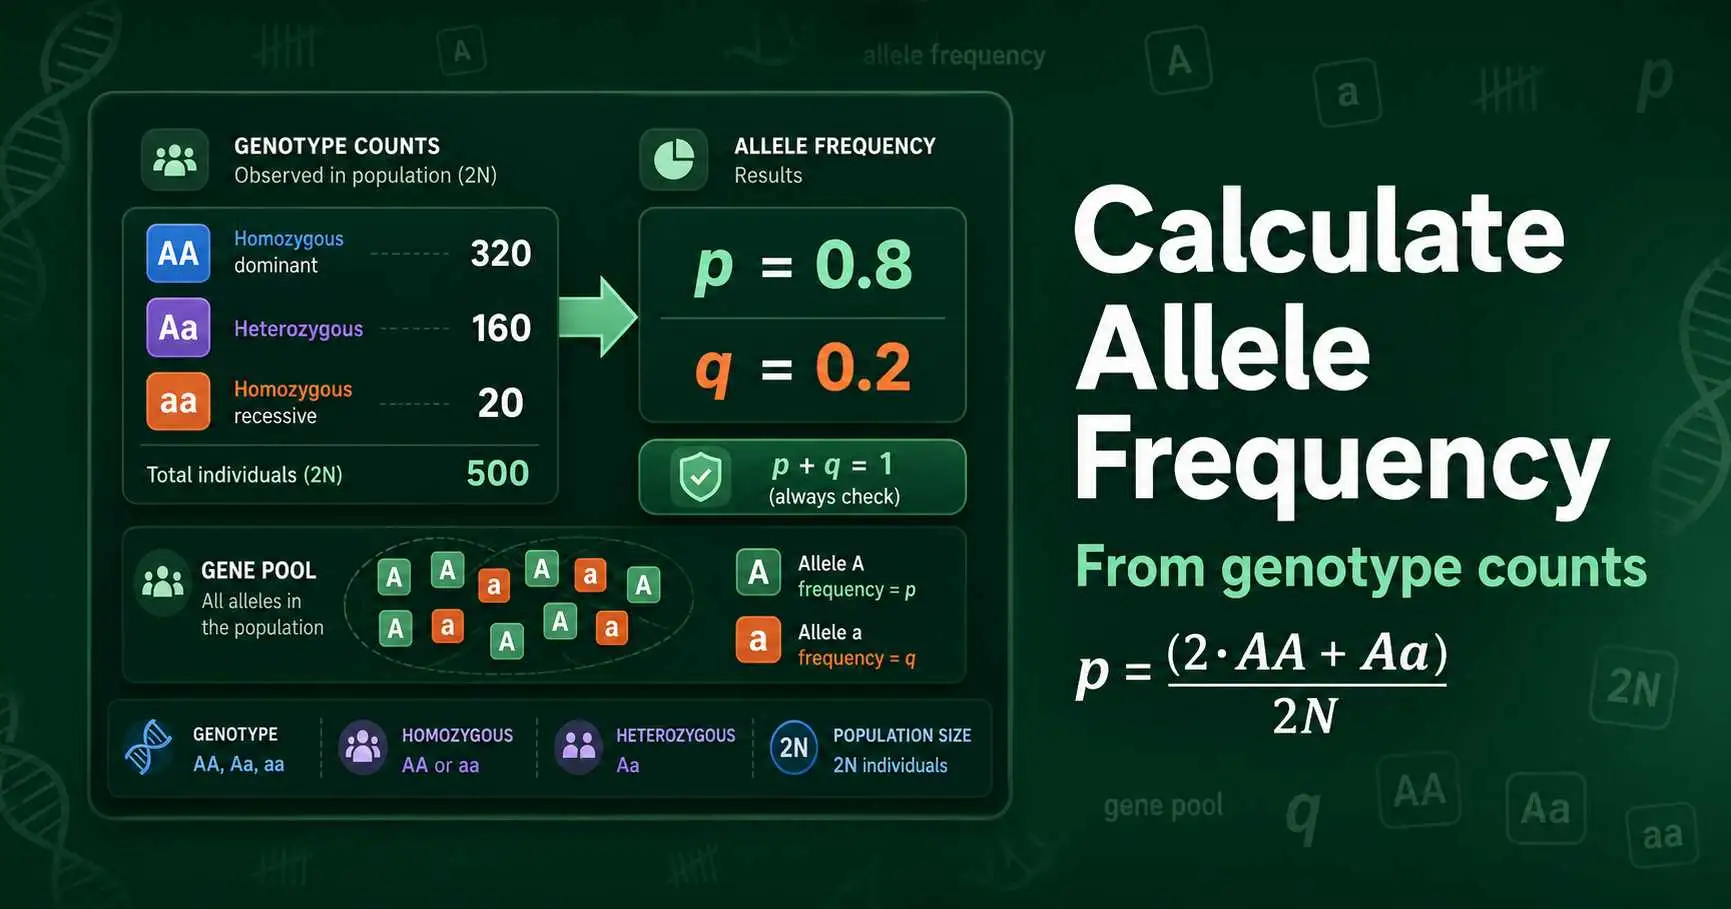
Most people learning population genetics hit a wall when they're told to calculate allele frequency because they try to memorize the formula instead of understanding what it actually means. The whole thing is simpler than textbooks make it look, but there are enough edge cases that trip people up that you'll probably need this as a reference more than once. Start with what you actually have: a sample of individuals and their genotypes at a specific locus. Let's say you're looking at a gene with two alleles, A and a. You count every individual in your sample, then count how many copies of each allele exist across all those individuals. That's it. The formula p = (2 × N_AA + N_Aa) / (2 × N_total) for the dominant allele and q = (2 × N_aa + N_Aa) / (2 × N_total) for the recessive one follows directly from counting chromosomes, not from any abstract rule. I remember running into this with a dataset of about 340 stickleback fish where the lab had mislabeled a bunch of samples. When I calculated the allele frequencies, q came out to something like 0.03, which meant Hardy-Weinberg equilibrium should give a homozygous recessive frequency of roughly 0.0009 — about one in eleven hundred. But the raw count showed zero affected individuals in the sample. That discrepancy meant either the sample was too small to detect the allele in homozygotes, or something was wrong with the genotyping. We spent two days re-running the PCR and turns out the water bath had drifted three degrees Celsius on the second plate. Lesson: always sanity-check your numbers against what you'd actually expect to see in the data before you move on.
The key insight that most intro courses skip is that allele frequency is just a proportion of gene copies in a pool. It has nothing to do with dominance or recessiveness in terms of the calculation itself. Whether A is dominant or not doesn't change how you count it. The only time that matters is when you're working with phenotypic data instead of genotypic data, which is where things get messy.
When You Only Have Phenotype Data
This is where most people get stuck and start making mistakes. If you can't directly observe genotypes — maybe you're working with a wild population where you can only score dominant and recessive phenotypes — you have to work backwards from the recessive phenotype frequency. The assumption here is that the population is in Hardy-Weinberg equilibrium, which is a big assumption and one that often isn't true. Take the frequency of the recessive phenotype as q², take the square root to get q, then subtract from one to get p. That sounds straightforward until you realize that small sample sizes will give you wildly inaccurate q² values, and if your population isn't actually in equilibrium, the whole exercise is garbage. I've seen people apply this to a sample of 50 individuals and report allele frequencies to four decimal places like it was some kind of precision measurement. It isn't. With n=50, your frequency estimates have standard errors in the range of 0.05 to 0.10 depending on the actual frequency. Reporting anything beyond two decimal places is just false precision.
Get the Full Details

Multiple Alleles Complicate Things Slightly
When you move past two alleles — say a locus with three alleles A1, A2, and A3 — the basic principle stays the same but the bookkeeping gets heavier. Each individual still carries two copies, so the total number of allele copies is always 2N. You count each allele separately and divide by that total. The frequencies should still sum to one, and that's your first check that you haven't made an arithmetic error. One thing nobody warns you about: when you have multiple alleles and you're working from phenotype data instead of genotype data, you can't reliably back-calculate frequencies unless you can distinguish every heterozygous combination. Co-dominance helps here because every genotype produces a unique phenotype. If you have a standard dominant-recessive relationship with three alleles, you're basically flying blind without additional crosses or molecular data.
Common Errors and What to Watch For
The most frequent mistake is dividing by the number of individuals instead of the number of allele copies. That's equivalent to forgetting that diploid organisms carry two alleles per locus. Another one is treating phenotype frequencies as if they were genotype frequencies when you're working with incomplete dominance or co-dominance situations without accounting for it properly. Population structure is another trap. If your "sample" actually comes from two subpopulations with different allele frequencies, the combined frequency you calculate won't represent either group accurately. This is the Wahlund effect, and it inflates the observed homozygosity relative to what Hardy-Weinberg would predict. I once analyzed what I thought was a single population of mussels and got a huge heterozygote deficit. Turns out I'd sampled from two different tide pools that happened to be twenty meters apart but genetically distinct. Splitting the data and recalculating fixed everything. Sampling bias is unavoidable in real work. If you're counting alleles from a convenient sample — say, fish caught in a single net location — your frequency estimate is only as good as how representative that sample is of the actual breeding population. There's no formula that fixes that. You just have to be honest about the limitation and state your sample size and collection method clearly.
Worst Case Scenario: Small and Structured Populations
The method breaks down noticeably when sample sizes drop below about 30 individuals and the population has any structure. In those cases, allele frequency estimates become extremely unstable, and confidence intervals widen to the point where the numbers are barely informative. Bootstrapping can help you estimate the uncertainty around your point estimate, but it doesn't solve the underlying problem of a small, biased sample. If you're working with endangered species or isolated populations where sample sizes are genuinely small, consider reporting Bayesian posterior distributions instead of point estimates. Programs like GENALEX or custom R scripts using Markov chain Monte Carlo methods can give you a distribution of plausible allele frequencies rather than a single number that may be deeply misleading. It takes more effort to set up, but it's more honest about what the data actually supports. Another hard limit: allele frequency calculations assume you're sampling from a sexually reproducing, diploid population with random mating. Anything outside that framework — clonal organisms, polyploidy, haplodiploidy, strong selection at the locus, non-random mating — requires modified approaches that go well beyond the basic counting method. Don't just apply the two-allele diploid formula to a polyploid crop species and call it a day. I've seen that mistake in peer-reviewed papers.
The Quick Reference
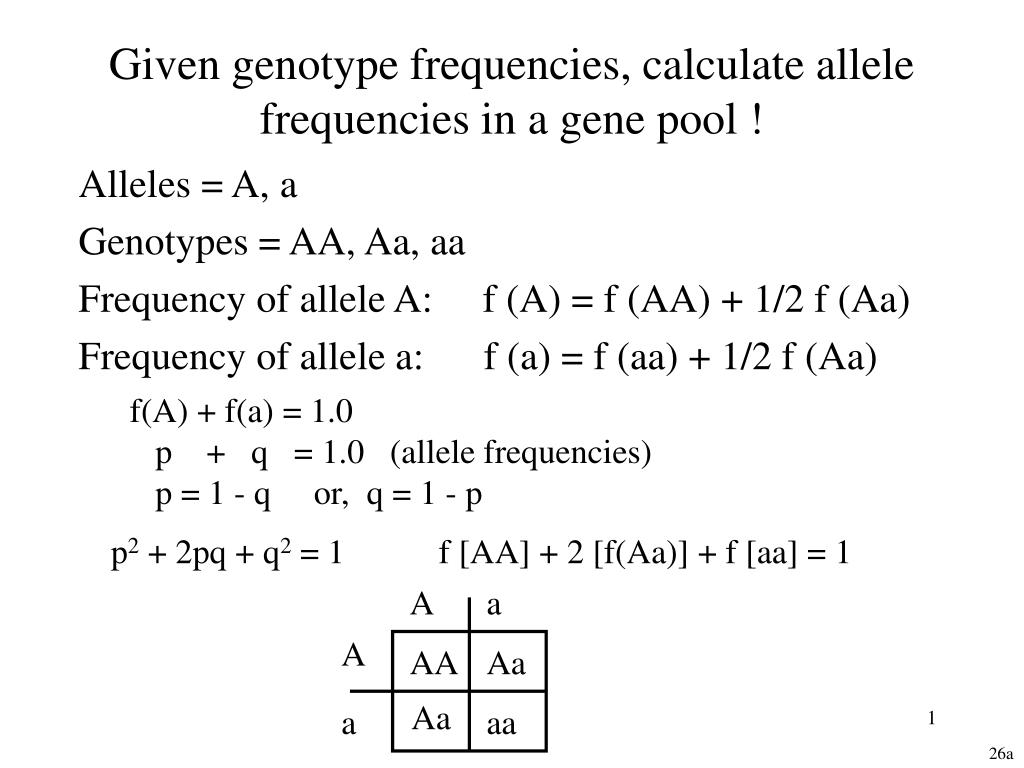
Count total individuals (N). Count each genotype class. Total allele copies = 2N. Frequency of allele A = (2 × homozygous A count + heterozygous count) / (2N). Frequency of allele a = 1 - p. Check that they sum to one. Report sample size and method of genotype determination. If you only have phenotype data, note the Hardy-Weinberg assumption explicitly and consider the sample size limitations before interpreting the result.