Consumer Surplus Basics
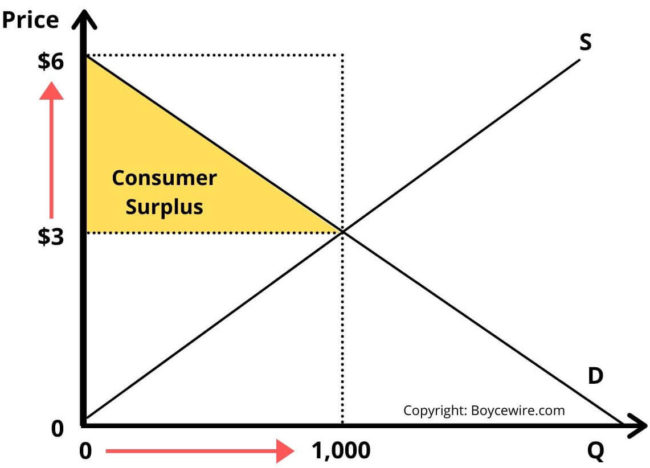
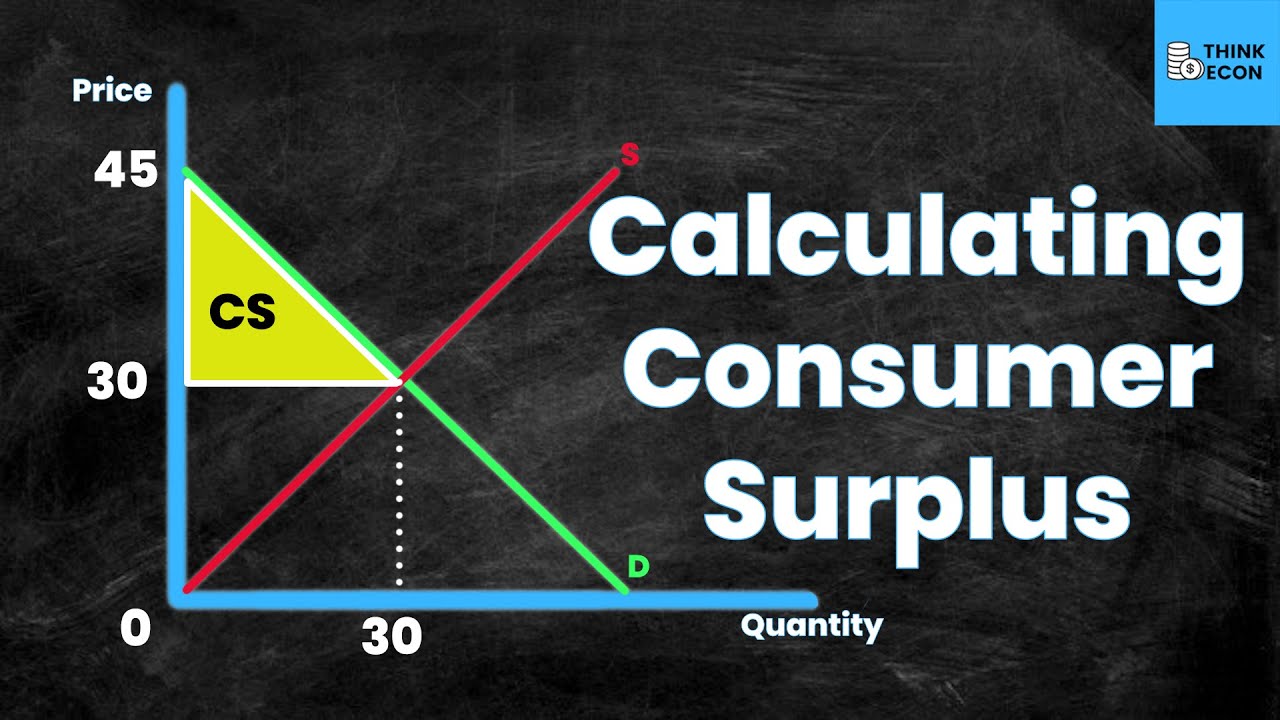
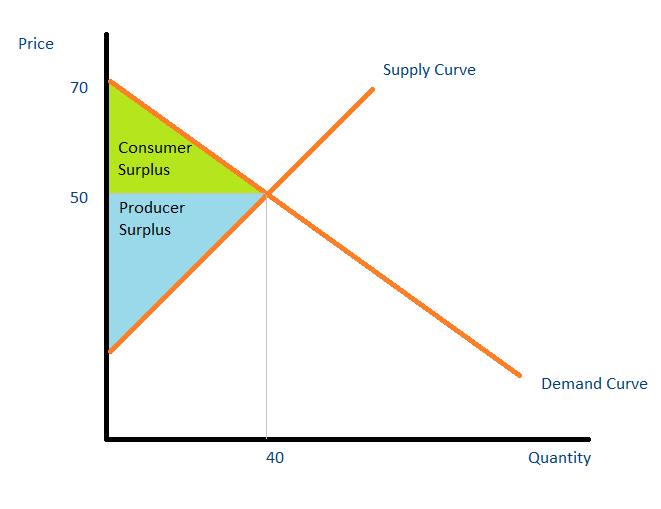
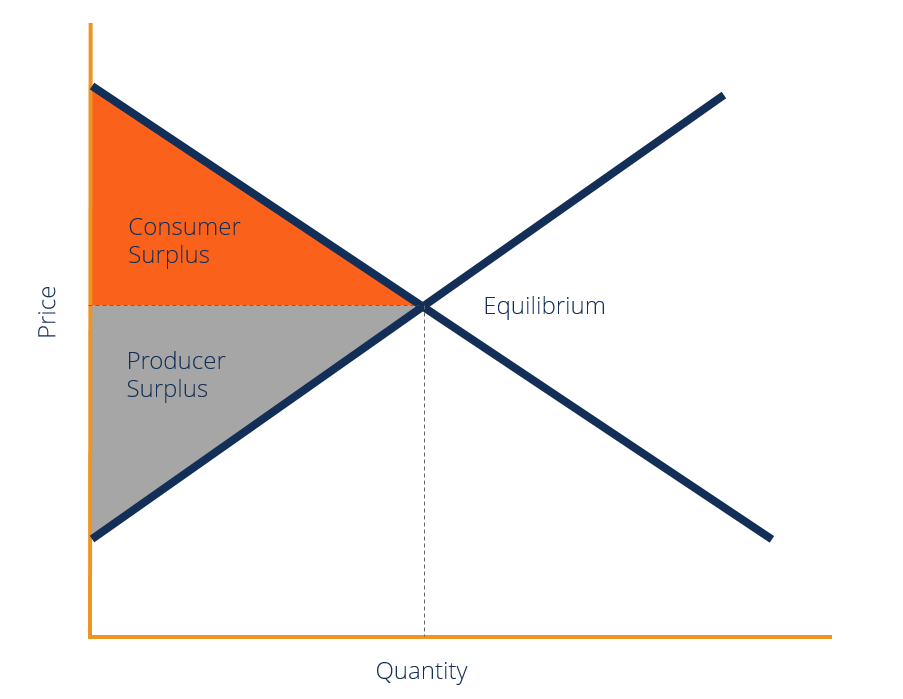
Consumer surplus is the difference between what a buyer is willing to pay for something and what they actually end up paying. It shows up on a graph as the area below the demand curve and above the price line. The math behind it depends on whether you are dealing with a simple linear demand curve or something messier. For a straight-line demand curve, the calculation is straightforward. You need three pieces of information: the maximum price consumers are willing to pay (where the demand curve hits the vertical axis), the actual market price, and the quantity sold at that price. The consumer surplus forms a triangle, so you take the base (quantity) and multiply it by the height (maximum willingness to pay minus actual price), then divide by two. Here is the formula written out plainly: Consumer Surplus = 0.5 × Quantity × (Maximum Willingness to Pay Market Price). That is it for linear demand. If your demand curve is curved or represented by discrete data points, you need to integrate or sum instead.
In practice, I worked on a project a few years back involving a SaaS pricing analysis where the demand curve was definitely not linear. The client had usage data across three price tiers, and using the triangle formula gave us a consumer surplus estimate that was wildly overstated. What I ended up doing was approximating the area under the curve using the trapezoidal rule with the data points we had. It took more work but produced numbers that actually made sense when we cross-referenced them with willingness-to-survey results. One thing beginners consistently miss is that consumer surplus is a static snapshot. It does not account for changes over time, substitution effects, or the fact that different consumers have different willingness-to-pay schedules. When you present consumer surplus as a single dollar figure, people treat it like it is a concrete measure of value created, but it is really just an estimate based on whatever demand data you fed into the model. Another pitfall is assuming the demand curve is stable. In markets where prices shift frequently or where network effects are at play, the demand curve can rotate or shift entirely between periods. Calculating consumer surplus at one point in time and then using it to predict welfare changes later will give you misleading results. In those cases, you need to model the demand function itself and recalculate across different equilibrium points rather than relying on a single triangle area.
For nonlinear demand, say something like Q = a bP² or an exponential form, you calculate consumer surplus by integrating the inverse demand function from zero to the quantity sold and then subtracting total expenditure (price times quantity). I usually set this up in a spreadsheet with small increments along the quantity axis, compute the price at each point from the demand equation, sum the areas, and do the subtraction. It is not elegant but it works reliably when you cannot get a clean closed-form integral. If you have only observed transactions rather than a full demand curve, revealed preference methods can approximate consumer surplus but they come with heavy assumptions. You are assuming that observed choices reflect true underlying valuations and that there is no income effect distorting the picture. In many real-world datasets, especially for heterogeneous products, those assumptions break down fast. The main limitation of consumer surplus as a metric is that it says nothing about distribution. A large aggregate consumer surplus might be concentrated among a small group of high-willingness buyers while the majority gains almost nothing. If you are using this for policy or pricing decisions, break it down by segment rather than treating the total as a single number.
Get the Full Details
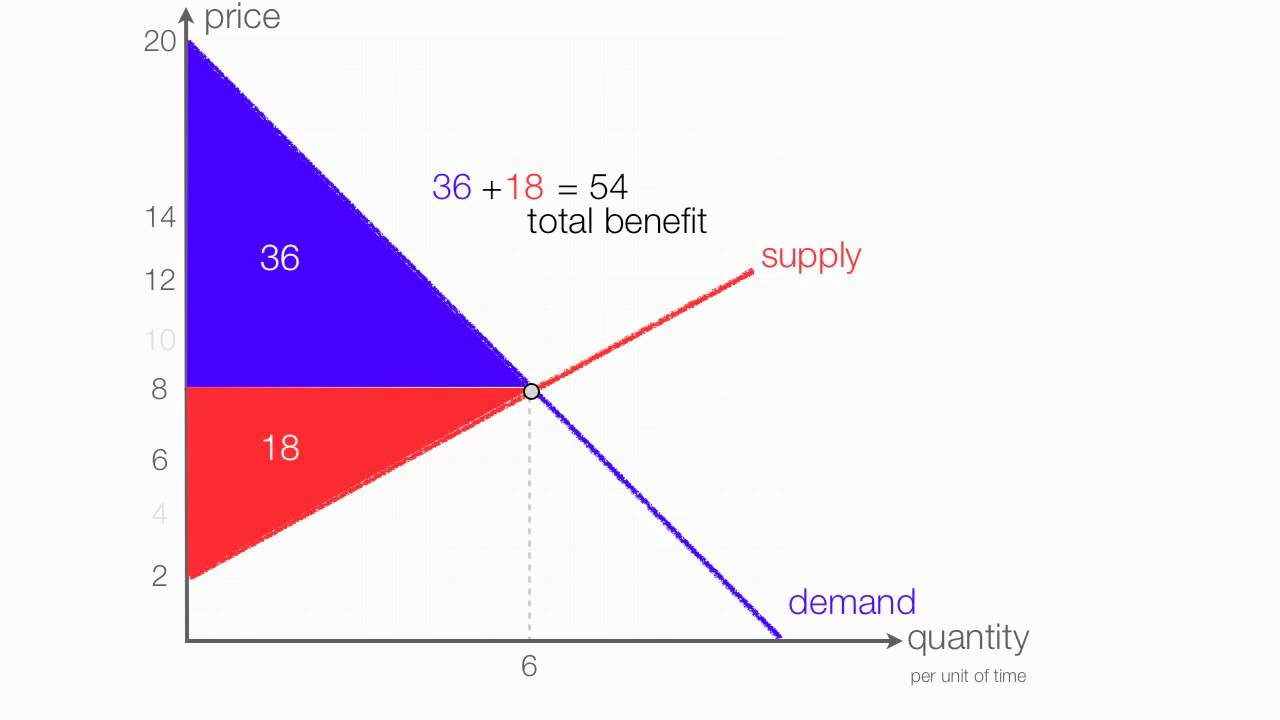
When consumer surplus calculations are driven by sparse data, the results become fragile. Small changes in the estimated demand slope can swing the surplus estimate by significant margins. I always run a quick sensitivity check by varying the key parameters by ten to fifteen percent and noting how much the surplus moves. If it moves a lot, you should flag that uncertainty explicitly rather than presenting a precise figure. For most practical purposes, getting the linear case right and understanding when to move to numerical integration or simulation is enough. The concept is simple. Applying it without thinking about the data quality and the shape of the underlying demand curve is where things go wrong.