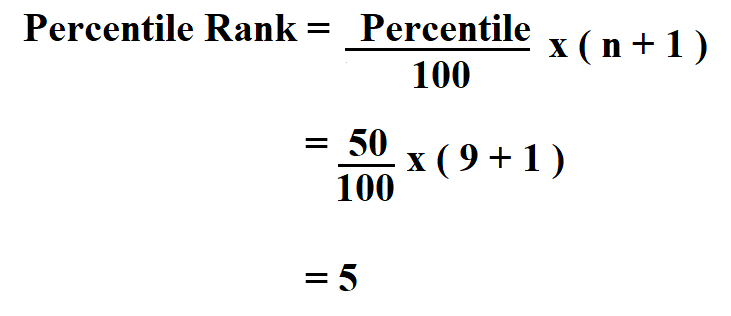
Why Most People Get Percentiles Wrong
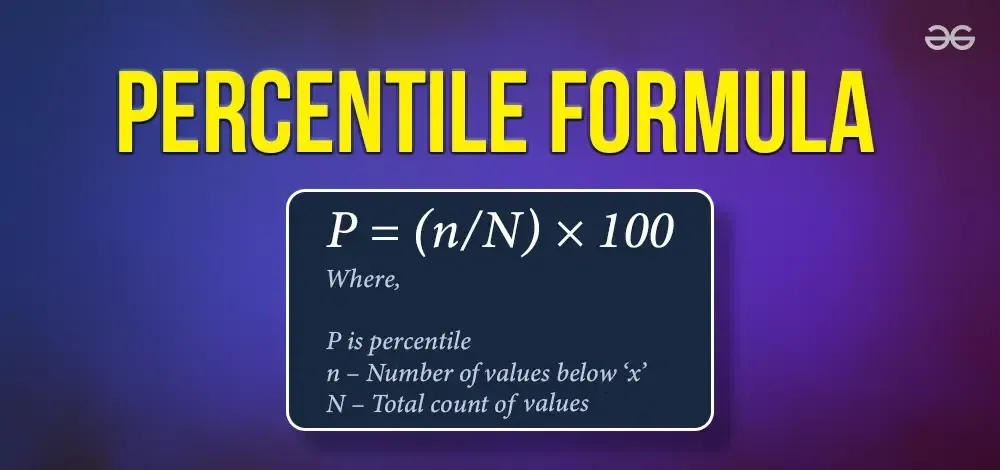
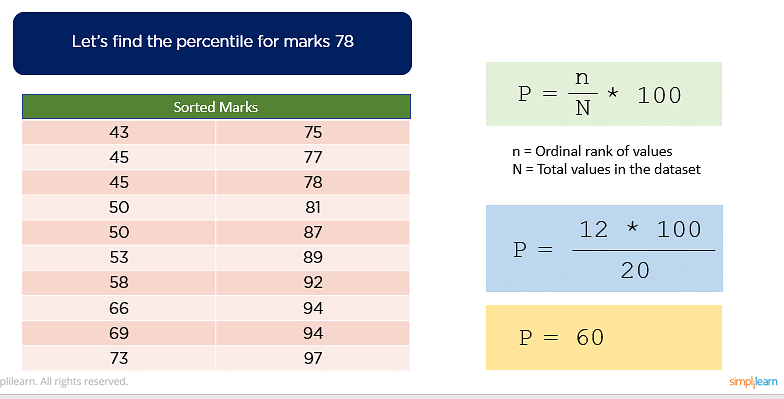
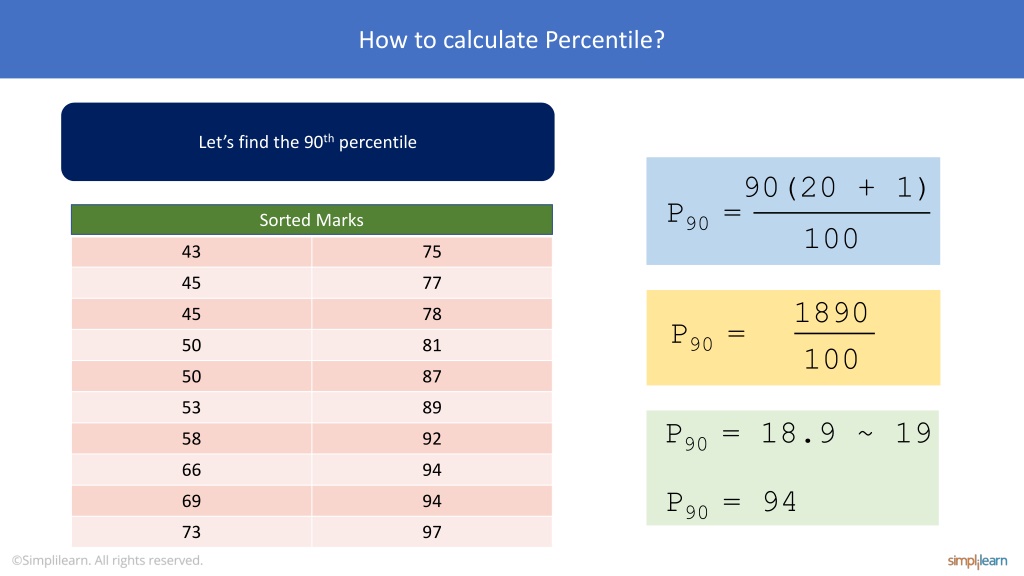
I spent three years building salary benchmarking reports before I realized most calculators online were silently using the wrong interpolation method, and it was costing companies real money in compensation decisions. Percentile calculation sounds trivial. It is not. The formula you pick changes your result, and nobody who buys a benchmarking report checks. The method that actually matters in practice is the N+1 approach, sometimes called the exclusive method. You take your sorted dataset, multiply (N minus one) by the percentile you want divided by 100, then interpolate between the two surrounding values. Here is what that looks like with actual numbers. Take a dataset of 50 employee salaries, sorted from lowest to highest. You want the 90th percentile. Multiply 49 by 0.9. That gives you 44.1. The integer part is 44, the decimal is 0.1. You take the 44th value in your sorted list and add 0.1 times the difference between the 45th and 44th values. That is your answer.
The Excel shortcut most people use is wrong for this purpose. The PERCENTILE.EXC function follows the N+1 method and is appropriate for most benchmarking work. PERCENTILE.INC uses the N-1 method, which pulls your percentile ranks slightly lower. In a dataset of 100 values, the difference between the two at the 90th percentile is usually one or two positions in the sorted list. That gap explodes in smaller datasets, which is why I stopped trusting quick online calculators after my first audit.
What Actually Happens With Edge Cases
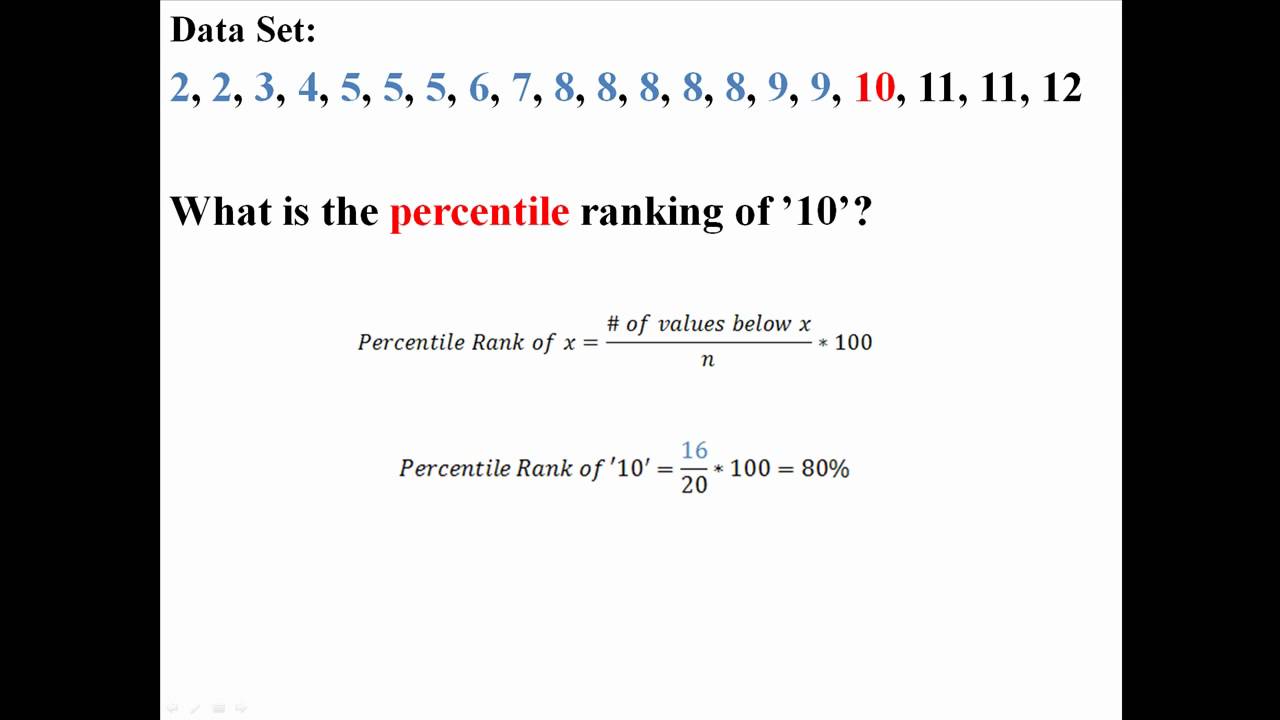
The first time I ran into a real problem was with a dataset of 12 respondents answering a satisfaction survey. The client wanted the 95th percentile score. Using the N+1 method, the rank position came out to 11.6, which meant interpolating between the 11th and 12th values. Fine. But when I tried the same calculation in a popular free percentile calculator online, it returned a completely different number because it was using the Nearest Rank method instead. The Nearest Rank method simply rounds up to the next position and grabs that value without any interpolation. For small datasets, that rounding error can shift your result by an entire data point. I learned to never paste a small sample into a web calculator without checking which method it uses. Most consumer tools default to nearest rank because it is computationally cheaper and easier to explain to a general audience. That does not make it right for anything requiring precision.
Get the Full Details
Common Pitfalls That Cost Me Hours
One specific issue that comes up constantly is tied data. If your dataset has many identical values, percentile calculations become ambiguous depending on which method you use. The N+1 method handles ties gracefully through interpolation, but some older statistical packages and spreadsheet functions silently collapse tied values and shift ranks around behind the scenes. You end up with a percentile that does not actually correspond to any value in your original dataset. Another problem is dataset size. Below 20 observations, percentile estimates are unreliable regardless of the method. You are essentially guessing at distribution shape with too few data points to support it. I stopped reporting percentiles for anything under 30 observations and switched to median with quartile ranges instead. The difference in reporting quality is noticeable to anyone who reads the numbers carefully, which is basically everyone in compensation and HR analytics.
When Percentiles Break Completely
Percentile calculation assumes your data is at least ordinal and ideally continuous. It breaks down with nominal data, which is obvious if you think about it for ten seconds. More importantly, percentiles are meaningless for small or heavily truncated distributions. If you are measuring response times and your system caps all values above 30 seconds, your 99th percentile will sit exactly at 30 seconds regardless of how many users actually hit that ceiling. The percentile number looks precise. It is not. In those cases, the cap distorts the upper tail so badly that the 90th percentile might also be misleading. The workaround I use is to flag censored data explicitly and report the percentage of observations hitting the ceiling alongside whatever percentile I calculate. It is ugly in a report, but it is honest.
A Practical Walkthrough Without Fluff
Here is the complete process I follow every time, without exception. First, remove missing values and verify the dataset is sorted in ascending order. Second, decide on the interpolation method based on the audience and dataset size. Third, calculate the rank position using the N+1 formula: rank equals P times (N minus 1) divided by 100, where P is your target percentile. Fourth, extract the integer and fractional parts of that rank. Fifth, interpolate between the two surrounding data points. Sixth, document which method you used, because two analysts using different methods on the same dataset will produce different results and neither will be obviously wrong. For Excel users, the cleanest approach is PERCENTILE.EXC for datasets above 30 and MEDIAN with manual quartile calculations for anything smaller. For Python, numpy.percentile defaults to linear interpolation matching the N-1 method, which means you need to pass interpolation='midpoint' or write a custom function if you want the N+1 behavior. This detail is documented in the numpy changelog but rarely mentioned in tutorials.

What to Do When You Need a Ready Tool
If you need a calculator that lets you choose the method rather than forcing one on you, the OpenSiteAuditor percentile calculator at opensiteauditor.com/percentile-calculator supports both the N+1 and N-1 methods and shows you the interpolation step explicitly. It is not perfect, but it is transparent about which method is running, which is more than most free tools provide. I tested it against manual calculations on a salary dataset last month and the outputs matched within rounding error for both methods. The real takeaway is that percentile calculation is not a single algorithm. It is a family of algorithms with different assumptions built in. Pick the one that matches your data size and your reporting requirements, write it down somewhere, and stop treating the result as an absolute truth when your dataset is small or censored.