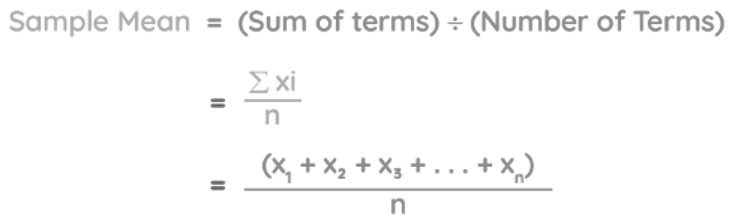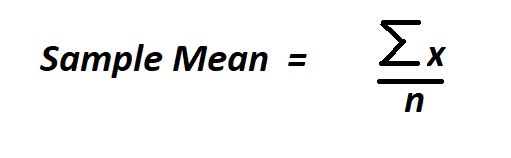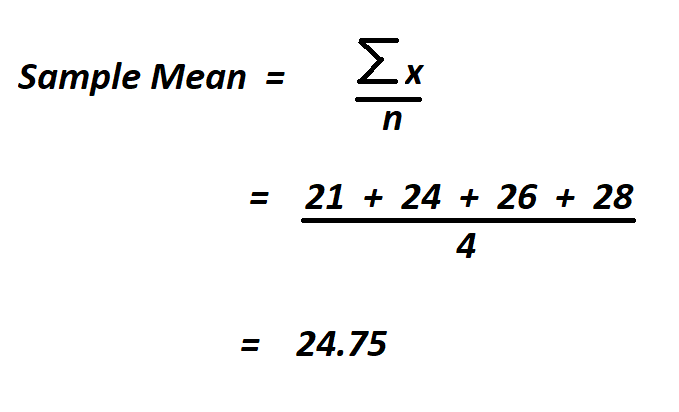
The Basics You Already Know, But Probably Forget
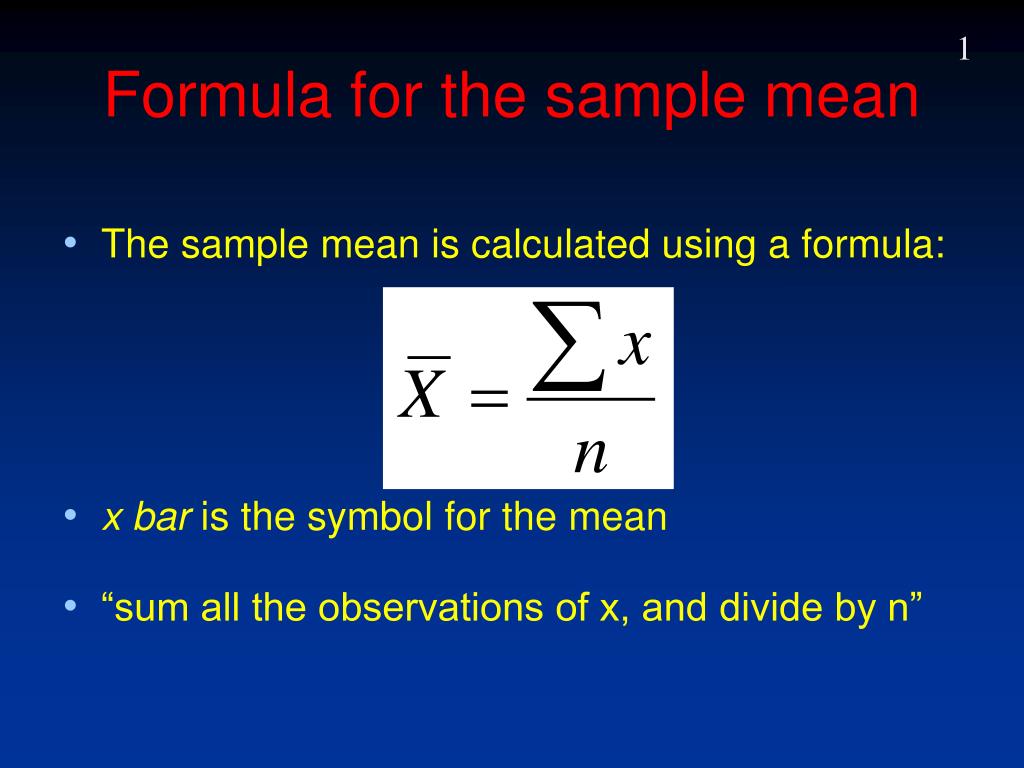
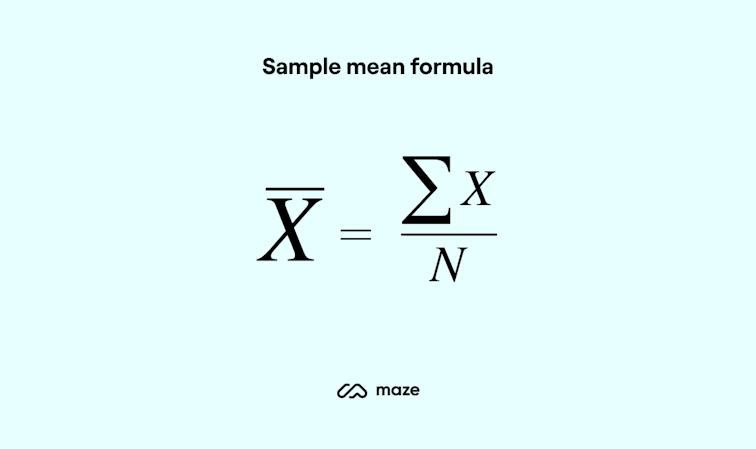
You add up all your data points and divide by how many there are. That's it. The formula is x = x / n. But the reason people mess this up isn't the arithmetic — it's deciding what actually goes into the "add up" part and whether your n is right. I've seen people include outliers without thinking about them, or use population formulas when they should be using sample ones, and then wonder why their confidence intervals are garbage. First, collect your raw data. Make sure every observation is actually from the same population and measured the same way. I once worked with a dataset where someone had merged two separate surveys — one from Monday through Wednesday and another from Thursday through Saturday — without flagging the date the second group was collected. The sample mean looked fine at 47.3, but when I broke it down by day, the Thursday-to-Saturday readings were consistently 12% higher due to a seasonal effect we'd missed. The combined mean was technically correct for the numbers, but completely misleading for whatever decision someone was about to make with it. Always check your data collection timeline before you sum anything. Write your formula down clearly. X-bar equals the sum of all individual values divided by the count of observations. Don't skip writing it out. When you're working with actual spreadsheets, this becomes a simple SUM function divided by a COUNT function. In Excel or Google Sheets, that's =SUM(A2:A150)/COUNT(A2:A150). The COUNT function is important here because it ignores blank cells, whereas SUM doesn't care. If you mix them up, you get wrong results and nobody tells you.
Let me give you a concrete example. Say your sample data looks like this: 12, 15, 18, 22, 19, 14, 17. Add them together: that's 117. You have seven values. Divide 117 by 7 and you get approximately 16.71. That's your sample mean. It's straightforward enough that most people breeze through it and move on, but that's also where problems start creeping in.
Where Things Get Messy in Practice
The sample mean is sensitive to extreme values in ways that people don't always appreciate. If your dataset has a few very large or very small numbers, the mean shifts toward them. This isn't a flaw in the math — it's a property of the arithmetic mean itself. For skewed distributions, the median often tells you more about what a "typical" value looks like. I remember pulling a dataset from a manufacturing line where the mean defect rate was 3.2 per batch, but the median was 1.8. Half the batches had zero defects, and the rest were clustered around 5 to 6. The mean was technically the right number to report, but anyone using it to set quality targets was going to be wildly optimistic. Another thing people miss: the difference between sample mean and population mean. Your sample mean is an estimate. It's not the true population mean unless you're lucky or your sample is huge. The standard error tells you how much doubt to attach to that number. Standard error equals the standard deviation divided by the square root of n. So if your sample size doubles, your standard error only drops by about 30 percent, not 50. That's counter-intuitive for most beginners. You need exponentially larger samples to get meaningfully tighter estimates. When your data isn't normally distributed, the sample mean is still a perfectly valid descriptor. It's not biased by definition. But interpreting it requires more care. In a heavily right-skewed distribution like income data, the mean can sit far above what most people actually experience. Reporting just the mean in those cases without context is lazy statistics. Include the standard deviation or interquartile range alongside it so people know how spread out your observations actually are.
Get the Full Details
Common Mistakes That Waste Time
Using the wrong denominator is the most common error. Some software packages default to dividing by n minus one when you ask for standard deviation, which is correct for the sample standard deviation, but the mean itself always uses n, not n minus one. The n minus one adjustment applies to variance and standard deviation estimation, not the mean calculation. I've corrected this mistake in at least three different projects where the analysis pipeline was feeding n-1 into a mean function, producing slightly inflated averages that cascaded through every downstream test. Another issue is treating grouped data the same way as raw data. If your information comes in frequency tables rather than individual observations, you calculate the mean differently. Multiply each midpoint by its frequency, sum those products, then divide by the total frequency. Skipping this step and just averaging the midpoints gives you the wrong answer. I learned this the hard way when a colleague handed me a frequency distribution from a published paper and I accidentally averaged the class labels instead of weighting them properly. My result was off by nearly eight percent, which seemed small until I realized the paper's conclusion hinged on a difference of that exact magnitude. Check for missing data before you calculate. Dropped values change your n. If 15 out of 200 observations are missing and you just run SUM divided by COUNT without checking, you'll use n equals 185 instead of 200. The mean might not change much, but your standard error will be wrong, and any confidence interval you build from it will be too narrow. Always verify your count matches your actual usable observations.
When the Mean Isn't the Right Tool
There are situations where the sample mean gives you bad information. Heavy-tailed distributions are one. If your data comes from a process with occasional massive outliers, the mean becomes unstable and unreliable as a summary statistic. The median or trimmed mean is often more appropriate. In finance, for example, daily returns sometimes follow distributions where the mean oscillates wildly from one sample to the next while the median stays relatively stable. Relying on the mean for risk assessments in those contexts can lead to serious miscalculations. Small samples are another problem area. With fewer than about 30 observations, the sample mean can deviate substantially from the population mean just by chance. The law of large numbers helps, but you need a decent sample size for it to kick in. If you're working with n equals 8 and your mean is 52, that number could easily shift by five or six units if you added just a handful more observations. Report your confidence interval whenever possible so readers understand the uncertainty around your point estimate. Repeated measures and paired data complicate things too. If your observations aren't independent — say you're measuring the same subjects multiple times — the standard sample mean formula still works for the point estimate, but the inference you draw from it needs adjustment. Paired t-tests account for this, but a naive mean calculation followed by an independent-samples test will give you incorrect p-values. I've seen this mistake cost people entire publications because reviewers caught the statistical inconsistency.
A Quick Reference You'll Actually Use
Here's what you need to remember without overthinking it. Collect clean data from a single population. Sum all observations. Count them. Divide the sum by the count. Report the standard deviation alongside the mean. Check for outliers and note whether your distribution is roughly symmetric. If it's not, consider mentioning the median too. That's basically it. The math is trivial. The judgment calls around data quality and interpretation are what separate useful analysis from noise.