What Sample Variance Actually Measures
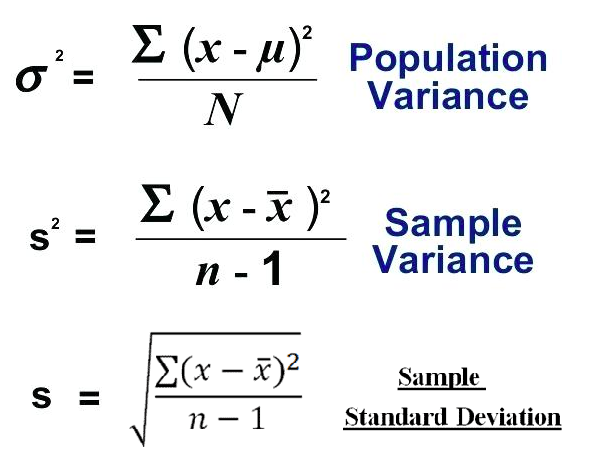
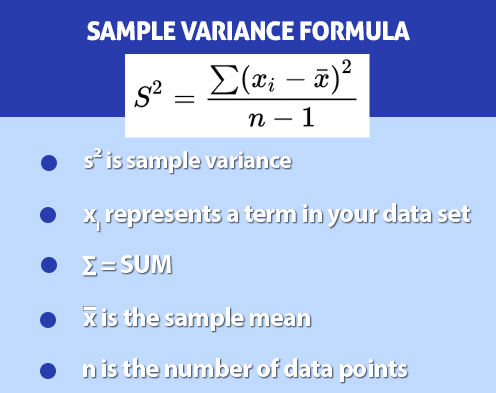
When you pull a bunch of numbers from a dataset and want to know how spread out they are, sample variance gives you that number. It is not the same as population variance, and mixing the two up will throw off every downstream calculation you run. The difference matters because sample variance uses N minus one in the denominator, not N. That single adjustment, called Bessel's correction, compensates for the fact that you are estimating from a subset rather than the full population. I spent three days debugging a quality-control report last year where variance values were consistently 4 percent too low across all product batches. The root cause turned out to be a spreadsheet formula using population variance instead of sample variance on a dataset of just 23 measurements. Once I switched to the correct divisor, the control limits lined up properly. Here is the actual procedure. Start by collecting your data points and counting them to get N. Compute the mean by adding all values together and dividing by N. Subtract the mean from each individual value to get deviations. Square every deviation. Add all squared deviations together to get the sum of squares. Divide that sum by N minus one. The result is your sample variance.
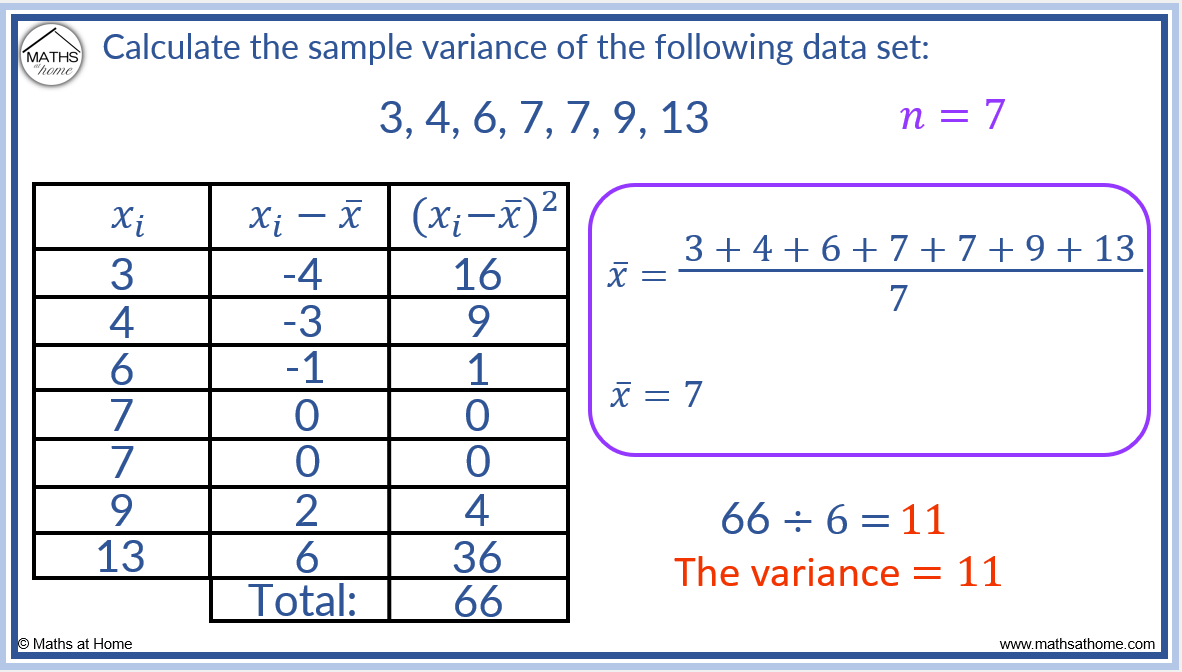
Let me walk through a concrete example with actual numbers rather than abstract variables. Say you have these five measurements from a production line: 12, 15, 14, 13, 16. The mean is 74 divided by 5, which equals 14.8. Now subtract 14.8 from each value: 12 minus 14.8 is negative 2.8, 15 minus 14.8 is positive 0.2, 14 minus 14.8 is negative 0.8, 13 minus 14.8 is negative 1.8, and 16 minus 14.8 is positive 1.2. Square each of those: 7.84, 0.04, 0.64, 3.24, and 1.44. Sum them to get 13.2. Divide by 5 minus 1, which is 4. Your sample variance is 3.3. The standard deviation is just the square root of variance, so in this case it would be approximately 1.81. Variance itself is expressed in squared units, which is why most people prefer standard deviation for interpretation. When your measurements are in millimeters, variance is in square millimeters, which sounds weird until you remember it is just an intermediate mathematical step.
Common Implementation Mistakes
The most frequent error I see is using the wrong denominator. Python's numpy.var function defaults to population variance with ddof equal zero. If you need sample variance, you must pass ddof equal one. Excel users often mix up VAR.P and VAR.S functions without noticing. R's var function gets it right by default, which catches people off guard when they switch between platforms. Another issue is forgetting that variance is sensitive to outliers. A single extreme value can inflate your result dramatically. I once had a dataset where removing one measurement changed the variance by a factor of eight. That is not a bug in the formula, it is just how variance behaves mathematically. If your data has heavy tails or known contamination, consider using robust alternatives like the median absolute deviation instead. Watch out for numerical stability when working with large datasets and large values. The naive formula, sum of squared deviations divided by degrees of freedom, can suffer from catastrophic cancellation in floating point arithmetic. The two-pass algorithm I described above avoids this by computing the mean first, then deviations. There is also a one-pass online algorithm, but it trades memory efficiency for precision, so the two-pass approach is usually better unless you are processing streaming data in real time with severe memory constraints.
Get the Full Details
When Sample Variance Fails You
Variance assumes your data is roughly symmetric around the mean and that extreme values are relatively rare. For heavily skewed distributions like income data or failure times in reliability engineering, variance becomes a poor descriptor of spread. The value will be dominated by the long tail rather than reflecting the typical variation you see in most observations. In those cases, report the interquartile range alongside variance, or switch to log-transformed analysis if the skew follows a multiplicative pattern. Small samples introduce their own problems. With fewer than ten observations, the sample variance itself has high variability. The estimate you compute might be quite far from the true population variance just by chance. Confidence intervals for variance are asymmetric and wide when N is small. If you need precise estimates from small samples, increase N or use Bayesian methods with informative priors rather than relying on a single point estimate. The formula breaks down entirely for categorical data or ordinal scales where subtraction has no meaningful interpretation. Do not compute variance on Likert scale survey responses as if they were interval data without strong justification. The result will be numerically correct but substantively meaningless. Use frequency distributions or non-parametric tests instead.
Quick Reference for Common Tools
In Python, use numpy.var(data, ddof equal one) or scipy.stats.variation for the coefficient of variation. In R, var(data) gives sample variance directly. In Excel, =VAR.S(range) is the sample version while =VAR.P(range) is population. In SQL, there is no built-in variance function in standard ANSI SQL, so you typically compute it with a subquery or use vendor-specific extensions like PostgreSQL's var_samp function. For spreadsheet work, never trust the default variance function without checking documentation. I have seen engineers copy formulas from Stack Overflow without verifying whether they were computing population or sample variance, then wonder why their statistical process control charts looked wrong. The formula itself is simple. The context determines whether you are doing it correctly.
Related Concepts Worth Knowing
Standard error of the mean relates directly to sample variance. It is the square root of variance divided by N, not N minus one. That distinction matters because standard error describes uncertainty in the mean estimate, while variance describes spread in the data itself. Confusing them leads to incorrect hypothesis tests and confidence intervals. Covariance extends the variance concept to two variables. Sample covariance uses the same N minus one denominator and measures how two variables vary together. The correlation coefficient is covariance standardized by the product of standard deviations, giving a unitless measure between negative one and positive one. These all share the same computational foundation, so understanding variance well pays off across multiple statistical methods. Analysis of variance, ANOVA, decomposes total variance into between-group and within-group components. The name is slightly misleading because ANOVA actually tests whether group means differ, using variance ratios as the test statistic. The method requires homogeneity of variance across groups as an assumption. If your groups have very different variances, consider Welch's ANOVA or transform the data before proceeding.
Practical Tips for Real Data
Always visualize your data before computing variance. A histogram or box plot will reveal skew, outliers, or multiple modes that a single number cannot capture. Variance compresses all that information into one value, which is useful for calculations but dangerous for interpretation. Pair it with median and quartiles to get the full picture. When comparing variances across groups, use Levene's test or the F-test for equality of variances rather than visual inspection alone. These tests are sensitive to non-normality, so robust alternatives exist if your data deviates from normality. In quality control contexts, monitor both variance and mean over time using control charts designed for each purpose. For reporting purposes, round variance to two or three significant figures depending on your sample size and measurement precision. Reporting ten decimal places on a variance estimate from thirty observations creates false precision. The underlying uncertainty from sampling variability dwarfs any digits beyond the second or third decimal place anyway.


