Calculating Standard Deviation When You Only Have the Mean
Here's the blunt truth that most tutorials skip: you cannot calculate standard deviation from the mean alone. The mean tells you the center. Standard deviation tells you the spread. These are two completely separate pieces of information. If someone hands you only a mean value and asks for the standard deviation, the answer is that it's impossible. Period. What people actually mean when they ask this is slightly different. They usually have a dataset, they've computed the mean, and now they want the standard deviation. Or they have summary statistics like the sum of squared deviations and the mean, and they want to work backward. Let me explain the actual mechanics so you stop running into dead ends.
How To Calculate Standard Deviation From Mean
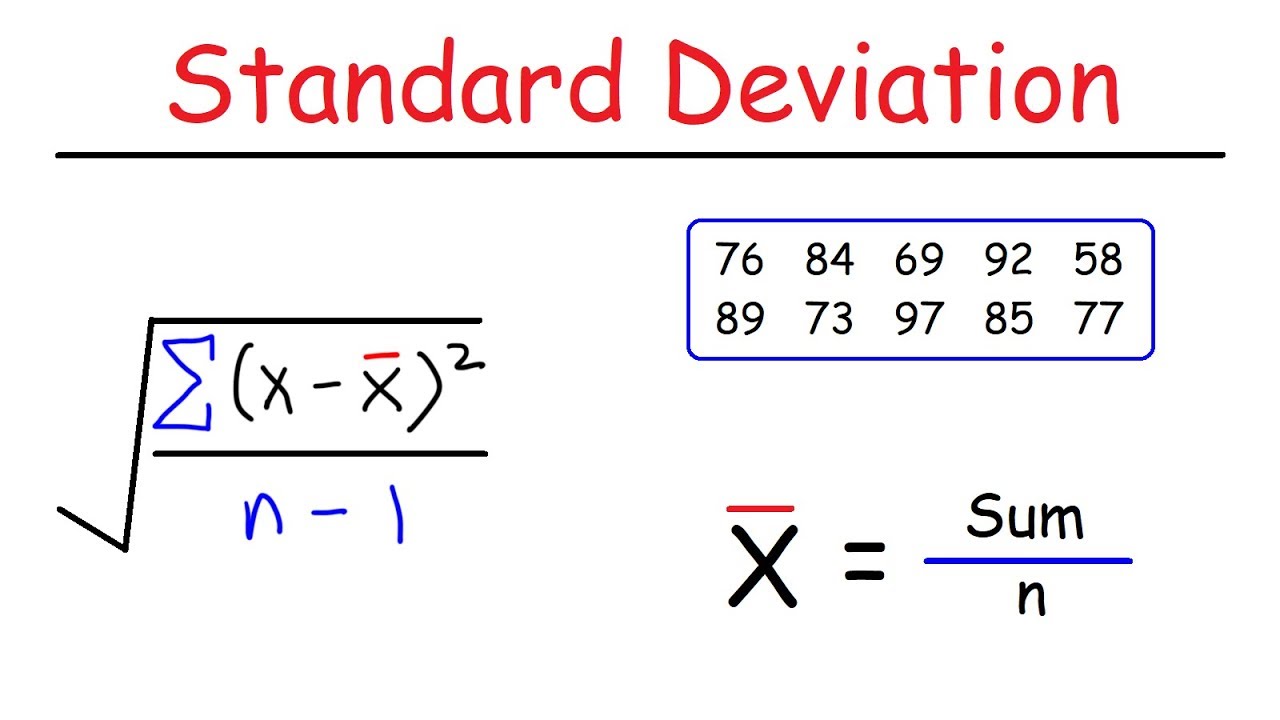
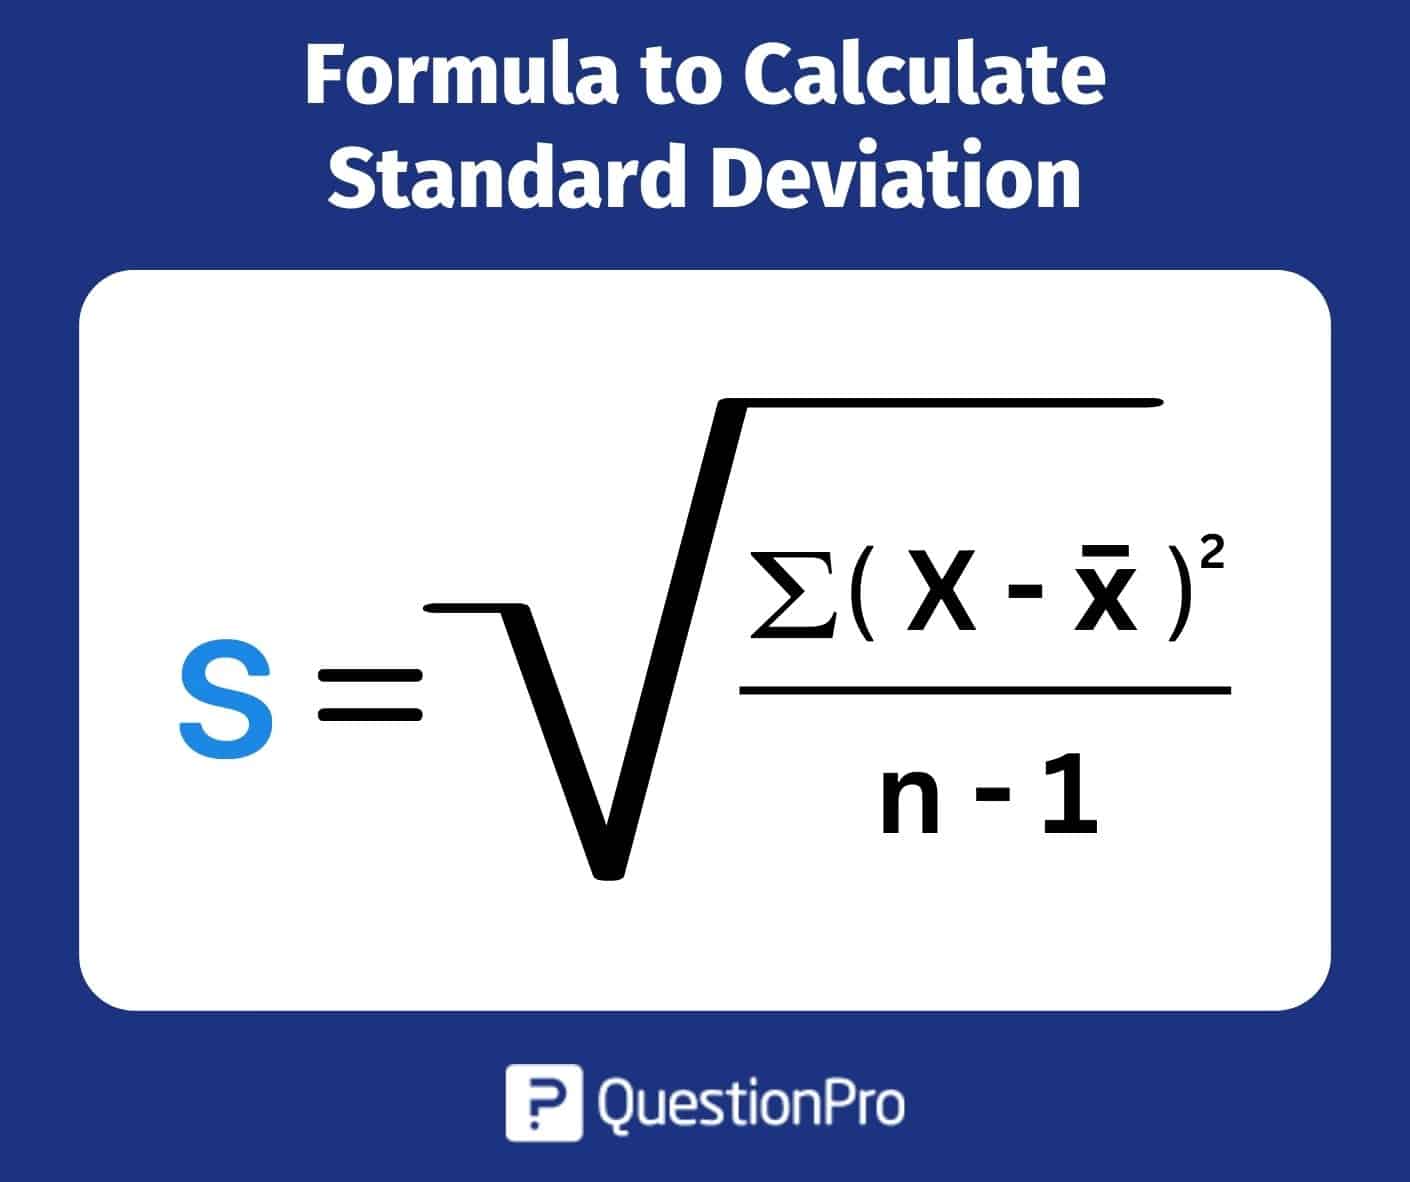
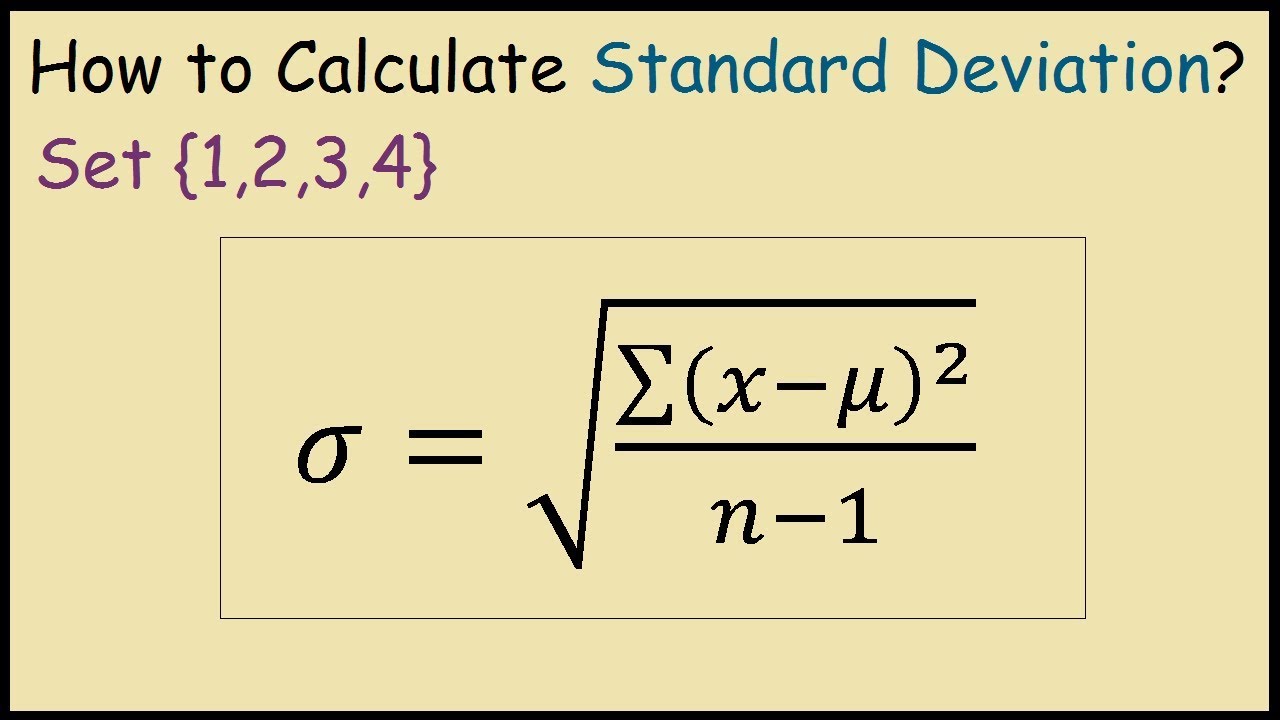
The full process starts with your raw data. Let's say you have 10 test scores: 72, 78, 85, 90, 68, 74, 81, 88, 76, 73. First you compute the mean by adding everything and dividing by the count. That gives you 78.5. Then you subtract the mean from each individual score, square each result, sum all those squares, divide by either N or N-1 depending on whether this is a population or a sample, and take the square root. The sample formula uses N-1. The population formula uses N. That distinction matters because using the wrong one introduces bias. For the example above with those 10 scores, the squared deviations are 42.25, 2.25, 12.25, 56.25, 84.25, 20.25, 4.25, 36.25, 2.25, and 12.25. Their sum is 272.5. Divide by 9 for sample variance, get 30.28, and the standard deviation is approximately 5.50. Divide by 10 for population variance, get 27.25, and the standard deviation is approximately 5.22. I remember working on a quality control project where our instrumentation only exported the mean and the standard error, not the raw readings or even the sum of squares. Someone on the finance team asked me to "back out" the standard deviation from the mean. I had to explain three times before they accepted that the data simply wasn't there. Eventually we got access to the raw log files and found the actual standard deviation was 40% higher than what a rough approximation based on the standard error would have suggested. The mistake almost led us to approve a batch that was significantly more variable than our specification allowed.
There's a shortcut formula that some people find useful. Instead of computing each deviation individually, you can use the sum of squares of the original values and the square of the sum. The formula becomes: standard deviation equals the square root of [sum of x² minus (sum of x)² divided by N], all divided by N for population or N-1 for sample. This is algebraically identical to the definition but computationally different. It works fine for small clean datasets but can introduce floating-point rounding errors when your numbers are large and the variance is small. I've seen this cause issues in financial modeling where asset returns had means in the low single digits but the raw price values were in the thousands. The real counter-intuitive insight most beginners miss is that the mean and standard deviation together assume a normal distribution, and that assumption is frequently wrong. A dataset can have a mean of 50 and a standard deviation of 10 and still be heavily skewed, bimodal, or contain extreme outliers. The standard deviation number looks precise but it's just a single summary statistic that collapses a lot of information. In my experience working with production metrics, the interquartile range often tells you more about actual variability than the standard deviation does, especially when your data has a long right tail. Another thing nobody emphasizes enough: if you're working with grouped or binned data where you only have frequency distributions and class midpoints, the standard deviation you calculate is an approximation. It assumes all values within a bin are exactly at the midpoint. This can introduce noticeable error, particularly with wide bins or non-uniform distributions within those bins. I encountered this when reconciling published statistics from a government survey that only reported grouped frequency tables. My recalculated standard deviation differed from their reported value by about 12%, and the entire difference traced back to the binning approximation.
Get the Full Details

For practical implementation, if you're doing this by hand for a small dataset, the direct method is fine. If you're programming this, use a numerically stable algorithm like Welford's method, which updates the mean and variance in a single pass without storing all the data. It avoids the catastrophic cancellation problem that the shortcut formula runs into. If you're using Excel or Google Sheets, the functions are straightforward: STDEV.S for sample and STDEV.P for population. Both require the actual data cells, not just a mean value. The fundamental limitation here is that standard deviation and mean operate at different levels of abstraction. The mean is a location parameter. The standard deviation is a scale parameter. You need information about both to describe a distribution meaningfully, and knowing one tells you nothing about the other. Any method that claims to derive one from the other without additional data is either making implicit assumptions about the distribution shape or producing a result that's essentially a guess. In practice, the workaround is to either collect the raw data, request the sum of squared deviations from whoever has it, or acknowledge that the question as stated has no determinate answer.