Computing Half-Life From Real Data
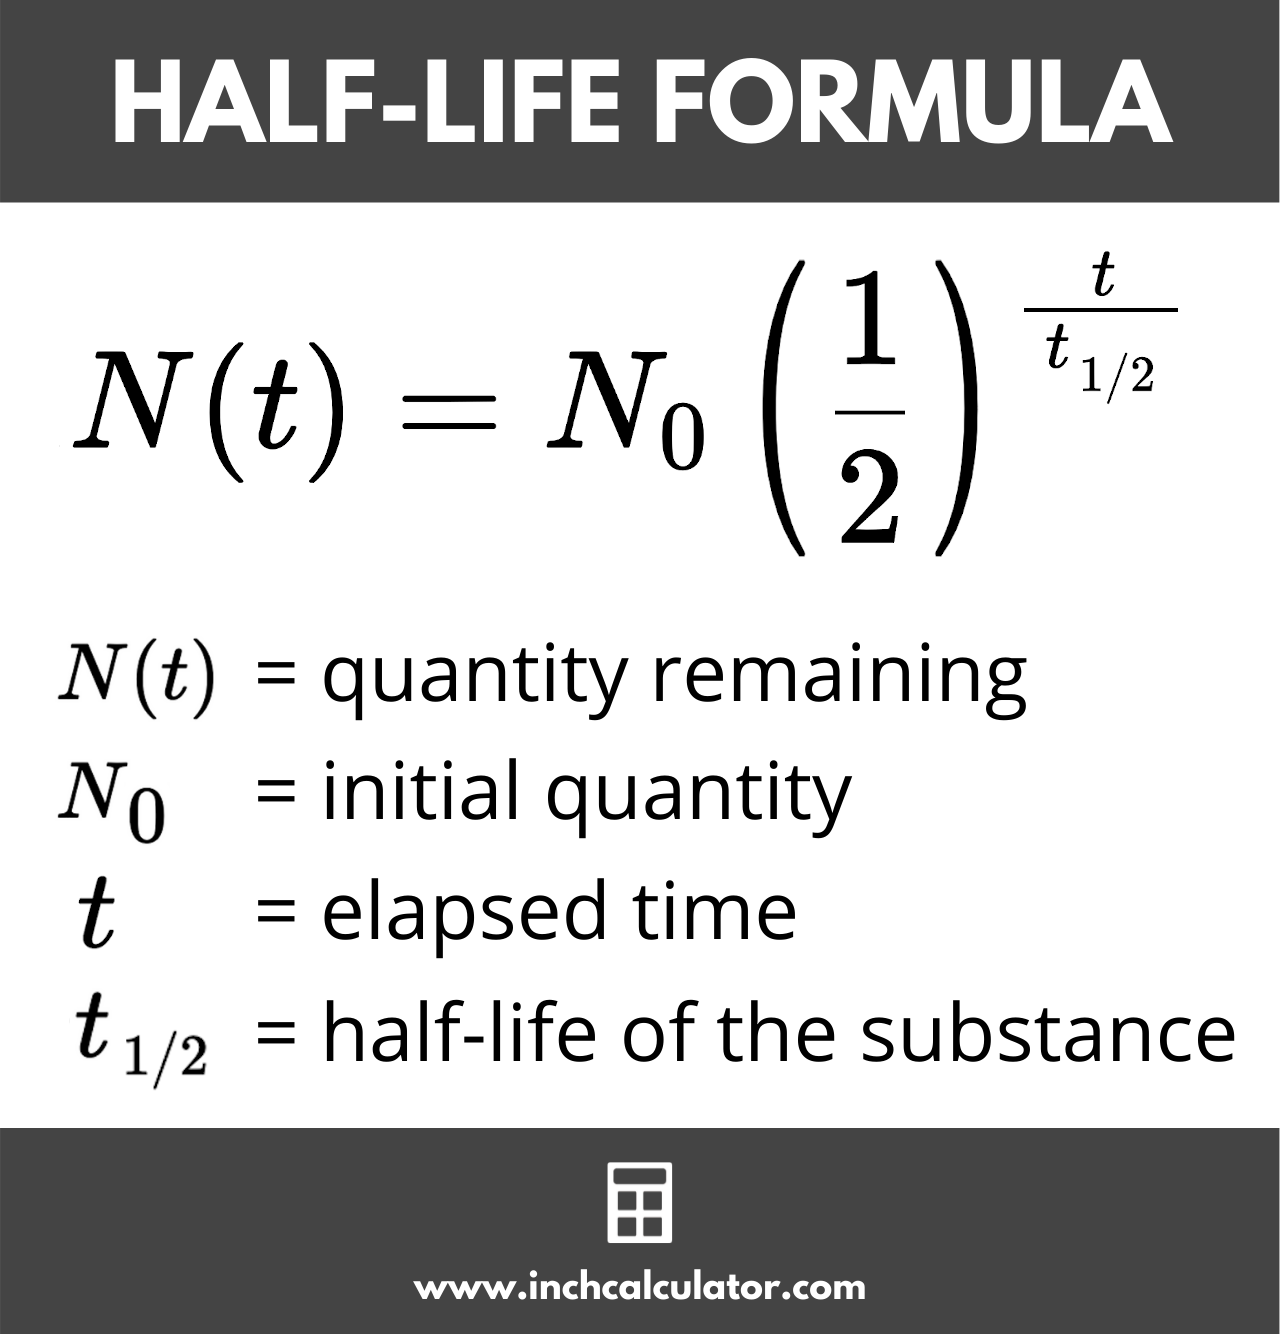
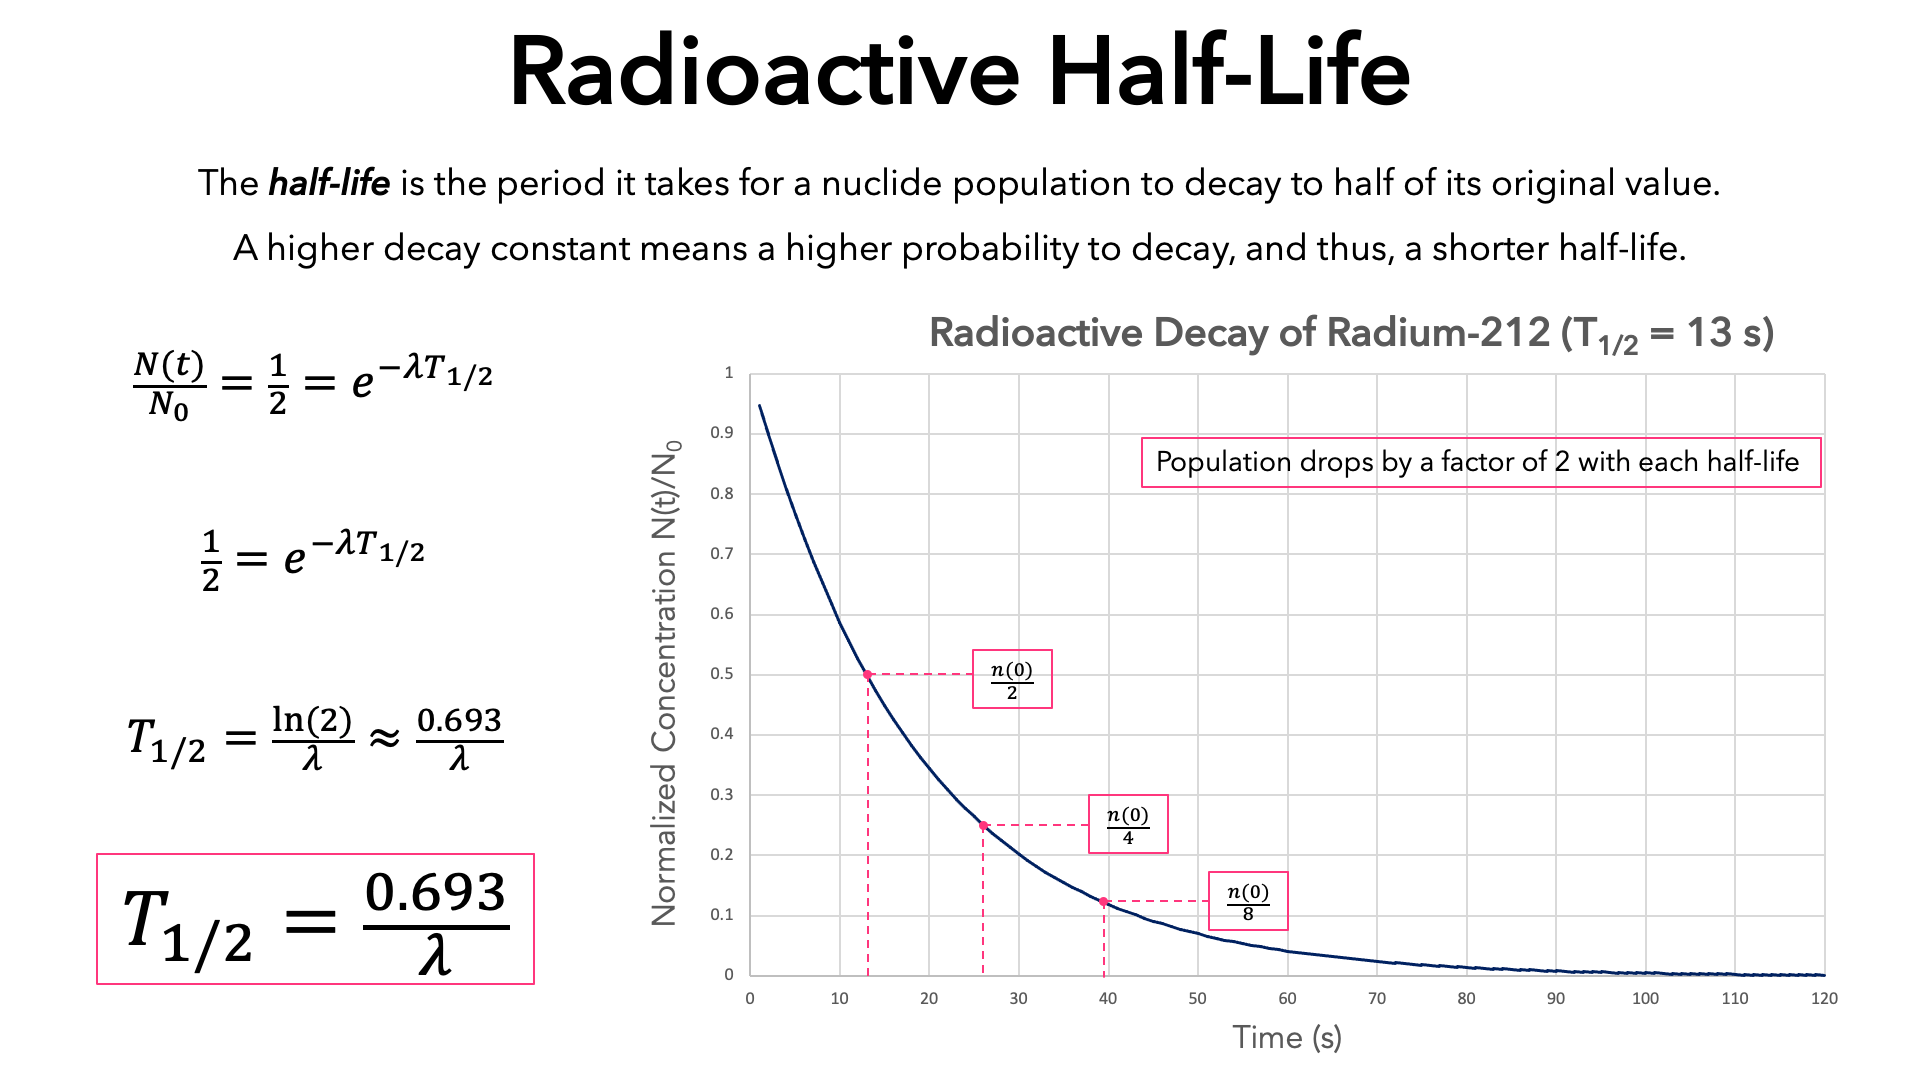
Most people learn the formula in a physics class and then never use it properly. The equation t_half = ln(2) / is straightforward enough, but getting from actual measurements is where things go wrong. I've seen too many people plug raw counts into that formula and wonder why their result looks nothing like published values. Start with your measurement. If you're working with a radioactive source, you log activity at various times. Ideally you have at least ten data points spread across a range that covers two or three half-lives. One point per hour for six hours beats four points over two hours every time. The method that actually works is fitting the exponential decay curve, not picking two points and plugging them in. When I do this, I natural-log-transform the activity values and run a linear regression on ln(A) versus t. The slope of that line gives me directly. Then I divide ln(2) by the absolute value of the slope and I have my answer.
Here's the thing most tutorials skip: you need to subtract the background count rate first. I worked with a lab tech once who was getting half-life values that drifted depending on which Geiger counter tube he used. Turns out the background in that room was sitting at about 42 cpm from construction materials in the walls. His sample was around 200 cpm gross. Without subtracting background, his "decay constant" was really just measuring the noise floor, not the isotope. Once we backed out the background and re-ran the regression, the half-life came back to 6.28 hours, which matched the literature value for the sodium isotope we were tracking. That was a day and a half of confusion saved. For a purely mathematical scenario where you already know the decay constant, the computation is trivial. Take any isotope. Iodine-131 has a of approximately 0.0864 per day. Half-life equals 0.693 divided by 0.0864, which gives you 8.02 days. That's the whole calculation. Not much to it when the parameters are given.
When You Only Have Two Measurements
Sometimes you're forced to work with minimal data. Maybe you have an initial activity A0 at time zero and a second reading A1 at time t1. The formula rearranges to = ln(A0/A1) / t1, then half-life is ln(2) / . It's mathematically valid, but your error margin is enormous. A ten percent uncertainty in either measurement can throw your half-life estimate off by thirty percent or more. Don't present this as a precise result. It isn't. The same approach applies to pharmacokinetics, by the way. Drug concentration in the bloodstream follows the identical exponential model. The decay constant is just called the elimination rate constant there, but the computation is identical. I've done this for both radiation safety assessments and dose-adjustment calculations, and the spreadsheet workflow is the same either way.
Get the Full Details

Common Pitfalls
Using uncorrected data is the biggest one. Background subtraction, detector dead-time correction, and for some setups, self-absorption in the sample itself — these all matter. A thin Mylar window detector and a thick sample pellet will give you different count rates not because the isotope changed, but because photons got absorbed in the sample before reaching the detector. I've wasted hours chasing phantom decay curves caused by exactly this. Another issue: people often try to compute half-life from a single measurement by assuming they know the initial activity. That only works if you have an independent calibration. Otherwise you're just making an assumption and calling it a result. And if your data doesn't actually follow a single exponential — say you're dealing with a decay chain where the daughter product is also radioactive — the simple ln-transform and linear fit will give you an effective half-life that's useful for rough estimates but wrong for anything requiring precision. In those cases you need to model the Bateman equations or at minimum fit a sum of exponentials. That's a different problem entirely.
What to Use
A spreadsheet with a scatter plot and trendline will handle basic cases. Excel's LINEST function or Google Sheets' SLOPE and INTERCEPT functions work fine for manual extraction. For anything with more than twenty data points or multiple decay components, I use Python with scipy.optimize.curve_fit. The whole script runs in under two seconds and gives you confidence intervals on the parameter estimates, which you need if you're reporting this in a lab setting. The core computation never changes — it's always ln(2) divided by the decay constant — but getting a reliable decay constant from noisy real-world data is where the skill lives. Measure well, subtract background, fit properly, and don't pretend a two-point calculation is anything other than an approximation.