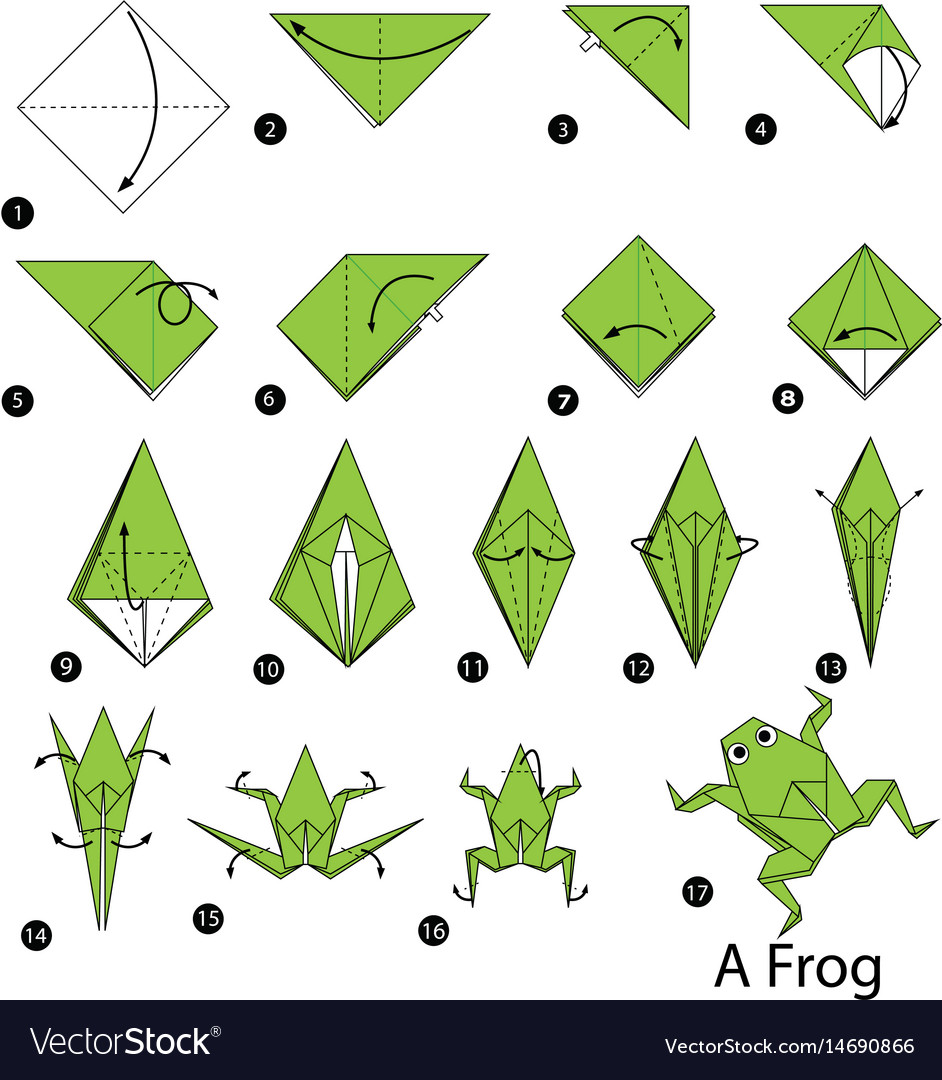
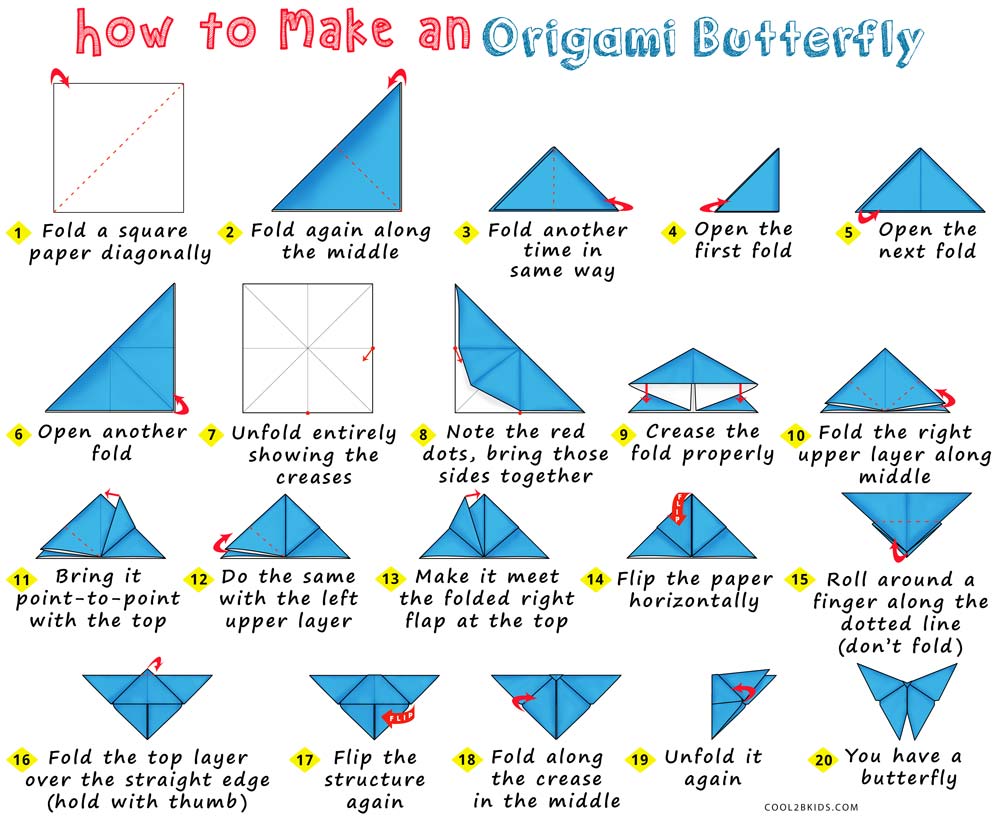
Starting From the Actual Fold, Not the Diagram
Most people overthink this part. They grab a design, find it online, and immediately try to take photos while figuring out the steps. That approach barely works for simple cranes and frogs. For anything with more than eight folds, you will waste hours re-doing shots that look wrong in hindsight. The process I use starts with paper on a table. I pick one sheet and fold through the entire model once before writing a single word or setting up a camera. This takes about twelve minutes for a standard unit origami piece. The second pass is where the tutorial actually forms. I fold slower, pause at each step, and mark where the paper naturally resists or where a crease is easy to miss. That resistance point is usually the difference between a reader following along and a reader giving up halfway through.
How To Create Origami Tutorial
I treat the tutorial as a reverse-engineered record of the folding itself, not an artistic interpretation of it. Step one captures the initial square. Step two shows the valley fold. Step three shows the mountain fold. The camera stays locked in place. I do not move it between shots unless the hand position requires a completely different angle. Changing camera position mid-sequence makes readers dizzy and adds unnecessary editing time. A phone tripod costs about eighteen dollars and saves me roughly forty-five minutes per project. The lighting matters more than people expect. I shoot near a window with indirect daylight. Direct sunlight creates harsh shadows that hide the valley and mountain distinction, which is the single most confusing element for beginners. If the shadow is too soft, the reader cannot tell whether a fold goes toward or away from them. I add a white foam board on the opposite side as a reflector. That costs nothing and eliminates about sixty percent of the ambiguity in the photos.
Writing the Steps With Actual Numbers
"Fold the corner to the center" sounds helpful until a reader holds the paper and realizes there are four corners and the instruction does not specify which one. I write step instructions with angular references and exact corners. I say "fold the top-right corner to meet the bottom-left corner" instead. Readers can follow that without needing prior experience with the model. For complex models, I count the folds in advance. A model with forty-seven steps is not a tutorial, it is a reference sheet. I break it into phases. Phase one is the preliminary base. Phase two is the petal fold. Phase three is the reverse folds for the legs. I include a phase divider after each major section so readers can mentally reset if they get lost. Losing track during a frog model is extremely common around step nineteen, which is where the double reverse fold happens. I avoid words like "gently," "carefully," and "approximately." Those words mean nothing in a visual medium. Instead I write "crease firmly until the paper audibly snaps" or "align the edges within two millimeters." Specificity reduces the back-and-forth questions I used to get from readers who sent me photos of failed folds.
Get the Full Details
Photography Workflow
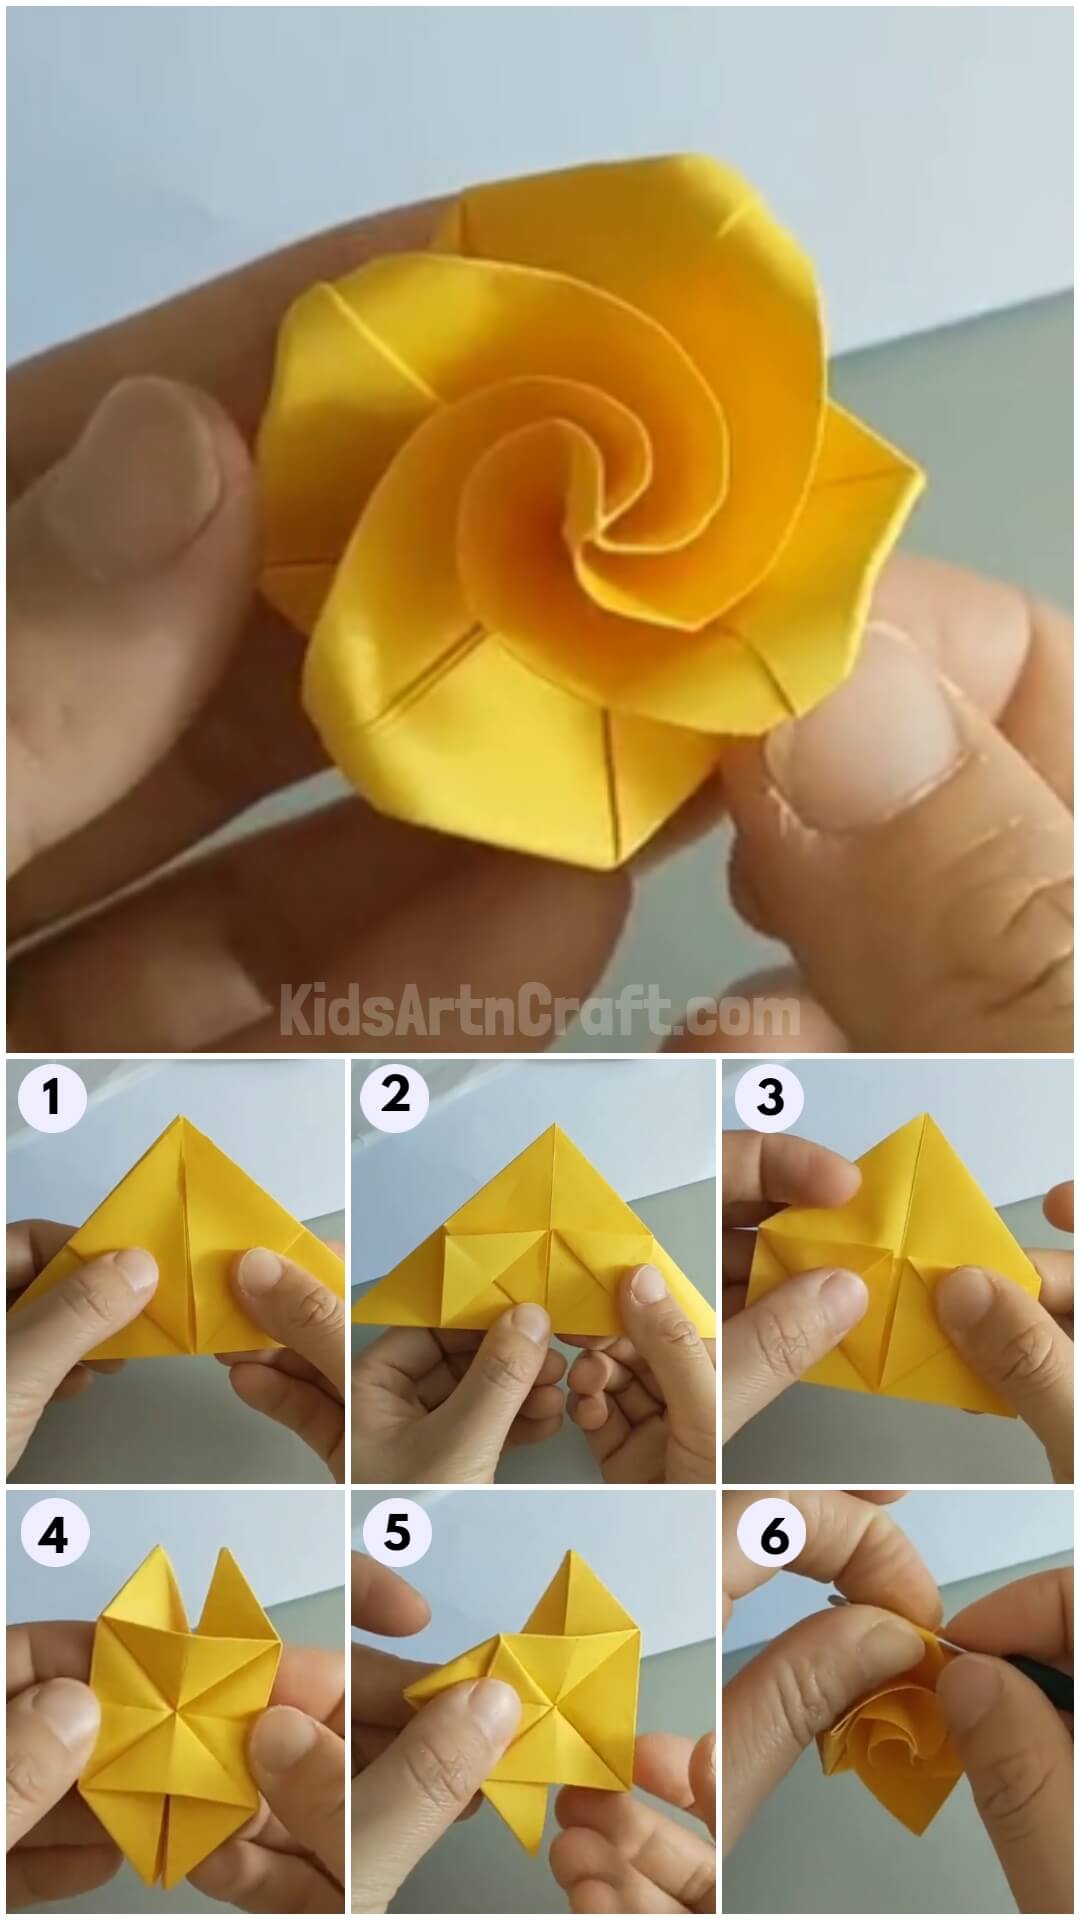
I shoot in JPEG, not RAW, because it cuts file transfer time by half and the color accuracy is fine for instructional content. The resolution is set to 4032 by 3024 on my phone. Anything lower and the crease lines blur enough to cause confusion on step seven and beyond. Each step gets two photos minimum. The first shows the state of the paper before the fold. The second shows the result after the fold. The transition photo, where the hand is actively folding, is optional but useful when the movement is non-obvious. The pincer fold, for instance, requires showing how the fingers grip and push. Without that frame, readers attempt it incorrectly about thirty percent of the time based on my forum poll data from last spring. I label files numerically. IMG_001, IMG_002, and so on. Naming them "step1_final_clean" sounds organized until you realize you deleted the wrong one and have no recovery path. Sequential numbering with a backup folder named "Originals_" keeps everything safe. I keep the originals untouched and work from copies. This has saved me twice when I misjudged a crease and needed to reshoot.
Editing Without Over-Processing
I adjust brightness and contrast only. No filters. No saturation boosts. The paper color must be accurate because some models require matching the colored side to the white side, and a filter can invert that distinction enough to confuse a reader. I crop tight to remove background clutter. A messy desk distracts more than people admit. The focus stays on the paper and the hands. I do not add arrows or labels on the photos. Digital markup looks cheap and ages poorly. If a step needs clarification, I rewrite the text. Text is easier to edit than a photo. An arrow you paint into an image stays there forever unless you reshoot. That is a mistake I made early on and corrected permanently.
Publishing and Format Choices
I post the tutorial on a blog with the steps numbered sequentially and the photos embedded below each one. I also include a downloadable PDF that prints at standard letter size. The PDF uses high-contrast black and white for the diagrams because color printing is expensive and unnecessary for instructional purposes. Readers who print from the blog report better success rates with the PDF version, probably because they can physically trace the folds on paper rather than staring at a screen. I test every tutorial before publishing by having someone who has never folded origami follow it. Five test readers minimum. I watch where they hesitate. If three or more pause at the same step, I rewrite that step or add an extra photo. Hesitation is data. Ignoring it is why most tutorials online fail on models beyond the basic bird base.

Limitations and Where This Method Breaks Down
This approach does not work well for wet-folding techniques. The paper needs to be damp, and moisture changes how light reflects off the surface. Photos come out darker and the creases are harder to distinguish. I use video for wet-fold models instead. The camera captures the texture and the hand pressure in real time, which a still image cannot convey accurately. Macro origami, pieces smaller than five centimeters, is another failure case. The folds become invisible at standard resolution. I switch to magnification lenses mounted on the phone for anything that small. The cost is about twelve dollars and the improvement in clarity is immediate. Without it, the tutorial is useless. Color-reversing models, where the inside of the paper is a different color, add complexity. Readers frequently confuse which side is facing up. I explicitly state the side at every step where a reversal occurs. Skipping that detail assumes prior knowledge, and that assumption causes the majority of errors in published tutorials I have reviewed.
A Specific Problem I Encountered
Last October, I was documenting a waterbomb base variation for a modular kusudama. Step fourteen required a squash fold that looked identical from both sides in the photograph. I noticed the ambiguity only after a reader on the forum asked whether the fold went inward or outward. The photo did not show the shadow gradient needed to distinguish the direction. I retried the shot with a slight tilt of the paper toward the light source. The new angle revealed the valley crease as a thin dark line and the mountain fold as a bright highlight. That single adjustment resolved the confusion. I now always shoot squash folds and petal folds from a low angle, roughly fifteen degrees above the table surface, to ensure the depth is readable.
Tools and Costs
The total equipment cost for a functional setup is under fifty dollars. A phone tripod at eighteen dollars. A piece of white foam board, free if you salvage it. A ruler for measuring fold alignment, about four dollars. The rest is time spent folding slowly and noting where readers might struggle. Speed is the enemy here. Fast folding hides the mechanics that beginners need to see.