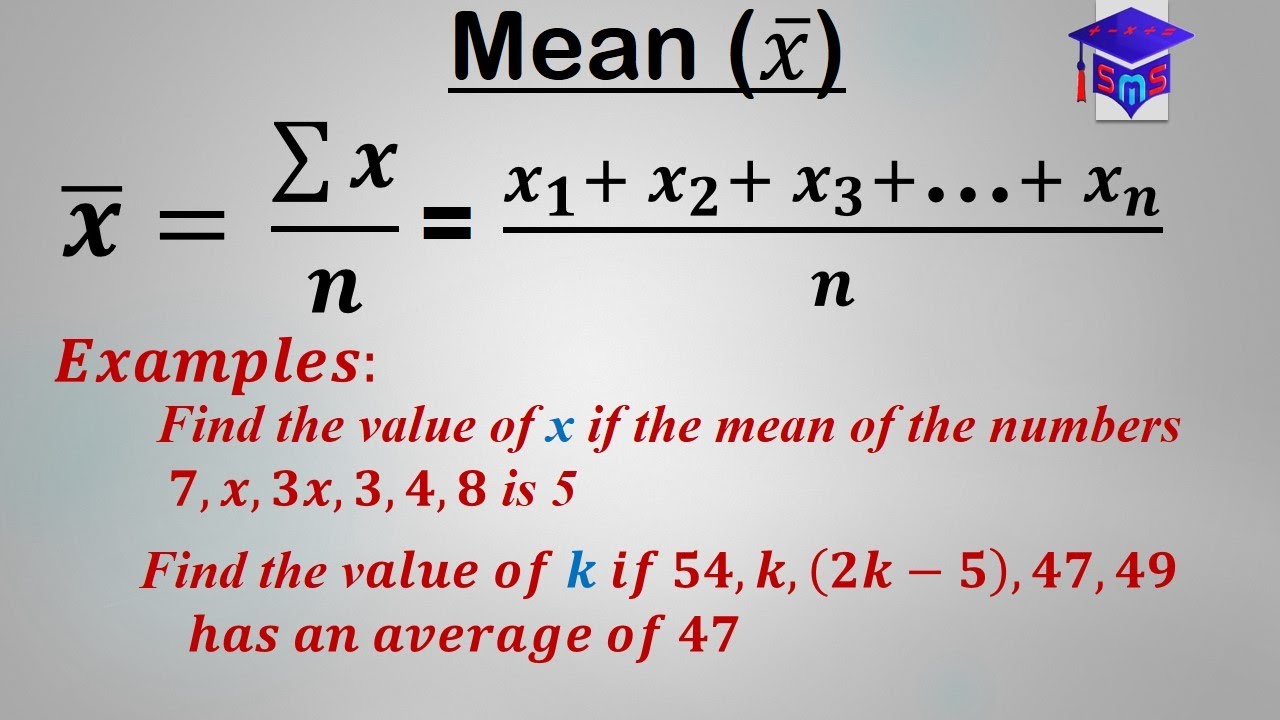The Average Nobody Ever Gets Right
You add up numbers and divide by how many there are. That is the mean. Most people learn this in elementary school and then never think about it again until they encounter a spreadsheet that refuses to cooperate. The simple definition does not cover what happens when the data fights back. I spent a quarter dealing with support ticket resolution times for a customer service platform. The manager wanted a single number to represent typical performance. We calculated the mean and it came out to 4.7 days. Everyone looked bad. The median was 1.1 days. The problem was roughly three percent of tickets involved account migrations that took two to three weeks due to database dependencies. Those outliers dragged the mean way past where the typical experience actually sat. I ended up trimming the top and bottom five percent, reporting the trimmed mean at 1.4 days alongside the median. The executive summary changed completely.
How To Do Mean In Math
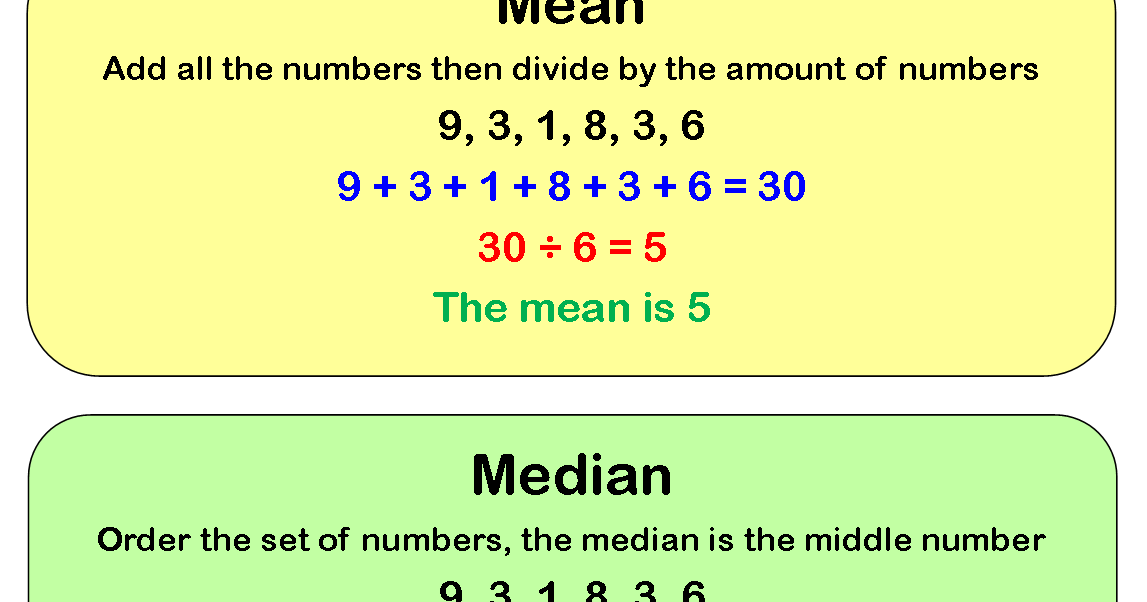
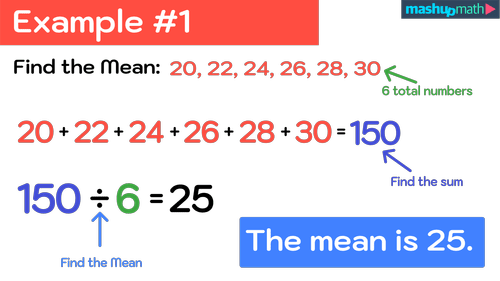
Write down every value you need to average. Add them together. Count how many values you have. Divide the sum by the count. If you are working with grouped data where each value appears multiple times, multiply each unique value by its frequency, sum those products, and divide by the total frequency. That gives the same result but saves you from writing out sixty-seven identical entries by hand. The arithmetic mean has a property beginners miss. The sum of the deviations from the mean always equals zero. This means the mean is the balancing point of the dataset. If one value goes up, something else has to shift to compensate. This is why the mean is sensitive to extreme values. A single massive outlier pulls the balance point toward it. The median does not care about that pull. It only cares about position. Another thing that trips people up is that the mean of combined groups is not the average of the group means unless the groups are the same size. Say Group A has ten values averaging 50 and Group B has one hundred values averaging 60. The combined mean is not 55. It is 59. You have to weight each group mean by its sample size. I see this mistake constantly in report reviews where someone averages quarterly averages to get an annual figure without accounting for different transaction volumes per quarter. The error compounds fast.
Use the mean when your data is roughly symmetric and free of extreme outliers. Stop using it when your distribution is heavily skewed or contains measurement errors that need to be removed before calculation. For income data, hospital stay durations, or house prices, the median usually tells the actual story. The mean tells a different story, and sometimes that different story is the one you need. Know which one you are looking for before you calculate. There is also the question of when not to calculate a mean at all. Circular data, like time of day or wind direction, breaks the mean. The average of 11 PM and 1 AM is not 6 PM. It is 12 AM. You need a circular mean for that. Nominal data, like favorite color or product category, has no meaningful mean. Do not average categorical labels just because your software will let you. I have seen dashboards where someone averaged a coded severity score that used labels like low medium high and got a number that mapped to nothing recognizable in the actual scale. When you do need the mean and your dataset is large enough that manual addition is impractical, spreadsheet functions handle it reliably. SUM divided by COUNT works. AVERAGE does the same thing with slightly different handling of empty cells and text. If you are cleaning data first, remove the text and blanks explicitly before averaging so you do not get a silent inclusion error.
Get the Full Details
The mean remains the most used average in practical work because it uses every data point and plays nicely with further statistical operations. Standard deviation, variance, and regression all build on it. That utility comes with the cost of sensitivity. Know your data shape before you trust the number.