Working Out Standard Deviation By Hand
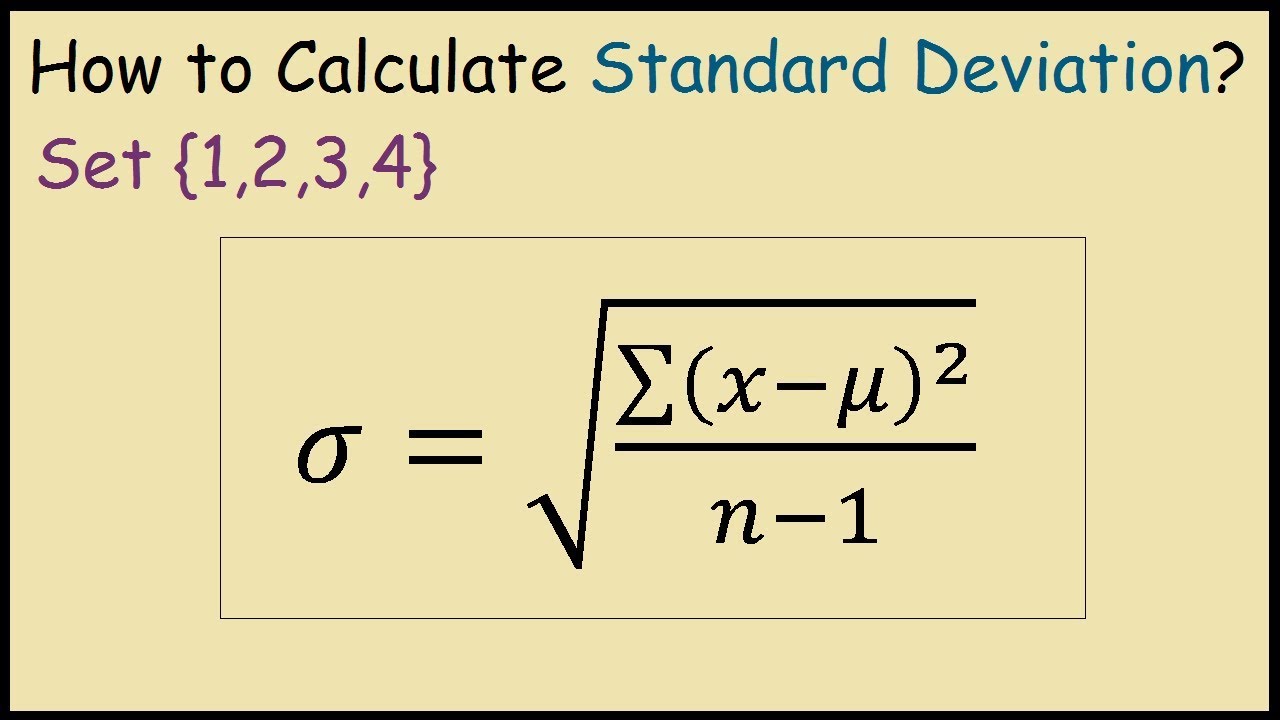
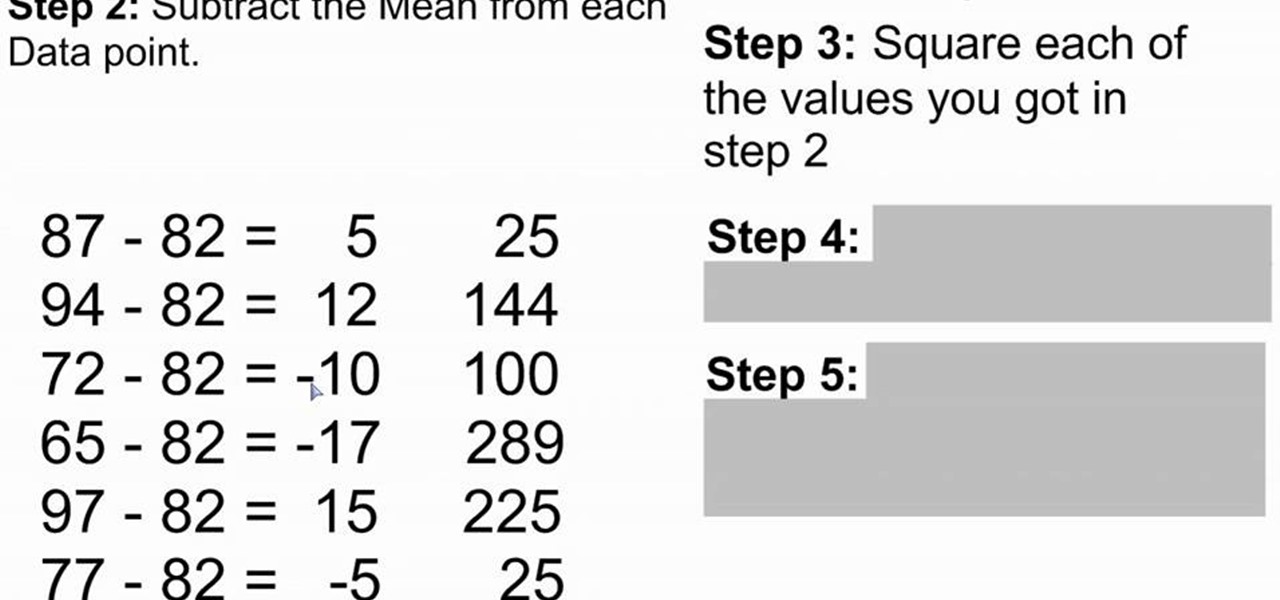
Most people mess this up on the first try because they skip a step. I see it constantly when I'm reviewing spreadsheets or helping teams clean their data pipelines. The formula itself is straightforward, but the mechanics trip everyone up at some point. Here is how it actually works. Start with your dataset. Let's say you have these five numbers: 4, 7, 2, 9, 5. The first thing you do is calculate the mean, which is just the average. Add them all up, then divide by the count. 4 plus 7 plus 2 plus 9 plus 5 equals 27. Divide by 5 and you get a mean of 5.4. Next, subtract the mean from each individual data point. This gives you the deviations. For our example: 4 minus 5.4 is -1.4. 7 minus 5.4 is 1.6. 2 minus 5.4 is -3.4. 9 minus 5.4 is 3.6. And 5 minus 5.4 is -0.4. Now square every single one of those results. Negative 1.4 squared is 1.96. 1.6 squared is 2.56. 3.4 squared is 11.56. 3.6 squared is 12.96. 0.4 squared is 0.16. These are all positive now because squaring wipes out the negative sign.
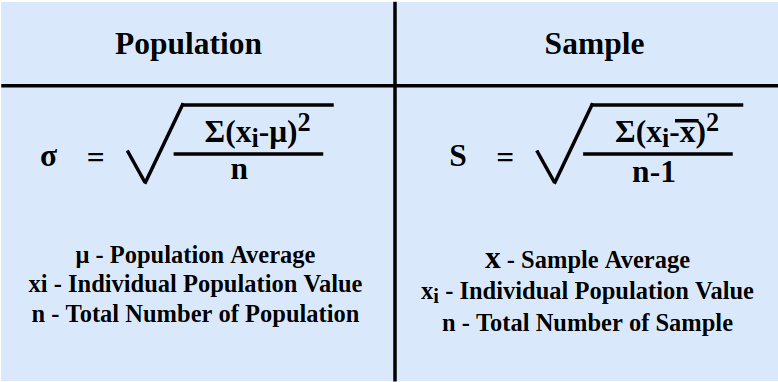
Add those squared values together. You get 29.2. Then divide by either n minus 1 or n depending on whether you're working with a sample or a population. This is where most people make mistakes. If your five numbers represent the entire group you care about, divide by 5. That gives you 5.84. If those five numbers are just a sample pulled from a larger population, divide by 4 instead, which gives you 7.3. The distinction matters more than people think. Finally, take the square root of that result. For the population method, the square root of 5.84 is about 2.42. For the sample method, the square root of 7.3 is roughly 2.70. That number is your standard deviation. I should mention something that doesn't show up in textbooks. When I was building a real-time monitoring system a few years back, I ran into a problem with standard deviation on streaming data. The naive approach of recalculating from scratch on every incoming data point was killing our CPU. The dataset was growing to millions of records per day. I had to implement Welford's online algorithm instead, which updates the mean and sum of squared differences incrementally. It's O(1) per update instead of O(n), and it avoids the floating point precision issues that creep in when you repeatedly subtract large numbers. That saved us from rewriting half the pipeline.
Here is another thing nobody warns you about. Standard deviation assumes your data is roughly normally distributed for the interpretation to make any real sense. If you have heavily skewed data, like revenue figures or response times with a long right tail, the standard deviation becomes nearly useless as a summary statistic. The number will be massive but not particularly descriptive. In those cases, interquartile range or median absolute deviation tells you way more about what is actually happening. I learned that the hard way when I was debugging a logging system that showed absurd standard deviations on latency metrics. The distribution was log-normal, not normal, and nobody on the team had checked that before trusting the stats. There are other practical issues worth noting. Standard deviation is sensitive to outliers. A single extreme value can inflate the number dramatically, making a dataset look far more spread out than it actually is for the vast majority of observations. You should always check for outliers before relying on this metric alone. Another limitation is that standard deviation only captures linear spread. If your data clusters in two distinct groups, the standard deviation will suggest moderate spread across a range where there are actually no data points at all. The metric is blind to multimodal distributions. If you want to automate this in practice, most people use Python with numpy or pandas, or Excel with the STDEV.S and STDEV.P functions. The manual calculation method I described above is useful for understanding what the software is doing, but you should not be doing it by hand unless you have a very small dataset and no tools available. For anything beyond a handful of values, the computational shortcut formulas work fine, but they reintroduce the floating point drift issue I mentioned earlier with Welford's method being the safer alternative for large or streaming datasets.
Get the Full Details