Getting The Center Right When Your Data Isn't Clean
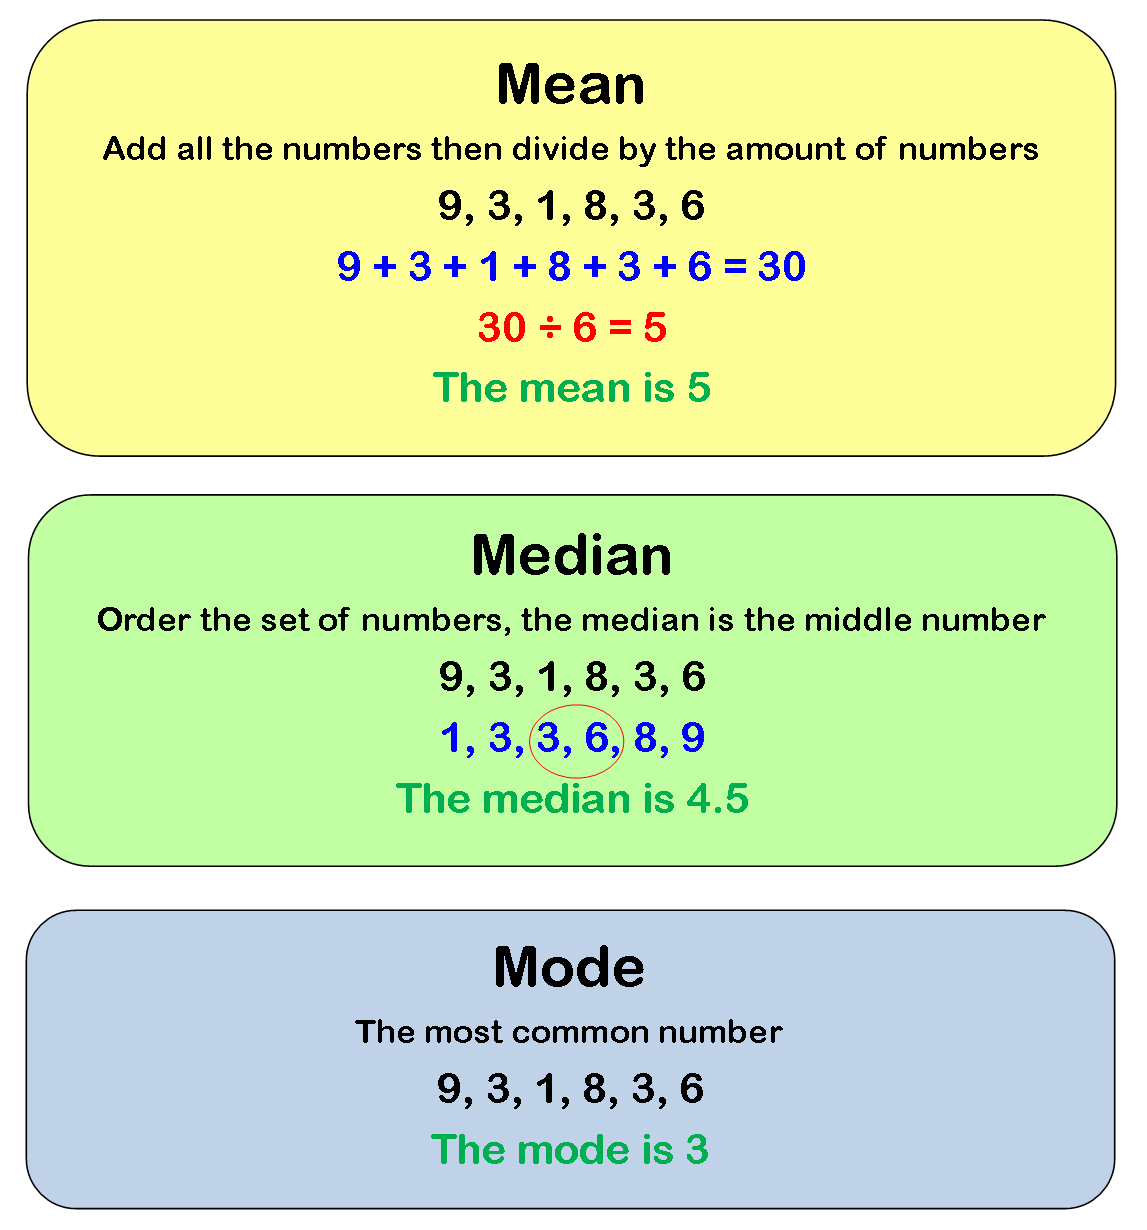
Most people learn mean, median, and mode as three separate formulas they memorize for a test and forget by lunch. In practice, figuring out which measure to use and how to calculate it without second-guessing yourself is a completely different problem. I spent years cleaning sales data for retail chains and the messiest datasets always came from POS systems that recorded returns as negative numbers, mixed in some employee purchases at cost instead of price, and had a handful of products listed under wrong categories. One particular dataset for a grocery chain had 14,000 transaction records where the mode was useless because 87 percent of the SKUs appeared fewer than five times, and the median was being dragged around by a few hundred extreme-value orders from a wholesale account that had inflated the top end of the distribution. The workaround was to segment the data by customer type before calculating anything, then run the three measures on each segment separately. That single step changed the reported median by nearly 18 percent compared to the raw aggregate number. Start by getting your numbers into order. Mean calculation is the most straightforward part: add every value together and divide by the count of values. If you have a list of 200 daily store revenue figures, sum them and divide by 200. The mean for that sample turned out to be 3,412 dollars, but that number alone told a misleading story because the wholesale account I mentioned above contributed four transactions worth 47,000 dollars each. Those outliers pulled the mean well above what any typical day looked like. The median fixes that distortion. Arrange all values from lowest to highest and pick the middle one. With an even number of observations like 200, take the average of the 100th and 101st values. In that same dataset, the median came in at 2,180 dollars, which was far closer to what actually happened on most days. The mode was the least helpful measure here. The most frequent daily revenue figure appeared only twice across the entire dataset, which is a common pattern with continuous or near-continuous data. I learned to skip the mode entirely for that kind of distribution and focus on median and mean together. For categorical data like product type preferences or survey responses, the mode becomes useful again because the values repeat. A restaurant chain survey about favorite menu items might show "burger" as the mode at 34 percent of responses, which is actually informative. The trick is knowing when the mode carries weight and when it is just noise. There are edge cases that trip people up regularly. One of the most common is handling zeros correctly. If you are calculating the mean ticket size for a business and some transactions are exactly zero because of voided orders or returns, including those zeros in the mean calculation will deflate the result. Whether you include or exclude them depends on what question you are actually trying to answer. Including them answers "what is the average per attempted transaction." Excluding them answers "what is the average per completed transaction." I used to default to excluding zeros without thinking about it, which systematically biased my revenue metrics downward. Now I flag the decision explicitly in whatever report I am producing. Another pitfall is treating the mode as a substitute for the median when a distribution is heavily skewed. I once saw a logistics team use the mode delivery time to set customer expectations because it was a clean round number. The mode happened to be two hours faster than the median because the left tail of early deliveries pulled it down. Customers were told one thing and got another. The median would have been the honest choice there.
When skew is present, the mean shifts toward the tail and the median stays anchored. This is the practical takeaway most beginners miss. In a right-skewed income distribution, the mean can be 40 to 60 percent higher than the median depending on how heavy the tail is. That gap is not a calculation error. It is a feature of the data. Reporting both numbers side by side is usually the clearest way to communicate what is happening. If you only report the mean for a skewed distribution, you are hiding information. If you only report the median, you are also hiding something about the magnitude of the extreme values. For income data specifically, I routinely calculate the mean-to-median ratio as a quick diagnostic. A ratio above 1.5 almost always signals enough skew to warrant a separate discussion about the tail. A ratio below 1.15 means the distribution is close enough to symmetric that the two measures will tell roughly the same story. For grouped data where you do not have individual observations but only frequency tables, the calculations change slightly. The mean for grouped data uses the midpoint of each class interval multiplied by its frequency, summed and divided by the total frequency. The median requires finding the cumulative frequency to locate the median class, then interpolating within that class using the formula. Mode for grouped data uses the modal class and a similar interpolation approach. These approximations are standard but introduce their own error. I worked on a census project where using raw data versus grouped data shifted the estimated median household income by about 2.3 percent. The difference was small in absolute terms but large enough to affect policy thresholds in a couple of districts. Always note whether your numbers come from raw or grouped data and avoid comparing them directly without acknowledging the approximation layer.
When These Measures Break Down
Mean, median, and mode are not universal solutions. They fail predictably under certain conditions. Bimodal or multimodal distributions are the most obvious failure point for any single summary measure. A hospital scheduling dataset might show two peaks because morning appointments cluster around 30 minutes and afternoon procedural consults cluster around 75 minutes. The mean would land somewhere around 52 minutes, which describes neither group accurately. The median would be similarly unhelpful. The mode would pick one of the two peaks arbitrarily unless you split the data by appointment type first. In cases like this, segmenting the data and reporting separate measures per segment is the only honest path. Merging the segments back together just produces a number that sounds precise but is functionally meaningless. Ordinal data without equal intervals should never be averaged. This is a mistake I see constantly in business reports. Likert scale survey results are ordinal. The distance between "agree" and "strongly agree" is not mathematically guaranteed to equal the distance between "neutral" and "agree." Treating them as interval data and computing a mean is technically incorrect, though some statisticians accept it as a reasonable approximation when the scale has seven or more points and the distribution is roughly symmetric. Even then, the median is the safer choice. I usually report the median response and the distribution of responses rather than collapsing a Likert scale into a single average number. Open-ended distributions present another problem. If your dataset includes uncensored values like "more than 10 years" or "over 500 units," the mean cannot be calculated accurately without making assumptions about the tail. The median can still work if the middle falls in the censored region, but it will be approximate. In one inventory project, we had supplier lead times reported as "greater than 90 days" for about 12 percent of entries. Using the mean led to a planning system that was perpetually understocked because the actual tail was much longer than any fixed replacement value would suggest. We switched to median-based replenishment thresholds and accepted that the mean was unknowable until those censored observations could be resolved through direct supplier contact.
Get the Full Details
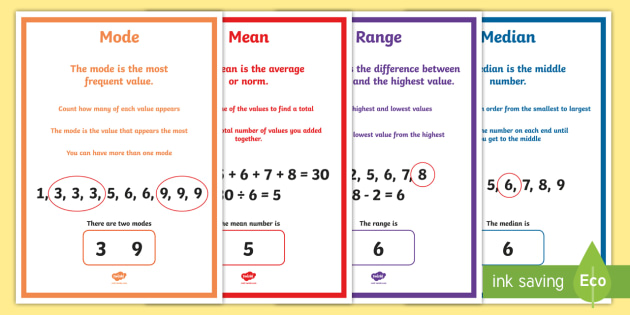
The practical workflow I use now is simple and takes about 10 minutes for most datasets. First, sort the data and inspect the distribution visually or through a quick frequency table. Second, calculate the mean and median side by side and check their ratio. Third, compute the mode only if the data is categorical or the distribution has clear repeating values. Fourth, identify any segments or subpopulations that need separate treatment. Fifth, decide whether to report all three measures or to explain why one or two should be omitted. This process usually catches the kind of issues that make published averages look wrong. The time investment is small compared to the cost of acting on a distorted central tendency. I still keep a printed cheat sheet on my desk for the grouped-data formulas because pulling them up from memory takes longer than glancing at the sheet during a live meeting. The raw-data formulas are straightforward enough to use without notes, but the interpolation steps for grouped median and mode are easy to fumble when you are doing them cold. The core principle that matters most is not memorizing any formula. It is recognizing that each measure answers a different question and choosing the one that matches the question you actually need to answer.