The basics nobody actually explains well
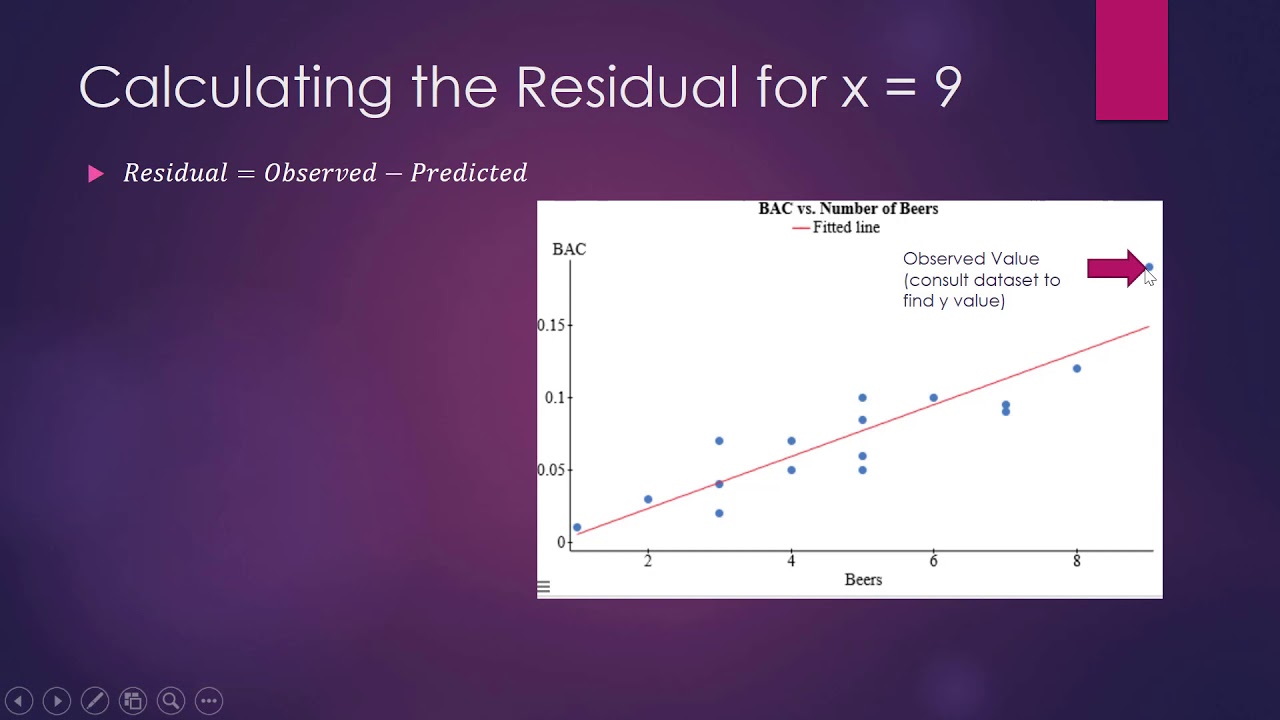
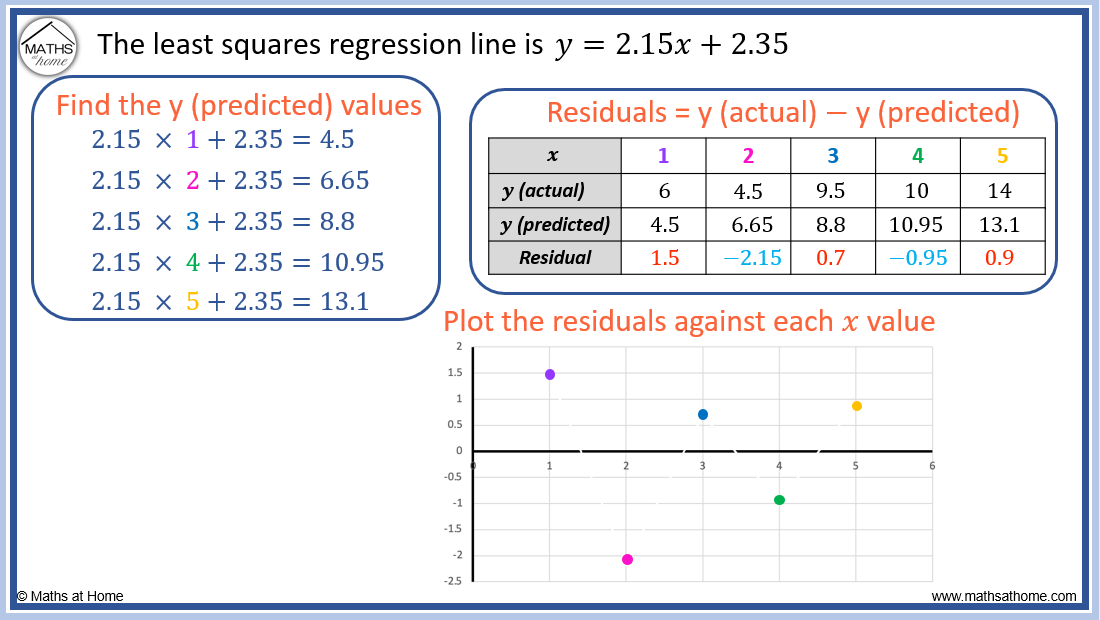
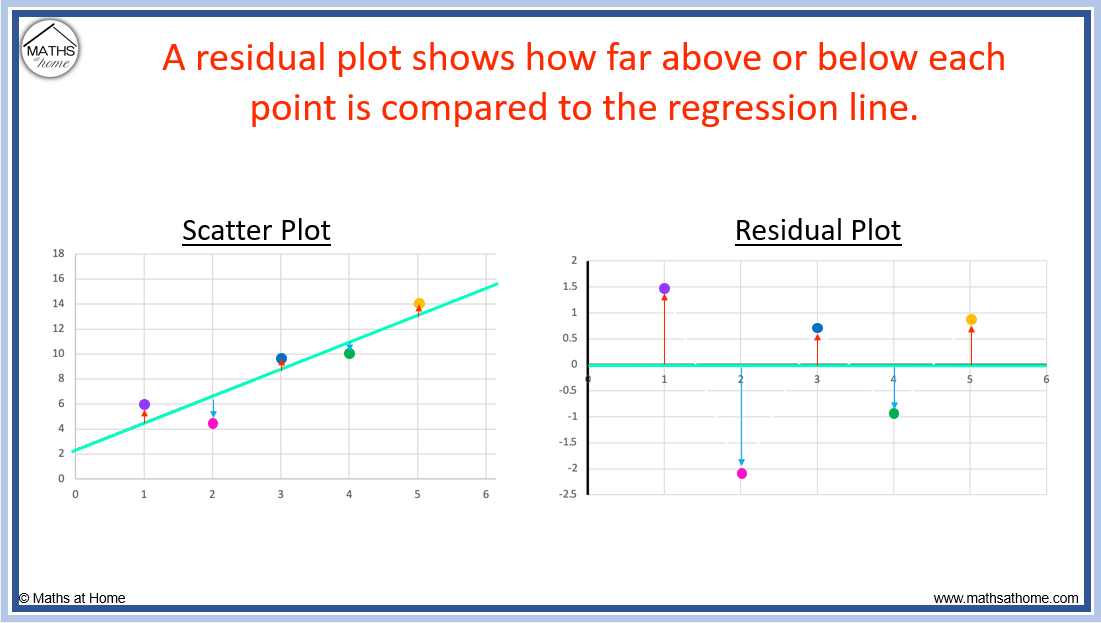
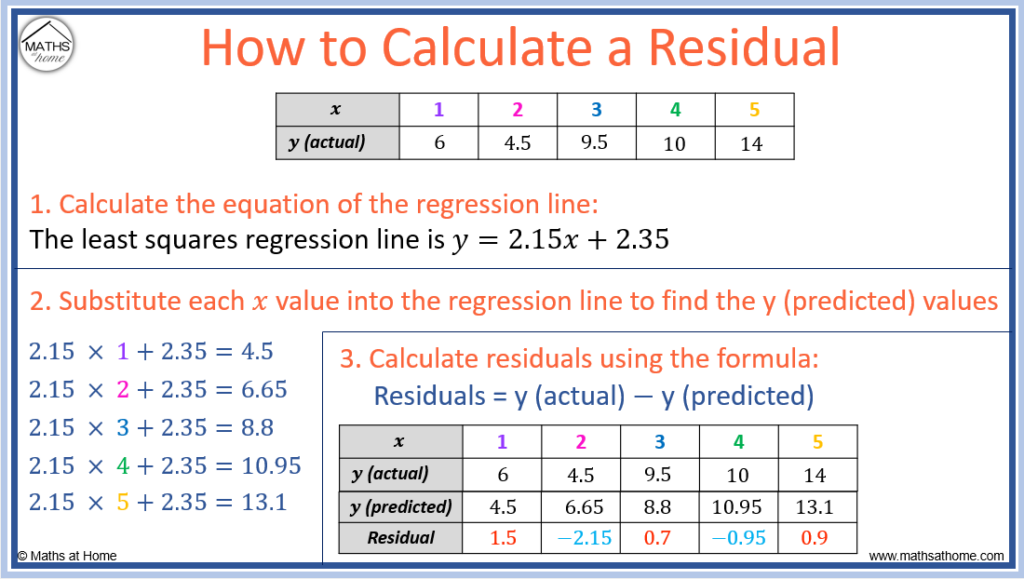
Residuals are just the difference between what actually happened and what your model predicted. That's it. You subtract the fitted value from the observed value for every data point. It sounds so simple that people often overcomplicate it, especially when they're dealing with regression output from whatever software they're using. Here's how to actually find them in practice. Run your regression model first, get your coefficients, then calculate the predicted values. For each observation, subtract that predicted y-hat from the actual y you observed. The result is your residual. Store them in a new column, plot them against the fitted values, and you've got a basic diagnostic picture.
How To Find A Residual in Python
If you're using statsmodels or scikit-learn, the calculation is usually one line. With statsmodels OLS, the fitted model object has a .resid attribute that spits out the residual vector directly. With sklearn, you do it manually by taking y_test minus model.predict(X_test). Both approaches give you the same numbers if the model converged the same way. The statsmodels route is faster because it handles the centering and degrees of freedom corrections automatically. I remember spending about three hours once chasing a weird pattern in my residual plot that turned out to be nothing more than a sign error in how I'd defined the subtraction. I had written predicted minus observed instead of observed minus predicted. The absolute values were identical, so the magnitude checks passed, but the sign confusion threw off every diagnostic test I ran after that. Standardized residuals flipped direction, the Breusch-Pagan test gave opposite conclusions, and I was genuinely confused until I just printed out ten raw residuals by hand and compared them to the output. Once I flipped the subtraction order, everything lined up. Now let me tell you about something most guides skip. Residuals are not the same thing as errors. Your model never sees the true errors because you don't know the actual data generating process. What you get from residuals are estimates based on fitted parameters, and those estimates inherit all the uncertainty from your coefficient estimates. This distinction matters when you're doing inference on the residuals themselves, like running a Ljung-Box test for autocorrelation on regression residuals. The test statistics are approximately valid, but they're not exact because you've already used up degrees of freedom fitting the model. With small samples, this can push p-values off enough to change your conclusion.
Another thing people get wrong is assuming that summing residuals to zero means your model is good. It means nothing of the sort. Ordinary least squares always produces residuals that sum to zero by construction, regardless of whether your model fits the data at all. A model with completely nonsense coefficients will still have residuals that sum to zero. What actually matters is the structure, or lack thereof, in the residual pattern. When residuals show a clear funnel shape, where the spread widens or narrows as fitted values increase, that's heteroscedasticity. You can fix it with weighted least squares or by switching to robust standard errors. The fixed effect estimation in panel data also changes how residuals behave, and the within-transformation residuals don't follow the same distributional assumptions as plain OLS residuals. If you're working with clustered data, cluster-robust standard errors become necessary, and the residual diagnostics need to account for the clustering structure too.
Get the Full Details

Standardized and studentized residuals
Raw residuals are hard to interpret because their variance isn't constant across observations. Standardized residuals divide each residual by an estimate of its standard deviation, giving you values that are roughly comparable across the dataset. Studentized residuals go further by recalculating the model fit without each observation in turn, giving a more accurate measure of leverage impact. If you're hunting for outliers, use studentized residuals. Values outside the plus or minus three range are worth investigating seriously. Raw residuals will mislead you here because high-leverage points pull the regression line toward them, shrinking their own residuals and hiding the problem. I ran into this exact issue last year on a housing price dataset. The R-squared was decent, the overall F-test was significant, and the residual plot looked fine at a glance. But when I calculated the studentized residuals, three observations had values above four. Removing them improved the model's adjusted R-squared by about eight percentage points and eliminated the heteroscedasticity pattern entirely. Those three points were luxury properties in the lowest income neighborhood, which made intuitive sense once I thought about it, but the raw residuals kept them hidden.
Common pitfalls to avoid
Don't rely on residual plots alone. They're useful but subjective and can be misleading, especially with large datasets where even tiny patterns look dramatic. Run formal tests alongside visual inspection. Don't ignore the leverage and influence metrics. Cook's distance and DFBETAS tell you which observations are distorting your coefficients, and they catch problems that residual plots miss entirely. Don't assume normality of residuals is required for prediction. It's required for valid confidence intervals and hypothesis tests on the coefficients, but if you only care about point predictions, the normality assumption doesn't matter as much. Don't apply transformations without checking whether they actually improve the residual diagnostics. Adding a log transform because someone told you to without examining the residual pattern first just moves the problem elsewhere. Residual analysis is one of those skills that gets harder the more data you have, not easier. With ten thousand observations, you can spot patterns anywhere. The key is learning what normal noise looks like versus what a real structural problem looks like, and that only comes from running diagnostics on dozens of different models across different domains.