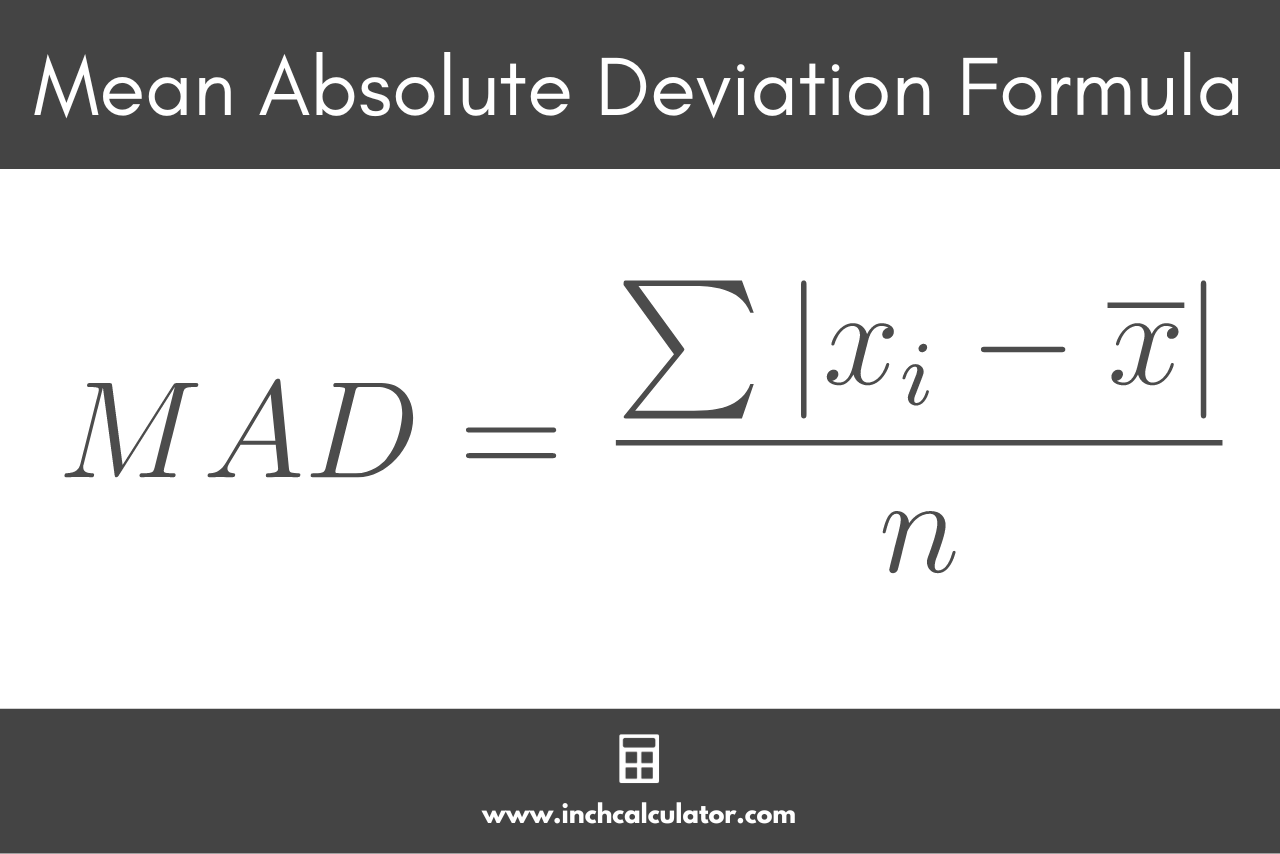Getting the Numbers Right
I keep seeing people confused about this in stats forums. The concept is straightforward but the execution trips people up because of how the order of operations gets mangled. Here is the actual process.
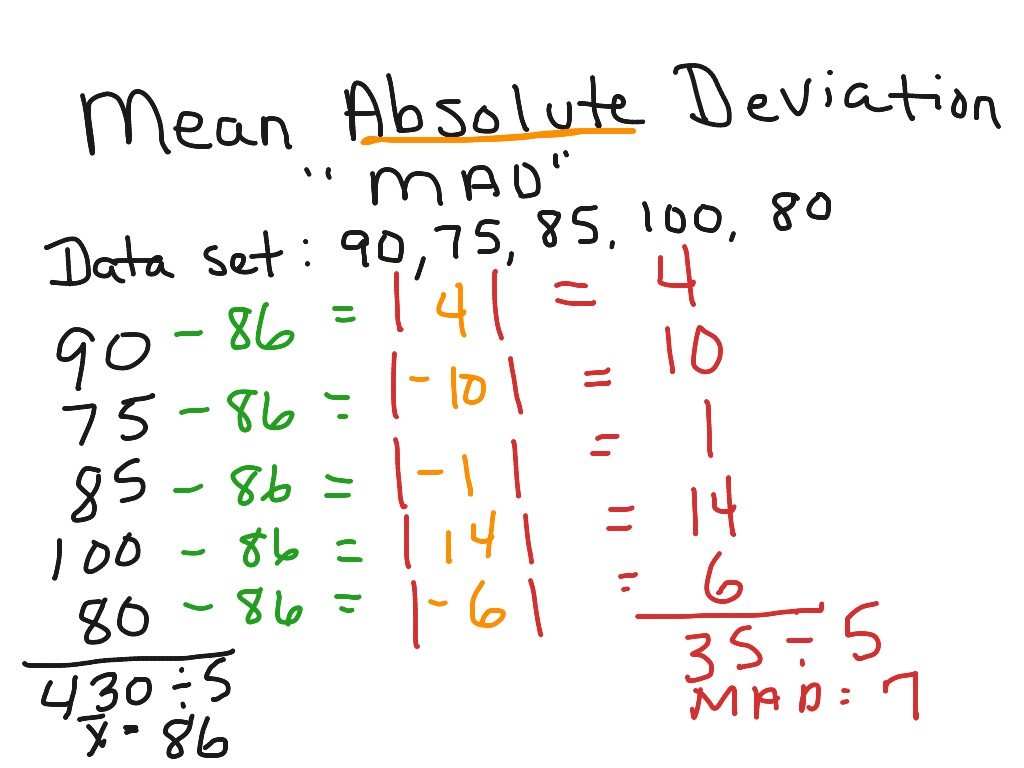
First you need your mean. Add up every data point in your set and divide by how many items there are. That gives you the average value around which everything clusters. Then for each individual number in your dataset, subtract the mean from it. Take the absolute value of that result. Absolute value means you drop any negative sign. Whether the deviation is positive or negative doesn't matter here, only the distance from the mean matters. Finally, add up all those absolute deviations and divide by the count of data points. That final number is your mean absolute deviation, sometimes called MAD.
How To Find Absolute Deviation From Mean
Let me walk through a real example so you see it. Say your data is: 4, 7, 9, 12, 18. The mean is 4 plus 7 plus 9 plus 12 plus 18 divided by 5, which equals 10. Now the individual deviations from the mean:
|4 minus 10| = 6 |7 minus 10| = 3 |9 minus 10| = 1
Get the Full Details
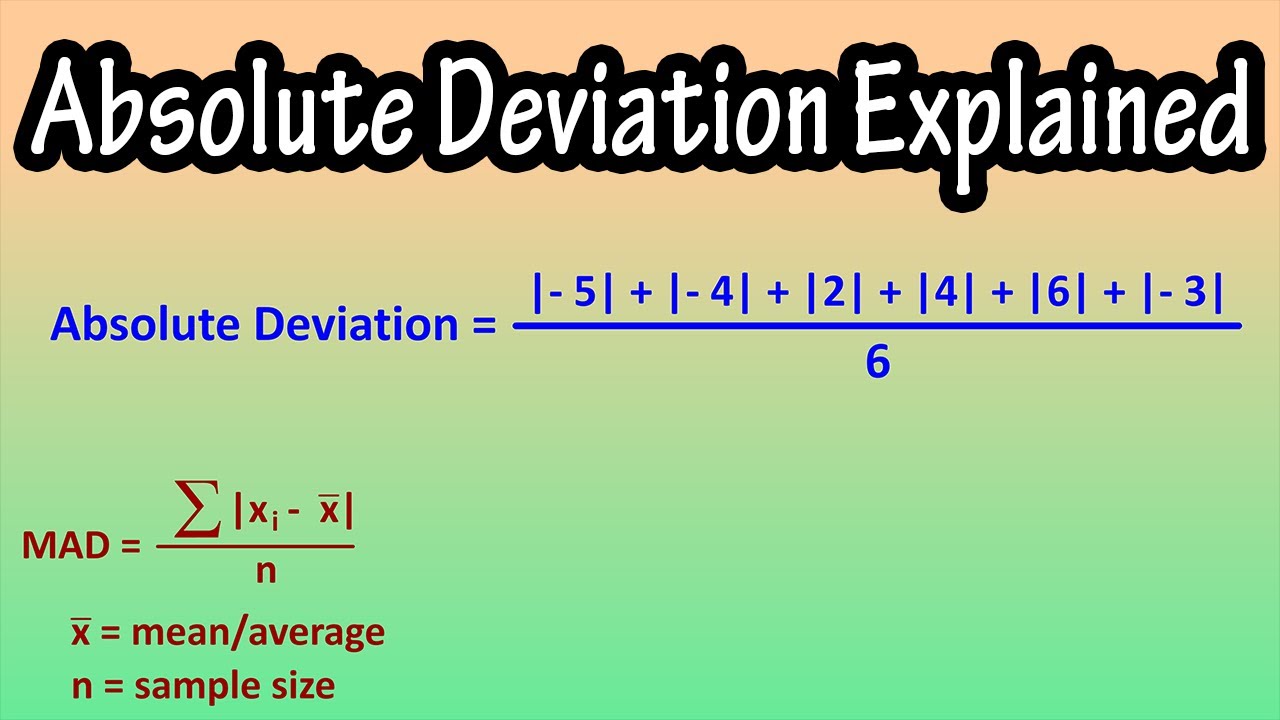
|12 minus 10| = 2 |18 minus 10| = 8 Add those together: 6 plus 3 plus 1 plus 2 plus 8 equals 20. Divide by 5 data points and you get 4. Your mean absolute deviation is 4.
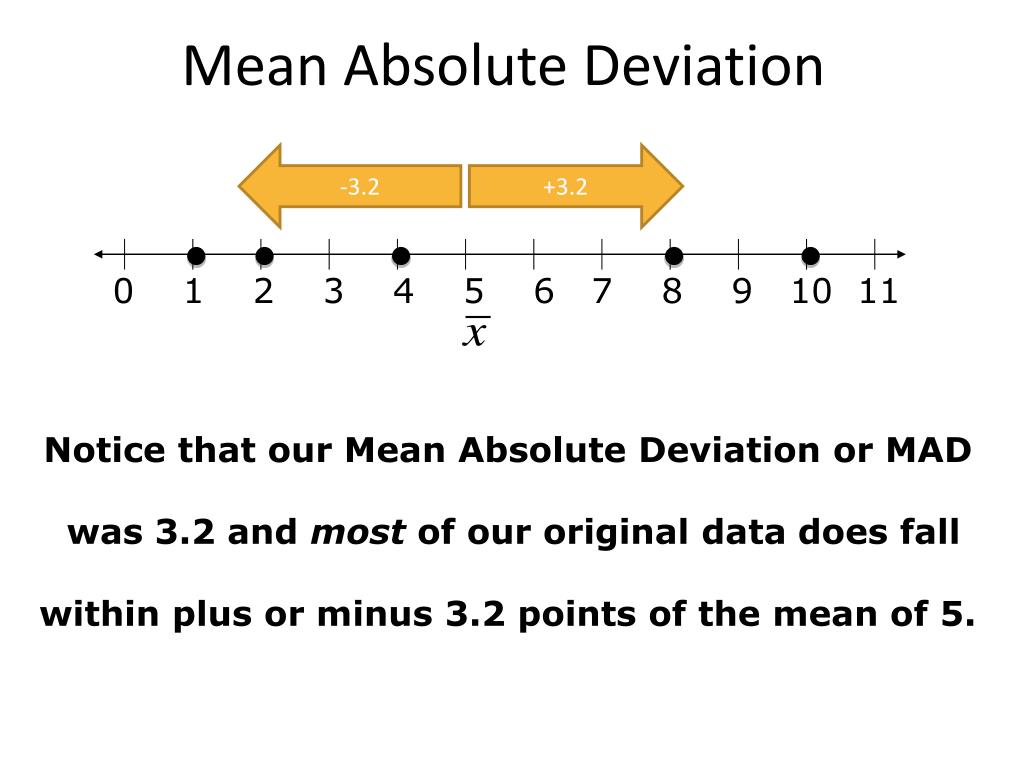
That means on average each value sits 4 units away from the mean of 10. It is a measure of spread, similar to standard deviation but using absolute values instead of squaring. I used to do these calculations by hand back when I was doing field work in environmental testing. One time I had a dataset of 200 water sample readings where the mean absolute deviation was throwing off my quality control charts. The problem was that three values were missing from the automated readout. I ended up having to manually compute MAD for the incomplete set, then cross-reference against the raw logbook entries to figure out what those three numbers should have been. Took me about forty minutes that could have been done in five if someone had caught the gap earlier. I started building a quick spreadsheet template after that and haven't done manual MAD calculations for anything over fifty data points since.
What People Miss About This Metric
Most beginners treat MAD and standard deviation as interchangeable. They are not. MAD uses absolute values while standard deviation squares every deviation before averaging, then takes the square root. That squaring step gives more weight to outliers. If your dataset has extreme values, MAD will stay closer to the center of the distribution while standard deviation gets pulled further away. Another thing nobody explains clearly: MAD is less sensitive to outliers, which sounds like a feature until it isn't. In fields like finance or engineering where outliers carry important signal, that robustness becomes a liability. You might miss a genuine anomaly because MAD smooths it over. There is also the assumption that MAD tells you something about normal distribution. It doesn't. Standard deviation assumes normality for confidence intervals and z-scores. MAD does not have that same statistical machinery behind it. If you need to do hypothesis testing, you are better off converting MAD to an approximate standard deviation using the relationship that roughly divides MAD by 0.7979, but that is an approximation and introduces its own error.
The biggest practical limitation: MAD only describes spread around the mean. It says nothing about the shape of the distribution. Two datasets can have identical means and identical MAD values but look completely different when plotted. One could be tightly clustered while the other is bimodal with two peaks far apart. Always visualize your data before relying on MAD alone. If you are working with large datasets regularly, you can calculate this in Excel using the AVEDEV function. It computes mean absolute deviation directly without manual step-by-step work. For Python, numpy or scipy do not have a built-in MAD function but you can write a one-liner: mean of absolute differences from the mean using numpy.abs and numpy.mean together.