Counting Degrees in Graphs Without Overcomplicating It
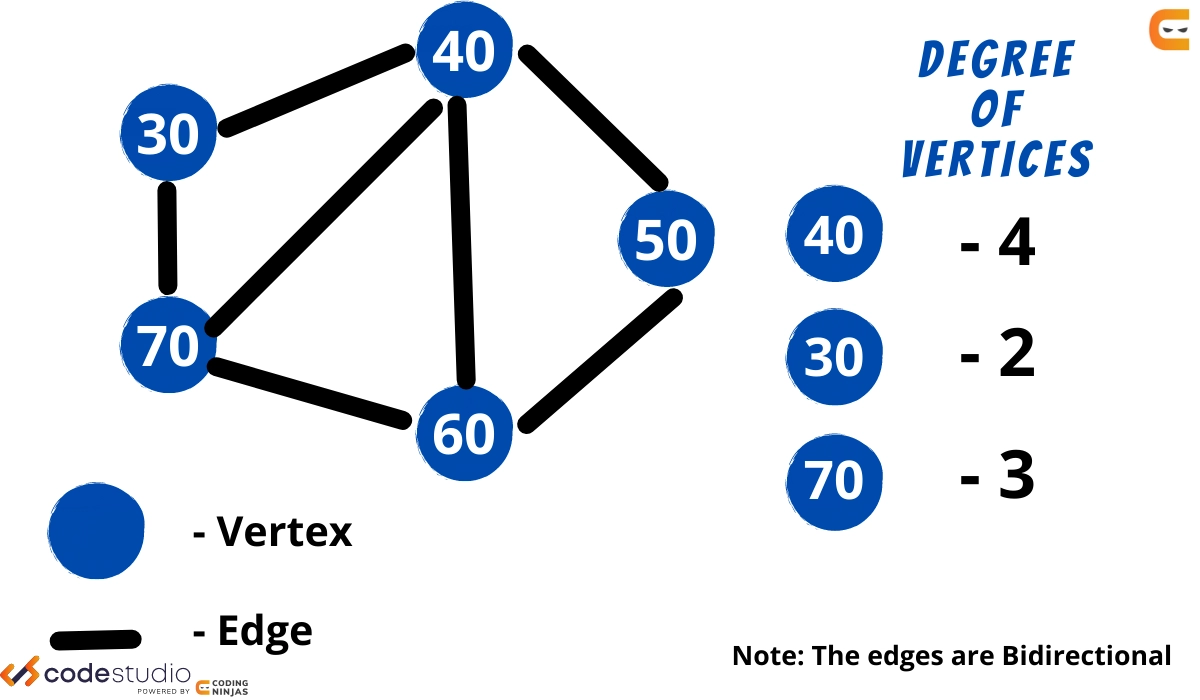
The degree of a vertex is just the number of edges touching it. In a directed graph, you split that into in-degree (edges coming in) and out-degree (edges going out). That's the whole concept. The part people mess up is the implementation, especially when they start working with large datasets or sparse representations. There are really three standard ways to represent a graph, and your approach changes depending on which one you're using. An adjacency matrix is a square 2D array where row i and column j tell you whether an edge exists between vertex i and vertex j. To find the degree, you sum across the row (or down the column for directed graphs).
This is straightforward but eats memory like crazy. An adjacency matrix for a graph with 100,000 vertices is 10 billion entries. Even as booleans, that's 10 GB. You wouldn't use this for anything beyond maybe a few thousand nodes unless you have a reason to do random access lookups constantly. The time complexity is O(V²) for construction and O(1) per degree query after that, which sounds nice until V gets big.
Adjacency List
This is what you'll actually use most of the time. Each vertex holds a list of its neighbors. The degree of a vertex is simply the length of its list in an undirected graph. In a directed graph, in-degree requires summing the lengths of all lists that reference that vertex, or maintaining a separate incoming-edges structure. Construction is O(V + E), which is optimal. Degree queries on the vertex itself are O(1) since you're just reading the list length. The catch is in-degree in directed graphs — there's no free way to get it without preprocessing or storing the reverse graph separately.
Get the Full Details

Edge List
An edge list is just a list of pairs. It's the simplest representation and the one most data imports give you directly. Finding degrees from an edge list requires scanning every edge and tallying up. You use a hash map or dictionary keyed by vertex ID, incrementing counters as you iterate through edges. Time complexity is O(E). Space is O(V) for the counter table. This is usually the right starting point. Take the edge list, build an adjacency list or degree counter in one pass, then do whatever analysis you need off that.
Practical Implementation Notes
Here's how I'd actually write this in Python for a typical workflow: For undirected graphs using an adjacency list: from collections import defaultdict
graph = defaultdict(list)
edges loaded somehow
for u, v in edge_list:
graph[u].append(v)
graph[v].append(u)
degree of vertex n
degree = len(graph[n])
For directed graphs where you need both in-degree and out-degree, maintain two structures: out_degree = defaultdict(int)
in_degree = defaultdict(int)
for u, v in edge_list:
out_degree[u] += 1
in_degree[v] += 1 This is cleaner than building full adjacency lists if you only need degree information. Processing a million edges through this takes maybe two seconds on a normal machine. The defaultdict approach avoids key existence checks and keeps it tight.
The Problem With Isolated Vertices
This caught me once on a project where I was analyzing a network of user interactions. I built the graph from an edge list and computed degrees using defaultdict. When I queried for the total number of vertices with degree zero, the answer was wrong. The defaultdict simply never created entries for vertices that had no edges at all. If your vertex set isn't given upfront, you won't know which ones are isolated unless you explicitly track them. The workaround is simple: initialize the degree counters with all known vertices before processing any edges, or do a second pass to identify missing vertices by comparing against the full vertex set. In the user interaction case, I had a separate list of all user IDs from the database, so I did: all_vertices = set(user_ids_from_db)
for v in all_vertices:
out_degree.setdefault(v, 0)
in_degree.setdefault(v, 0)
That fixed it. The isolated users showed up correctly. This is one of those things that doesn't come up in tutorials but will waste your afternoon if you don't expect it.
Common Pitfalls
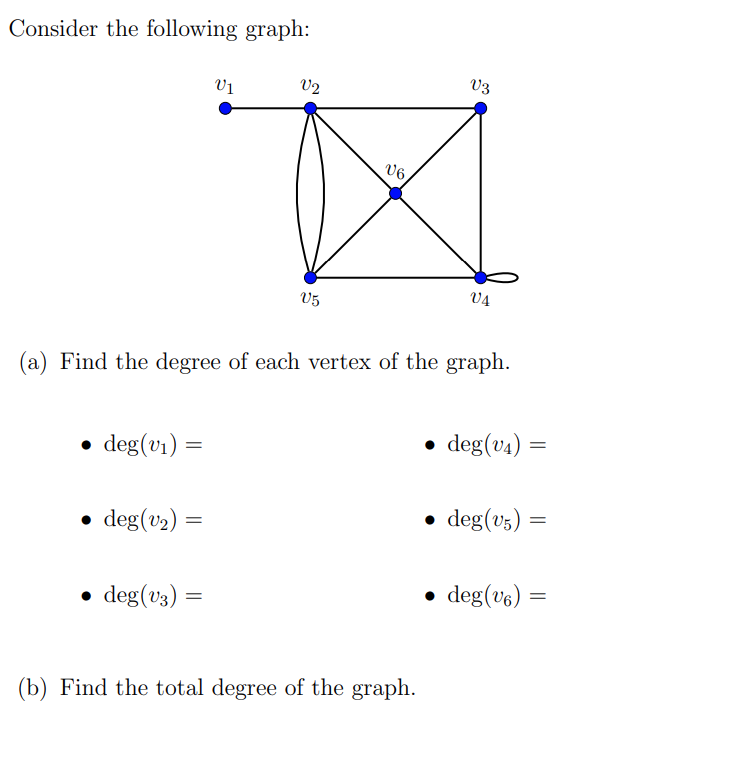
Self-loops are the first thing to watch. A self-loop contributes 2 to the degree in an undirected graph, not 1. If you're counting from an adjacency list where a vertex appears in its own neighbor list, you'll undercount by 1 for each self-loop. Edge lists have the same issue — you need to detect when u equals v and handle it explicitly. Multigraphs compound this. Multiple edges between the same pair of vertices each count toward the degree. An adjacency set won't work here; you need a list or a counter. I've seen people use sets for adjacency because "duplicates don't matter" and then wonder why their degree sums are too low on graphs with parallel edges. Weighted graphs don't change the degree definition. Degree counts edges, not weight. If you need something that incorporates weight, that's a different metric entirely, sometimes called strength or weighted degree. Don't conflate the two.
Large-Scale Considerations
When you're dealing with graphs that don't fit in memory, the single-pass edge list approach still works if you stream the edges. Sort the edge list by vertex ID first, then do a linear scan accumulating counts. This is O(E log E) for the sort but uses minimal memory. For something like the Twitter social graph with billions of edges, this is basically the only approach that doesn't require a distributed system. NetworkX handles this kind of thing well for medium-sized graphs. Its degree() method abstracts away the representation details. But NetworkX overhead becomes real around 100,000 vertices and 500,000 edges if you're doing repetitive queries. The raw dictionary approach above is faster and uses a fraction of the memory. I switched my pipeline from NetworkX to custom defaultdict structures on a social graph project and went from about 45 minutes of processing down to roughly eight minutes.
When Degree Alone Isn't Enough
Degree distribution is useful for identifying hubs and understanding network structure, but it has blind spots. A star graph and a path graph can have the same degree sequence but very different properties. Degree doesn't capture clustering, reachability, or community structure. If you're using degree as a feature for something like node ranking or anomaly detection, combine it with betweenness centrality or eigenvector centrality. Those take longer to compute but give you information degree quietly ignores. For most practical work, building the degree counters from an edge list in a single pass and being careful about self-loops, multiedges, and isolated vertices covers 90 percent of cases. The rest depends on what you're actually trying to do with the numbers.