Getting Past the Basics
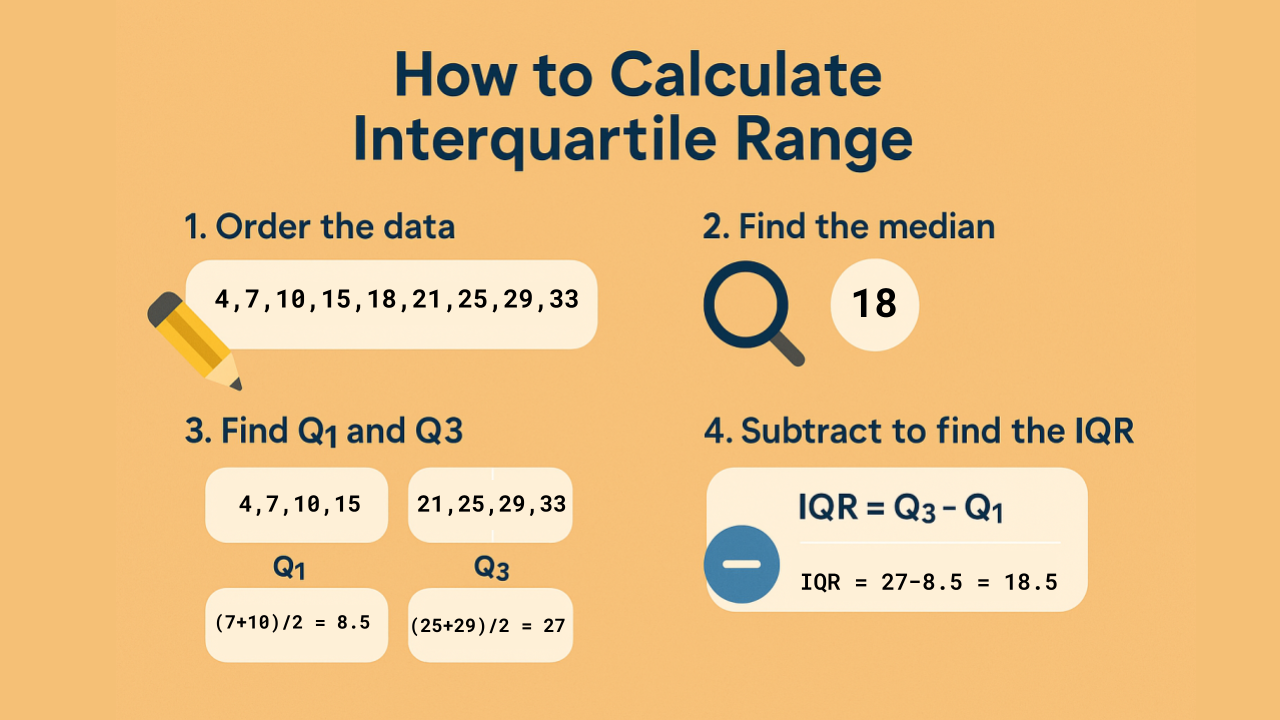
The interquartile range is just the spread of the middle fifty percent of your data. Q3 minus Q1. That's it. But anyone who's actually had to use it on real-world datasets knows that getting the right answer takes more than plugging numbers into a formula. The method you choose changes the result when your dataset is small, and Excel and Python will sometimes disagree with each other. Start by sorting your data from smallest to largest. Then find the median, which splits the set in half. The median of the lower half is Q1 and the median of the upper half is Q3. Subtract Q1 from Q3 and you have your IQR. Here's where people mess it up. When you have an odd number of values, do you include the median itself in both halves or exclude it? If your dataset has 9 values, the median is the 5th value. Do you split into a lower half of four and an upper half of four, or a lower half of five and an upper half of five? Different sources say different things, and the discrepancy shows up most when you're working with small samples. The convention I've seen used most often in practice is to exclude the median from both halves when the total count is odd. It matters. I've seen it change Q1 by one full data point in a dataset of about 30 values.
Take this example. Say your data is 3, 7, 8, 10, 12, 15, 16, 19, 24. Nine values. The median is 12. The lower half is 3, 7, 8, 10 and the upper half is 15, 16, 19, 24. Q1 is the average of 7 and 8, which is 7.5. Q3 is the average of 16 and 19, which is 17.5. The IQR is 10. If you include the median in both halves instead, Q1 becomes the median of 3, 7, 8, 10, 12, which is 8, and Q3 becomes the median of 12, 15, 16, 19, 24, which is 16. Now the IQR is 8. Same data, different answer depending on which method you pick. I ran into this exact problem a few years back while cleaning up a dataset for a logistics analysis. The client was using a spreadsheet tool that included the median in both halves, and I was using a Python script that excluded it. We got two different IQRs from the same numbers, which threw off the outlier detection entirely. The workaround was just to standardize on the exclusion method across the board and document it in the data dictionary so nobody would second-guess the discrepancy later. Took about ten minutes to fix and saved us from weeks of back-and-forth.
Tools and What They Actually Do
Excel uses a method called Method 1 for percentile calculations, which means its quartile values can drift from what you'd calculate by hand, especially on small datasets. Python's numpy uses linear interpolation by default, and pandas gives you options. R has three different methods built into its quantile function alone. If you're comparing results across tools, always check which interpolation method each one is using. It's not a bug, it's just how the math works out differently depending on who wrote the code. For anything over a few hundred data points, the differences between methods tend to be negligible. The range collapses to roughly the same answer whether you use exclusive or inclusive splitting. It's only below about 30 values that you really need to pay attention.
Get the Full Details

Outlier Detection and the Fence Problem
The IQR's most common use is flagging outliers. The standard approach is to multiply the IQR by 1.5 and mark anything below Q1 minus 1.5 times the IQR or above Q3 plus 1.5 times the IQR as an outlier. This is the Tukey fence method, named after John Tukey who came up with it in the 1970s. Here's something most people don't realize about this approach. The 1.5 multiplier isn't a law of nature. It's a heuristic that works well for roughly normal distributions. When your data is heavily skewed, which happens a lot in real datasets, that fence can end up including or excluding way more points than you'd expect. I've seen income data where the 1.5 IQR fence flagged nearly forty percent of legitimate observations as outliers because the distribution was so right-skewed. In those cases, switching to a 3x multiplier for "extreme outliers" helps separate the noise from the actual anomalies. Another thing worth knowing: the IQR completely ignores the tails of your distribution. Two datasets can have identical IQRs and median and mean but look nothing alike. One might be tightly clustered while the other has extreme values that don't show up in the IQR at all. If you're relying on IQR as your sole measure of spread, you're getting an incomplete picture. Pair it with something like the standard deviation or a box plot for a fuller view.
When IQR Fails You
The IQR breaks down when your dataset has very few unique values. A Likert-scale survey with answers from 1 to 5, for example, might have Q1 equal to Q3, giving you an IQR of zero. The method still runs, but it tells you nothing useful about spread because there simply isn't enough variation in the middle of the distribution. In those cases, look at the full frequency table instead of bothering with the IQR. It also doesn't work well for ordinal data where the distances between ranks aren't meaningful. If you're ranking customer satisfaction as "poor," "fair," "good," "excellent," calculating an IQR on those ranks is mathematically possible but statistically misleading because the gap between poor and fair isn't the same as the gap between good and excellent. For skewed data with heavy tails, the IQR will give you a narrow range that makes your dataset look more consistent than it actually is. A box plot alongside the IQR number will reveal that mismatch immediately. Don't skip the visualization step just because you have a clean number.
If you need a single spread metric that accounts for every data point equally, the standard deviation is the better choice. If you need robustness against outliers but still want a range-based measure, the IQR is solid. Pick the right tool for what you're actually trying to measure instead of defaulting to whichever one you remember from statistics class.