Margin of error is not a mystery most people let sit around too long
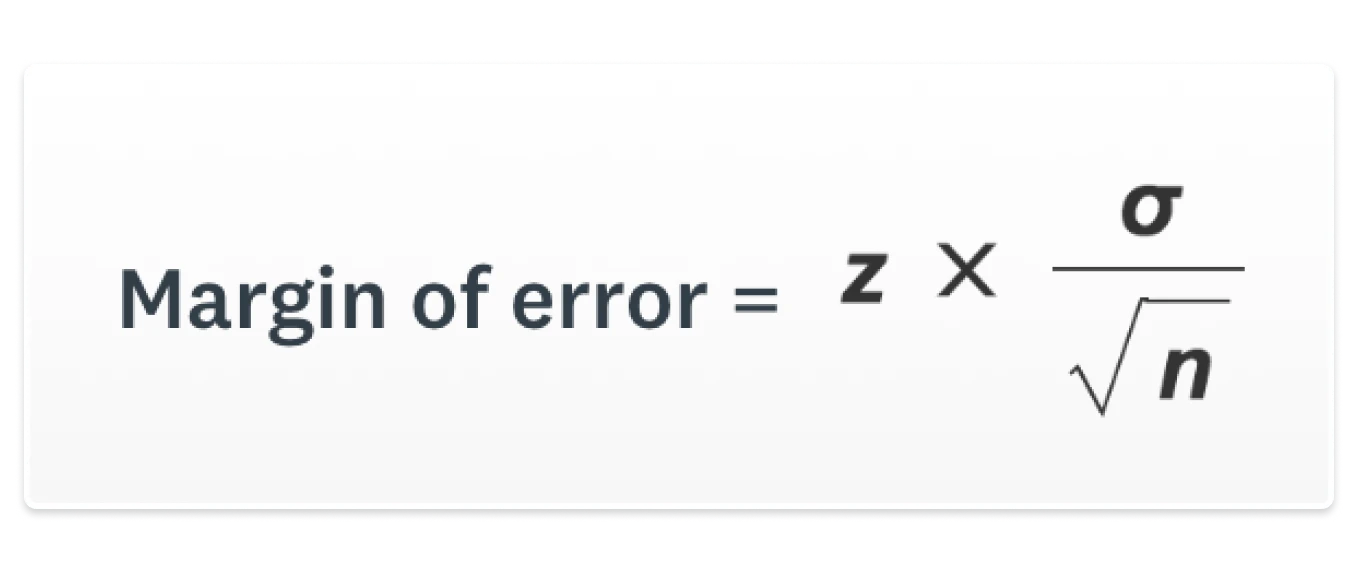
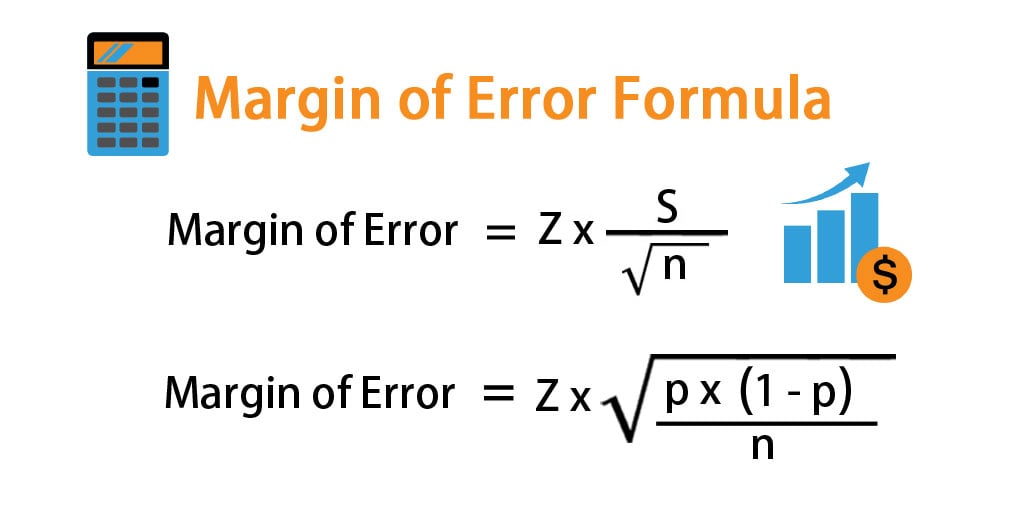
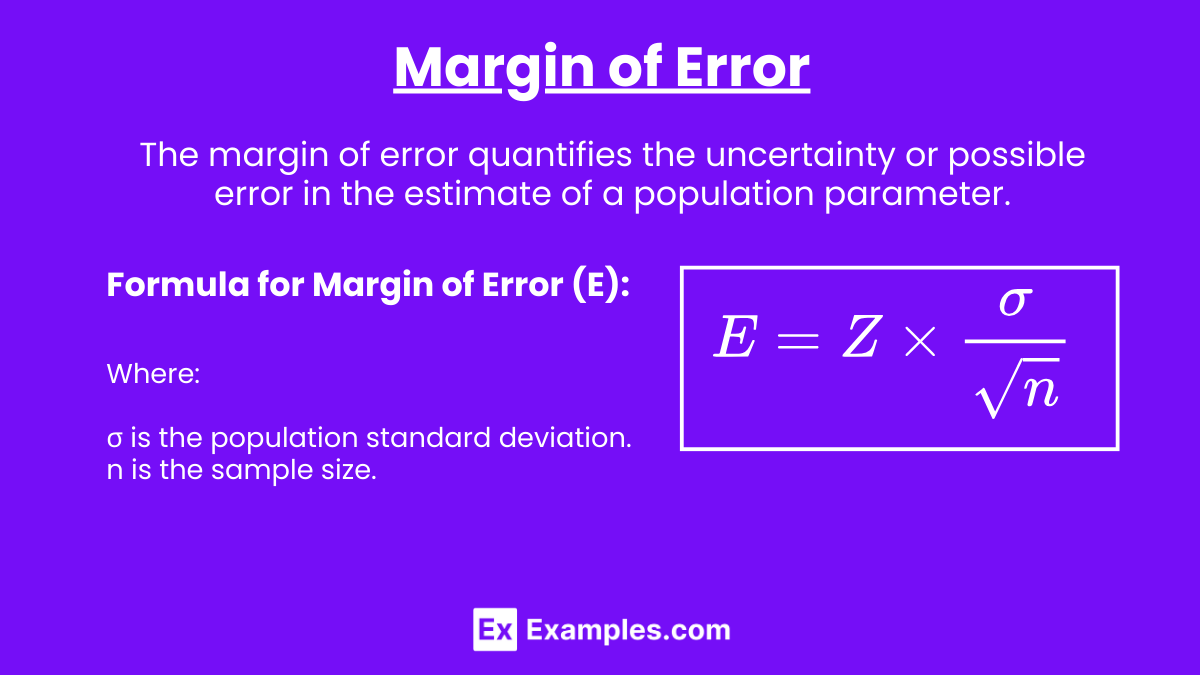
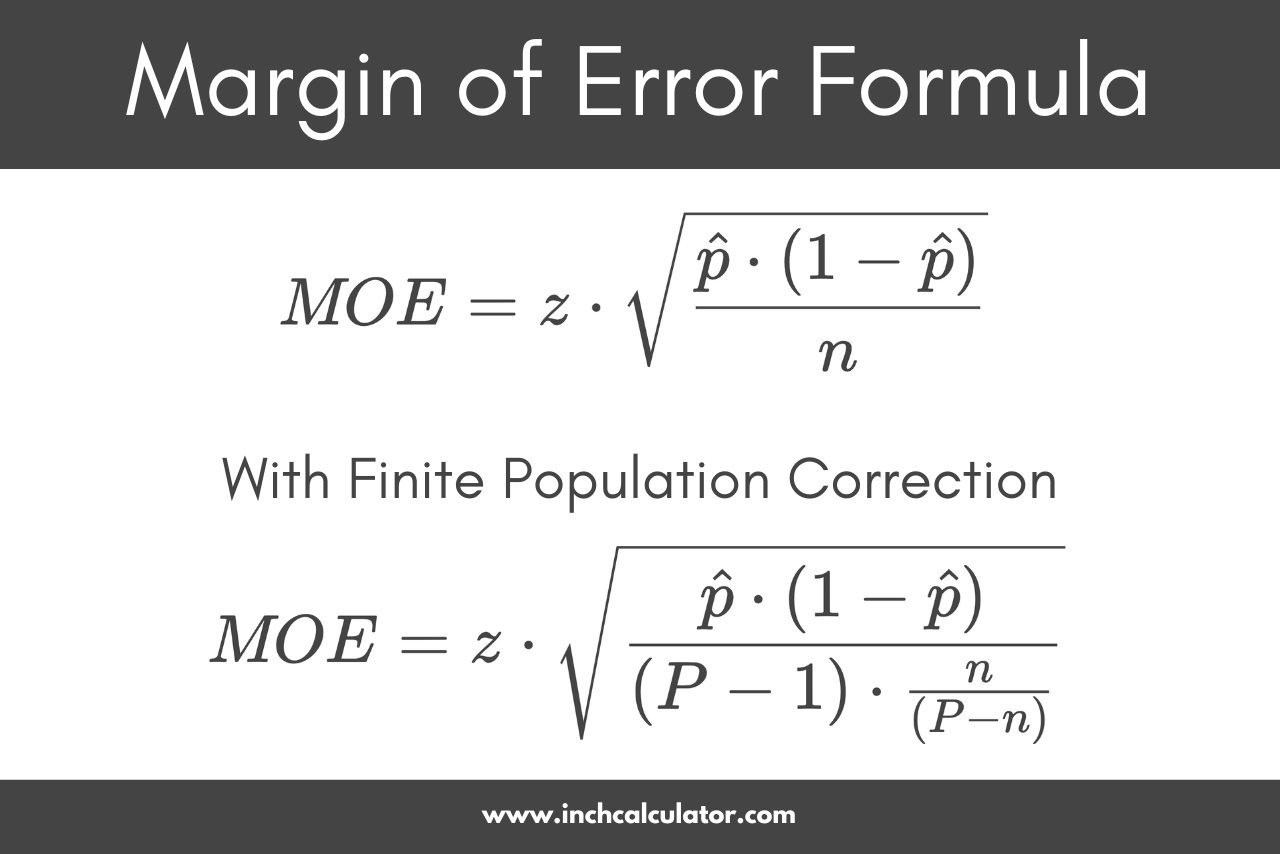
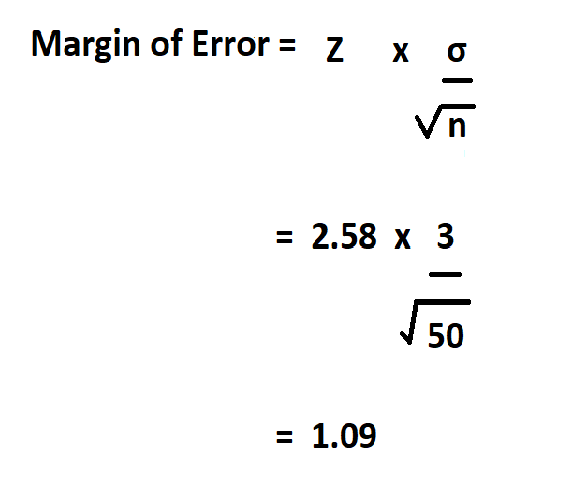
It shows up in survey results, election polls, and A/B test dashboards. You see plus or minus three percent and you assume it means something solid. It does, but not always what you think it means. I spent years cleaning up polling data for clients who wanted to bet real money on numbers they didn't actually understand. The first time someone asked me how to find margin of error, I thought they meant the formula. They meant something else entirely. They wanted to know whether the result was trustworthy enough to act on. That is a different question. The mathematical definition comes first, even though most people skip it. Margin of error is the radius of a confidence interval built from your sample data. It tells you how far the true population value might sit from your measured value, given a specific confidence level. The standard formula for a proportion is z times the square root of p times one minus p, all divided by the square root of n. Z is your z-score for the confidence level you picked. P is the sample proportion. N is your sample size. For a 95 percent confidence level, z is approximately 1.96. That is the number most people memorize without understanding why it matters.
How To Find Margin Of Error in Practice
Start with your sample proportion. If you surveyed 500 people and 280 said yes, your p is 0.56. Plug that into the formula along with n equals 500 and z equals 1.96. The calculation gives you a margin of error of about 4.4 percent. That means the true population proportion is somewhere between 51.6 percent and 60.4 percent at 95 percent confidence. You report it as 56 percent plus or minus 4.4 percent. Simple arithmetic. The thing that trips people up is when they apply this to small samples or extreme proportions. I had a client once who ran a customer satisfaction survey with 47 respondents. Twenty-six said they were satisfied. Their p was 0.55. When I calculated the margin of error, it came out to roughly 14.2 percent. They wanted to present this to their board as evidence that customer satisfaction was above 50 percent. It was, but the margin of error was so wide the result was basically noise. I told them the number was not actionable and they should either rerun the survey with a larger sample or reframe their findings as preliminary. They reran it with 412 respondents instead. The new margin of error dropped to 4.8 percent, which was actually useful. There is a second issue most guides do not mention. The standard formula assumes simple random sampling. If your data came from convenience sampling, online opt-ins, or any non-probability method, the margin of error you calculate is technically meaningless. It gives you a false sense of precision. I have seen analysts quote margins of error from website pop-up surveys as if they represented entire customer bases. The numbers looked professional on a slide deck. They were not defensible under any statistical review. This is probably the single biggest problem in applied survey work right now.
When dealing with finite populations, you need a correction factor. If your sample size is more than five percent of your total population, the standard formula overestimates the margin of error. The finite population correction multiplies the result by the square root of one minus n over N, where N is the population size. In practice this rarely changes things dramatically unless you are polling a small defined group, like employees at a company with 800 people and you sample 60 of them. The correction drops your margin of error by maybe half a percentage point. Worth applying if you want accuracy. Not worth losing sleep over if you are working with large populations. Another edge case that comes up constantly: comparing two proportions. You have two groups and you want to know whether the difference between them is statistically significant. You cannot just subtract one margin of error from the other. You need the standard error of the difference, which combines both variances. The formula is the square root of p one times one minus p one over n one plus p two times one minus p two over n two. Multiply that by your z-score and you get the margin of error for the difference. I use this all the time in A/B testing. Half the people who ask about it try to eyeball significance by looking at overlapping confidence intervals. That is a shortcut that fails when the overlap is thin. The correct calculation takes about thirty seconds in a spreadsheet and saves you from making the wrong decision. Software handles most of this automatically now. R, Python with scipy or statsmodels, even Excel with the right add-ins will compute margins of error in a single function call. I recommend Python for anything beyond basic calculations because it lets you handle complex sampling designs without fighting the tool. The code is straightforward. Import statsmodels proportion_confint and pass your successes, sample size, and alpha. It returns the confidence interval bounds directly. No manual formula needed. If you are doing this repeatedly, wrap it in a function that also prints the margin of error as plus or minus format. It saves maybe ten minutes per project, which sounds small until you add up a year of work.
Get the Full Details
Here is what nobody tells you about margins of error: they only account for random sampling error. They do not measure bias. If your survey question is leading, your sample skews demographic, or your response rate is twenty percent because the other eighty percent silently opted out, your margin of error is technically correct and practically useless. I worked on a healthcare policy poll once where the margin of error was a clean two percent. The response rate was fourteen percent and the sample was overwhelmingly older than the general population. The reported numbers were off by eleven percent from the actual census data. Two percent margin of error gave everyone confidence in a result that was directionally wrong. This is the trap. Always check how the data was collected before you treat the margin of error as the whole story. If you need a quick reference calculation without writing code, there are free online margin of error calculators. SurveySystem.com has a simple one. So does the CDC's public health calculator. They use the standard formula and assume simple random sampling, which is fine for most basic uses. Just remember that assumption applies to you too. If your sampling method is anything but random, treat the output as a lower bound on uncertainty, not the actual uncertainty. One more thing about confidence levels. Most people default to 95 percent because that is what news outlets use. But 95 percent corresponds to a z-score of 1.96, which means one in twenty results will fall outside the margin of error by chance alone. If you are running multiple tests or multiple polls, that probability adds up fast. Switching to 99 percent confidence raises the z-score to 2.576 and widens your margin of error by about thirty percent. It costs precision. It buys you something real: fewer false alarms. In regulatory or legal contexts where a wrong call has consequences, 99 percent is worth the wider interval. In marketing research where you need tight estimates to compare product variants, 95 percent is usually sufficient. Pick the level based on what a wrong answer would cost you, not based on habit.
Bottom line: margin of error is a tool, not a verdict. It quantifies one specific type of uncertainty under a set of assumptions. Check those assumptions. Verify your sampling method. Calculate it correctly. Then decide whether the number is close enough to act on. If it is not, gather more data or adjust your expectations. There is no formula that replaces common sense here.