Standard Deviation is Just a Measure of Spread
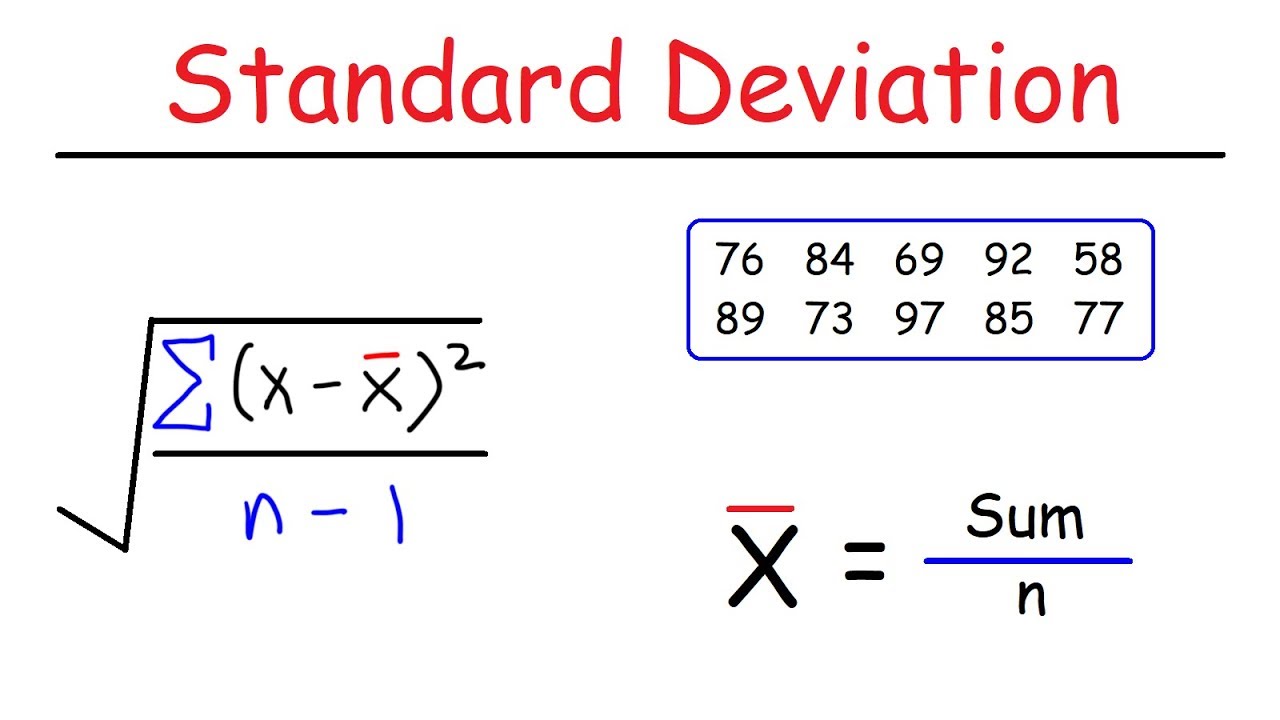
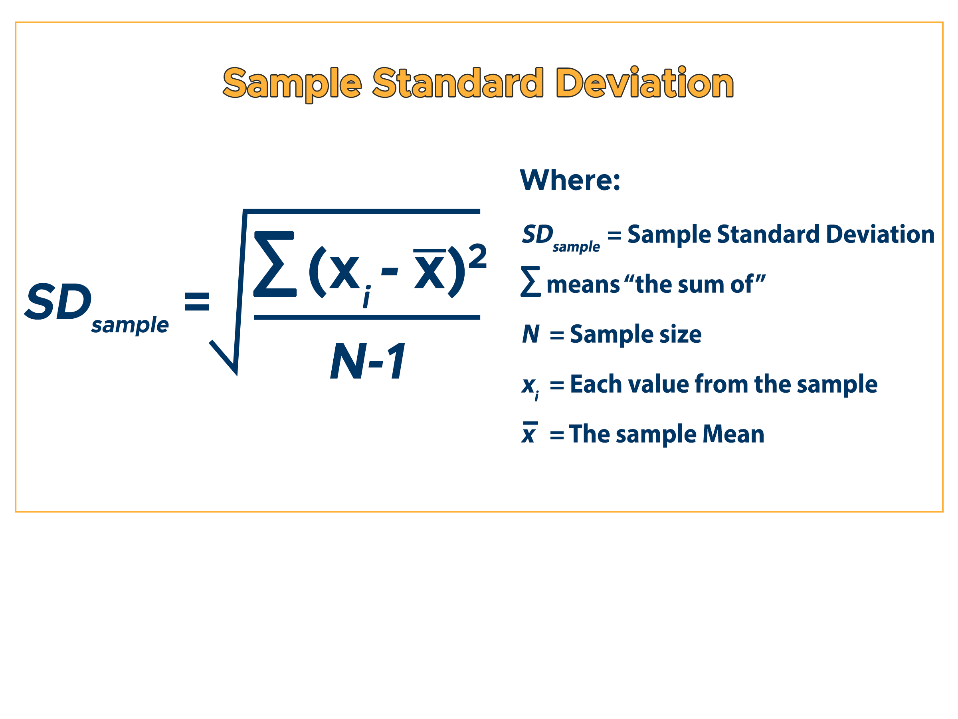
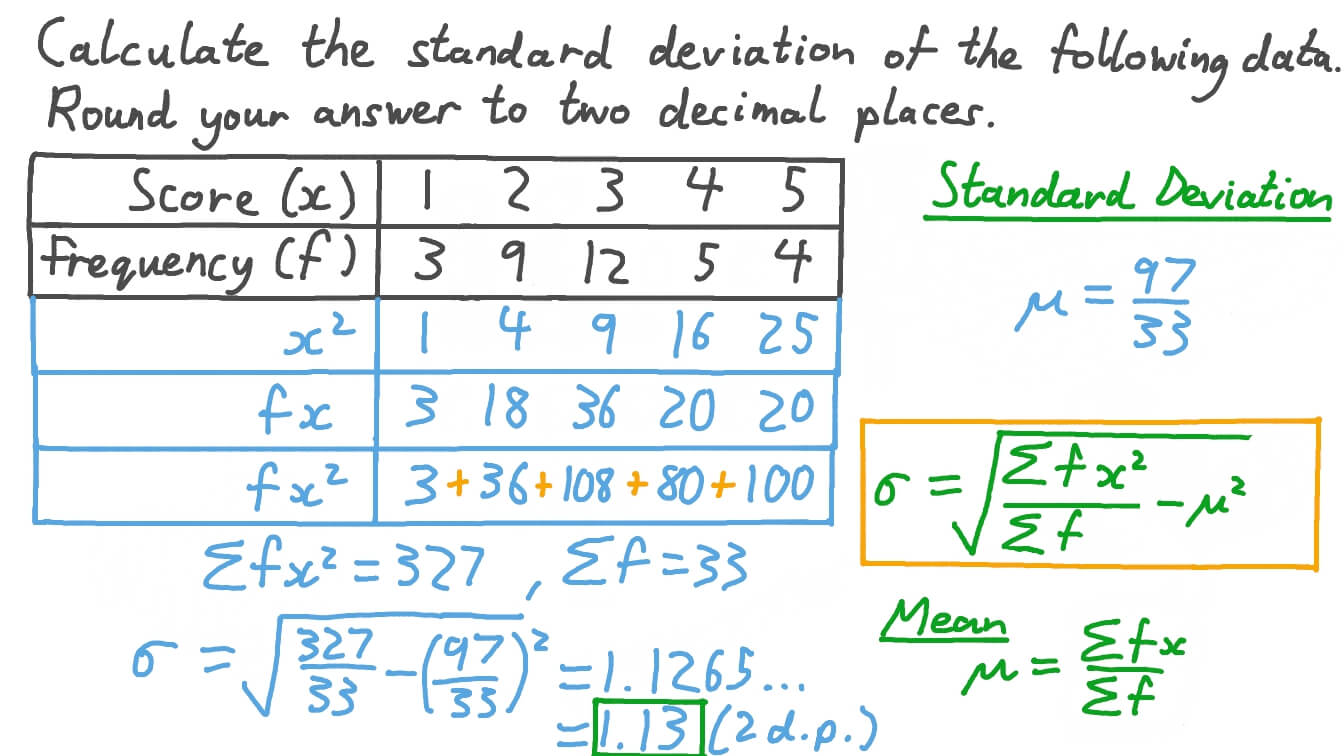
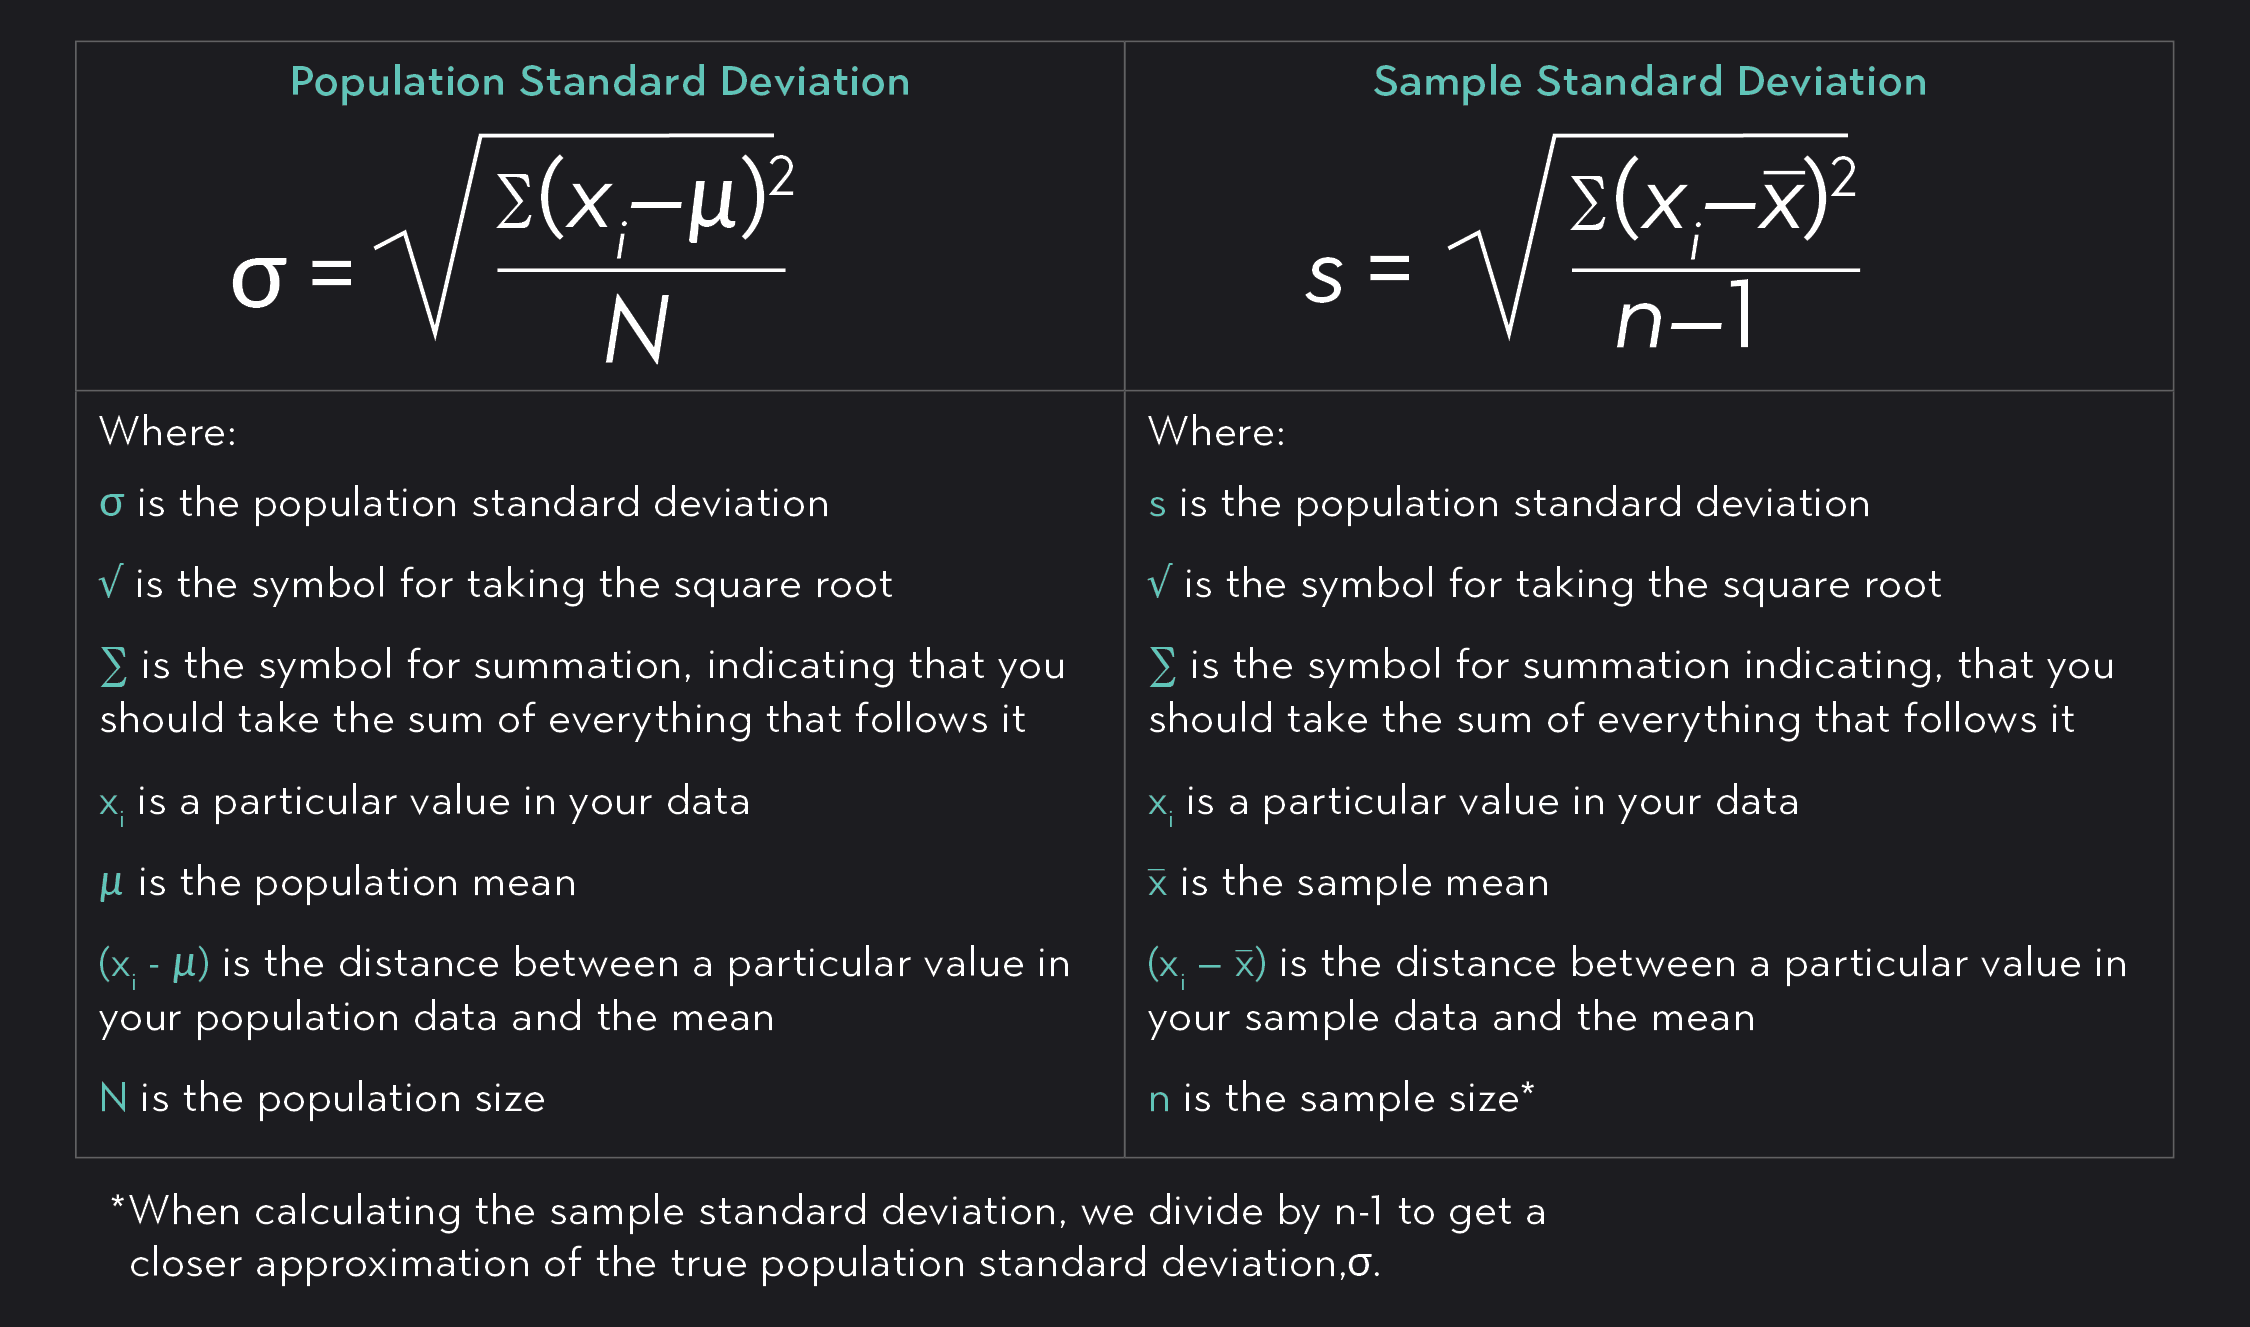
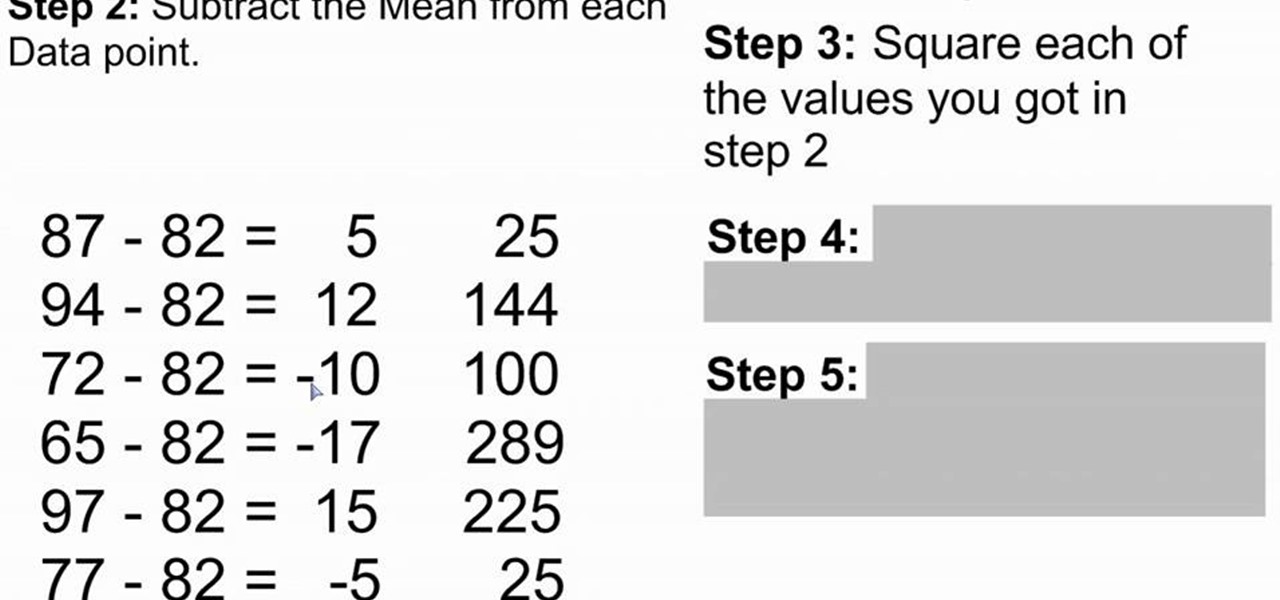
You don't need a statistics degree to calculate it by hand, but you do need to stop treating it like magic and start treating it like arithmetic. The formula looks intimidating if you've never seen it before, but each piece does exactly one thing. You subtract the mean from every data point, square the result to eliminate negatives, average those squared values, then take the square root to bring the number back into the original units. That's it. Nothing mystical about it. Start by writing out your dataset. Let's say you have five numbers: 4, 7, 9, 12, 18. Add them up, get 50, divide by 5, and your mean is 10. From here, go point by point and subtract 10 from each value. You'll get negative and positive numbers. Square every single one. That gives you 36, 9, 1, 4, and 64. Add those up for 114, divide by the count of numbers — 5 here, giving you 22.8 — and then take the square root. Your standard deviation comes out to approximately 4.77. If you're working with a sample rather than the full population, divide by n minus 1 instead, which would be 4 in this case, pushing the result slightly higher to around 5.34. I spent three years in a lab where we measured tensile strength across batches of polymer material, and the standard deviation was the number that decided whether a batch shipped or got sent back. One time I caught an error that would have completely skewed our results. Two data entry operators had recorded their readings on separate sheets and I merged them without checking if one sheet had extra zeros appended to certain values. The spread looked enormous at first glance — a standard deviation nearly triple what it should have been. I caught it because I recalculated by pulling the raw data from the original logbook rather than trusting the spreadsheet. That's a habit I'd recommend developing early. Spreadsheet errors compound silently and standard deviation amplifies them because they affect every data point.
When people ask how to find sd manually they usually just need the mechanical steps above. But there are two things most beginners get wrong about this number and neither one gets covered in intro textbooks. The first is that standard deviation is extremely sensitive to outliers because of the squaring step. A single extreme value can inflate the number dramatically and make the rest of your data look far more variable than it actually is. The second is that sd assumes a roughly symmetric distribution. When your data skews heavily — income data, reaction times, failure rates — the standard deviation tells you less than you think it does. In those cases the interquartile range gives you a more honest picture of spread without getting dragged around by extreme tails. For everyday use your fastest option is a calculator or spreadsheet. In Google Sheets or Excel you type =STDEV.S for a sample or =STDEV.P for a full population and you're done. Python gives you numpy.std with an optional ddof parameter that handles the sample versus population distinction without any manual division. The manual method matters when you're in an exam, debugging a formula that isn't returning what you expect, or working with tiny datasets where the calculation is faster than navigating software. It also builds actual intuition about what the number means rather than treating it as an opaque output. The main limitation people don't talk about is that standard deviation alone doesn't tell you anything about the shape of your data. Two completely different distributions can share the exact same sd value. Always pair it with a histogram or at least the minimum and maximum to understand what you're actually looking at. There's also the false precision problem — reporting sd to three decimal places when your measurement tool only records integers is pointless noise. One or two decimal places is plenty in almost every practical situation.
If your data is heavily skewed or contains many outliers, consider using median absolute deviation instead. It's less sensitive to extreme values and often more useful in real-world quality control or experimental work where clean bell curves are the exception rather than the rule. I switched most of my workflow to mad after the polymer batch incident and stopped pretending standard deviation was giving me the full story.
Get the Full Details