The actual process of finding standard deviation
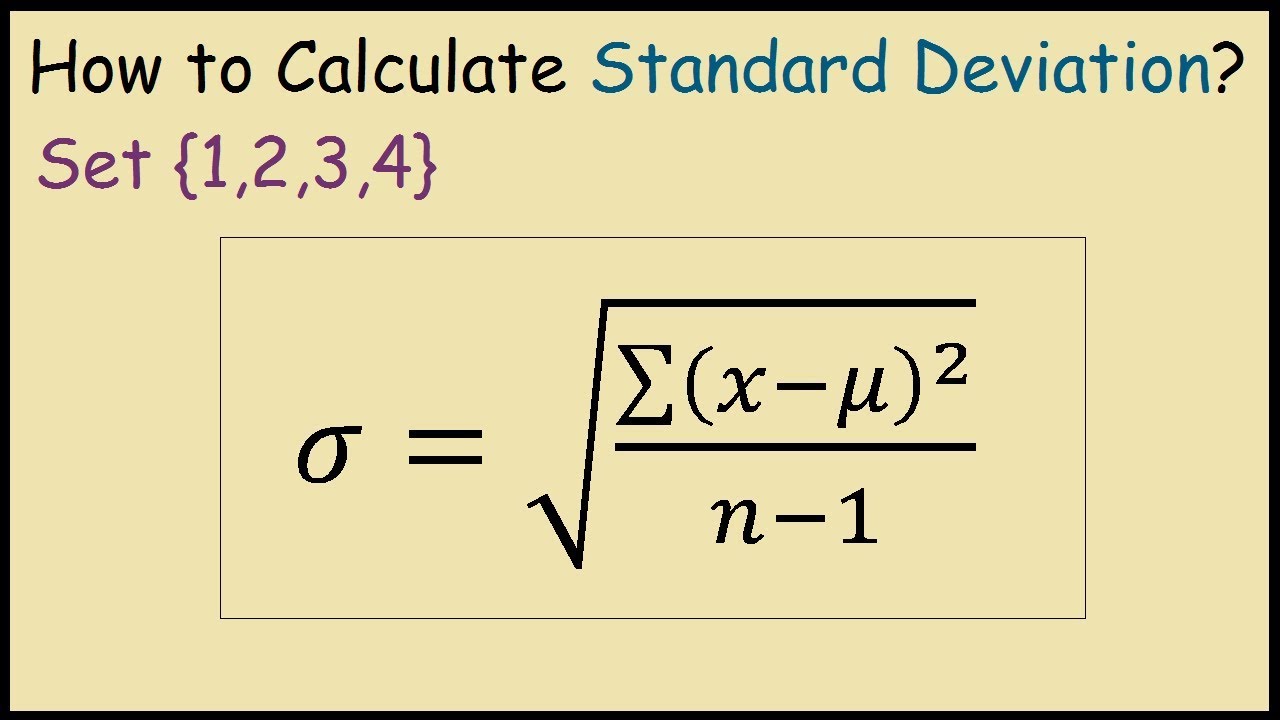
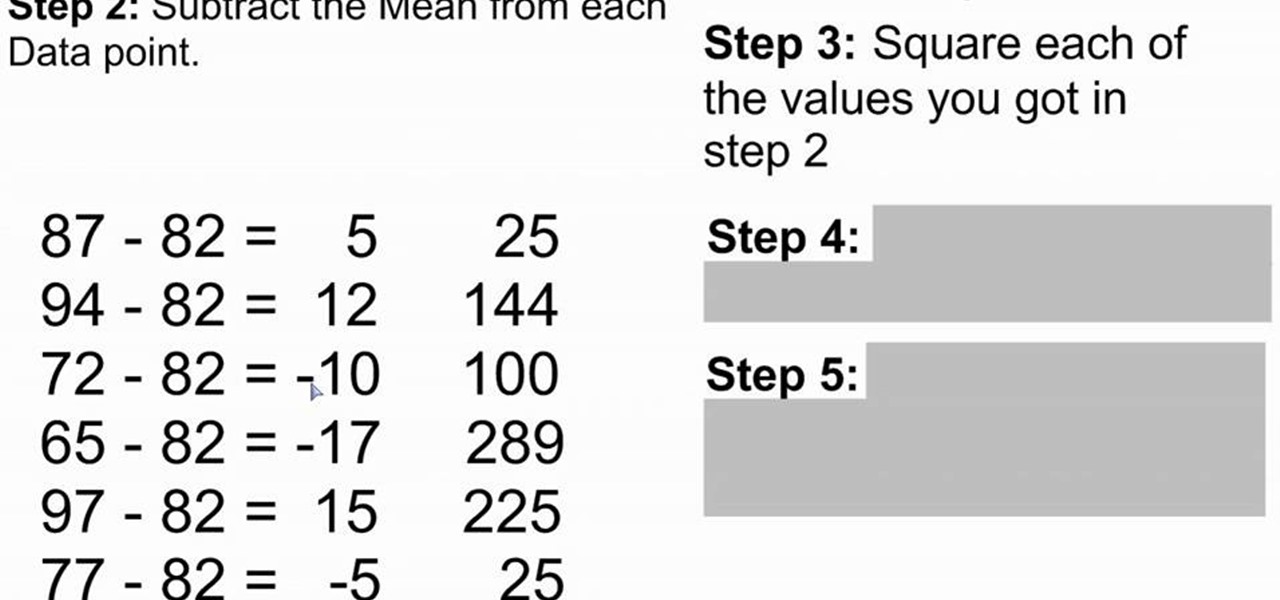
Standard deviation measures how spread out numbers are from their average. You probably learned the formula in school, but I am guessing you never actually used it in a real workflow until something broke and you needed to know whether a process was stable or completely out of control. That is when the math matters. Here is how I actually do it, step by step, the way it works on paper and in code. You subtract the mean from each data point, square that result, add all the squared values together, divide by the count if you have the whole population or the count minus one if it is a sample, and then take the square root. That is it. The result tells you, in the same units as your original data, how far data points typically sit from the center.
How To Find Standard Deviation in practice
Let me give you a concrete example. Say your dataset is 4, 8, 6, 5, 3, 7. The mean is 5.667. Subtract that from each value and you get -1.667, 2.333, 0.333, -0.667, -2.667, 1.333. Square those and you get 2.778, 5.444, 0.111, 0.444, 7.111, 1.778. Add them up and you get 17.667. Divide by n minus one, which is 5 for a sample, giving you 3.533. Square root of 3.533 is 1.88. Your standard deviation is 1.88. If this were a full population, you would divide by 6 instead of 5, and the result would be 1.71. The difference looks small here, but in production environments with thousands of records, using the wrong divisor can shift your confidence intervals enough to change a decision. I worked on a manufacturing quality line once where we were measuring the diameter of machined parts in microns. The spec tolerance was tight, and our SP chart was throwing false alarms because someone had stored the data as integers and the rounding error was inflating the standard deviation by about twelve percent. We switched to keeping raw measurements with decimal precision in the database and the alarm rate dropped to what it should have been. That is a detail most tutorials skip entirely.
Population versus sample standard deviation
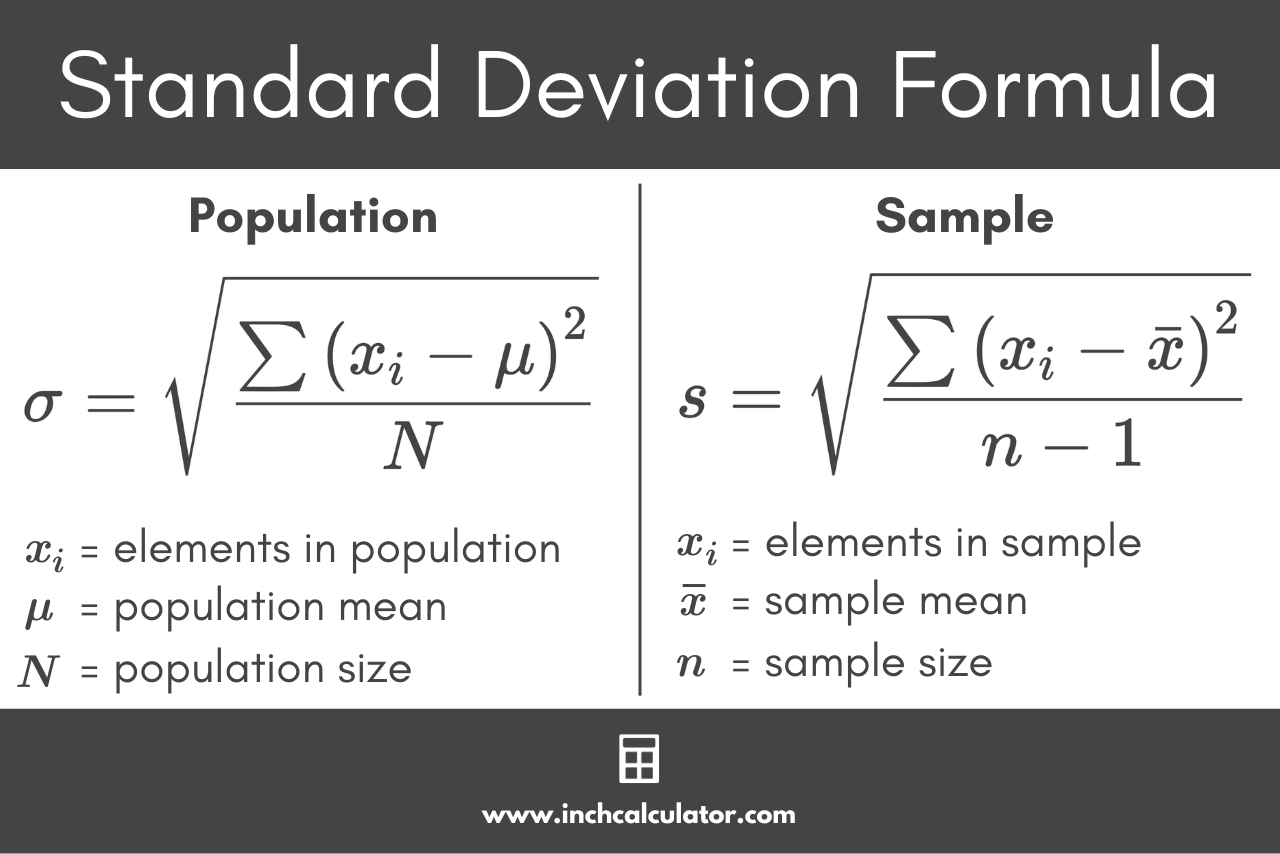
This is where most people make mistakes. The formula changes depending on whether your data represents an entire population or just a sample drawn from one. Population standard deviation uses the N in the denominator. Sample standard deviation uses N minus one. The N minus one version is called Bessel's correction and it exists because a sample tends to underestimate the true population variance. Without the correction, your standard deviation is systematically too small, especially with small sample sizes. In most real work situations you are dealing with samples. You measure a batch, not every single item that will ever be produced. So you use the sample formula. Excel's STDEV.S function uses N minus one. STDEV.P uses N. Python's numpy std function defaults to population standard deviation unless you pass ddof=1, which is the delta degrees of freedom parameter that switches it to sample mode. R's sd() function always uses N minus one. The inconsistency across tools is something you will run into more often than you think.
Get the Full Details
Common pitfalls and counter-intuitive things
One thing that catches people off guard is that standard deviation is sensitive to outliers in a nonlinear way because it squares each deviation before averaging them. A single extreme value can inflate the standard deviation dramatically, sometimes making a tight cluster look wildly variable. I had a dataset where one sensor malfunctioned and recorded a value twenty standard deviations away from the mean. That single point increased the overall standard deviation by roughly forty percent. I ended up using the median absolute deviation as a secondary check to confirm whether the spread was real or an artifact. Another issue is that standard deviation assumes your data is roughly normally distributed for many of its interpretations to hold. If your data is heavily skewed, like income distribution or website click counts, the standard deviation becomes harder to interpret meaningfully. A standard deviation of fifty dollars around a mean income of thirty thousand dollars tells you very little when half the data points are clustered below five thousand and the other half is stretched out to millions. In those cases, interquartile range is often more useful, even though nobody talks about it the way they talk about standard deviation. There is also the matter of units. Standard deviation is expressed in the same units as your data, which is actually an advantage over variance, which is in squared units. But that advantage disappears when you compare variability across datasets measured in different units. You need the coefficient of variation, which is standard deviation divided by the mean, to make that comparison.
When standard deviation is not the right tool
Let me be blunt about the limitations. Standard deviation does not tell you the shape of your distribution. Two datasets can have identical means and standard deviations but completely different distributions. One could be normal, another could be bimodal, another could have heavy tails. You need additional statistics like skewness and kurtosis, or visual tools like histograms and Q-Q plots, to understand what is actually going on. For time series data with trends or seasonality, computing a single standard deviation across the whole series is usually meaningless. The variance you calculate will be dominated by the trend, not by the noise you probably care about. You need to detrend or differenced the data first before standard deviation gives you useful information about process variability. Small sample sizes are another weakness. With fewer than five data points, the standard deviation is so unstable that reporting it is often misleading. The confidence interval around your standard deviation estimate can be wider than the estimate itself. I have seen people report standard deviations from samples of three and treat them as if they were precise measurements. They are not. If you have limited data, bootstrap your standard deviation estimate or use Bayesian methods to get a proper uncertainty interval.
Practical shortcuts and tools
You do not need to compute this by hand anymore. In Python, numpy and pandas handle it in one line. In Excel, STDEV.S or STDEV.P. In SQL, you can use STDDEV_SAMP or STDDEV_POP depending on your database. R has sd(). JavaScript has no built-in function, so you write a small utility or use a library like math.js. Most statistical software packages include it as a default output. If you are doing this repeatedly as part of a pipeline, I would recommend wrapping the calculation in a function that automatically detects whether you are working with a sample or population based on context, and that returns both the standard deviation and the standard error of the standard deviation. The standard error of the standard deviation is approximately sigma divided by the square root of two times N minus one, and it tells you how much your standard deviation estimate itself is expected to vary from sample to sample. That second piece of information is rarely reported but it is often the more important one. The formula itself is straightforward, but the decisions around divisor choice, outlier handling, distribution assumptions, and sample size limitations are where the actual work happens. Get those right and standard deviation is a powerful descriptor. Get them wrong and you are just producing a number that looks precise but means nothing.