The Standard Form and Why It Matters
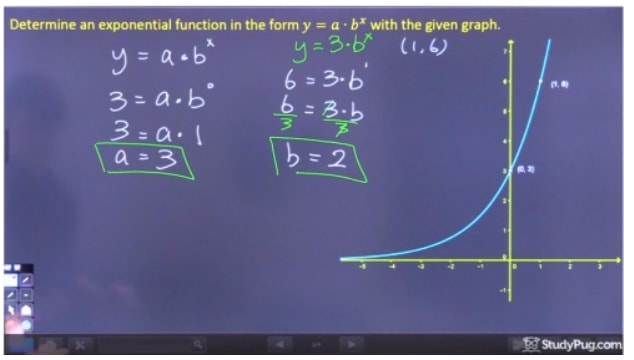
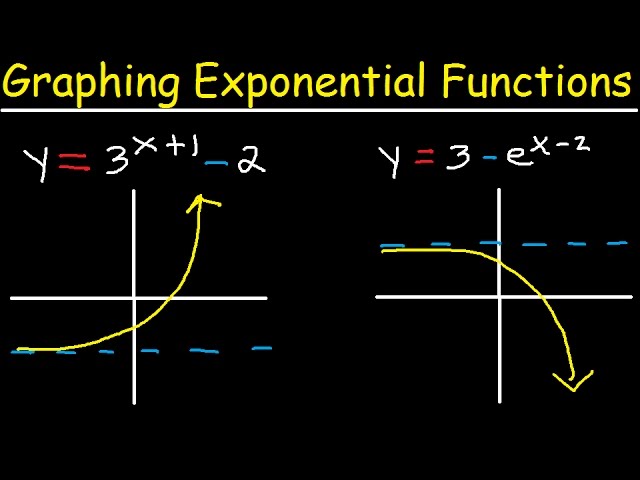
An exponential function sits in the form y = ab^x + k. The variable a controls the starting height before any vertical shift. The base b determines whether you are looking at growth or decay, and k is the horizontal asymptote. Most people skip past the asymptote and try to plug random points into a calculator. That works sometimes, and it breaks often enough to cause real headaches on exams or when you are building something that actually needs to fit. Start with the asymptote. If the graph flattens out and never crosses a horizontal line, that line is k. Read it off the grid directly. A graph approaching y = -4 means k = -4. A graph with no visible asymptote on the axis range you are given means you either need a wider window or you are dealing with a different type of function altogether. I once spent twenty minutes trying to force an equation onto a graph that looked exponential until I zoomed out and realized the horizontal line was at y = 12, not zero. The equation was completely wrong until I included that offset. Once you have k, use the y-intercept if it exists. When x equals zero, the term b^x becomes one. That leaves y = a + k. Subtract k from the y-value and you get a directly. This saves you from setting up a system of equations in most textbook cases. If there is no y-intercept on the visible portion of the graph, pick any two clean points and work from there.
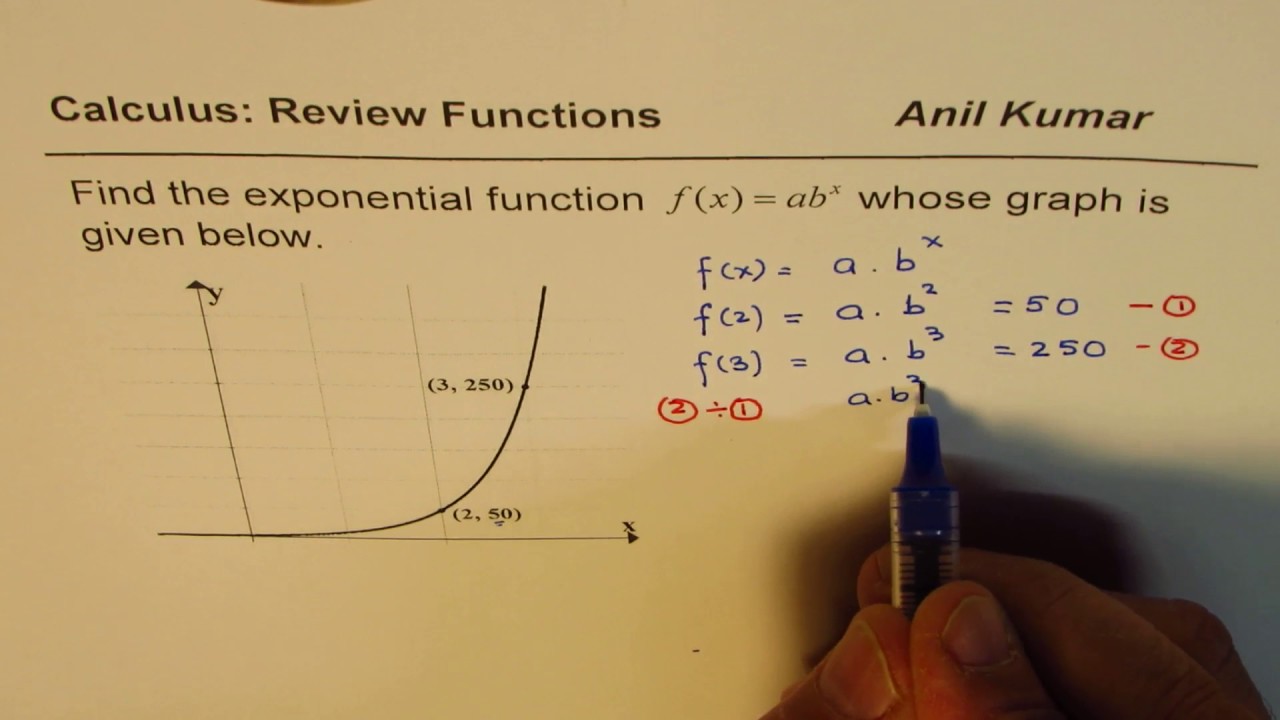
Take point one and point two, subtract k from each y-value, and divide. The k shift cancels out in the ratio, which leaves you with b raised to the power of the difference in x-values. Solve for b by taking the appropriate root. Round only at the end. Early rounding is what makes your check point drift three percent off and makes you second guess the whole method. Let me walk through a concrete example. A graph has an asymptote at y = 3, passes through the point zero comma seven, and also through two comma nineteen. The asymptote gives k = three. The y-intercept gives a + three = seven, so a = four. Now use the second point. Four times b squared plus three equals nineteen. Subtract three to get four times b squared equals sixteen. Divide by four to get b squared equals four. Square root gives b = two. The equation is y = 4 * 2^x + 3. Check it with another point on the graph if one is available. Not every case hands you a clean y-intercept. I had a dataset last year where the curve started at x = 3 with a value of eighty-five and the asymptote sat at y = 25. Two points were available: three comma eighty-five and five comma one forty-five. I subtracted k from both y-values to get sixty and one hundred twenty. The ratio is two to one, and the x difference is two. That means b squared equals two, so b equals the square root of two. The equation became y = 60 * (sqrt(2))^(x-3) + 25. Notice the shift in the exponent because the reference point was not at zero. Writing it as y = 60 * (sqrt(2))^(x-3) + 25 is algebraically identical to expanding it, and it is less prone to arithmetic errors.
When The Quick Method Fails
Linearizing the equation with logarithms is the backup when points are messy or the asymptote is uncertain. Take the form y = ab^x + k, subtract k, and take the natural log of both sides. You get ln(y - k) = ln(a) + x*ln(b). Plot ln(y - k) against x and the result should be a straight line with slope ln(b) and intercept ln(a). This is standard regression territory and it works even when b is irrational or the data has noise. The catch is that you need a reasonable estimate of k before you can linearize. If k is wrong, the transformed points curve instead of lining up, and you will fit garbage without noticing. In practice I test a few candidate asymptotes, transform each, and see which one produces the cleanest straight line. The correct k gives an R-squared value near one. Wrong k values drag it down visibly. This is faster than guessing from a crowded grid and it catches the asymptote shift that a quick visual read misses by a point or two. There is a harder edge case that shows up in real work. The graph crosses its own asymptote because it is not a pure exponential. A common example is a logistic or a transformed rational function that looks exponential over a narrow window. The curve shoots up, crosses the horizontal line, and then bends back. If you fit an exponential model to that section, your equation will predict values that diverge from reality the further you move from the fitted range. I learned this the hard way when I used an exponential fit on a viral load curve that plateaued and declined. The model predicted infinite growth for the next period. Switching to a logistic form fixed the forecast entirely. If your residuals show a systematic pattern instead of random scatter, the model is wrong, not the algebra.
Get the Full Details
Pitfalls to Avoid
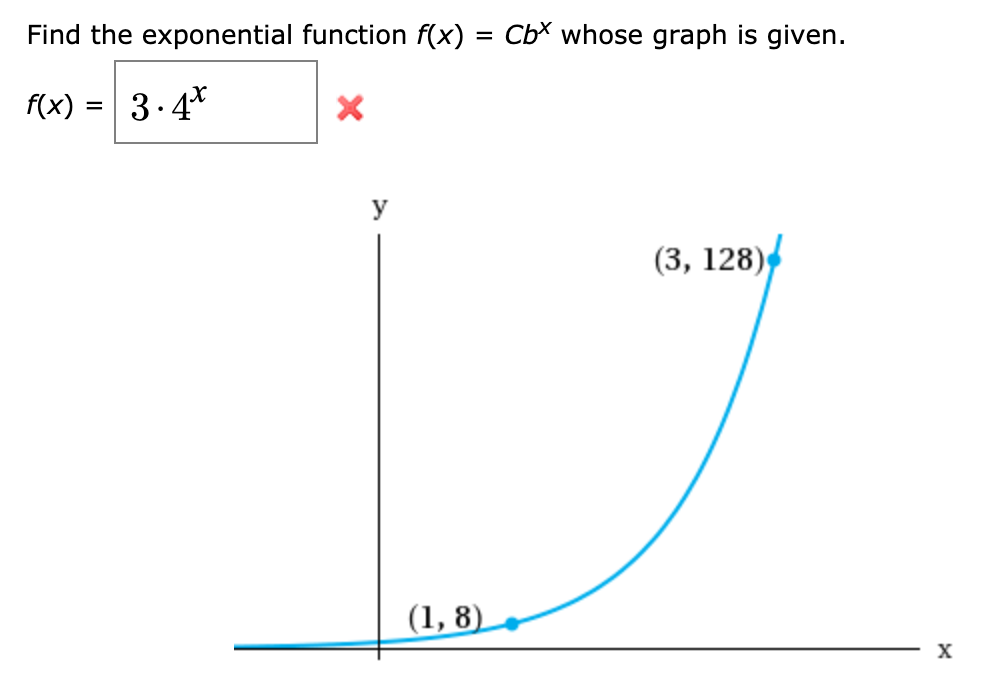
Do not assume the base is always an integer. Decay problems commonly produce bases like 0.75 or 1/sqrt(3). Leaving the answer in exact radical or fractional form is better than forcing a decimal approximation that rounds poorly. Do not confuse the initial value a with the y-intercept unless k equals zero. The y-intercept is a + k, and mixing those two values is the single most common error I see in student work and in quick professional estimates alike. Another trap is using only one point. One point and an asymptote leave one degree of freedom unresolved. You need at least two points or an additional constraint such as a known growth rate or a point at a specific x value. Throwing three points into a nonlinear solver and calling it done is fine for a rough fit, but it hides the algebraic structure and makes debugging harder when the output does not match the graph.
Quick Reference for Common Cases
If the asymptote is at y = zero and the y-intercept is known, the equation is simply y = y-intercept * b^x. Solve for b using any second point. If the asymptote is nonzero, always shift the y-values by k before solving. If the given points do not include x = zero, factor the exponent shift explicitly as b^(x - x0) to avoid arithmetic drift. For noisy data, linearize with logs after estimating k, then use linear regression to extract a and b in one pass. The method itself is straightforward. The failure modes are where the work actually lives. Get the asymptote right, keep the algebra exact until the final step, and verify with at least one extra point or a residual check. Most equations fall into place when you stop hunting for a shortcut and follow the structure.