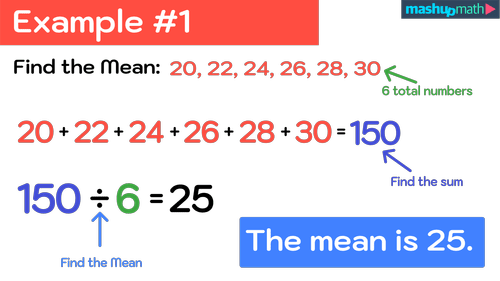
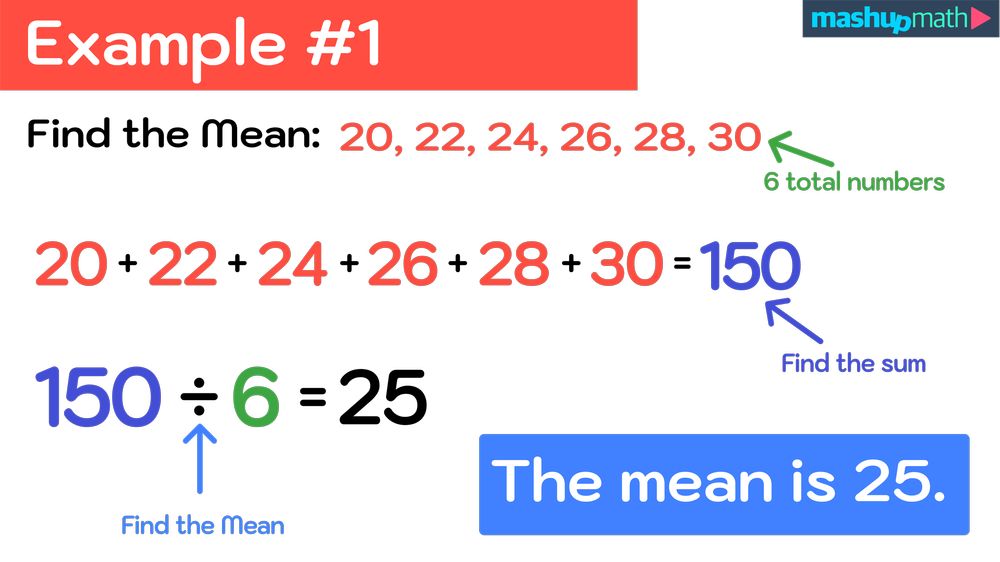
Adding numbers and dividing by how many there are. That is the whole thing.
Most people overcomplicate this when they are first learning it. They see a data set—say, something like 12, 7, 3, 9, 14—and they freeze because it looks like school math. I used to watch people do this at work all the time, especially on teams pulling reports from dashboards without thinking about what the numbers actually represent. You do not need a fancy tool for the mean. You need a calculator, a spreadsheet cell, or even just your hands if the list is short enough. Here is the actual process: add every value together, then divide that total by the count of values. That is it. No tricks. If your data has 5 items, you sum them and divide by 5. If it has 500 items, you still sum them and divide by 500. The formula everyone writes down is x = x / n, where x is the sum of all values and n is the number of values. I keep it on a sticky note at my desk only because people ask me to check their work, not because I need it. I recently had someone send me a list of 23 transaction amounts from a retail shift, asking for the average so they could reconcile it against a reported total. The list was ugly—some values had trailing decimals, one was written as text, and another was a negative return. I added them up in a Google Sheet with =SUM(), counted the entries with =COUNTA(), and then divided. The result came out to 47.83 per transaction. What tripped the person up was not the math. It was the fact that one cell was formatted as text and quietly broke the sum. I found it by running =ISNUMBER() on each cell and fixing that one entry. That is the kind of detail nobody mentions in a textbook.
When you are doing this by hand, write the numbers in a column. Sum them. Count them. Divide. Take your time. If you are rushing, you will misplace a decimal and spend twenty minutes debugging a wrong answer instead of learning anything.
How To Find The Mean for a larger or grouped data set
When the data gets big, or when you are working with grouped frequency tables, the manual method starts eating into your afternoon. In that case, you move to a spreadsheet or a scripting tool. A quick Python snippet does it in about three seconds for tens of thousands of rows, and it handles missing values gracefully if you tell it to ignore them. For grouped data, you do not have exact values anymore. You have ranges. The standard workaround is to take the midpoint of each range, multiply it by the frequency, sum those products, and then divide by the total frequency. It is an approximation, but it is the accepted one. I have seen people skip the midpoint step and just use the upper bound, which inflates the mean noticeably. Do not do that. The error grows with wider bins.
Get the Full Details
What the mean actually tells you, and what it does not
The mean is a measure of central tendency. It gives you a single number that represents the balance point of the distribution. It is useful for planning, forecasting, and comparison. It is also brutally sensitive to outliers. If your data set includes one extreme value, the mean shifts toward it. This is not a flaw in the calculation. It is a feature of what the mean measures. If you want a number that resists outliers, you look at the median instead. Another thing people miss: the mean of a combined group is not the average of the subgroup means unless the subgroups are the same size. I saw this wreck a quarterly report once. Someone averaged the regional means directly and got a number that was off by several percentage points. The fix was to compute a weighted mean, where each subgroup mean is weighted by its sample size.
Common pitfalls and when to stop using the mean
If your data is heavily skewed, the mean can be misleading. Income data is the classic example. A few high earners pull the mean far above what most people actually make. In those cases, the median or a trimmed mean is more informative. A 10 percent trimmed mean, where you drop the top and bottom 10 percent before averaging, is a practical compromise that I reach for when I need a robust summary statistic. There are also edge cases where the mean simply cannot be computed. If your data contains non-numeric values, division by zero is possible when n equals zero, and some statistical assumptions break down entirely with tiny samples. I have run into the zero-count issue when filtering a dataset and ending up with an empty group. The spreadsheet returns an error, and the dashboard breaks. The workaround is to add a conditional check: if the count is zero, return blank or a placeholder instead of attempting the division.
Quick reference for the standard approach
- Sum all values.
- Count the values.
- Divide the sum by the count.
- Check for non-numeric entries, missing data, and extreme outliers before trusting the result.
If you need a repeatable workflow, keep a template sheet with =SUM(), =COUNT(), and a division cell. Paste your data in, verify the formats, and let the formulas do the work. It takes less than a minute once the sheet is set up, and it removes the arithmetic errors that creep in when you are doing this manually for the tenth time in a week.