The Actual Method For Getting The Median Out Of A Histogram
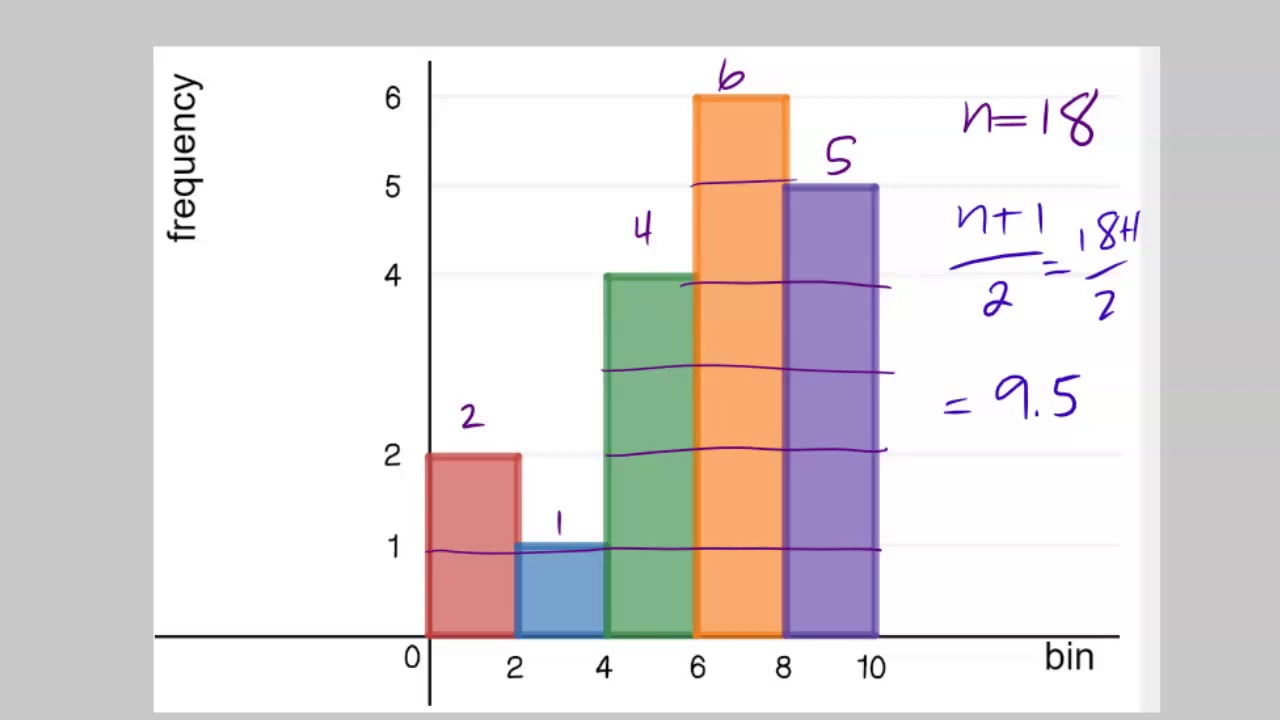
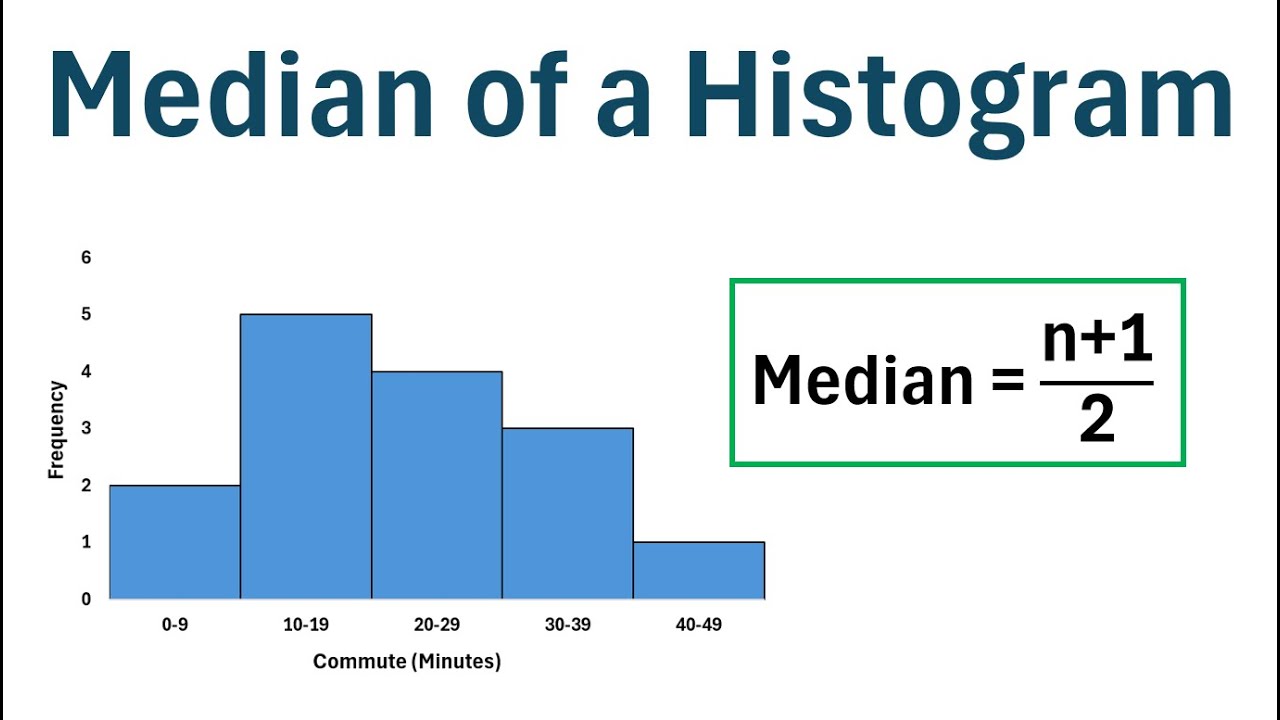
Most people overcomplicate this because they try to work directly from the visual bars on the chart. The median from a histogram is fundamentally an interpolation problem, not a visual estimation problem. You need the raw frequency data behind the histogram first. Without frequencies and class boundaries, you can't get anywhere near an accurate answer—estimating by eye might give you a rough ballpark within maybe ±10% of the true value, which is useful for quick checks but useless if anyone asks you to show your work. Here is the standard procedure. First, calculate the total frequency, N. Then find the median position, which is (N + 1) / 2 for discrete data or N / 2 for grouped continuous data. Most histogram problems treat the data as continuous, so you typically use N / 2. Identify the class interval that contains that position. Then apply linear interpolation within that interval to pinpoint the exact value. The interpolation formula looks like this: Median = L + [(N/2 - F) / f] × w. L is the exact lower boundary of the median class, N/2 is the median position, F is the cumulative frequency of all classes before the median class, f is the frequency of the median class itself, and w is the width of the median class. The key detail most students miss is that L is the actual boundary, not just the stated lower limit of the class. If your classes are 0–10, 10–20, 20–30, the boundary between the first and second class is literally 10. But if your classes are 0–9, 10–19, 20–29, there is a gap, and the actual boundary sits at 9.5, not 10.
How To Find The Median From A Histogram
Once you have identified the median class and its parameters, plug them into the formula. Here is a concrete example. Say you have a histogram with these class intervals and frequencies: 0–10 has frequency 5, 10–20 has frequency 12, 20–30 has frequency 8, and 30–40 has frequency 3. N equals 28. N/2 is 14. The cumulative frequency before the 10–20 class is 5. The 10–20 class has frequency 12 and width 10, with a lower boundary of 10. Median = 10 + [(14 - 5) / 12] × 10 = 10 + (9/12) × 10 = 10 + 7.5 = 17.5. That is your answer. Now, here is the thing that catches people out in practice. When the median position falls exactly on a cumulative frequency boundary between two classes, the formula becomes ambiguous. I ran into this once with a dataset where N was 60, so N/2 was 30, and the cumulative frequency jumped from 28 to 34 at a particular class boundary. Technically, the median class is the one containing position 30, which is clear. But I had originally misidentified the class because I was looking at the bar heights visually instead of building the cumulative frequency table first. Building the table takes about 30 seconds and prevents this mistake entirely. Another nuance that is worth knowing: histograms assume uniform distribution within each class. The interpolation method spreads the median linearly across the class interval, but the actual data could be heavily skewed within that bin. If your median class has a frequency of 2 across a width of 50 units, the interpolation gives you a precise-looking number, but the true median could reasonably sit anywhere in that wide gap. In those cases, widening your confidence range or noting the limitation in your answer is the honest move.
If you are dealing with an open-ended class like "60 and above," you cannot reliably calculate the median without making an assumption about the upper boundary. I once had to work with a dataset that had an open-ended final class, and since the median fell in a different class, it didn't affect the result. But if the median lands inside an open-ended class, the whole exercise falls apart. You either need to estimate a reasonable upper bound based on domain knowledge or fall back to reporting the median class rather than a precise value. Also worth noting: some textbooks use N/2 and some use (N+1)/2 for the median position. The difference is negligible for large datasets, usually shifting the result by less than one class width. For small samples, however, (N+1)/2 is technically more accurate for discrete data, while N/2 remains standard for the grouped continuous approximation that histograms represent. Stick with whichever convention your course or organization uses, but be consistent. If you need to automate this process, writing a simple spreadsheet or Python script that takes class boundaries and frequencies as input will cut the calculation time to seconds and eliminate arithmetic errors. Doing this by hand for more than a handful of problems gets repetitive fast, and the opportunity for a sign error or a boundary mistake grows with each additional class interval.
Get the Full Details