
Uncertainty quantification is the part of experimental work nobody wants to do but everyone needs to be honest about.
Most people treat uncertainty as something you calculate once at the end of an experiment and shove into a footnote. That approach works fine if you're only dealing with clean data and repeatable conditions. It falls apart the moment you step outside a controlled lab environment. I'm going to walk through How To Find Uncertainty starting with the practical method rather than some textbook definition, because the definitions don't help when you're staring at a messy dataset at 11pm and need to ship results by morning.
Start with Type A and Type B classification
The ISO Guide to the Expression of Uncertainty in Measurement (GUM) splits everything into two buckets. Type A uncertainties come from statistical analysis of repeated observations. Type B uncertainties come from everything else - manufacturer specifications, calibration certificates, environmental factors, your own judgment about instrument limits. Here's what beginners consistently miss: Type B uncertainties are not second-class citizens. They often dominate the final result in real-world measurements. I spent six months trying to get a sensor array to report consistent readings across different ambient temperatures. The Type A uncertainty from repeated measurements was tiny - around 0.3 percent. The Type B uncertainty from temperature dependence alone was nearly four percent. Focusing only on the statistical stuff would have made me very confidently wrong.
The actual process
Take your measurement model. Write down the equation that connects what you're measuring to the input quantities. If you're measuring resistance from voltage and current, that's R = V/I. If you're calculating an area from length and width, that's A = L × W. The structure matters more than the complexity. For each input quantity, determine its standard uncertainty. For Type A, that's the standard deviation of the mean divided by the square root of the number of observations. For Type B, you take the specified tolerance or bound and divide by the appropriate factor. A rectangular distribution gives you division by the square root of three. A triangular distribution gives you division by the square root of six. A normal distribution at three sigma gets divided by three. Calculate the sensitivity coefficients. These are the partial derivatives of your measurement model with respect to each input quantity, evaluated at the measured values. This step is where most people introduce errors by either skipping it entirely or computing it incorrectly. A sensitivity coefficient tells you how much the output changes when you perturb one input by a small amount.
Get the Full Details
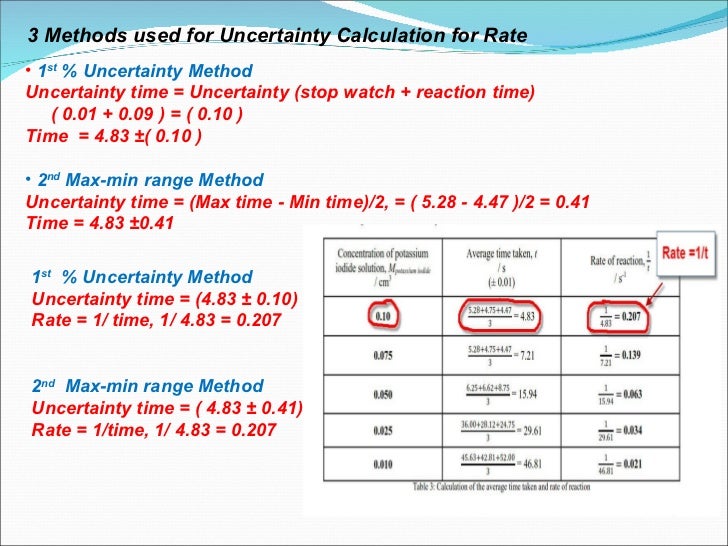
Multiply each input uncertainty by its sensitivity coefficient, square the results, add them together, and take the square root. That gives you the combined standard uncertainty. This is the law of propagation of uncertainty, and it assumes your input quantities are uncorrelated. If they're correlated, you need to add covariance terms, which complicates things significantly.
Expanded uncertainty and coverage factors
The combined standard uncertainty is not your final answer. You need to expand it to create an interval that has a stated level of confidence. Multiply by a coverage factor k. For approximately normal distributions and a 95 percent confidence level, k equals approximately 2. For higher confidence levels or smaller sample sizes, you need to use the t-distribution instead of the normal distribution. I once had a client who reported a coverage factor of 1.96 for a measurement with only five degrees of freedom. The correct value from the t-table was 2.776. That difference changed their entire uncertainty budget and invalidated several of their published results. It cost them about three weeks of rework and a public correction notice. The degrees of freedom for the combined uncertainty can be estimated using the Welch-Satterthwaite formula, which weights each input by the fourth power of its contribution to the variance.
Common pitfalls that aren't obvious
One issue that causes problems repeatedly is treating systematic errors as if they were random. If your scale reads 0.5 grams too high every time, taking more measurements won't reduce that uncertainty. You need to characterize the bias through calibration and include it as a Type B uncertainty component. The same principle applies to instrument resolution limits, aging components, and environmental drift. Another problem is ignoring the correlation between input quantities. When you calibrate a thermocouple against a reference thermometer in the same bath, their readings move together. If you later use both measurements independently in a calculation without accounting for that shared error source, your uncertainty will be understated. Check for correlations whenever two or more inputs share a common reference, calibration standard, or environmental condition. There's also the issue of over-specifying precision. Reporting an uncertainty of 0.000147 millimeters implies a level of confidence that rarely exists in practice. Round your final uncertainty to one or two significant figures at most. The measured value should then be rounded to match the same decimal place as the uncertainty.
When propagation of uncertainty breaks down
The standard method works well for linear or nearly linear models with small uncertainties relative to the measured values. When you have strongly nonlinear relationships or large uncertainties, the linear approximation introduces significant errors. In those cases, you should use Monte Carlo simulation instead. Generate random samples from each input distribution, propagate them through your measurement model, and analyze the distribution of the output. This approach is built into the GUM Supplement 1 and handles nonlinearity, non-Gaussian distributions, and complex correlations without additional assumptions. The tradeoff is computational cost and implementation effort. For a simple calculation with three inputs, Monte Carlo might take twenty minutes to set up versus twenty seconds for analytical propagation. But for a financial model with fifteen correlated inputs and nonlinear interactions, the analytical approach gives you garbage results while Monte Carlo takes an hour and gives you something defensible. Know which regime you're in.
A practical example
Let me walk through a real case. I was measuring the thermal conductivity of a polymer sample using a guarded hot plate method. The governing equation relates thermal conductivity to the heat input, temperature difference across the sample, sample thickness, and sample area. The input quantities and their standard uncertainties were: heat input at 50 watts with a Type B uncertainty of 0.5 watts from the power supply specification, temperature difference at 20 kelvin with a Type A uncertainty of 0.08 kelvin from repeated measurements and a Type B uncertainty of 0.05 kelvin from thermocouple calibration, thickness at 3.2 millimeters with a Type B uncertainty of 0.02 millimeters from the calibration certificate, and area at 0.01 square meters with negligible uncertainty compared to the other inputs. The sensitivity coefficients worked out to roughly 0.02 for heat input, -1.6 for temperature difference, 2.0 for thickness, and near zero for area. Propagating these through gave a combined standard uncertainty of about 0.12 W/(m·K) on a nominal result of 0.25 W/(m·K). The expanded uncertainty with k equals 2 was approximately 0.24 W/(m·K). The dominant contributor was clearly the temperature difference measurement, which meant further reducing the heat input or thickness uncertainty would have been wasted effort.
Documentation and traceability
Whatever method you use, document everything. Record the measurement model, each input value and its uncertainty, the distribution type assumed for each input, the sensitivity coefficients, the correlation assumptions, and the coverage factor chosen with its justification. Future you and anyone auditing your work will need this information, and you will not remember the details months from now. Uncertainty estimation is not a one-time exercise. Revisit it when your methodology changes, when you introduce new equipment, or when the results start looking suspiciously precise. The act of estimating uncertainty is itself a diagnostic tool - if your uncertainty budget doesn't explain the scatter you see in repeated measurements, you've missed an input quantity or mischaracterized a distribution.


