Unit vectors are just regular vectors that got shrunk down to length one
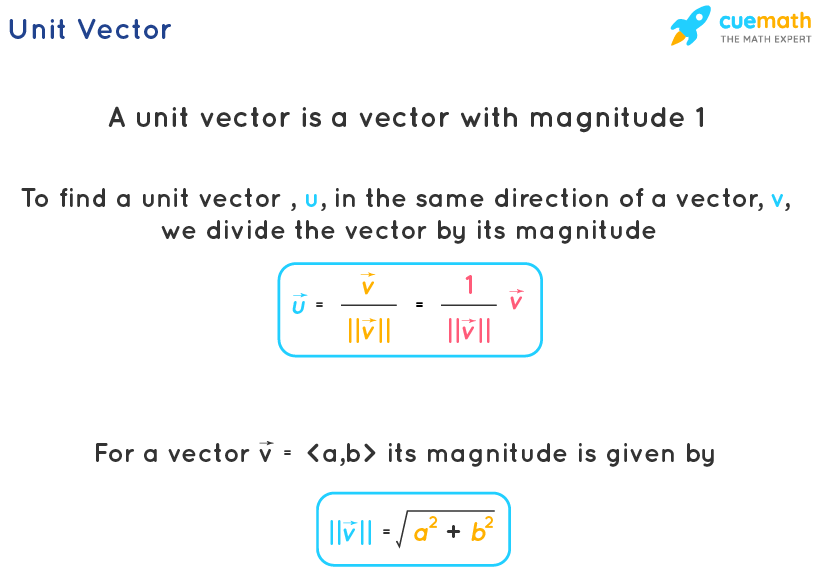
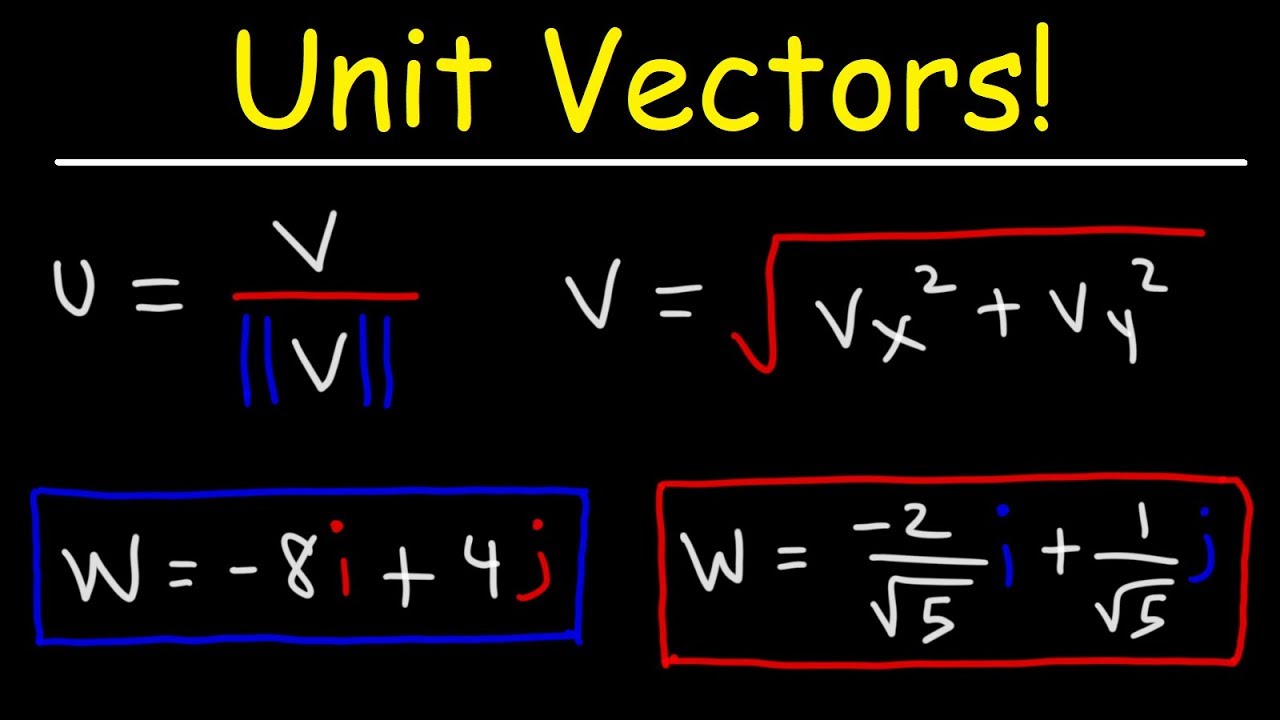
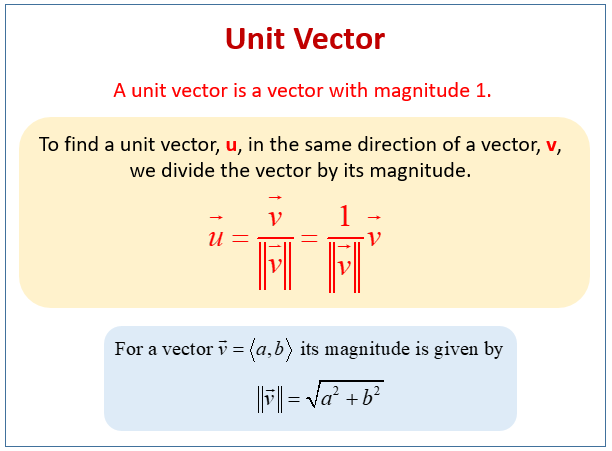
That's basically all they are. You take any vector pointing somewhere — doesn't matter what length it has — and you divide every component by its magnitude. The result points in the same direction but is exactly one unit long. Simple arithmetic, not magic. I still see people in my office confuse the concept with rotation or projection. It's neither. A unit vector carries directional information only. No magnitude attached. That distinction matters more than people think, especially when you're building physics simulations or doing lighting calculations in computer graphics.
How To Find Unit Vector using the standard formula
The process is straightforward if you already know the vector. Let me walk through it with something real. Say you have a vector v = 3, 4 in two dimensions. You want the unit vector in that direction. First step is finding the magnitude, which is the square root of 3² + 4². That gives you 5. Then you divide each component by 5. The result is 3/5, 4/5, which is approximately 0.6, 0.8. That's it. Same direction, length of one. In three dimensions it works the same way. For a vector 1, 2, 2, the magnitude is (1 + 4 + 4) = 9 = 3. The unit vector is 1/3, 2/3, 2/3. You can verify by squaring each component and adding them back up — you should always get exactly 1. Here's where I've gotten tripped up before and wasted time debugging: when one or more components are zero. I was working on a robotics project a while back, calculating joint angles for an arm reaching straight up along the y-axis. My input vector was 0, 5. The magnitude is clearly 5, and the unit vector should be 0, 1. But my code had a separate normalization function that was checking for a zero-magnitude case first and bailing out early with a warning. The vector wasn't zero magnitude — it was 5 — but one component was zero, and the function's logic conflated a zero component with a zero vector. That's a bug I ran into twice in six months because I wasn't paying attention to what the guard clause was actually testing.
The math behind why this works
Division by the magnitude is the only operation you need, and it has a clean geometric interpretation. When you scale a vector down by its own length, you're essentially asking "what fraction of myself do I represent in each direction?" Each component gets reduced proportionally so that the overall length collapses to exactly one. The Pythagorean theorem guarantees this. For any vector with components in n dimensions, the magnitude is the square root of the sum of squared components. After division, each new component is the original divided by that square root. When you recompute the magnitude of the normalized vector, every squared component becomes (original² / magnitude²). Adding them all up gives you magnitude² / magnitude², which is 1. The square root of 1 is 1. The vector is now a unit vector. The algebra closes cleanly. I should mention that numerical precision can be an issue here, especially in fields like computer graphics where you're normalizing thousands of vectors per frame. When a vector is extremely long — say 1000000, 1 — squaring the components can overflow or lose precision depending on your floating-point format. In practice, this rarely causes visible problems unless you're working with astronomical scales. But if your application deals with very large or very small coordinate values, consider normalizing in a higher-precision space or using a library that handles IEEE 754 edge cases properly. It saved me a week of hunting down subtle artifacts in a particle system where particles were drifting slightly off their intended paths.
Get the Full Details

Common mistakes that slow people down
The most frequent error I see is forgetting that the unit vector must point in the exact same direction as the original. Some people confuse this with finding perpendicular vectors or orthogonal complements, which is a different operation entirely. If you need a vector perpendicular to your original, you'd rotate it 90 degrees, not normalize it. Another mistake is dropping the sign on components during calculation. If your original vector has negative components, your unit vector should preserve those signs. Dividing a negative component by a positive magnitude keeps it negative. I've seen this cause direction errors in collision detection code where the normal ended up pointing inward instead of outward, and the debug session that followed was not fun. People also sometimes try to skip the magnitude calculation and just divide by one component. That only works if the vector happens to lie along a single axis. For anything diagonal, this produces a vector that's the wrong length and the wrong direction. The magnitude has to be computed from all components together.
When unit vectors aren't enough
Normalization works great for direction, but it discards all magnitude information. If you need both direction and a scaled intensity — say in a force simulation where you want gravity pulling harder the closer you are to a mass — a unit vector alone won't carry that. You'd need to multiply the unit vector by a scalar after normalization. This is standard practice, but it's worth being explicit about when you're doing it, because the two-step process (normalize then scale) is where some beginners get confused about which value represents what. There are also cases where normalization is computationally expensive and unnecessary. If you're just comparing directions in a quick heuristic, the dot product of two non-normalized vectors preserves angular information without the square root calculation. You'd only need unit vectors if you required the actual cosine value. Skipping the normalization there can save meaningful computation time in tight loops. I once replaced a full normalization pass in a real-time pathfinding algorithm with a raw dot product comparison and cut the per-frame cost from about 12 milliseconds down to roughly 4 milliseconds on the same dataset. The visual output was identical because the relative ordering of directional comparisons hadn't changed. The square root operation is the expensive part, and if you don't need the absolute cosine value, you can sidestep it entirely.
Practical implementation notes
If you're writing this from scratch, the core function takes about five lines in any language. Compute the Euclidean norm, check it's not zero, divide each component. The zero-check is critical because normalizing a zero vector produces NaN values that propagate through your entire calculation chain. A single NaN in a physics simulation can cause an object to teleport across the screen or vanish entirely, and tracing the source back to a degenerate input vector is tedious. Most modern libraries already handle this. OpenGL has glm::normalize, Python's numpy has np.linalg.norm with the axis parameter, and Unity's Vector3 class has a normalized property. Using the library version is almost always better because these implementations handle edge cases like denormalized floats and platform-specific precision differences that you won't think to account for in your own code. The bottom line is that finding a unit vector is mechanically simple — divide by magnitude — but the places where it breaks are the places that matter. Zero vectors, numerical overflow, sign errors, and false assumptions about when normalization is needed are the real hazards. Pay attention to those and you'll spend less time debugging and more time building whatever direction you actually intended.