What flattening a PDF actually means
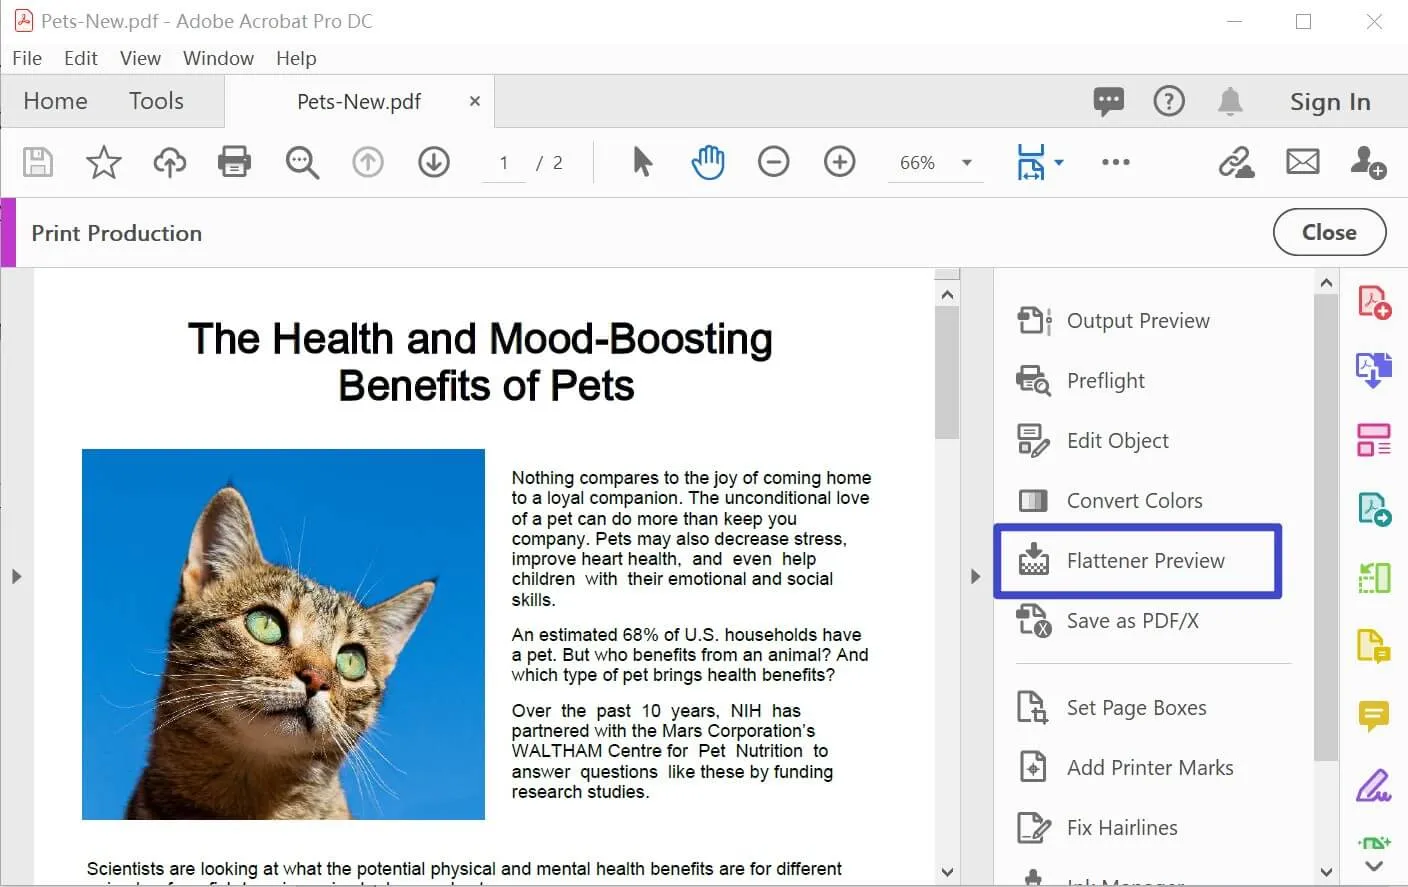
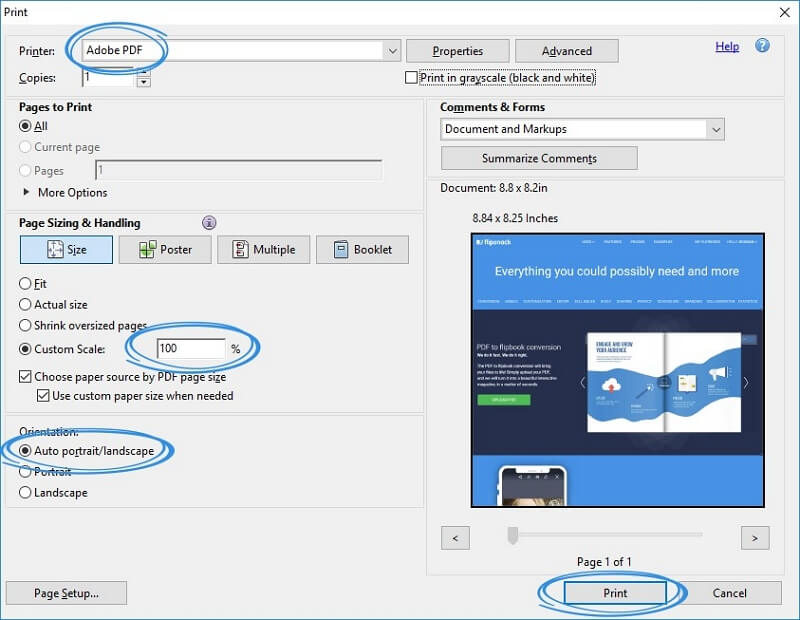
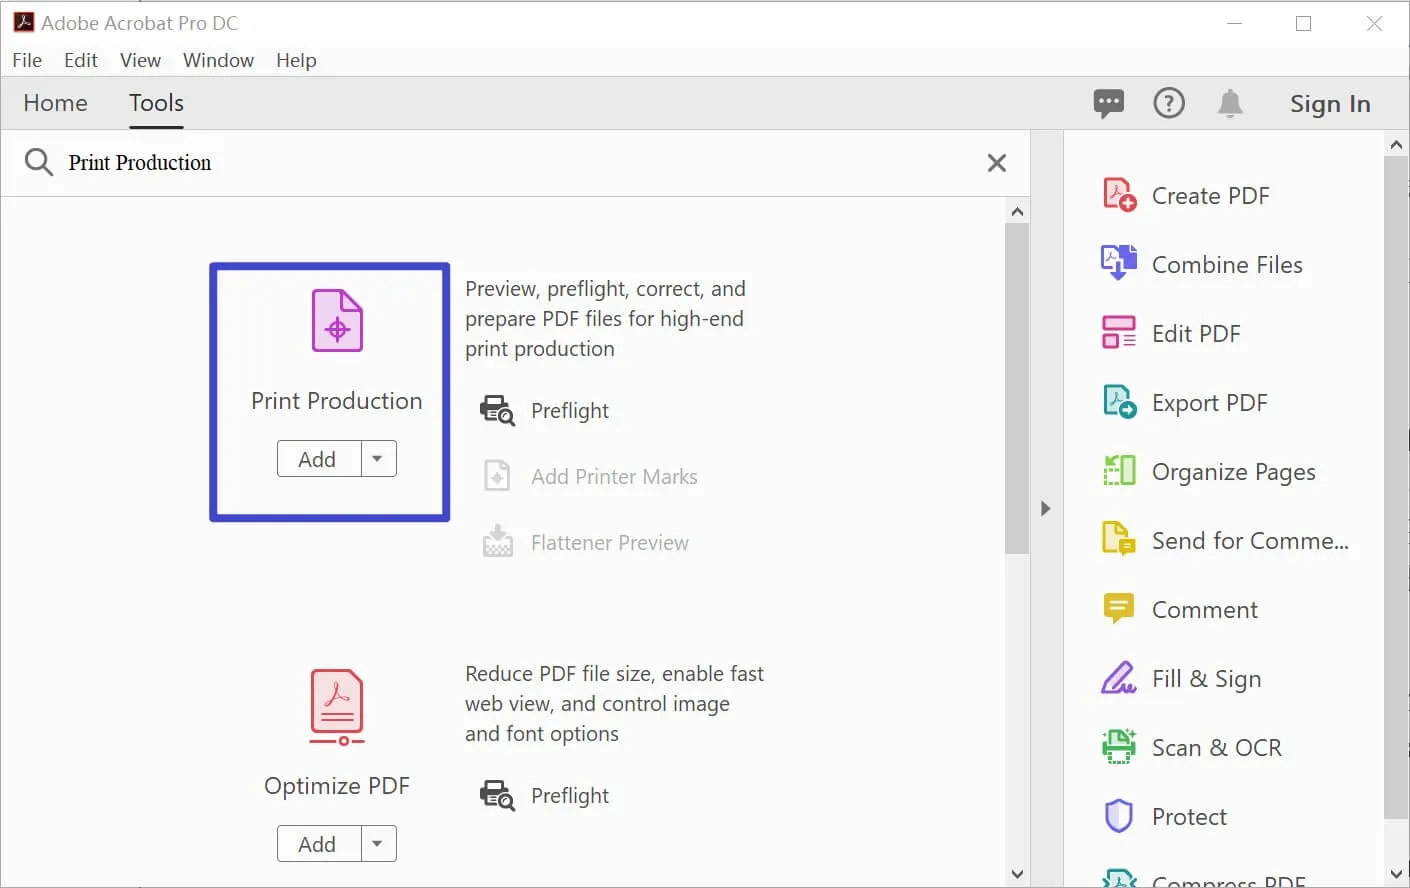
A flat PDF is one where every layer, form field, annotation, and hidden object has been merged into the visible page content. Once flattened, there is no editable text layer sitting behind an image, no fillable forms, and no separate annotation objects. It becomes what most people think of as a traditional scanned document, even if no scan ever occurred. This matters for submission systems, print production, and legal workflows where the receiving party needs guarantee that your document cannot be modified by anyone opening it. This is the method I use most often, and it works reliably for standard documents up to about 200 pages. Open your file in Acrobat Pro. Go to the Print Production toolset. Select Flattener and choose Prepress from the Quality menu. Click Flatten and then save. The resulting file will have all transparency effects, form fields, and annotations rasterized into the page stream. File size will increase, usually by 20 to 40 percent depending on how many interactive elements were present. There is a quicker route through the export function as well. Choose Export PDF, select Image PNG or JPEG, and convert. This flattens everything because you are essentially turning the entire document into a series of images. The tradeoff is that text becomes completely non-searchable and non-selectable. You lose OCR data entirely unless you run a separate OCR pass afterward, which adds another fifteen to thirty minutes to the process for a typical 50-page document.
The free method most people overlook
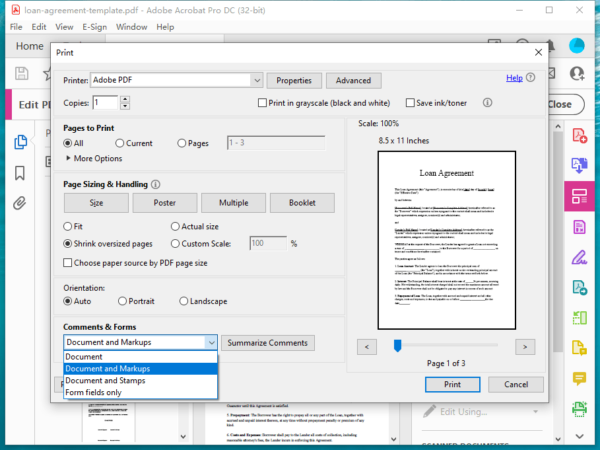
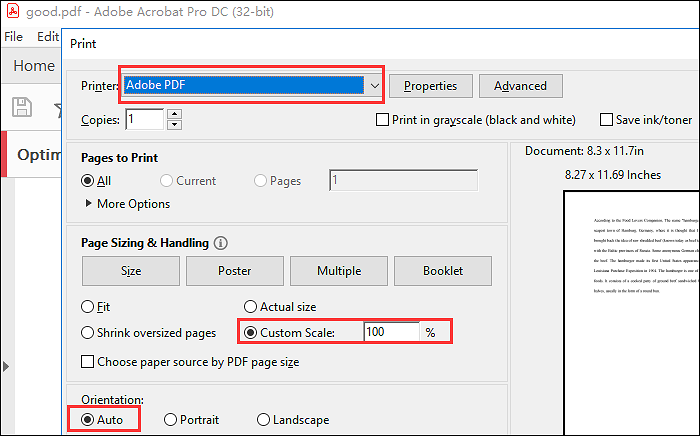
If you do not have a license for Acrobat Pro, the combination of Chrome or Edge plus the print-to-PDF driver will flatten most documents without any third-party software. Open the PDF in the browser. Press Ctrl+P. Under More settings, enable Background graphics if that option is available. Print to Microsoft Print to PDF or Save as PDF. The browser's rendering engine composites every layer into a single output stream. Fields, highlights, and comments all disappear into the page content. It is not perfect. Complex forms with JavaScript calculations will not behave the same way after this process. Interactive elements simply vanish because a browser print driver cannot execute or preserve JavaScript in the output. For straightforward static documents with some annotations layered on top, it takes about two minutes and produces a result indistinguishable from a paid tool in most practical scenarios.
Where this approach breaks down
The browser method fails consistently on PDFs that use heavy transparency, like drop shadows on text boxes or semi-transparent watermark overlays. I ran into this with a client who submitted a grant application that included a faint institutional logo watermarked across every page. When I flattened it through Chrome's print driver, the logo rendered as a solid white patch that obliterated the underlying text. The PDF looked corrupted to the review committee. The workaround was to open the file in Illustrator, expand the appearance on each affected page, and export as PDF. That took about eight minutes per fifty pages instead of two minutes for the whole document. If you are dealing with large volumes of transparent-heavy files, pre-flatten them in batches using a scripted action in Acrobat Pro rather than doing it manually through Illustrator. The action runs at roughly one minute per page on a modern machine, which is still significantly faster than handling each file individually.
Get the Full Details
Advanced considerations most guides skip
Flattening is not a reversible operation. Once the layers are baked into the page content, there is no way to recover the original interactive elements. Do not flatten a master copy that you might need to edit later. Always keep the original file untouched and flatten only the version you intend to submit or distribute. Another thing people miss is that flattening changes the PDF structure in ways that can trigger validation errors in certain archiving systems. PDF/A compliance checks may flag a flattened file differently than the original because the object hierarchy has been altered. If you are preparing documents for long-term archival or government submission, test the flattened version against the specific validator the receiving organization requires before sending it out. I learned this the hard way when a municipal court rejected a compliant filing because the flattening process had converted tagged PDF text into pure content stream commands, breaking the accessibility tree the system was checking for.
How To Flatten A Pdf programmatically for bulk workflows
If you need to flatten hundreds of files, manual methods will not scale. The most reliable approach is using Ghostscript with the prepress preset. A single command line does the job: ghostscript -sDEVICE=pdfwrite -dCompatibilityLevel=1.4 -dPDFSETTINGS=/prepress -dNOPAUSE -dQUIET -dBATCH -sOutputFile=output.pdf input.pdf. This compresses all layers into the page stream and handles transparency correctly, which is where the browser method typically fails. For Python-based automation, pikepdf or PyMuPDF can iterate through a folder and apply flattening operations. The runtime for a hundred average documents is roughly three to five minutes total on a standard laptop. File sizes after processing increase by about 30 percent on average. The main limitation is that these libraries do not preserve interactive form metadata at all, so if you need to maintain form data in a separate file while also creating a flattened version, you will need to run two parallel passes. The core rule is simple: flatten only what you are ready to lock down, verify the output visually before submission, and never trust a single method for every type of file you encounter. PDF structures vary too much for one-size-fits-all approaches to work reliably across different document sources and versions.