The mean is just what people call the average, but getting it right is where most folks mess up.
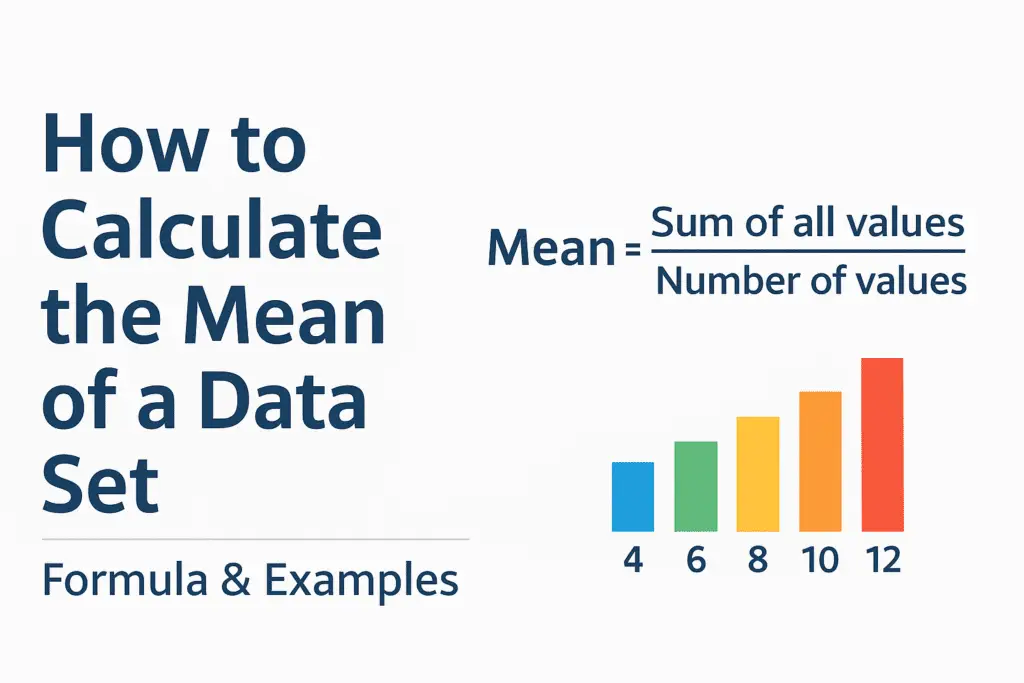
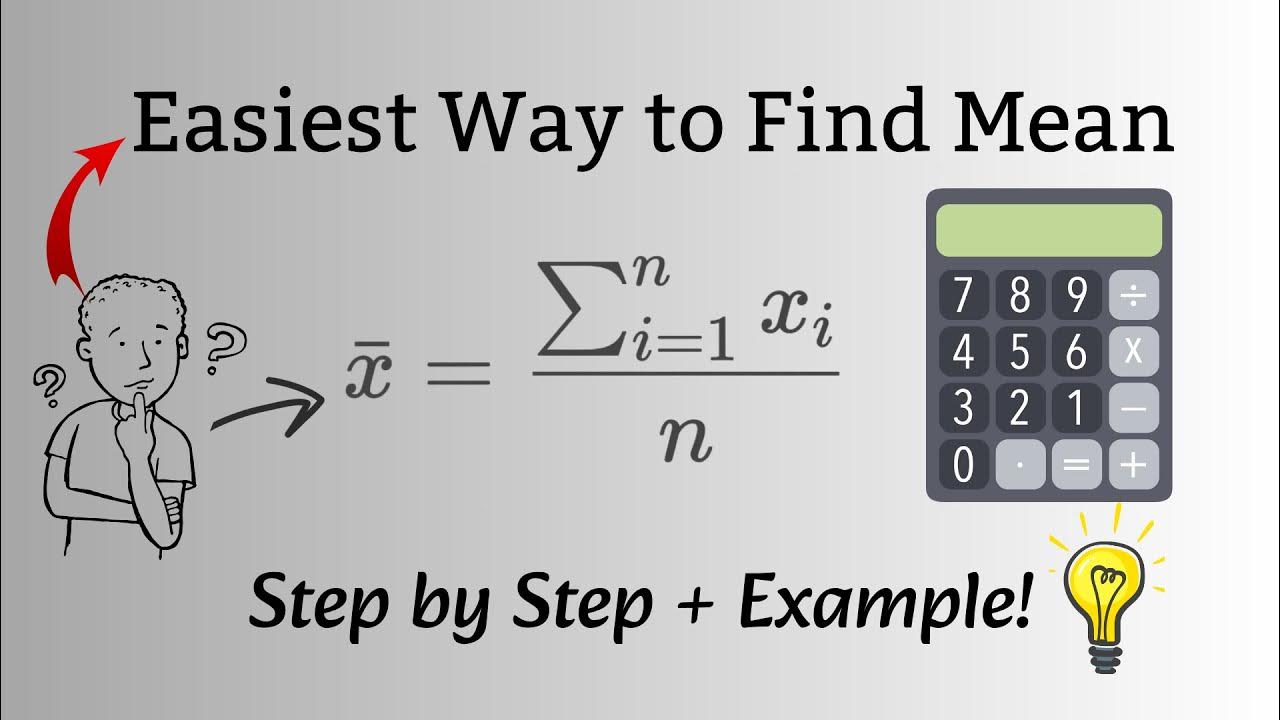
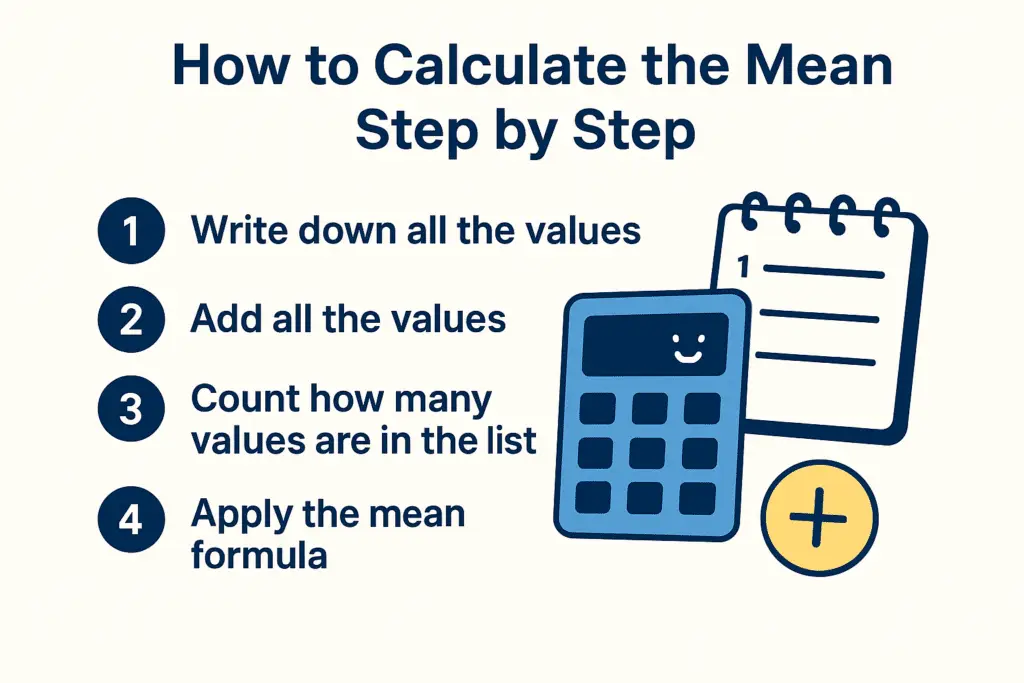
You add up every value in your dataset, then divide by the count of values. That's the formula. The problem isn't learning it, it's knowing when the result actually tells you something useful and when it's lying to you. I've spent years watching people use means from skewed distributions and then wonder why their models perform poorly. The mean will happily give you a number even when that number doesn't represent a single real observation in your data. Take a list of numbers. Sum them. Count them. Divide. Here's a concrete example because abstract math gets muddy fast. You have these five numbers: 4, 7, 12, 19, 28. The sum is 70. The count is 5. The mean is 14. You're done. Now the real part. Most people stop there. They report 14 and move on. But if your data looks like this instead: 2, 3, 4, 5, 100. The sum is 114. The count is still 5. The mean is 22.8. There is not a single data point anywhere near 22.8. The mean is being dragged by that one outlier and it's giving you a false sense of where most of your data actually sits. That's the first thing you need to understand before you ever put a mean into a report or hand it to someone else to interpret.
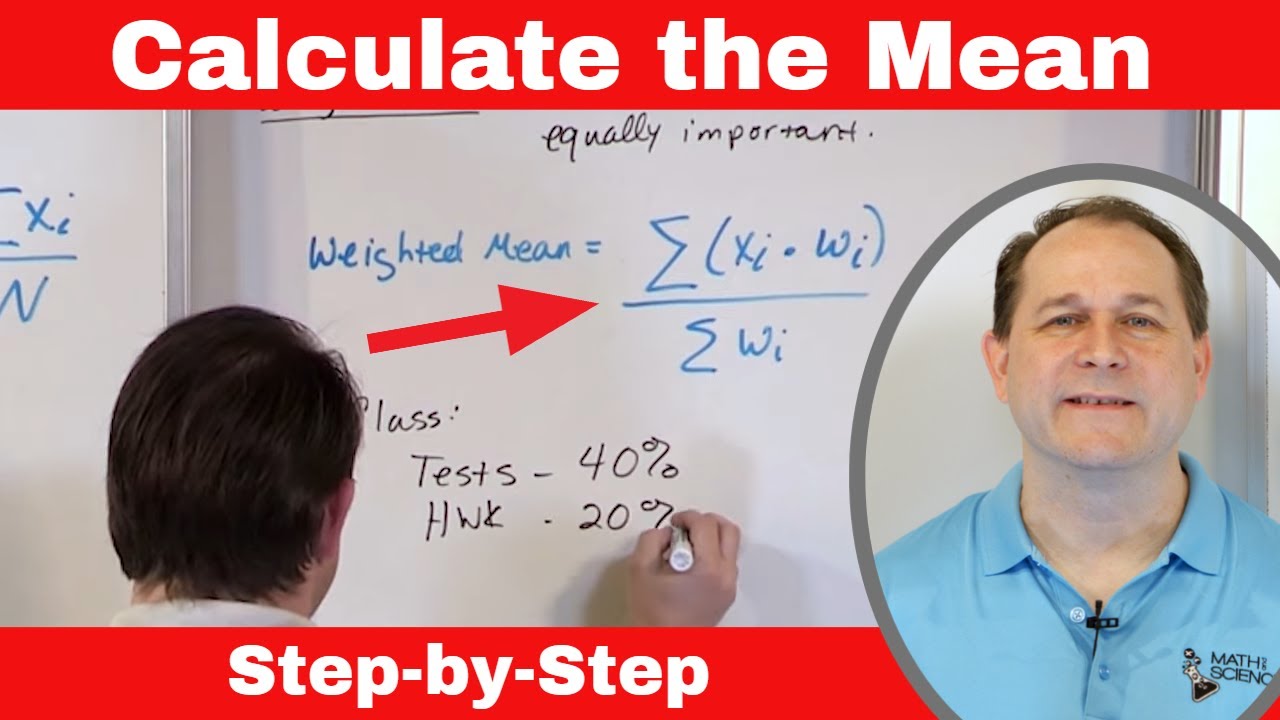
I once had a client sending me maintenance logs from industrial pumps. Mean time between failures came out to about 47 days. Sounds terrible. But when I plotted the distribution, I realized 80 percent of the pumps lasted between 90 and 150 days. The remaining 20 percent failed within the first week and tanked the average. The mean wasn't wrong. It was just useless for planning spare parts inventory. We switched to using the median for that project and it dropped the number to 112 days, which actually matched what our maintenance crew was experiencing on the floor. That one change saved us from ordering double the spare units we actually needed. Here's another nuance people miss. The mean changes depending on how you weight things. If you're looking at monthly sales across twelve regions and you just average the twelve regional means, you're giving equal importance to a region with two stores and a region with two hundred stores. That's not a mean that reflects reality. You need a weighted mean where larger regions carry more influence. The formula adds the sum of each value multiplied by its weight, then divides by the sum of the weights. Simple enough in practice, but easy to skip when you're rushing. If you're working with large datasets and doing this by hand, you're wasting time. Use a calculator, Excel, or a quick Python script. One line in Python does it cleanly. import numpy as np. Then np.mean(your_data). Takes about three seconds and removes any arithmetic error risk. If you're doing this in Excel, the AVERAGE function works fine until your dataset has blanks or text mixed in, then it silently ignores those cells and your count gets off. I learned that the hard way on a quality control project where a dozen blank cells made our mean look better than it actually was. The fix is checking your cell count matches your data count before trusting the output.
When the mean stops being useful
Not every dataset deserves a mean. If your data is heavily skewed, bimodal, or has a long tail, the mean will sit somewhere between the actual clusters and represent neither group well. In those cases the median or mode does the job better. A bimodal dataset might have a mean right in the valley between two peaks. Nobody actually lives there. Reporting that number as representative is misleading, plain and simple. Categorical data doesn't get a mean. You can't average colors or product names. Sometimes people try to assign numbers to categories and then average those, which produces a result that sounds precise but is essentially noise. I've seen it happen with survey data where responses were coded 1 through 5 and then averaged across questions with different scales. The resulting mean meant nothing. There's also the issue of missing data. If values are missing non-randomly, the mean becomes biased. Say you're measuring customer satisfaction and only very unhappy or very happy customers respond. The mean will look closer to neutral even if the actual population is polarized. This isn't a calculation problem. It's a sampling problem that no amount of mathematical trickery fixes.
Get the Full Details
The good news is that once you know your data is appropriate for a mean, computing it is straightforward. The harder part is deciding whether to report it alongside other measures, flagging skewness, and being honest about what the number actually communicates. A mean without context is just a digit. Context is what makes it meaningful.