Standard Deviation Doesn't Lie, But It Doesn't Tell You Everything Either
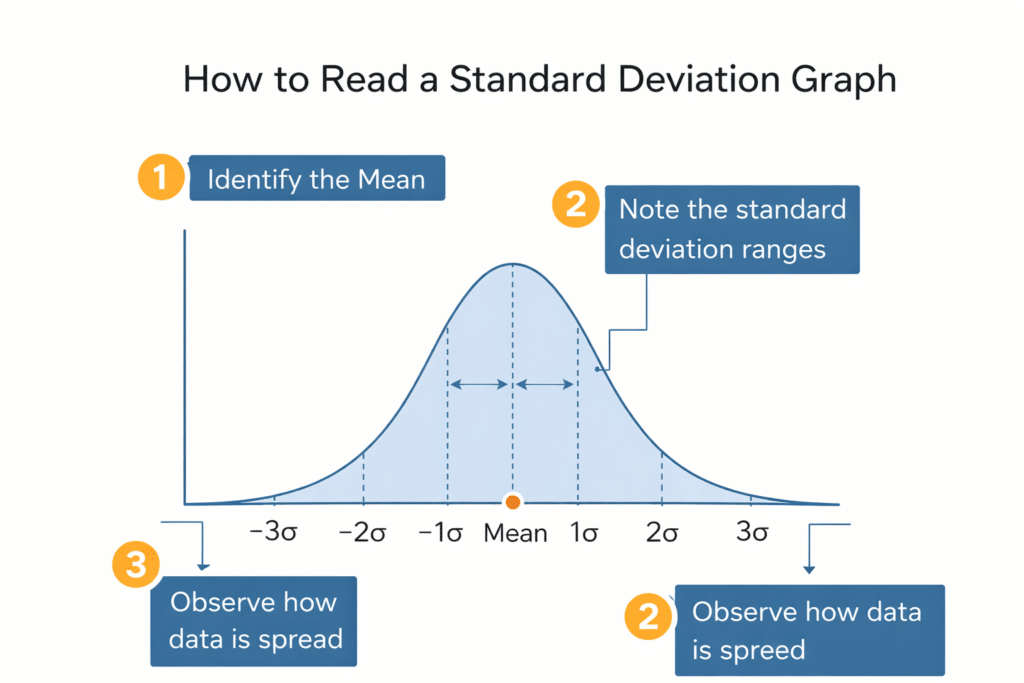
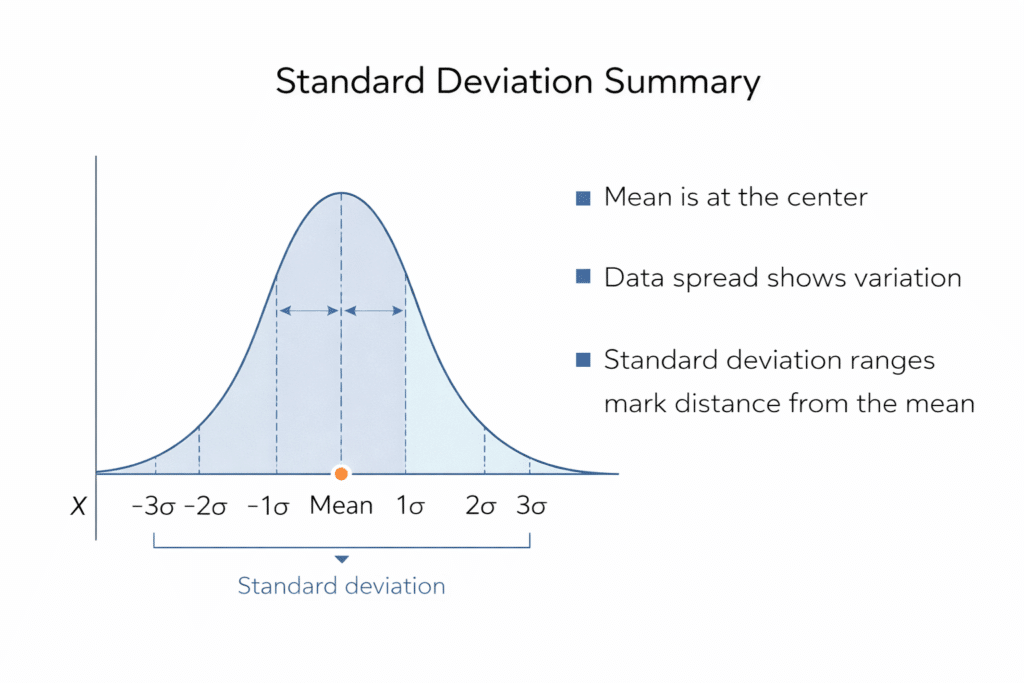
Most people learn standard deviation in a statistics class and then never really understand what they're looking at when they encounter it in actual work. I've sat in meetings where someone would throw out a mean and a standard deviation and everyone would nod like they got it. They didn't. Here's what actually matters. Start with the mechanics because everything else builds on them. Standard deviation measures spread around the mean. That's it. It tells you roughly how far individual data points tend to sit from the average. A small number means most values cluster tight around the mean. A large number means they're scattered wide. In a normal distribution, about 68 percent of observations fall within one standard deviation of the mean, 95 percent within two, and 99.7 percent within three. Those are the empirical rule numbers you probably memorized and promptly forgot. The formula itself is straightforward enough that you don't need to compute it by hand anymore. Take every value, subtract the mean from each one, square those differences, average the squared differences for population standard deviation or divide by n minus one for sample standard deviation, then take the square root. The square root part is what brings the units back to something readable. Without it you'd be working in squared units, which is useless for interpretation.
I remember running into this problem a couple years back when a client sent me their manufacturing defect rates across three production lines. Line one had a mean defect rate of 2.1 percent with a standard deviation of 0.3. Line two averaged 1.8 percent but with a standard deviation of 1.4. Line three sat at 3.5 percent with a standard deviation of 0.2. My initial reaction was to flag line three as the problem because the average was highest. That would have been wrong. Line two was actually the riskiest line in practice because its high standard deviation meant occasional spikes well above 1.8 percent, sometimes hitting six or seven percent. The mean hid that entirely. The standard deviation revealed it. I ended up recommending they investigate line two's process variation instead of line three's baseline level.
The Parts People Get Wrong About Interpretation
There's a common misunderstanding that standard deviation describes the shape of the distribution. It doesn't. It's a single number summarizing dispersion, nothing more. Two completely different shaped distributions can share the exact same standard deviation. One could be normal and bell-curved, another could be uniform, another could be bimodal, and their standard deviations would still match. If you need to understand the shape, look at histograms or use other metrics. Standard deviation alone won't give you that. Another thing nobody emphasizes enough is the difference between population and sample standard deviation. The formula changes by that division step. Population uses N in the denominator. Sample uses N minus one. That's Bessel's correction, and it exists because sample standard deviations tend to underestimate the true population spread if you don't adjust for it. Using N instead of N minus one in a sample will systematically bias your result downward. In practice with small samples this matters a lot. With samples over a few hundred it barely matters. But if you're pulling data from a subset and treating it as if it represents a whole population, you need to know which version you're computing and whether your software has already applied the correction or not. Many tools default to one or the other without warning you. The units point is worth returning to because it's practically important. Standard deviation shares the same units as your original data. If you're measuring temperature in degrees Celsius, your standard deviation is in degrees Celsius. That makes it interpretable in a way variance never is. Variance is in squared units. If your data is in meters, variance is in square meters. Nobody can quickly look at a variance number and intuit what it means about the data. Standard deviation gets around that. That's why you almost always report standard deviation instead of variance unless you're doing further statistical calculations.
Get the Full Details

What Standard Deviation Misses Completely
Outliers dominate standard deviation. A single extreme value can blow it up dramatically because every deviation gets squared before averaging. This means standard deviation is not a robust measure. If your data has even a few outliers, standard deviation will overstate the typical spread. I ran into this constantly when analyzing website traffic metrics. One viral post could spike page views to ten times the normal level, and suddenly the standard deviation looked enormous even though the day-to-day variation was perfectly stable. In cases like that, I switched to interquartile range or median absolute deviation as complementary measures. They tell you about spread without being hijacked by extreme points. Standard deviation also assumes symmetry around the mean for comfortable interpretation. When data is skewed, the 68-95-99.7 rule stops being reliable. A right-skewed distribution with a long tail will have a mean pulled toward that tail, and the standard deviation will be larger than what most individual observations actually experience. In those situations, reporting the median alongside the mean and standard deviation gives a more honest picture. The median tells you where half the observations actually sit. The standard deviation tells you about overall dispersion but not where the bulk of the data lives. There's also the issue of comparability across different scales. You cannot meaningfully compare the standard deviations of two datasets measured in different units. And even when the units are the same, comparing standard deviations across datasets with very different means can be misleading. A standard deviation of five dollars sounds small for a product averaging two hundred dollars but enormous for a product averaging ten dollars. For cross-dataset comparisons, use the coefficient of variation instead. That's the standard deviation divided by the mean, expressed as a percentage. It standardizes dispersion relative to the scale of the data.
When Standard Deviation Is Actually Useful
The real power comes when you're working with normally distributed data and need to set expectations or tolerance bands. In quality control, you'll see standard deviation used constantly because control charts are built on multiples of it. Three-sigma limits mean you flag anything beyond three standard deviations from the mean as unusual. Under normal conditions, that should happen less than 0.3 percent of the time. If it happens more often, your process is likely out of control or your data isn't actually normal. Finance uses standard deviation as a proxy for risk. Portfolio managers talk about volatility, which is just standard deviation of returns over time. A stock with higher standard deviation is considered riskier because its returns swing more widely. This is a simplification because it treats upside and downside swings equally, but it's the industry standard shorthand and it works well enough for rough comparisons between assets with similar return profiles. Survey analysis relies on standard deviation too. When you report survey results, the mean response tells you the center, but the standard deviation tells you whether respondents actually agree or just split in opposite directions. A mean of four on a five-point scale sounds positive until you see the standard deviation is nearly one, which means responses are spread all over. People aren't aligned. That distinction changes how you interpret the findings entirely.
Practical Steps For Interpreting Standard Deviation
First, check whether the data is roughly normal. Plot it. A quick histogram or box plot will tell you in seconds if standard deviation is a fair descriptor. If the distribution is heavily skewed or has obvious outliers, note that limitation before making any claims based on the standard deviation alone. Second, compare the standard deviation to the mean. If the standard deviation is larger than the mean, that's a red flag for positively skewed data. Values can't go below zero in many real-world datasets, so a standard deviation exceeding the mean usually means the distribution has a long right tail. The mean is being pulled upward and the standard deviation is inflated along with it. Third, look at the range relative to the standard deviation. In a normal distribution, the range is roughly four to six times the standard deviation. If the range is much wider, you likely have outliers inflating the spread. If the range is much narrower, the data might be truncated or rounded.

Fourth, use standard deviation alongside other statistics. Mean and standard deviation together give you two dimensions of information. Add median, quartiles, and a visual if possible. Never rely on standard deviation in isolation, especially when presenting to people who aren't statistically trained. They'll fixate on the number without understanding what it implies about the underlying data. Fifth, consider the context and the purpose. Are you trying to detect anomalies? Standard deviation works. Are you trying to describe typical behavior? It can work but median and interquartile range might serve better. Are you comparing variability across groups? Make sure the groups are on similar scales or use the coefficient of variation.
Common Software Pitfalls
Excel's STDEV.P and STDEV.S functions are the population and sample versions respectively. People use them interchangeably all the time, which can introduce bias into their analysis. SPSS, R, and Python's numpy all handle this differently by default. R's sd function computes sample standard deviation. Numpy's std defaults to population standard deviation. If you're pulling numbers from different tools and they don't match, check which version each one used. The difference is usually small with large datasets but can be noticeable with small samples. Google Sheets has its own set of functions with slightly different naming. STDEVP and STDEV are the legacy versions for population and sample. There are also newer variants with the P suffix that behave the same way. It's confusing because the naming conventions shifted and older functions are still supported for compatibility. Don't assume two sheets using STDEV are computing the same thing if one is old and one is new. If you're building your own calculations from scratch, make sure you're not accidentally using a biased estimator when you think you're getting an unbiased one, or vice versa. It happens more often than you'd expect in ad hoc analysis scripts where someone copies a formula from Stack Overflow without checking which denominator it uses.
The Bottom Line
Standard deviation is a tool for measuring dispersion, not a complete description of your data. It's most trustworthy with symmetric, outlier-free, roughly normal distributions. Outside of that, it still has value but you need to be aware of what it's obscuring. Report it with the mean, check the distribution shape, watch for outliers, and pick complementary measures when standard deviation alone gives you a misleading story. That's about all there is to it.