The Hard Way
Most people start with documentation. That is backwards. You need to write code before you read anything else. Specifically, you need to write a loadable kernel module that prints to the kernel log buffer and see it compile and load on a real system. The first time you run insmod and dmesg shows your string, everything clicks differently than it would have reading any book. I remember writing my first out-of-tree module in 2016. It was a character device that echoed data back. I tried to read from a user-space pointer using a direct dereference and instantly panicked the machine. No error return. No graceful handling. Just a kernel oops that filled three pages of my terminal. The fix was copy_from_user(). That one mistake taught me more about the boundary between user-space and kernel-space than any tutorial ever could. You cannot touch user memory directly. Period. It is the single most fundamental rule, and it is also the first rule people ignore repeatedly.
How To Learn Linux Kernel Programming
Start by understanding that the kernel is not an application. It does not have a main function. It responds to interrupts, syscalls, and hardware events. The entry points are completely different from anything you have built before. A kernel module loads into a running kernel and registers itself. It does not start and stop. It is already there when the scheduler needs it, when the network stack needs it, when a block device needs it. You need solid C. Not application-level C. I mean bit manipulation, pointer arithmetic, structures with packed attributes, and a working understanding of how the stack actually works. If you are shaky on void pointers or can second-guess yourself on __user annotations, spend two weeks on those concepts before proceeding. The kernel is full of macros that expand into things that look like functions but are not. container_of is the most common example. It appears everywhere and beginners frequently mishandle it. You also need a working Linux development environment. A virtual machine with the source tree checked out and compiled is sufficient. Debian-based systems make this straightforward with apt install linux-headers-$(uname -r) and build-essential. Do not attempt this inside a container. Containers share the host kernel namespace and the debugging experience is degraded to the point of frustration.
The Build System Is Its Own Nightmare
Kbuild is the kernel's build system. It is not Make. It is Make with additional layers of abstraction that trip people up constantly. Your out-of-tree module needs a Makefile that references the kernel source tree using KDIR. A standard setup looks like this: This compiles in about 45 seconds on a modern machine if the kernel headers are cached. Without caching, the first build of a full kernel source tree takes roughly 20 to 30 minutes depending on core count. Factor that into your planning. Here is something nobody tells you: the kernel's own scripts/ directory contains every tool you will eventually need, including checkpatch.pl and spatch for semantic patching. Running ./scripts/checkpatch.pl on your patch before submitting it catches about 80 percent of the style issues that cause maintainers to reject patches on sight. I wasted three days on a patch rejection once because I had spaces instead of tabs in a comment block. The technical content was fine. The style was not.
Get the Full Details

Start With a Character Device Driver
A character device is the simplest real driver. It has an open, read, write, and release function. It does not involve hardware, DMA, or interrupt handling. This is your training wheels. Write a driver that allocates a buffer, copies data between user-space and kernel-space using the proper APIs, and returns byte counts. That is it. The _IOR, _IOW, and _IOWR macros in linux/ioctl.h generate ioctl command numbers. You will use these in your file operations struct. They encode direction, type, and size. Beginners often pass raw integers and then wonder why their ioctl handler receives garbage. When you load your module, register it with alloc_chrdev_region() or register_chrdev(). The former is preferred because it allocates dynamically. The latter assigns a static major number and will fail if another driver is already using that number. I once spent two hours debugging a mysterious load failure before realizing another module had already claimed major number 240. Dynamic allocation solves this entirely.
Reading the Source Changes Everything
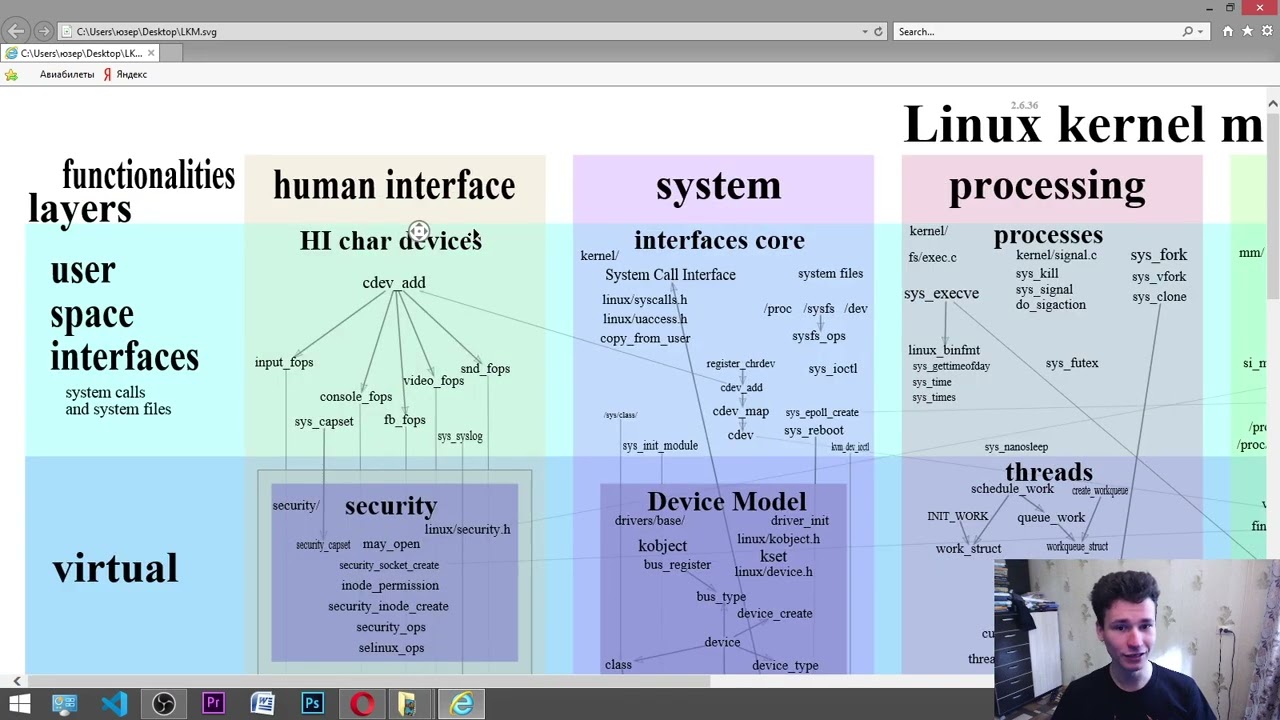
After your first module works, you need to read the actual kernel source for the subsystem you are working in. If you built a character device, read fs/char_dev.c and fs/file_table.c. Do not expect it to be readable immediately. It will not be. Read it anyway. Start with the public interfaces and work inward. Follow chrdev_open to inode_iops to the actual file operation dispatch. You will find the same patterns repeating across thousands of lines of code. The kernel is not written linearly. Functions call other functions that call others again. The call graph is a dense web. Use cscope or ctags or the newer clangd with kernel symbols to navigate. vim with ctags set up properly cuts your navigation time significantly compared to searching text with grep alone.
Common Pitfalls
Sleeping in Atomic Context
You cannot sleep in interrupt context. This sounds obvious until you write a driver that calls kzalloc() with GFP_KERNEL from an interrupt handler and the system hangs. Use GFP_ATOMIC in interrupt handlers. In process context, GFP_KERNEL is fine. The allocator will sleep and wait for memory if needed. In atomic context, sleeping is impossible and the kernel will oops if you try. Similarly, you cannot take a mutex from interrupt context. Use spinlock_t instead. Spinlocks disable preemption on the current CPU and prevent the scheduler from switching away while you hold the lock. Mutexes can sleep. Do not mix them up. Lockdep exists precisely to catch this class of bug at runtime. Enable it with CONFIG_LOCKDEP=y in your kernel config. It adds overhead but it caught a deadlock in my first real driver that would have been nearly impossible to reproduce otherwise.

Memory Allocation in the Kernel
kmalloc is not malloc. It allocates from the kernel's slab allocator, which manages caches of pre-sized objects. Common sizes like 32, 64, 128, 256, 512, and 1024 bytes have dedicated caches. Allocating exactly 64 bytes with kmalloc is cheaper than allocating 65 bytes because the latter falls into a different cache slab. This matters when you are allocating thousands of structures per second in a network driver. vmalloc allocates virtually contiguous memory but the underlying physical pages may be scattered. Use it for large allocations where virtual contiguity matters more than physical contiguity. dma_alloc_coherent is for hardware that needs physically contiguous memory for DMA transfers. Each allocator serves a different purpose. Using the wrong one causes silent data corruption that is extremely difficult to debug.
Races and Concurrency
The kernel runs on SMP systems. Your code executes concurrently on multiple CPUs. smp_load_acquire and smp_store_release provide the memory ordering guarantees you need when sharing data between CPUs without a lock. Standard load and store do not provide these guarantees on weakly-ordered architectures like ARM. This is a common source of bugs that only manifest under heavy load or on specific hardware. I once had a driver where a flag was read on CPU 0 and written on CPU 1 without proper memory barriers. It worked perfectly on x86 and failed intermittently on ARM servers in production. The fix was replacing plain reads and writes with smp_load_acquire and smp_store_release. The code looked identical. The behavior was completely different.
Tools That Actually Help
KASAN (Kernel Address Sanitizer) detects out-of-bounds accesses and use-after-free bugs. Compile your kernel with CONFIG_KASAN=y and CONFIG_KASAN_INLINE=y. It adds roughly 2x memory overhead and 1.5x execution overhead but it catches bugs that would otherwise manifest as random panics weeks later. I recommend running with KASAN enabled during development on your test VM. The overhead is acceptable when you are iterating quickly. KFENCE is a newer alternative to KASAN that has lower overhead. It is still maturing but worth monitoring if you run a recent kernel. ftrace is the kernel's built-in tracing framework. function_graph tracer shows you the call graph of any function in real time. Run echo function_graph > /sys/kernel/debug/tracing/current_tracer and then trigger your driver code. You get a textual call graph output showing every function entered and exited. This is invaluable for understanding execution flow without setting breakpoints in GDB, which is another viable option but requires kernel debugging symbols and a separate debugger session.

bpftrace and BPF programs let you trace kernel behavior from user-space without modifying kernel code. This has become the standard approach for performance analysis and debugging in modern kernels. Learn BPF. It is the future of kernel observability and it is available in kernels from 4.8 onward.
The Mailing List Reality
If you plan to contribute patches upstream, you will deal with the Linux kernel mailing list. Patches go through git format-patch, are sent with git send-email, and receive review comments that are often harsh. This is normal. The process is designed to be rigorous because bugs in the kernel affect every system running it. A single null pointer dereference in a network driver can crash an entire server farm. Subscribe to the mailing list for your subsystem before submitting. Read existing patches. Understand the review culture. Reply-all is mandatory. Do not CC random people. Use --to and --cc flags correctly in git send-email. I have seen experienced developers get their patches rejected on the first submission for violating basic mailing list etiquette. Technical correctness alone does not get patches accepted.
Recommended Progression
Month one: character device driver with read/write/ioctl. Read fs/char_dev.c and understand the vma and inode structures. Get comfortable with kmalloc, copy_from_user, and file operations. Month two: a platform driver. This introduces device tree binding, of_match_table, and hardware register access. Read drivers/platform/ for reference implementations. Understand why ioremap is necessary for memory-mapped hardware. Month three: an interrupt-driven driver. Request an IRQ with request_threaded_irq. Handle the interrupt in a threaded context. Debounce if needed. This is where spinlocks and atomic context rules become critical.
Month four: a network device driver or a block driver. These are significantly more complex. Pick one based on your interest. Network drivers require understanding net_device and the networking stack. Block drivers require understanding the block layer, request queues, and the elevator. At each stage, read the existing kernel source for similar drivers. The kernel already has drivers for everything you will attempt to build. Studying them is faster than inventing your own approach.
What This Approach Does Not Cover
This guide focuses on out-of-tree module development, which is the practical entry point. It does not cover in-tree development, kernel configuration, cross-compilation for embedded targets, or real-time kernel patching (PREEMPT_RT). Those are separate topics that become relevant once you have the basics down. Also, this does not address the growing importance of eBPF as an alternative to traditional kernel modules for many use cases. If your goal is network packet processing or observability rather than hardware drivers, eBPF may be a more productive path than learning C in the kernel. The kernel source tree at https://git.kernel.org/pub/scm/linux/kernel/git/torvalds/linux.git is the authoritative reference. Clone it, branch it, and start breaking things in a VM. That is the only way this works.