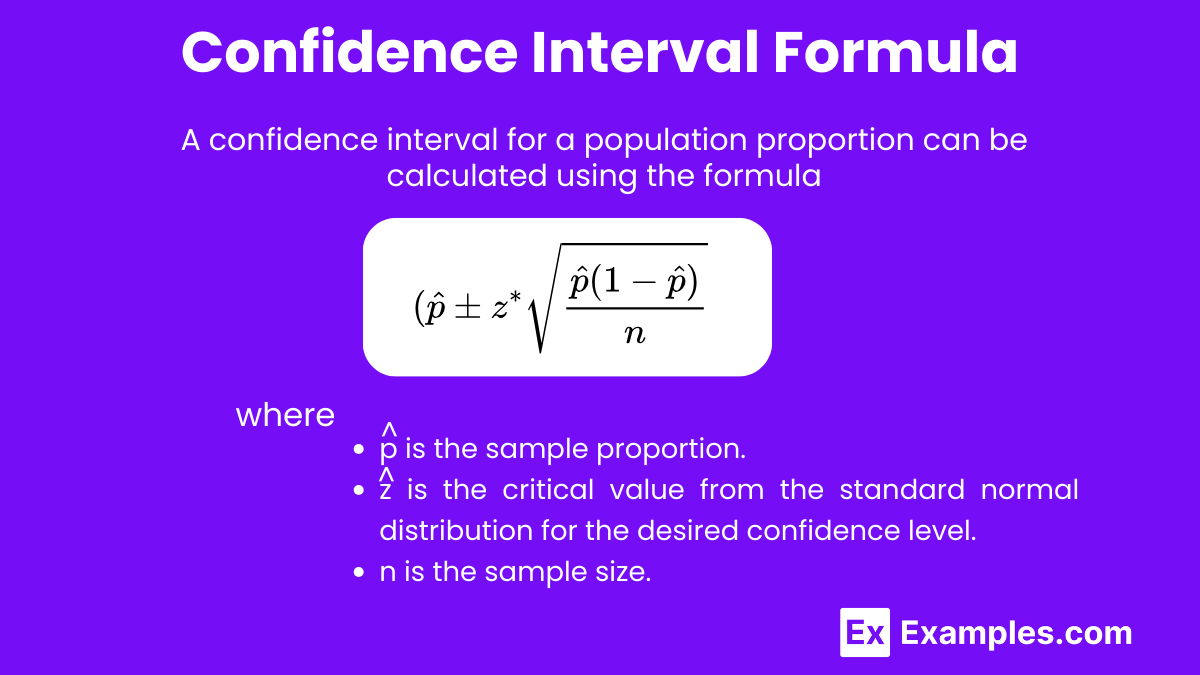
Confidence Intervals for Proportions: The Actual Method
Most people learn the standard Wald interval in intro stats and never question it. That usually comes back to bite them. The formula looks simple enough—take your sample proportion, add and subtract the margin of error, and you're done. It's not. For anything but large samples with proportions near 0.5, the Wald method produces intervals that miss their target coverage rate substantially. You want to know the actual mechanics, not the simplified textbook version. Start with your data. You have a sample of size n, and x successes out of those n trials. Your point estimate is p-hat equals x divided by n. For the standard large-sample Wald interval, you calculate the standard error as the square root of p-hat times one minus p-hat, all divided by n. Multiply that standard error by the appropriate z-value—for a 95 percent confidence level, that is 1.96—and you get your margin of error. Add and subtract it from p-hat. Here is where it gets fiddly in practice. That Wald interval assumes the sampling distribution is approximately normal, which requires both np-hat and n times one minus p-hat to be at least five, though many practitioners prefer ten as a cutoff. When you violate that assumption, your interval can land partly outside the zero-to-one range, which is mathematically nonsensical for a proportion.
I ran into this problem last year when analyzing survey data from a niche online community. We had roughly 120 respondents and were looking at the proportion who reported a very uncommon symptom—about four percent prevalence. The Wald interval produced a lower bound below zero. I switched to the Agresti-Caffo interval, which adds two pseudo-successes and two pseudo-failures to the data before computing everything. It shifted the estimate slightly upward and gave me a lower bound of positive 0.01 instead of negative territory. For this sample size and proportion, that adjustment made the difference between an interval that was usable in a report and one that would have raised questions from anyone who knew what they were looking at. The Agresti-Caffo adjustment is conservative, meaning it tends to produce slightly wider intervals than nominal. That is usually preferable to undercoverage. Another option worth knowing about is the Wilson score interval, which does not rely on the normal approximation in the same way and performs well across a much broader range of proportions and sample sizes. It is the default in R's binom.confint function and in many modern statistical packages for good reason. There is a practical consideration that does not show up in textbooks. When you are working with weighted survey data, the effective sample size is almost always smaller than the raw respondent count. If your design weight has a coefficient of variation above 0.3, you should deflate your nominal n before applying any interval formula. Ignoring this will make your intervals too narrow and give you false confidence in precision you do not actually have.
For small samples below thirty observations with rare events, exact methods based on the Clopper-Pearson distribution are available. They guarantee at least the nominal coverage level but tend to be overly conservative, producing intervals that are wider than necessary. I use them as a last resort when the Wilson interval still produces unintuitive results, which happens when x equals zero or x equals n. Software choices matter here. In Python, the statsmodels library has proportion_confint with options for Wilson, Agresti-Caffo, and beta intervals. In R, the binom package covers nearly every method I have encountered in practice. Writing your own implementation is possible but easy to get wrong on edge cases. The time saved by using a vetted function library is usually worth more than the theoretical understanding you gain from coding it from scratch.
Get the Full Details