The part nobody tells you before you start
I spent three weeks building a supply chain optimization model for a mid-sized logistics company last year. The final version took about forty minutes to run. The first version — the one I threw out — took six hours and produced results that looked plausible but were wrong in ways that mattered. That happens a lot. You build something that compiles, you trust the output, and then reality shows up and it doesn't match. The process of figuring out how to make a mathematical model properly is mostly about learning what not to skip. People rush the assumptions. They skip the sanity checks. They treat the model like a black box instead of a living thing that needs to be questioned at every step.
How To Make A Mathematical Model
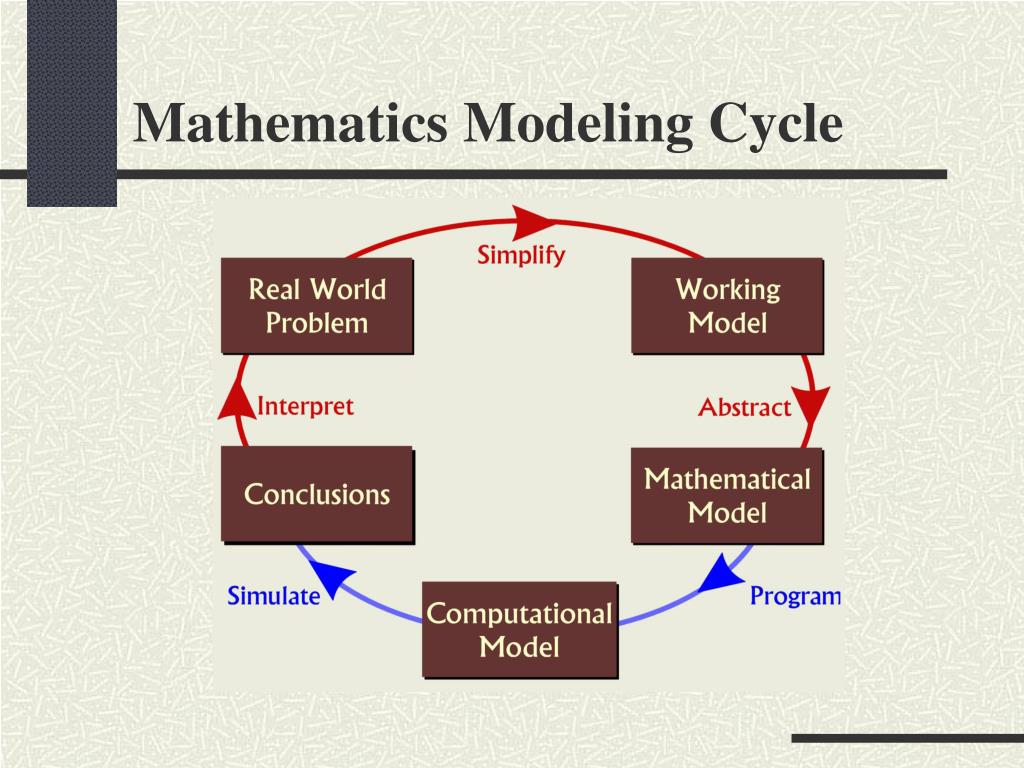
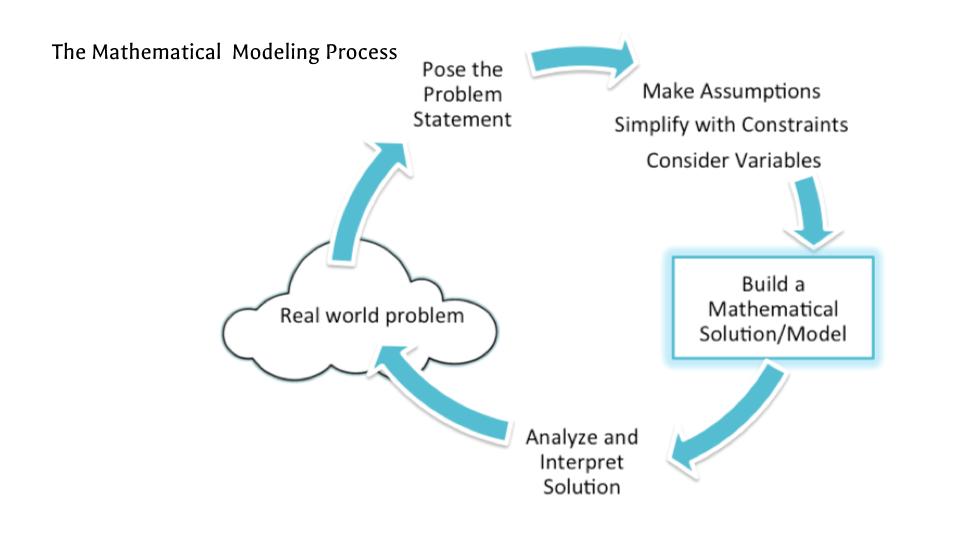
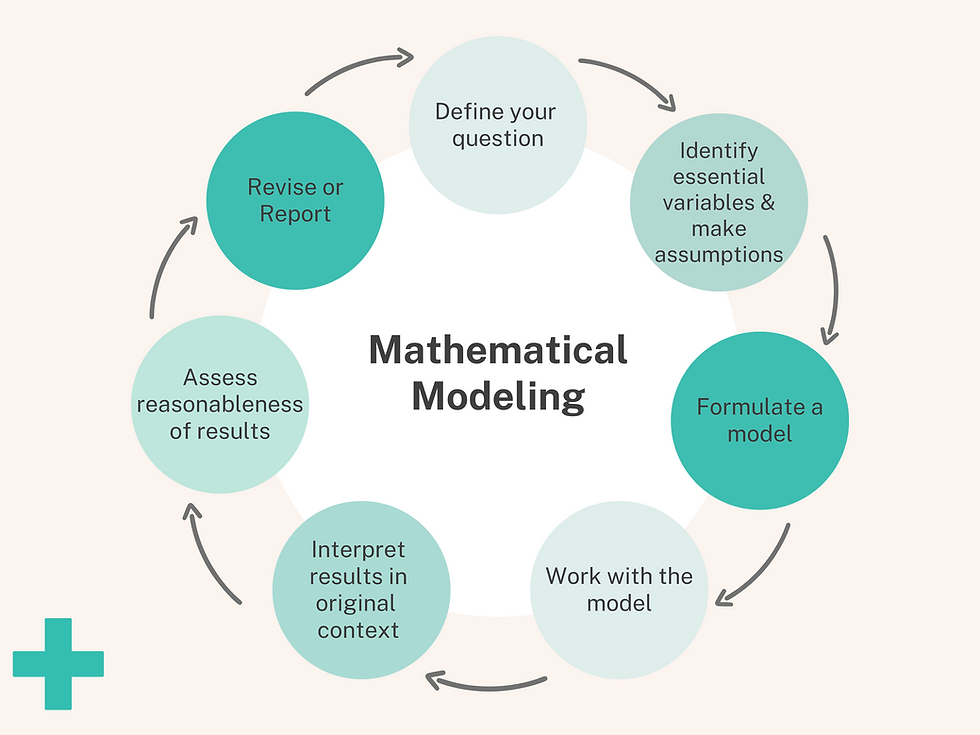
You start by writing down what you actually want to know. Not what you think the model should tell you. What you need to decide. This sounds obvious but most people start with data instead of objectives. They download a spreadsheet, fire up Python, and then figure out three days later that they were solving the wrong question. Define your decision variables first. These are the unknowns you are trying to find. If you are modeling inventory, they might be quantities of product ordered each week. If you are modeling a routing problem, they could be binary variables indicating whether a truck takes a particular path. Get these down on paper before you touch any code. Then write the objective function. This is the single mathematical expression that captures what "best" means in your context. Minimize cost. Maximize throughput. Minimize delay. It has to be one thing, or you need to combine multiple goals into a weighted sum and document exactly how you decided on those weights. I've seen projects fail because the stakeholder didn't realize the optimization was silently prioritizing cost over service level.
Constraints come next. These are the boundaries your solution has to respect. Demand must be met. Capacity cannot be exceeded. You can't ship negative quantities. Write every constraint explicitly. I once worked on a model where someone forgot to constrain a flow variable to be non-negative and the solver returned a solution involving negative inventory, which the client initially interpreted as some kind of time-travel technology before we caught it.
Get the Full Details

Choosing the right solver and setting it up
For linear problems, CBC, GLPK, or Gurobi depending on your budget. For mixed-integer problems, Gurobi or CPLEX will save you from pulling your hair out. Open-source options like HiGHS are getting decent. The choice matters more than people admit because a bad solver configuration can turn a five-minute run into a five-hour run, or make an infeasible problem silently return garbage instead of telling you it's infeasible. Set your solver parameters correctly. MIP gap tolerance, time limits, presolve settings. I usually start with a presolve enabled and a reasonable MIP gap around 0.01 for production models. For prototyping, you can loosen it. But don't leave everything at defaults and pretend you understand what's happening under the hood. Use a modeling language rather than raw matrix assembly unless you have a good reason not to. Pyomo, JuMP, or AMPL will save you from writing hundreds of lines of constraint generation code. I switched to Pyomo about four years ago after spending a weekend writing constraint loops by hand for a scheduling problem. I got it working. I also got it wrong in one corner case that only showed up under edge-case demand patterns. The modeling language catches those kinds of mistakes faster because the syntax mirrors the math.
Validation before you trust it
This is where most people stop and ship something they aren't confident in. Run historical data through the model and see if it reproduces known outcomes within a reasonable tolerance. If your demand forecasting model can't reconstruct last quarter's numbers, it is not ready for next quarter's decisions. Check feasibility and sensitivity separately. A model can be feasible and still be brittle. Change one parameter by ten percent and see if the solution structure collapses or adapts gracefully. I built a staffing model for a hospital unit once where the optimal schedule looked efficient on paper but fell apart when I introduced a single absenteeism event. The model had no slack built in because I hadn't included a constraint for backup shifts. It was technically correct and practically useless. I added the constraint and re-ran it. The solution changed by about eight percent in cost but became something a shift supervisor could actually work with. Document your assumptions. Every single one. The model will outlive your memory of why you made certain choices, and the next person who touches it will not either. I keep a separate assumptions file alongside the model code. It's not glamorous. It's also what prevents me from being confused by my own work six months later.
When the model breaks and what to do about it
Models fail. Usually because the real world is messier than the formulation allows. Nonlinearities get linearized poorly. Discrete events get smoothed over. Time dependencies get ignored because they complicate the structure. When your results look wrong, don't adjust the model to fit the answer you want. Adjust the model to reflect the mechanism you're actually trying to capture. If your problem is too large for exact methods, consider decomposition or heuristic approaches. Benders decomposition works well for problems with a block structure. Genetic algorithms or simulated annealing can give you decent solutions when the search space is too big for branch-and-bound. I use a rule-based heuristic as a warm start for mixed-integer problems now. It cuts solving time from around twenty minutes to about three on a reasonably sized instance. Not all problems benefit from this, but many do. There are also problems where mathematical modeling is the wrong tool. Causal inference questions, systems with high uncertainty and low historical data, or problems where human judgment and context matter more than optimization. I've seen people try to force optimization frameworks onto situations that needed scenario planning or simple simulation instead. It produces precise but misleading results, which is worse than no result at all.
Practical workflow that actually works
I don't write the full model from scratch anymore. I keep a template with the standard pieces — variable declarations, parameter definitions, objective construction, constraint generation, solver invocation, result extraction — and fill in the domain-specific parts. It takes me about an hour to set up a new linear or mixed-integer model now, down from maybe three or four hours when I was doing everything fresh. The time savings comes from not reinventing the wheel on boilerplate and from catching structural mistakes before they compound. Test each component as you add it. Run the objective function with dummy values. Verify constraints one at a time. Check that your data pipeline is feeding the model correctly. Data issues cause more model failures than mathematical issues. I had a project where the solver kept returning infeasible and we spent two days debugging the optimization logic before someone noticed the demand data had a unit conversion error. Millions of dollars were misaligned because one parameter was in kilograms instead of grams. Version control the model and the data separately. Keep snapshots of intermediate versions. When you make a change and the results shift unexpectedly, you need to be able to go back and compare. I use Git for the code and store datasets with timestamps in a separate directory. It's boring infrastructure but it saves you from the panic of not knowing which version produced which output.
Limitations you should accept upfront
A mathematical model is a simplification. It will always miss something. The question is whether it misses the right things and whether the error is bounded and understood. If you cannot articulate what the model does not capture, you should not be using it for decision-making. Linear models approximate nonlinear reality. Integer models assume discrete decisions when continuous approximations might exist. Stochastic models require distributional assumptions that are rarely verified thoroughly. Every modeling choice involves a tradeoff between tractability and fidelity. There is no free lunch. Acknowledge it in your documentation and in your communication with whoever is using the model. If you need something faster than an exact solution and the problem structure allows it, consider whether a surrogate model or a simplified analytical approximation would serve the use case better. Sometimes a rough answer quickly is more valuable than a precise answer hours later. I've seen teams burn through computational resources on large-scale optimization when a well-calibrated regression model or a rule-of-thumb heuristic would have been sufficient for their actual decision needs.
The core discipline is restraint. Build the simplest model that captures the essential structure of the problem. Validate it against known cases. Document what you left out. Iterate when the results don't hold up. Don't mistake a clean formulation for a true one.