Plotting Data Points Without Losing Your Mind
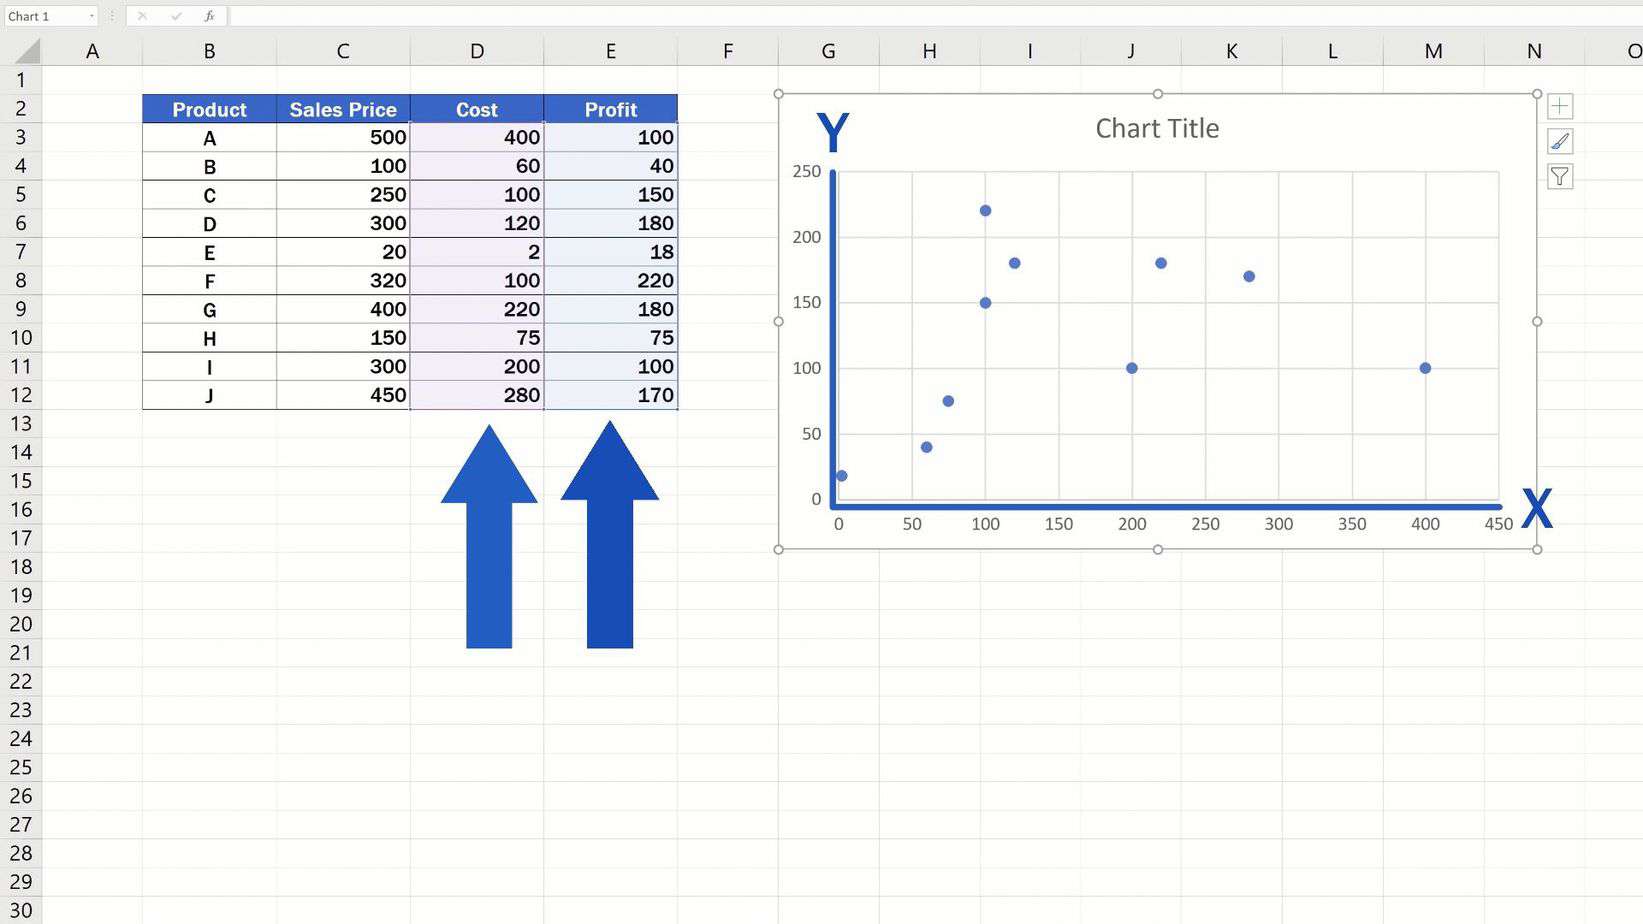
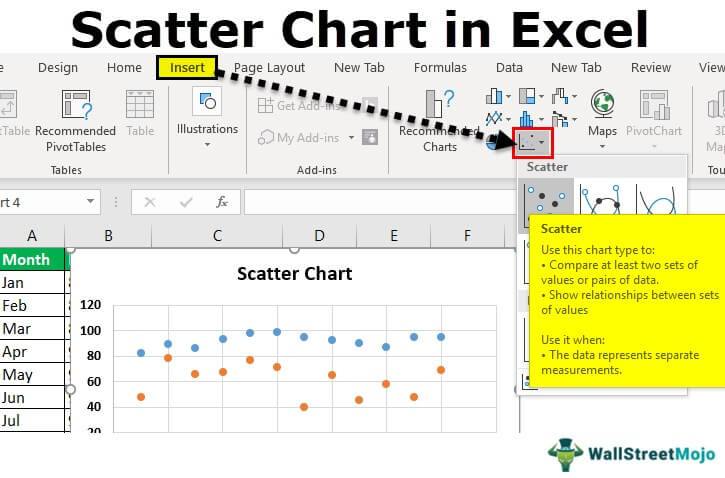
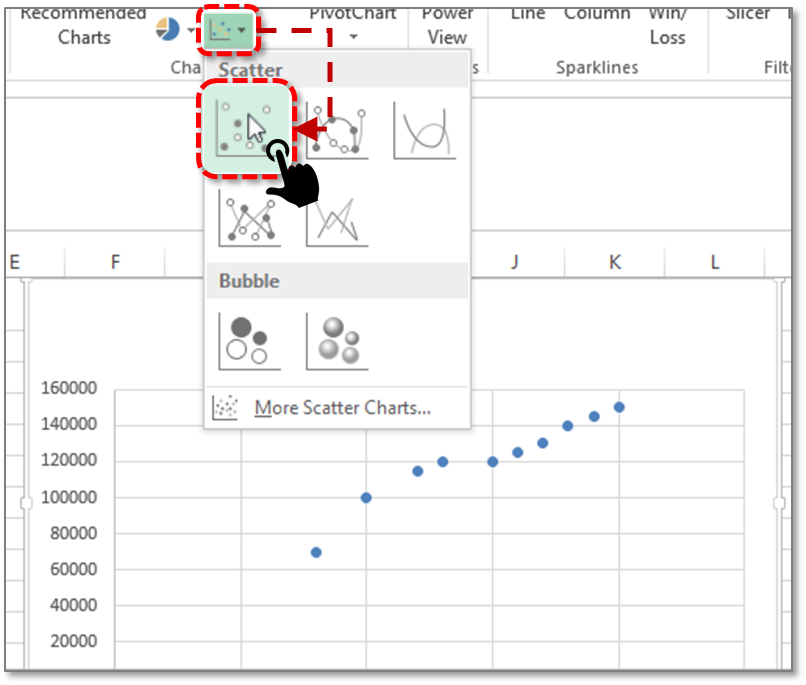
Open Excel, dump your data into two adjacent columns, highlight both columns, and go to Insert > Charts > Scatter. That is the literal process. Most people think they need to find some obscure menu or install a plugin, but the chart type is right there in the built-in gallery under the X Y (Scatter) group. The default scatter plot will draw each row as a single point based on the X value in the first column and the Y value in the second. Nothing fancy, nothing wrong with it for basic use. I have watched people struggle with this for twenty minutes when they do not understand how Excel interprets the data range. Here is what actually happens step by step. Put your independent variable data in column A and your dependent variable in column B. Select both columns including the headers. Click Insert, then the Scatter icon in the Charts section, and pick the first option with just dots and no lines. Excel assigns column A to the horizontal axis and column B to the vertical axis automatically. If your axes are flipped, click the chart and go to Chart Design > Switch Row/Column. That is it for a basic plot. The definition of a scatter plot is straightforward: it displays individual data points on a two-dimensional grid where each axis represents one variable. You use them when you want to see if two numerical variables have a relationship. Unlike a bar chart that groups categories, a scatter plot shows raw correlations or lack thereof between continuous values. People sometimes confuse them with line charts, but a line chart implies ordering and continuity between points, while a scatter plot treats each point as independent. That distinction matters more than most beginners realize because it determines whether you are misrepresenting your data.
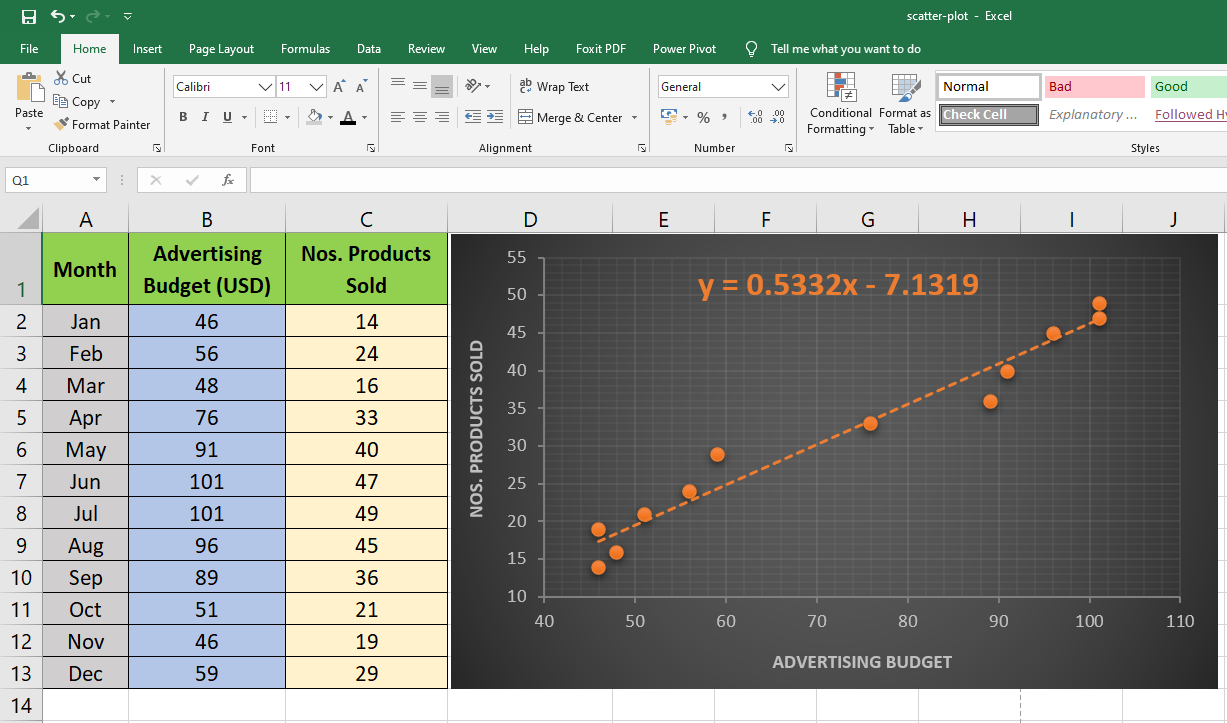
I had a situation last year where someone sent me a workbook to fix. Their scatter plot showed hundreds of points, but half of them were missing. It turned out they had included text labels in the same column as their numeric data, and Excel silently dropped every row that contained non-numeric values instead of flagging an error. The chart looked fine at first glance because the remaining points formed a reasonable pattern. What they were actually looking at was a selective subset that happened to cluster in one region. The workaround was filtering for blank cells and non-numeric entries before building the chart, then using Data > Validate to prevent bad input from getting in there in the first place. I also converted the range to an actual Excel Table with Ctrl+T so that new data would be automatically included and properly typed. One thing Excel does that trips people up constantly is how it handles empty cells. If there is a gap in your X or Y data, Excel will either skip that point entirely or connect lines across the gap depending on which scatter subtype you chose. The smooth-line variant can create misleading visual impressions that suggest a relationship where none exists. Always verify your raw data before committing to a chart style. Another nuance is the difference between the scatter types: the standard scatter will space points by their numeric value, while the stacked variant can create artificial trends if you are not careful about which data series you combine. For a real example, say you have sales figures in column A and customer satisfaction scores in column B, both running from row 2 to row 500. After selecting both columns and inserting the scatter, you would right-click any point, choose Add Trendline, and check the display R-squared value box. If the R-squared comes back at 0.03, your variables are effectively unrelated regardless of whatever pattern your eye thinks you see. Human beings are terrible at intuitively judging correlation from scatter plots without a reference line. I always add the trendline and let the number speak instead of my own bias.
There are legitimate downsides to relying on Excel for scatter plots if your dataset is large. Once you push past roughly 10,000 points, rendering becomes noticeably slow and the chart starts lagging your entire spreadsheet. Excel was never designed as a statistical visualization tool. For dense data clouds, you are better off exporting to R or Python and generating a proper high-density scatter plot with alpha blending. Even a mid-range dataset of 2,000 to 5,000 points can produce overlapping markers that make the chart unreadable. In those cases, adding a jitter function or switching to a hexbin approach helps, but Excel does not have a native hexbin scatter option. You end up building workarounds with conditional formatting or creating a helper column that adds random noise to the coordinates. If you need to save time on repeated chart creation, recording a macro once and reusing it cuts the process down from manual effort to a single click. I keep a personal macro workbook with a basic scatter plot template that I apply whenever I get a new dataset with the same column structure. It does not save much time per chart, maybe three to five minutes, but it prevents small mistakes like forgetting to switch axes or applying the wrong series grouping. The real time sink is usually cleaning the data, not generating the plot itself. Spend your energy on getting the numbers right before you worry about the chart aesthetics.
Get the Full Details