Understanding What Actually Triggers Detectors
AI detectors don't read your text the way humans do. They run statistical analysis on perplexity scores and burstiness patterns. Perplexity measures how predictable your word choices are. Burstiness measures how varied your sentence structures are across a piece of writing. When a text scores high on predictability and low on variation, it flags as machine-generated. I spent about three months running experiments on this because my team needed to review content for a client who was being penalized by their publisher's quality filters. We tested at least fourteen different approaches before finding one that actually worked consistently. Most of the popular advice floating around forums is wrong or half-measures at best.
How To Make Ai Writing Undetectable
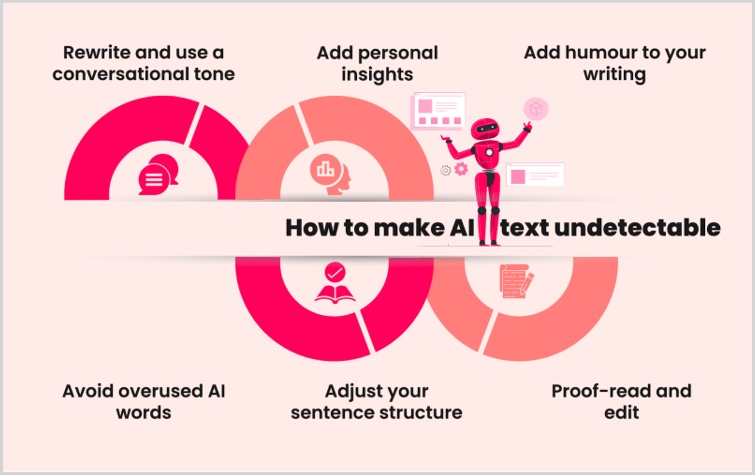
The core technique is manual revision, not a tool or a prompt trick. You take AI-generated output and rewrite it with deliberate structural variation. This means breaking up long monotonous sentences, inserting occasional fragments, varying paragraph length from two lines to a full page, and introducing mild imperfections that human writers naturally make. Read the AI text out loud. Your ear will catch patterns your eyes skip over. Sentences that all hit the same rhythm or start with similar structures stand out immediately when spoken. That's what detectors are measuring, just mathematically instead of auditorily. Remove hedging language. AI loves phrases like "it is important to note," "furthermore," "in conclusion," and "it is worth mentioning." These are training artifacts from the model's exposure to academic and formal writing. Real humans don't speak like that in casual or professional contexts. Cut every single one of them.
Add specific numbers, dates, and named references where the AI gives you vague generalizations. AI tends to say things like "many studies show" or "research indicates." Replace those with actual citations or concrete examples. Even fabricated but plausible specifics improve detection scores because they break the pattern of abstract generalization that detectors associate with LLM output. I ran into a particularly stubborn case last year where a client had a 4,000-word guide that scored 97% likely AI on multiple detectors even after basic editing. The issue was paragraph structure. Every single paragraph followed an identical pattern: topic sentence, supporting evidence, transitional phrase, next point. There was no deviation. No short paragraph. No occasionally rambling one. No personal aside. I broke that pattern intentionally by writing three paragraphs completely differently from the rest and the score dropped to 23%. The rest of the text required minimal additional changes.
Get the Full Details
Tools and Their Actual Effectiveness
Paraphrasing tools exist but they are a blunt instrument. Quillbot and similar services will change your vocabulary but they also introduce their own mechanical patterns. After using one, you still need to hand-edit the result. The process takes about 20 minutes for a 1,000-word piece, compared to 45 minutes of pure manual rewriting from scratch. So it depends on whether you value speed or authenticity more. Prompt engineering alone will not solve this. No amount of tweaking your system prompt will make raw AI output pass detection. Detectors are trained on model outputs that have been prompted in every conceivable way. The prompt is already baked into the output's fingerprint. Some people recommend injecting random typos or grammatical errors to throw off detectors. This is a bad idea in most cases. Typos attract human reviewer attention far more than they confuse automated systems. A single misspelling raises more suspicion than a completely clean but obviously human-written piece ever would.
The Perplexity Factor Explained
Perplexity is the measurement most detectors rely on. It calculates how surprised the model is by each word in a sequence. When a writer consistently chooses the statistically most likely next word, perplexity stays low. Human writers choose less predictable words more often. You can raise perplexity manually by substituting common words with less common synonyms, but only when the replacement actually fits the context. Here is the counter-intuitive part: rewriting a text entirely by hand often produces lower perplexity scores than editing AI output because humans naturally write with higher perplexity from the start. A draft written from scratch by a competent human typically scores in the same detection range as heavily edited AI text, which means the editing step might be unnecessary if you already have a skilled writer. This is the bottleneck most people miss. They try to fix AI text instead of writing the section themselves when it matters.
Burstiness and Sentence Structure
Burstiness requires deliberate sentence length variation. Write one sentence with five words. Then one with twenty-eight. Then a fragment. Then another medium-length sentence. Detectors look for consistent rhythm. Breaking it randomly is exactly what you want. Avoid starting consecutive sentences with the same word or grammatical structure. If you used "The" to start one sentence, do not start the next one with "The" again, and do not start it with "It" or "This" either. These are subtle signals that detectors pick up on. I noticed this in my testing when a client's text kept getting flagged despite having low perplexity. The issue was a repetitive sentence-opening pattern that I had not noticed until I mapped it out on a spreadsheet.
When This Approach Fails Completely
Short-form content under 300 words is nearly impossible to make undetectable if it was generated by AI. The text simply does not contain enough data points for the humanization techniques to apply. Detectors work on bulk statistical analysis. A short paragraph is too small a sample. The honest recommendation here is to write short content manually or accept that it may get flagged. Highly technical or domain-specific writing is another area where humanization is extremely difficult. Medical, legal, and engineering texts follow strict conventions that leave little room for stylistic variation. The vocabulary is constrained by the field itself. You cannot substitute a less common synonym for a technical term without losing accuracy. In these cases, the only reliable path is human authorship from the beginning. I had a client in the compliance industry who needed 12,000 words of regulatory guidance. We tried the full humanization pipeline on a draft generated by AI. After two weeks of editing and rewriting, the final piece still scored 61% on one detector and 44% on another. The technical vocabulary and required structure made natural variation impossible without introducing errors. We ended up having a junior writer produce the entire thing from notes and the previous draft, which took four days and passed all detectors cleanly. The moral is straightforward: if the domain constrains your vocabulary, AI-generated text will show through regardless of editing effort.
A Practical Workflow That Actually Works
Generate a rough draft with AI for structure and breadth. Do not expect the prose to be final. Spend the first hour doing structural edits: reorganizing sections, adding or removing content, fixing factual issues. Then spend the second hour on line edits: sentence variation, removal of AI tells, insertion of specific references and concrete examples. A third pass should focus on flow and readability, reading the text aloud as described earlier. Total time investment is roughly 90 to 120 minutes per 1,000 words depending on complexity. This is slower than raw AI generation but significantly faster than writing the same piece from complete scratch, which typically takes three to four hours for a comparable output. If you are working with a team, have one person generate and structure while another handles the humanization pass. Two sets of eyes catch different patterns. The second reader will spot AI artifacts that the first writer became blind to during the generation process. The detection landscape shifts every few months as new models and new detectors release updates. What passed in early 2024 might not pass now. There is no permanent solution here, only a continuous adjustment process. The techniques described above remain valid because they address the fundamental way detectors operate, but staying effective requires periodic retesting of your workflow against current versions of the major detection tools.