The Problem With Your Statistics Workflow
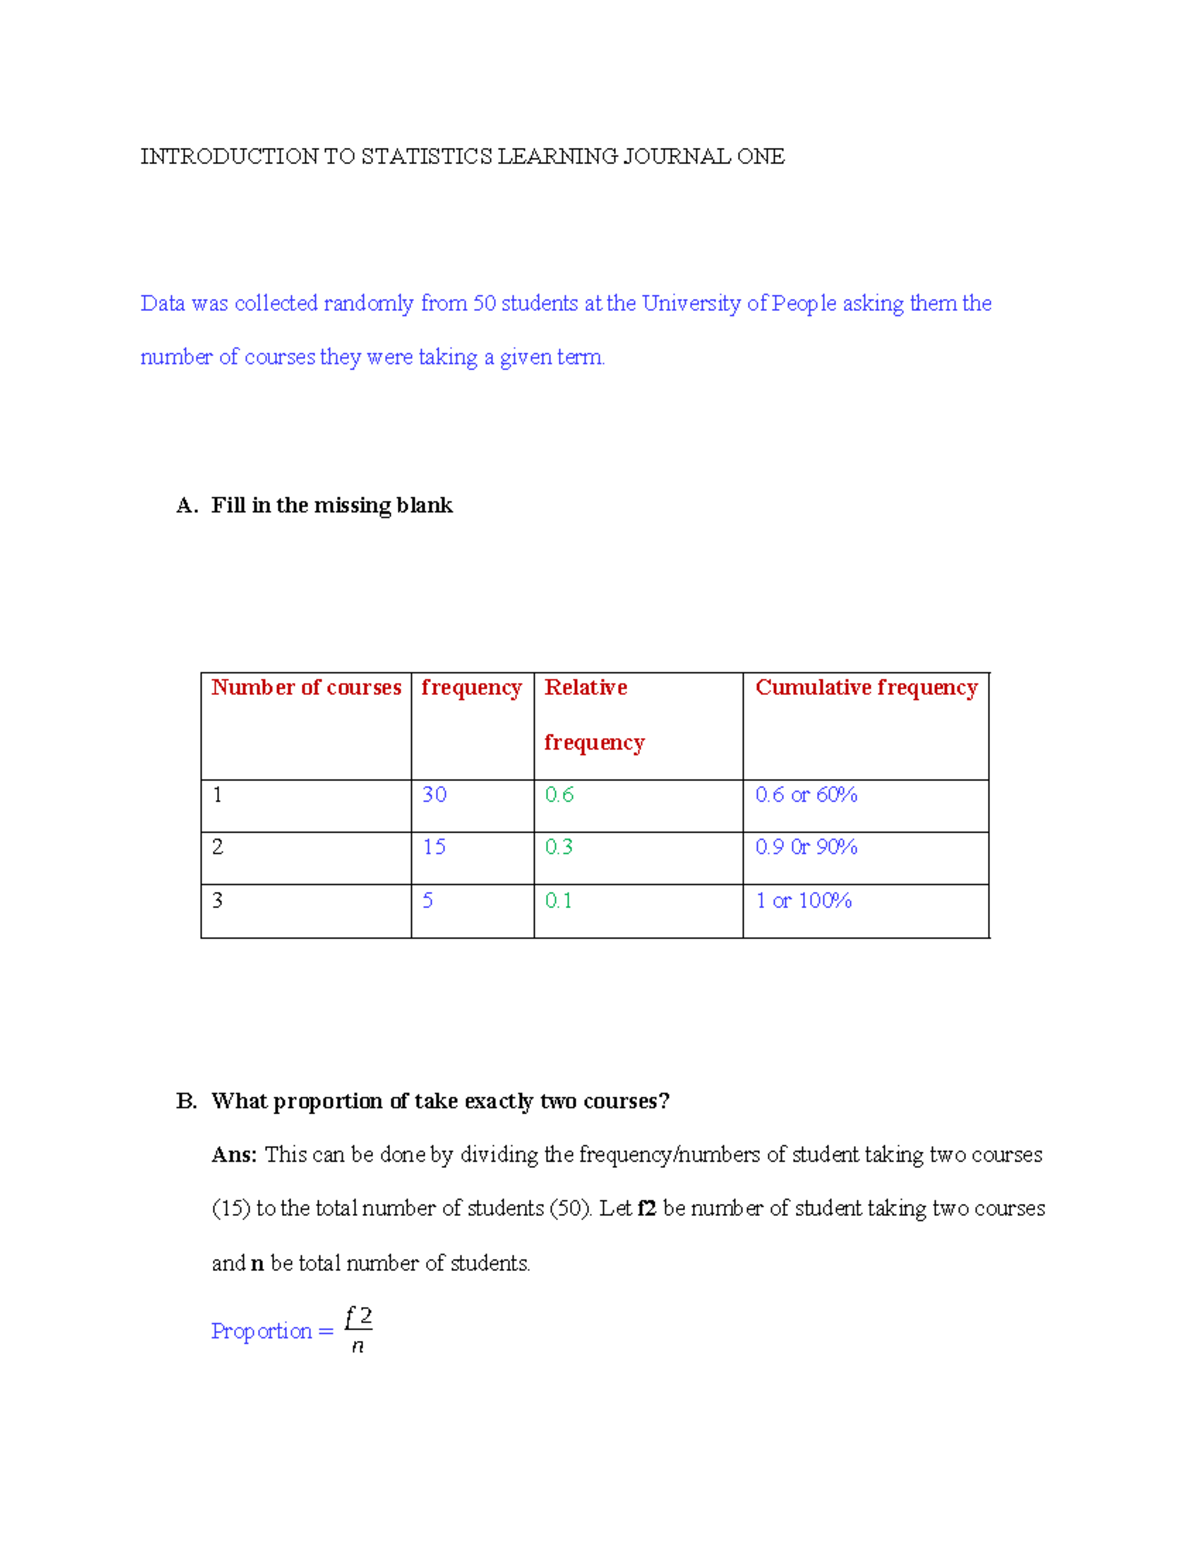
Most people treat statistics as a series of one-off calculations. They run a test, record the output, and move on. By the third month, they're repeating the same analyses because they never built a system to track what worked and what didn't. A journal for statistics exists to solve that specific failure mode. It is not a diary. It is a structured record of methods, parameters, decisions, and outcomes across every project you touch. I spent three years trying to maintain reproducibility across clinical research projects using nothing but folder names and mental notes. The turning point came when I lost an entire longitudinal dataset because I could not reconstruct the exclusion criteria I had applied in week two. The fix was not better storage. It was a journal entry format.How To Make Journal For Statistics That Actually Stays Useful
Start with the entry skeleton. Every single entry needs the same five fields: 1. Date and project tag. Something like "2025-04-12 / CARDIO-03". You will be searching this two years from now. Consistency matters more than creativity here. 2. Objective statement. One sentence describing what you were trying to determine. Not "run analysis." Something like "Compare time-to-event between treatment and placebo using Cox regression with time-varying covariates."
3. Method details. This is where most people skip. Write the exact software version, package, function call, and parameters. If you used a specific seed for bootstrapping, record it. If you handled missing data with multiple imputation, note the number of imputations, the model formula for the imputation step, and the convergence diagnostics. 4. Results. Raw numbers first, interpretation second. I used to mix these together and spend hours untangling what I had observed versus what I had assumed. Keep them separate. A result entry might look like: "Cox model HR 1.47, 95% CI 0.98-2.21, p=0.064. Proportional hazards assumption violated for treatment (Schoenfeld residuals p=0.012). Refitted with time-dependent coefficient." 5. Issues and decisions. This field catches the stuff that would otherwise become a mystery. "Excluded 23 patients due to missing baseline labs. Documented reason in section 3.2 of protocol. Sensitivity analysis showed
0.5% change in HR."
The medium does not matter as much as you would think. I have seen people use Word documents, spreadsheet tabs, Obsidian notes, and actual physical notebooks. The common denominator is structure, not platform. Pick one and stick with it for at least six months before judging it. I ran into a specific edge case that most journal templates ignore. When you are running batch analyses across dozens of datasets, the journal entries accumulate faster than you can keep them organized. I hit this when I was processing 47 biomarker panels for a single cohort study. Each panel generated roughly twelve different statistical outputs. My journal ballooned to over five hundred entries in two weeks and became completely unreadable. The workaround was adding a cross-reference column. Instead of writing out full results for every permutation, I wrote the method once and referenced it: "See entry STAT-0847 for full method. Results: panel ALB p=0.003, CRS p=0.412, FERRITIN p=0.089." This cut my maintenance time from about forty minutes per day back down to roughly eight. Here is something counter-intuitive that nobody teaches: your journal should contain failures more than successes. When a model converges and gives you a clean result, that is easy to reproduce later if you document the inputs. When it fails, or when you try something and it produces garbage output, that is the information you lose first. I now spend more time journaling failed approaches than successful ones. A log that says " Tried Bayesian hierarchical model with weakly informative priors. Chains did not mix. R-hat values exceeded 1.5 across all parameters. Switched to frequentist mixed-effects model instead" is worth more than ten entries that simply say "model worked." Another nuance beginners miss is the relationship between your journal and your code. They are not the same thing. Your code tells someone how you computed a result. Your journal tells them why you made the choices that led to that computation. When a reviewer asked why I had chosen a particular link function for a generalized linear mixed model, I could not find it in my R script. It was buried in a journal entry from fourteen months earlier. That entry saved the publication. There are hard limitations to this approach. The first is compliance overhead. A properly maintained statistical journal adds approximately two hours per week to a typical research workflow. If you are working alone on small projects, that may not be justified. In those cases, a simpler approach works: commit your code to version control with meaningful messages and attach a brief README that links each analysis file to its purpose. This is lighter weight and sufficient for projects under six months. The second limitation is scalability across teams. A single-person journal works well. Once you bring in collaborators, you need shared conventions or you end up with three different formats and nobody can parse anyone else's entries. If you are working in a group, I recommend adopting the journal entry structure as a formal standard and doing a brief review of previous entries so everyone understands the expected level of detail. A third limitation is that journals do not prevent bad statistics. A beautifully documented analysis is still a bad analysis if the assumptions are violated, the sample size is inadequate, or the p-hacking is real. The journal records what you did. It does not validate that what you did was correct. Treat it as an audit trail, not a quality guarantee. The tooling landscape has shifted significantly. Dedicated platforms like LabArchives and Benchling exist but cost money and introduce lock-in. Open-source options like Quarto or Jupyter notebooks with embedded narrative text can serve dual purposes as both code and journal. I personally found that a combination of plain text markdown files organized by project subdirectories gave me the best balance of portability, searchability, and zero dependency on any specific platform. You can run a simple grep command across years of entries in seconds, which is something you cannot do as easily with proprietary systems. To actually begin, create one test entry today. Pick a small analysis you have already completed and write it up using the five-field structure above. You will immediately notice gaps in your own documentation habits. That discomfort is normal and useful. Fill those gaps. Then do it again with a current project. After about thirty entries, you will notice a pattern in your own thinking. You will start to recognize when you are repeating the same methodological mistake across projects, or when you keep arriving at the same analytical dead end. The journal becomes a mirror for your own decision-making process. That is arguably more valuable than the reproducibility benefits, though both matter. The core insight is that statistics is not just computation. It is a sequence of decisions under uncertainty. The journal captures those decisions. Everything else is just formatting.Get the Full Details