The Method Before The Words
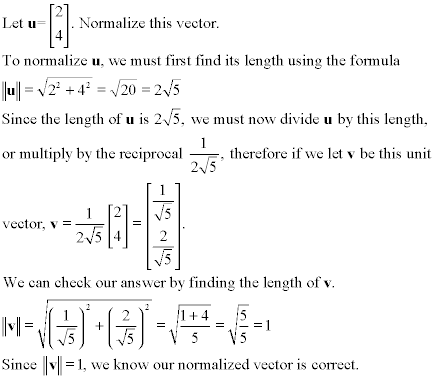
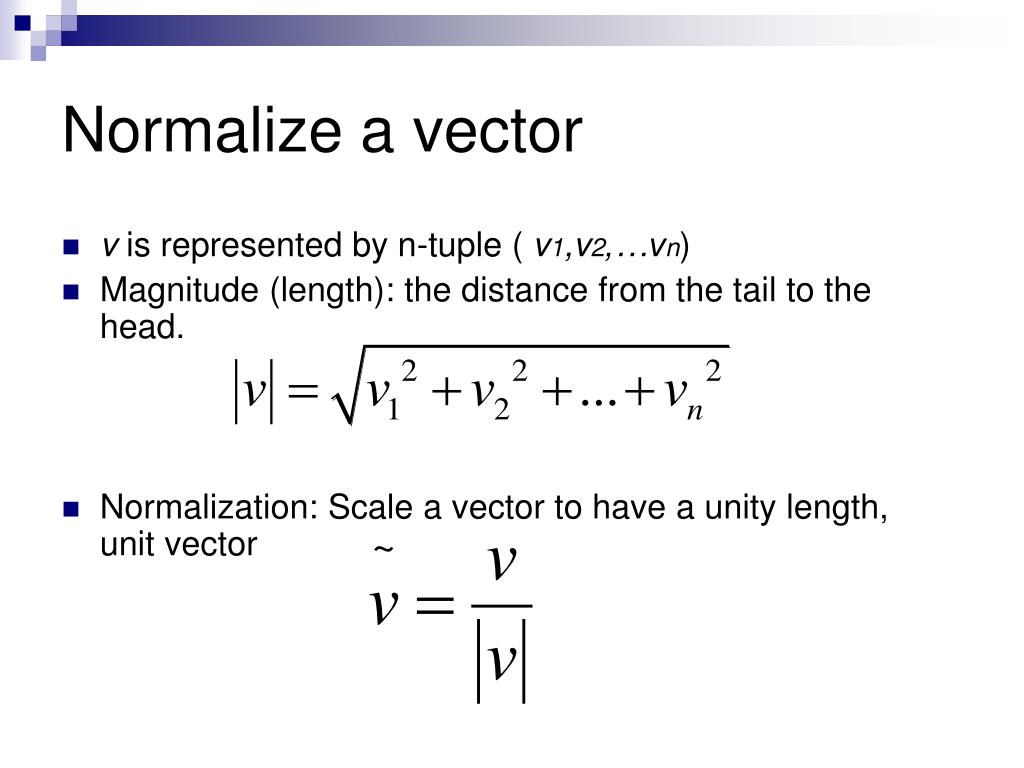
You divide every component of the vector by its magnitude. That's the whole operation. Magnitude is the square root of the sum of all squared components. For a 2D vector (3, 4), you'd square 3 to get 9, square 4 to get 16, add them for 25, take the square root to get 5, then divide both components by 5. Result: (0.6, 0.8). Done. Nothing to it, except when it isn't. In practice, this comes up constantly in game engines, computer graphics pipelines, physics simulations, and machine learning feature scaling. You're rarely doing it by hand anymore. What matters more is knowing what breaks when you implement it yourself, because I've seen this trip people up repeatedly. I spent a few weeks debugging a pathfinding system where characters were stuttering along navigation mesh edges. The issue traced back to normalized direction vectors losing precision after thousands of recursive calls. Each normalization introduces a tiny floating-point error, and over time those errors compound into visible drift. The workaround was simple enough: renormalize only when the vector's magnitude deviates from 1.0 by more than a threshold like 0.001, rather than blindly normalizing on every single call. Cuts down on error accumulation significantly and also saves some CPU cycles since you're not doing a square root calculation constantly.
Here's the standard formula again without the fluff: n = v / ||v||, where n is your normalized vector and ||v|| is the Euclidean norm (L2 norm) of v. The edge case everyone forgets is the zero vector. If you try to normalize (0, 0, 0), you're dividing by zero, and every language handles that differently. Some throw exceptions. Some return NaN. Some crash. In production code, you always check magnitude first. If it's zero or below your epsilon threshold, return the original vector or handle it as a special case depending on what makes sense for your application. I once had a physics engine crash on load because a character's velocity was exactly (0, 0, 0) at spawn and the normalization code didn't guard against it. Cheap fix, expensive debug session. Another thing that bites people: using normalized vectors for distance calculations later. A normalized vector has length 1 by definition. If you need an actual distance or displacement magnitude, don't use the normalized version. Keep the original vector or store the magnitude separately. I've watched entire systems get rewritten because someone normalized a position vector and then wondered why their distance checks were always returning values near 1 instead of actual world units.
For high-dimensional vectors like those you'd encounter in NLP embeddings or feature vectors, the concept is identical but the computational cost scales with dimensionality. A 768-dimensional vector needs 768 squarings, 767 additions, one square root, and 768 divisions. It's not heavy on modern hardware, but if you're doing this millions of times per frame in a tight loop, consider whether you actually need full L2 normalization or if an L1 norm or even quantization would serve your use case better and faster. L1 normalization just divides by the sum of absolute values, which avoids the square root entirely. Loses some geometric interpretability but gains speed, and in many ML preprocessing pipelines that tradeoff is completely acceptable. If you're implementing this from scratch in Python, NumPy has np.linalg.norm() which handles the magnitude calculation, or you can write it in one line: vector / np.linalg.norm(vector). In C++ with Eigen, it's simply vector.normalized(). In GLSL shaders, there's a built-in normalize() function. The library implementations are fine for most use cases, but they don't always include the zero-vector guard I mentioned, so wrapping them with a magnitude check is worth the five extra lines of code. The one scenario where normalization actively hurts performance is in real-time rendering pipelines where you're normalizing the same vertex normal every frame. Vertex normals are static per mesh. Compute them once during asset loading, cache them, and reuse. I've seen engines that re-normalize vertex normals in the vertex shader every draw call, which is unnecessary and adds up across thousands of meshes. Not a subtle difference when you're already GPU-bound.
Get the Full Details

There's also the question of which normalization variant to pick beyond the standard L2. Min-max normalization rescales to a [0, 1] range based on min and max values in your dataset. Z-score normalization subtracts the mean and divides by standard deviation, producing values centered around zero with unit variance. Neither is "normalization" in the vector geometry sense, but people conflate them constantly when they say they want to normalize data. Know which one you actually need before you start coding. For the zero vector edge case specifically, a common pattern is to define a small epsilon, check if magnitude
epsilon, and if so return a default direction like (1, 0, 0) or just skip the normalization entirely. The exact epsilon depends on your coordinate scale. If you're working in meters with values around 1 to 1000, something like 1e-6 is reasonable. If you're working in kilometers or millimeters, adjust accordingly. There's no universal value here, and using a hardcoded epsilon without thinking about your coordinate space is how you get bugs that appear only in certain scenarios. If you need a reference implementation, the canonical approach in most languages follows the same structure: compute norm, check for zero, divide each component. That's it. Anything more complex than that usually means you've got additional constraints or requirements that the basic formula doesn't address, and you should probably be looking at a specialized library rather than rolling your own.