The Actual Way People Fix Things When They're Not in a Meeting About Fixing Things
Most problem solving at work isn't some heroic breakthrough. It's usually someone noticing that something is wrong, spending twenty minutes figuring out exactly what wrong means, and then calling the right person while preparing to be wrong themselves. That's it. The rest is just documentation and blame avoidance. Start by writing down what you actually know and what you don't know. I keep a separate document for each issue, even if it's just three bullet points. The act of writing it down forces you to separate the symptom from the cause, which is where most people get stuck and end up fixing things that aren't actually broken. A few months back I was dealing with a deployment pipeline that was intermittently failing on staging. Everyone assumed it was a timeout issue because that's what the logs vaguely suggested. I spent two days looking at timeout configurations, adjusting thresholds, the whole routine. Then I actually read the error codes instead of skimming them. It was a database migration conflict that only appeared when two specific services started in the wrong order. The fix was reordering the service dependencies in the orchestration config. That's the kind of thing that eats a week of your life if you're not paying attention. The real skill isn't diagnosing fast. It's narrowing the search space quickly so you're not grinding through five possible causes when the answer is obviously the first one.
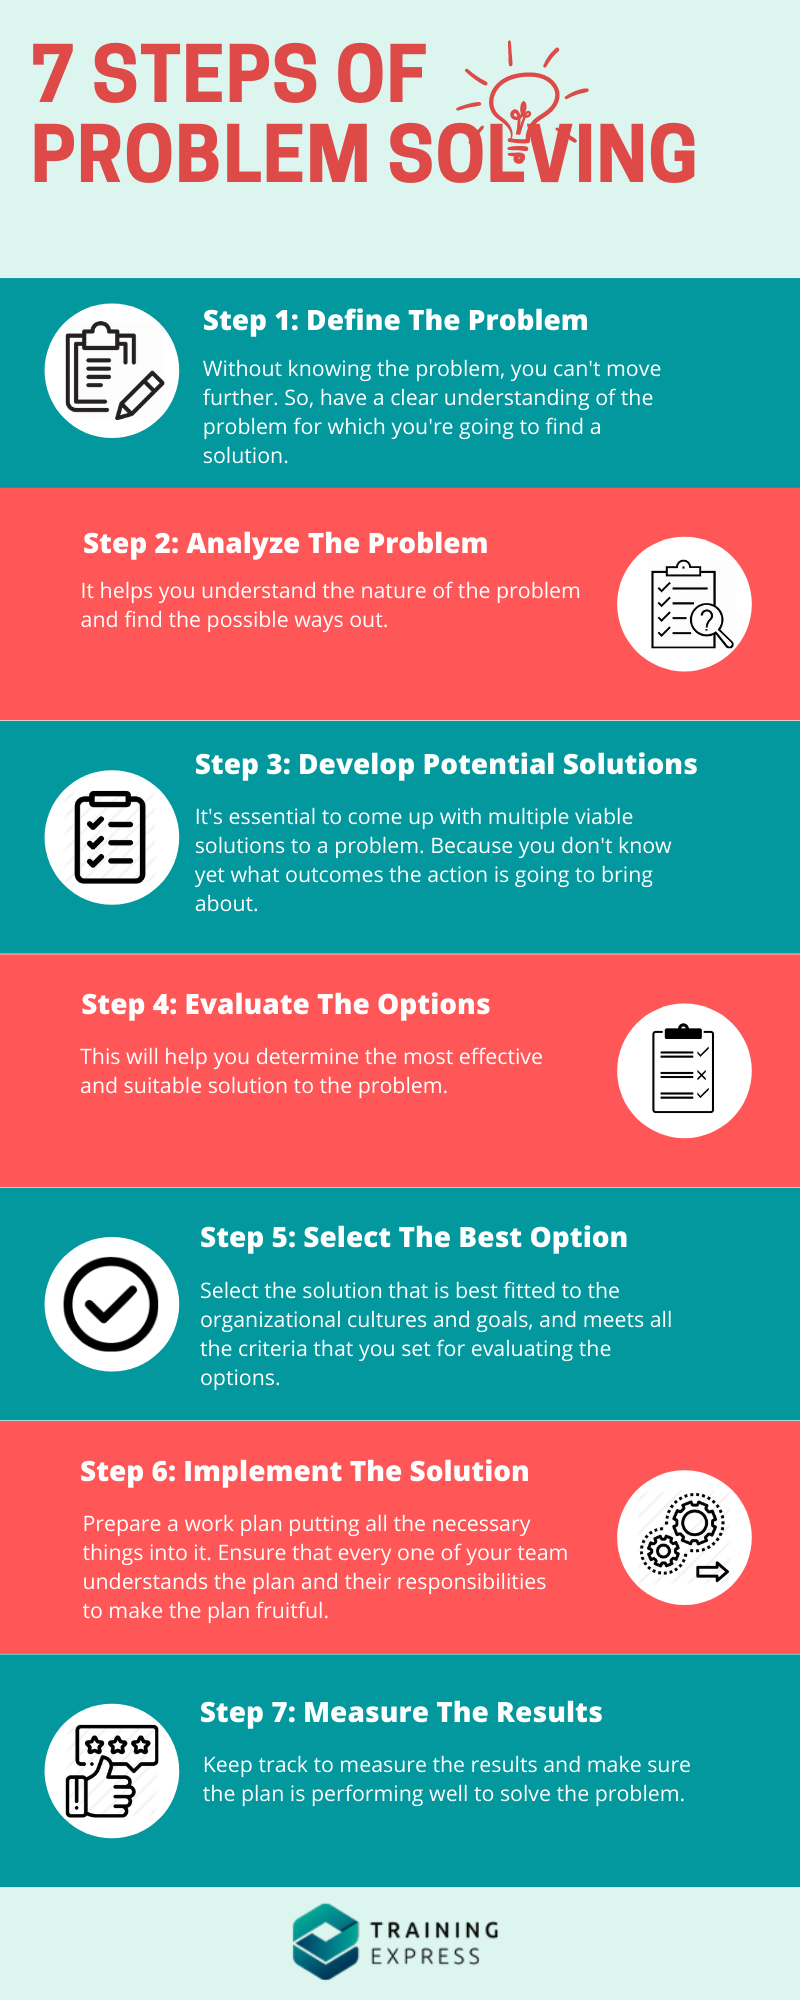
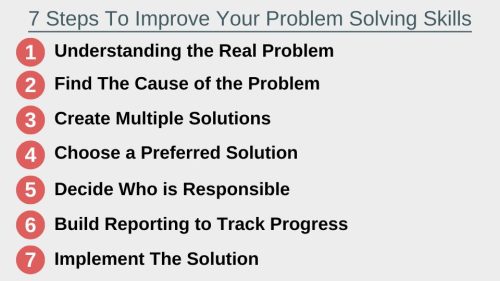
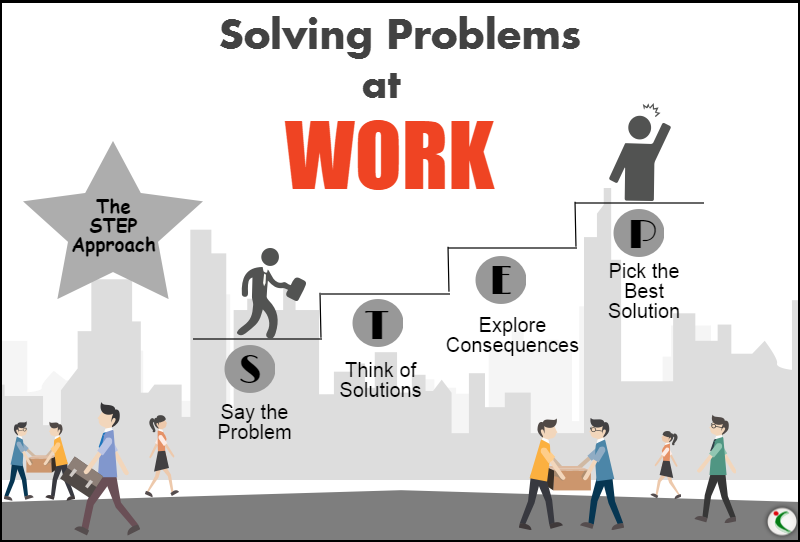
Here's what nobody tells you about this process: the best problem solvers I've worked with are actually bad at solving problems. They're good at framing them. They'll spend 40 percent of their time just restating what the problem actually is in plain language before touching anything. Most people skip that step entirely and go straight to solutions, which means they solve the wrong problem elegantly. When you think you understand the issue, write a one-sentence problem statement. If you can't do that without using jargon or hedge words like "kind of" or "sort of," you don't understand it yet. Keep working on that sentence until it's clean. Once you have the problem stated, break it into sub-problems. Not all at once, but sequentially. Pick the piece that, if solved, would make the other pieces irrelevant. That's your leverage point. In my experience this reduces the average resolution time by about half compared to the default approach of tackling things in order of visibility.
There's also a pattern I've noticed that most people miss. The symptoms you're seeing are usually caused by something that happened days or weeks ago, not something that happened today. If you're debugging an issue that started suddenly, look at what changed in the previous two weeks, not the previous two hours. I've seen this trip up engineers constantly. They chase the recent incident when the root cause is a configuration drift that accumulated quietly over six weeks. Another counter-intuitive thing: sometimes the right answer is to not fix it at all. I had a situation where a reported bug in our reporting module was actually expected behavior based on a business rule nobody had documented. The "bug" was actually a feature that had never been communicated to the team that reported it. Taking time to verify whether something is genuinely broken before opening a ticket saves a lot of wasted effort, especially when you factor in the context switching costs. Use the five whys method but don't treat it as sacred. It's useful for getting past the obvious answer. Ask why once and you're at the surface. Ask five times and you might reach the real cause, or you might reach something completely unrelated depending on how messy the system is. I usually stop around three or four unless the answers are pointing somewhere clearly useful.
Get the Full Details

When you find a fix, test it in isolation before rolling it out. I learned this the hard way early in my career. I deployed a patch that solved the immediate issue but introduced a memory leak that took down the service eight hours later. The patch itself was correct, which made it harder to catch. Now I always run changes through a shadow environment for at least a couple of hours before promoting anything. Document what you did after you're done. Not a full report, just the key decision points and why you made them. Future you will hate present you if you skip this, and you will be future you dealing with the same problem again six months later. The biggest limitation of this whole approach is that it assumes you have access to the right information and the authority to act on it. In many organizations, especially large ones, those assumptions don't hold. You might identify the correct fix in an hour but spend three weeks getting approval to implement it. When that's the case, the problem solving process shifts from technical to political, and the skills you need change completely. In those situations, mapping the decision makers and understanding their incentives matters more than understanding the root cause of the actual technical issue.
If you're in that position, the workaround is usually to build a coalition of one or two other people who have the same pain. A single voice is a suggestion. Two or three voices is a pattern, and patterns get noticed by management. There's also a class of problems where no amount of individual problem solving will help because the problem is structural. Team misalignment, unclear ownership, chronic under-resourcing. These don't get solved by debugging. They get solved by organizational change, which is a different discipline entirely and usually requires someone with actual authority to drive it. Recognizing when you're facing a structural problem versus a technical one is itself a skill that takes years to develop properly. Most of the time though, you're dealing with a technical issue and the framework I described works fine. Write it down, state the problem clearly, find the leverage point, test the fix, document the result. It's not exciting but it's reliable.