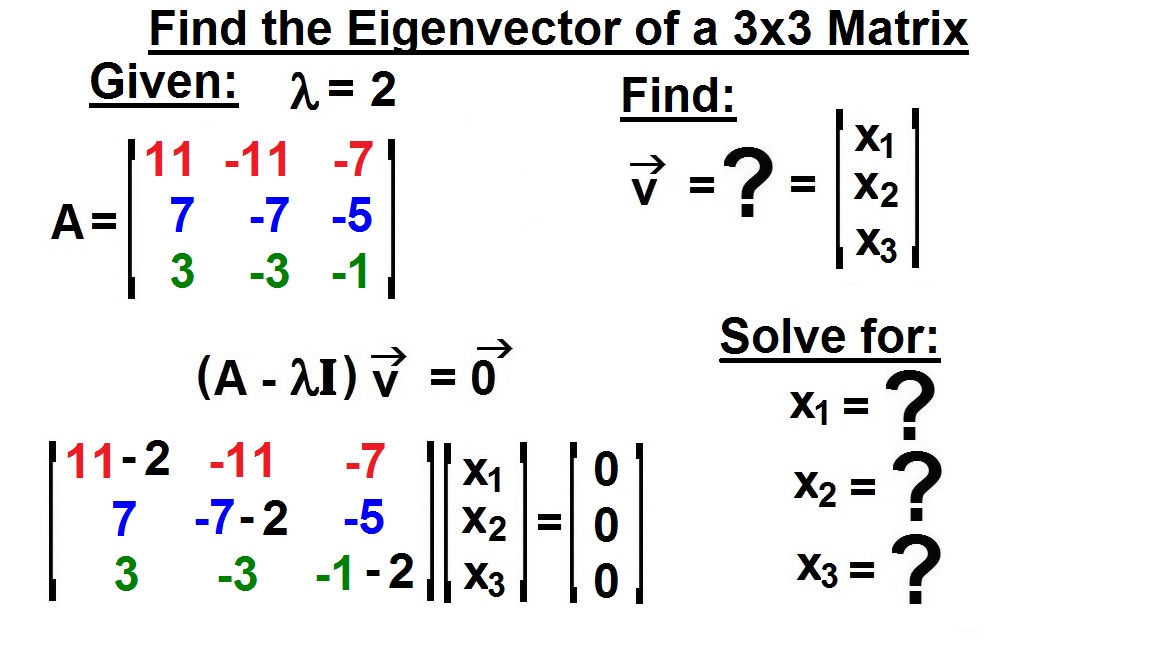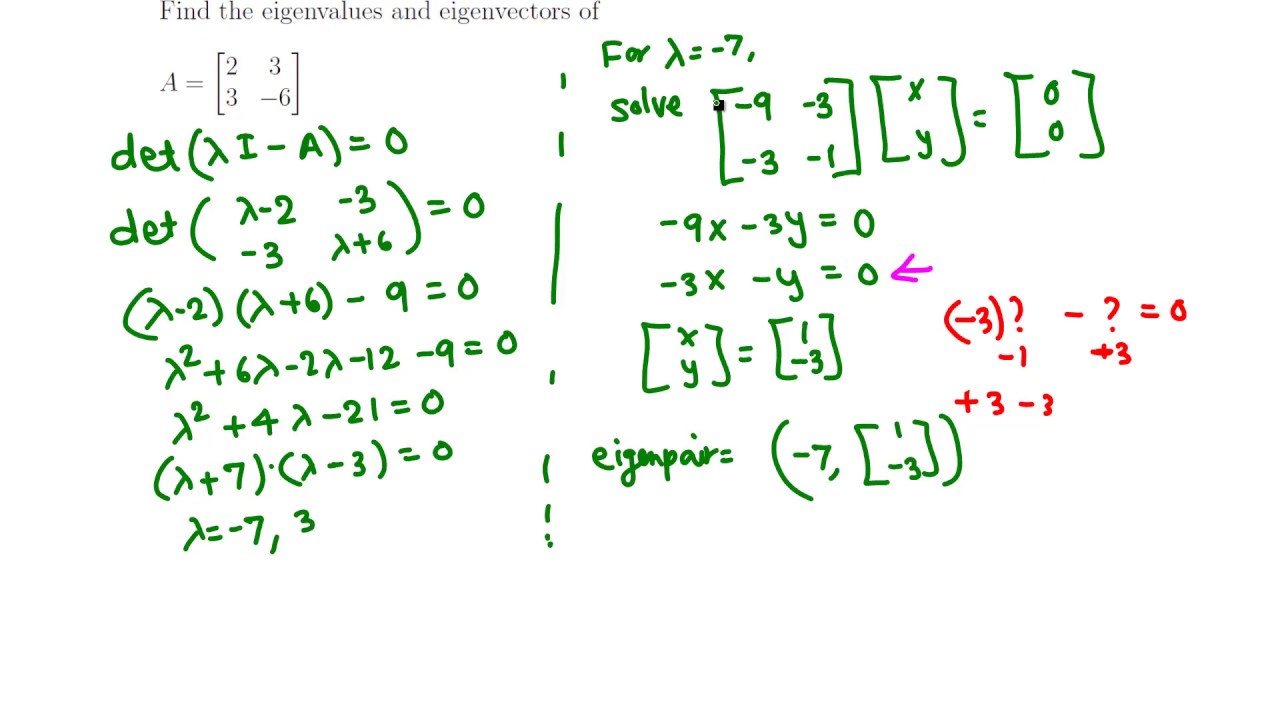
Working Out Eigenvectors by Hand
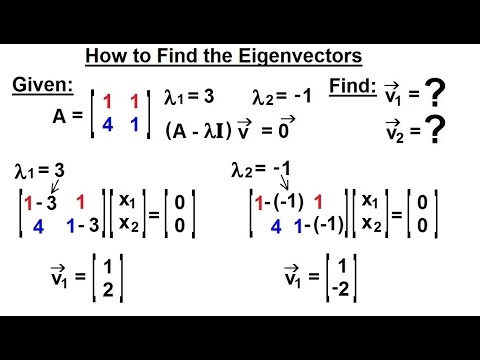
You find the eigenvalues first, plug each one back into a modified matrix, and row-reduce until you see what stays non-zero. That remaining freedom in the system is your eigenvector direction. The whole thing sounds abstract until you've actually done it enough times to notice where it breaks. Start with your square matrix A. Compute the characteristic polynomial by taking the determinant of A minus lambda times the identity matrix, set that equal to zero, and solve for lambda. Those roots are your eigenvalues. For each eigenvalue, substitute it back into A minus lambda I and row-reduce. The null space of that resulting matrix is where your eigenvector lives. Any nonzero vector in that null space works. Normalize it if your application requires unit length, skip normalization if it doesn't. Here is the part most guides skip. When the eigenvalue has algebraic multiplicity greater than its geometric multiplicity, you are dealing with a defective matrix and you will not get enough independent eigenvectors to form a full basis. In that case the process stops being straightforward and you need generalized eigenvectors through the Jordan chain method, or you accept that diagonalization is impossible and move to Schur decomposition instead. I ran into this with a 4 by 4 matrix from a structural dynamics problem where two eigenvalues were repeated at 3.7 but the rank drop only gave me one eigenvector instead of two. Took me an afternoon to realize what was happening because the textbook example always used matrices that played nice. The workaround was switching to a numerical solver that returned the Jordan form explicitly rather than pretending a full eigenbasis existed.
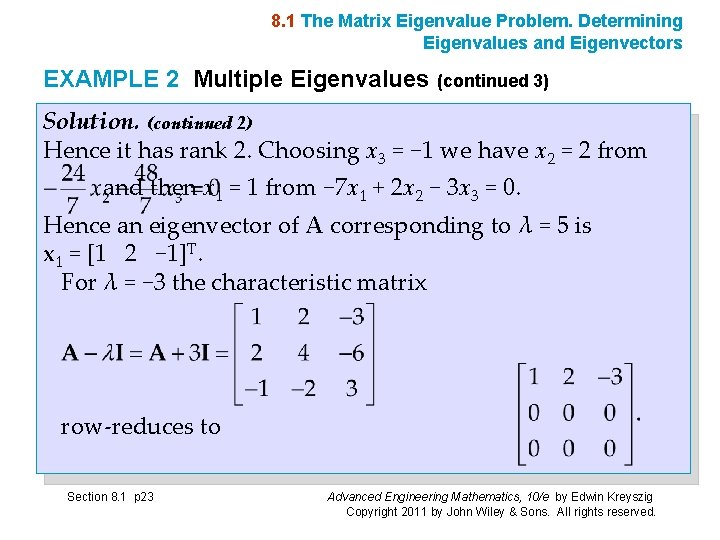
An eigenvector is a nonzero vector v such that multiplying it by the matrix A gives you the same vector scaled by a scalar lambda. In equation form that is Av equals lambda v. The scalar lambda is the eigenvalue. Geometrically, the matrix only stretches or compresses that direction, never rotates it. If you are modeling anything that involves repeated linear transformations, like iterative systems or principal component analysis, this property is what makes the whole approach useful. For a 2 by 2 matrix, the characteristic polynomial is always lambda squared minus the trace of A times lambda plus the determinant of A. That quadratic formula gives you both eigenvalues in one shot. For 3 by 3 it becomes a cubic and sometimes you need Cardano's method or just a numerical root finder if the coefficients are messy. For anything larger than 4 by 4, doing this by hand is rarely worth the effort unless you are in an exam room with no tools allowed. When you row-reduce A minus lambda I, pay attention to free variables. Each free variable corresponds to a dimension in the eigenspace. If you end up with one free variable, you have a one-dimensional eigenspace and one basis eigenvector. Two free variables means two independent eigenvectors for that eigenvalue. Setting the free variable to 1 and the rest to 0, then repeating with the roles swapped, gives you the basis vectors directly.
A practical issue people hit is floating point noise when the matrix is close to singular after substitution. A eigenvalue of 5.0000001 instead of exactly 5 can turn a clean zero row into something like 0.00023, which throws off your manual row reduction. I usually round entries below 1e-10 to zero when working numerically, and I verify by multiplying the result back through Av to confirm it is within tolerance of lambda v. That check catches about half the mistakes before they snowball. Numerical libraries use the QR algorithm, not characteristic polynomials. The power iteration method works if you only need the dominant eigenvector and the matrix is large but sparse. For symmetric matrices, the Jacobi eigenvalue algorithm is stable and gives all eigenpairs at once. The tradeoff is speed. Power iteration converges linearly and can be slow if the ratio between the largest and second-largest eigenvalue is close to one. QR is faster for dense moderate-sized matrices but uses more memory. If you are doing this in production code, use a library. LAPACK's DSYEV for symmetric real matrices or ARPACK for large sparse problems will beat a hand-rolled implementation every time. One counter-intuitive thing about eigenvectors is that they are not unique. Any nonzero scalar multiple of an eigenvector is also an eigenvector for the same eigenvalue. This sounds obvious but it causes real headaches when you compare results across different software packages. MATLAB, NumPy, and Julia may return eigenvectors that differ by sign or scale. Always normalize and check the direction, not the raw output values, when validating across tools.
Get the Full Details
Another thing that trips people up is assuming every matrix has real eigenvalues. Skew-symmetric matrices and rotation matrices often have complex eigenvalues. Your eigenvectors will be complex too. If your application requires real vectors, you need to work with the real canonical form or use the real and imaginary parts as a basis for the invariant subspace. This comes up constantly in control theory and vibration analysis where the underlying matrix is real but the spectrum is not. The condition number of the eigenvalue problem matters more than most people realize. For nonsymmetric matrices, eigenvectors can be highly sensitive to perturbations. A small change in the matrix entries can cause a large change in the eigenvector directions. This is quantified by the eigenvector condition number, which is related to the angle between left and right eigenvectors. If that angle is small, the problem is ill-conditioned and numerical results become unreliable regardless of the algorithm you use. For sparse large-scale problems, the shift-and-invert strategy combined with Lanczos iteration is usually the right choice. It targets eigenvalues near a specified shift rather than just the largest ones. Without that shift, you might spend hours converging on the top eigenpair when what you actually need is one from the middle of the spectrum. I spent three days debugging a model that was silently returning the wrong eigenvector because the default solver was converging to a different eigenvalue than I expected. The shift value of 2.3 was pulled from a rough spectral estimate, and it changed the runtime from impractical to about ten minutes.
If you are implementing this yourself, start with a 2 by 2 case and verify against the quadratic formula. Then move to a 3 by 3 symmetric matrix where you can check orthogonality of the eigenvectors. Symmetric matrices guarantee orthogonal eigenvectors for distinct eigenvalues, which is a free validation step. Once that checks out, try a nonsymmetric case and watch the complexity increase. The concepts are the same but the edge cases multiply quickly. Downsides of the hand calculation approach are obvious but worth stating plainly. It does not scale past about 4 by 4 for anything but the simplest integer matrices. Precision degrades rapidly with floating point arithmetic. Time investment is high relative to just calling a solver. You should only do it by hand when you are learning the mechanics or when you need to understand the structure of a small problem. For everything else, use established numerical routines and spend your energy on interpreting the results rather than computing them.