Getting Past the Z-Score Trap
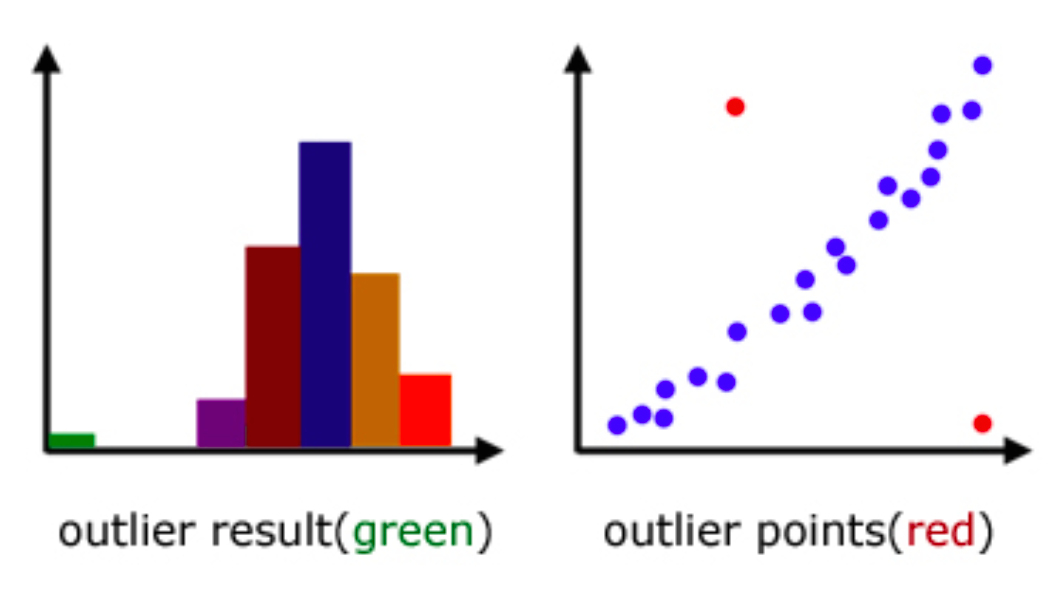
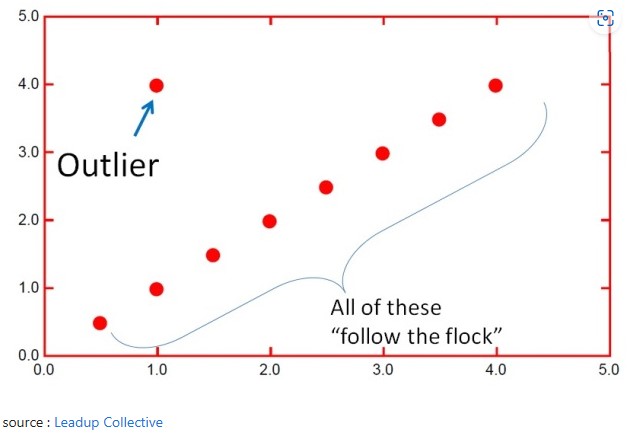
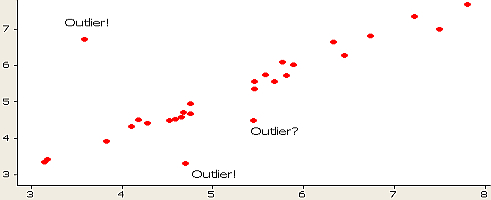
Most people learn about outliers by running a Z-score calculation and calling anything beyond three standard deviations a problem. That is technically a way to spot them, but it is also the reason your data ends up either full of false alarms or completely blind to the real ones. I spent about two years debugging pipelines where the Z-score approach was filtering out perfectly valid extreme values while letting actual corrupted entries slide through because they happened to cluster near the mean. The interquartile range method is where I usually start now. You take the 75th percentile, subtract the 25th percentile, multiply that gap by 1.5, and anything outside that band on either side gets flagged. It is more forgiving than Z-score on non-normal distributions, which is most real-world datasets. The flier points it identifies are your candidates for review. But flags are not conclusions. You need to actually look at the flagged values in context. A scatter plot or a box plot will show you whether a point is an outlier because it is far from the rest of the cloud, or whether it belongs to a separate cluster that happens to be distant from the main group. Distinguishing those two situations changes what you do with the data entirely.
I once had a dataset of server response times where the IQR method flagged roughly eight percent of entries. The automated cleanup script would have silently dropped them. When I actually plotted those points, I noticed they weren't random noise. They were all concentrated around 2 AM to 4 AM, and they corresponded to a different load balancer routing traffic to a backup cluster. Those values were legitimate. Removing them would have hidden the fact that the backup cluster was performing significantly worse during off-peak hours. The workaround was adding a time-of-day column as a grouping variable and running the outlier detection within each group rather than across the entire dataset.
Advanced Detection Methods That Actually Matter
When your data has multiple variables, univariate methods fall apart pretty quickly. A value might look normal for every individual column but completely impossible when you consider how the columns interact with each other. That is where multivariate techniques like Mahalanobis distance become useful. It measures how far a point is from the center of a multivariate distribution while accounting for correlation between variables. A single outlier in one dimension won't necessarily trigger it, but a combination of moderately unusual values across several correlated dimensions will. Isolation forests are another option that handles high-dimensional data without assuming anything about the underlying distribution. The algorithm works by randomly selecting features and split values to isolate points. Outliers tend to require fewer random splits to isolate because they are surrounded by sparse regions of the feature space. Random forest implementations of this concept are available in scikit-learn and run fast enough on datasets with millions of rows that you should just use them instead of building something custom. Here is a thing that catches most people off guard: outlier detection is not a preprocessing step you complete once and move on from. It is a decision you make repeatedly, and each decision carries consequences. Dropping outliers changes your model's bias. Imputing them introduces artificial density around the imputed value. Keeping them without documentation makes your results unrepeatable. The most important part of spotting an outlier is writing down exactly how you decided to handle it, because six months from now you or someone else will need to reproduce those results and you will not remember why you removed that one entry.
Get the Full Details

The Specific Problem With Automated Outlier Removal
Automated pipelines that detect and remove outliers without human review will systematically eliminate the cases you care about most. Fraud detection is the classic example. Fraudulent transactions are outliers by definition. A model trained after removing them will be excellent at predicting normal behavior and useless at identifying the anomaly you actually wanted to find. This is not theoretical. I saw a credit card company run an automated outlier removal step on their training data before feeding it into a fraud model. The model's AUC improved from 0.61 to 0.89 on their internal test set, and then performed worse than random on production data because the fraudulent transactions had been cleaned out of the training set entirely. The fix was to flag outliers separately and include a binary flag feature indicating whether each row was flagged, rather than removing them. The model then learned both the patterns of normal transactions and the characteristics of flagged anomalies. Performance on production fraud detection went from 0.89 back down to about 0.71, which looked worse on paper but actually caught real fraud more often because the model was no longer blind to the signal it had been trained to ignore.
Practical Thresholds and Tooling
For quick analysis in Python, scipy.stats.iqr and numpy.percentile will get you the IQR bounds in about five lines of code. For multivariate work, sklearn.neighbors.IsolationForest and sklearn.covariance.Mahalanobis cover the main use cases. R users have similar packages that do the same thing. The tool choice matters less than understanding which method matches your data structure. Time series data needs its own consideration because temporal correlation violates the independence assumption behind most standard outlier detection. A value that looks extreme in isolation might be a perfectly normal continuation of a trend. Use rolling statistics or segment your data by time periods before applying detection. Seasonal decomposition can also help separate the signal from what is actually anomalous in each component. How To Spot Outliers reliably comes down to using the right method for your data type, visually inspecting the flagged points before taking action, and documenting every decision you make about them. Anything more complicated than that is usually you looking for precision you don't actually need from the data you have.