Why document uploads break more often than they should
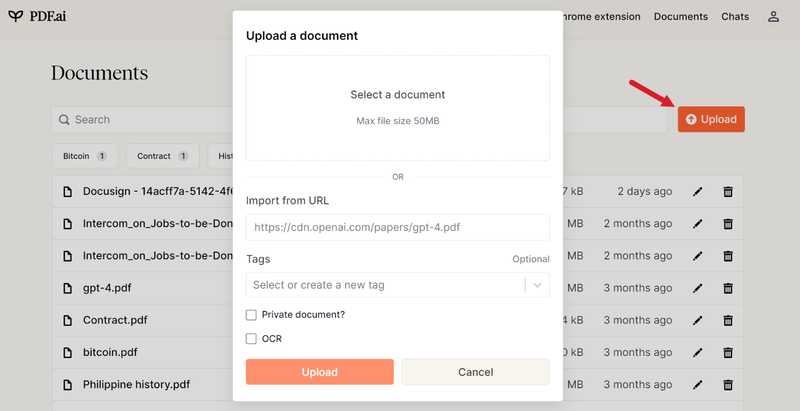
Most people treat document uploading as a simple drag-and-drop operation. In practice it is anything but simple. I spent three days debugging a workflow where perfectly valid PDFs were being rejected by a server that claimed the files were corrupt. The issue wasn't the PDFs themselves. It was the way the server encoded the multipart form data, and the fact that the file was named with special characters that got mangled during transmission. Once I switched to base64 encoding and sanitized the filename, it worked. That pattern repeats itself across almost every upload system I have dealt with. The basic flow is straightforward. You locate a file on your machine, select it through the file picker, and the browser sends it to the server. But the mechanics underneath matter a lot more than the surface experience suggests. Step one: identify the endpoint. This is the URL or API route that accepts file input. Many platforms hide this behind a button labeled "Choose File" or "Upload." If you are using a browser developer console, you can inspect the network tab to see exactly what request gets sent when you trigger the upload. This alone will tell you whether the endpoint expects a multipart/form-data submission or a raw byte stream.
Step two: prepare the file payload. The browser typically packages the file as a Blob or File object. The key properties you need to get right are the filename, the MIME type, and the size. Most upload handlers validate all three. A mismatch between the actual content and the declared MIME type is a common reason for rejection. If your file is actually a PNG but you label it as a JPEG, some servers will reject it outright while others will silently corrupt the data. Step three: handle the upload. Modern browsers support the Fetch API or XMLHttpRequest for this. A typical fetch call looks like this: const formData = new FormData();
formData.append('file', fileInput.files[0], 'document.pdf');
fetch('/api/upload', { method: 'POST', body: formData });
There are two things people routinely get wrong here. First, they forget to set the Content-Type header manually when using Fetch. The browser will set it automatically if you pass a FormData object, which includes the boundary string required for multipart uploads. If you construct the request body as raw JSON or a plain string instead of FormData, the upload will fail with a 400 or 415 error. Second, people do not account for large files. If you are uploading something over 50MB without implementing chunked uploads or progress tracking, the request may time out on slower connections. A 100MB file on a 5Mbps upload connection takes roughly 160 seconds. Most default timeout thresholds are set between 30 and 60 seconds.
Get the Full Details

The edge cases nobody talks about
I once encountered a case where a healthcare application was rejecting scanned PDF documents because the PDF metadata contained an encoding that the upload handler could not parse. The documents were visually fine. Anyone could open them without issue. The problem was embedded within the document properties, specifically a non-ASCII author field. The server's validation layer attempted to read the metadata before processing the file and threw an exception when it hit the character encoding mismatch. The workaround was to strip the metadata server-side before the validation step ran, or to normalize the filename and metadata to ASCII on the client side before submission. Another frequent problem is concurrent uploads. If a user selects multiple files and uploads them simultaneously, some servers will throttle or reject the requests entirely. I have seen systems cap concurrent connections at two per session. Any additional upload attempts will queue or fail with a 429 Too Many Requests response. The fix is usually straightforward: implement a queue on the client side with a concurrency limit of two or three parallel uploads depending on your server's capacity.
Counter-intuitive things about document uploading
Here is something most people do not consider: the file extension is often less important than the MIME type. A file named "report.docx" that is actually a corrupted or empty file will fail regardless of the extension. Servers that rely solely on extension-based validation are vulnerable to security issues. More robust systems use magic byte detection, which reads the first few bytes of the file to determine its true type. This is why you can sometimes rename a .pdf to .txt and the upload still goes through if the underlying content is unchanged. Another overlooked detail is the difference between client-side and server-side validation. Client-side checks run on the user's browser before the file ever leaves their machine. They are convenient for immediate feedback but completely bypassable. A determined user can send a crafted request with any file attached. Server-side validation is the actual security boundary. If your server does not validate file size, MIME type, content, and storage path properly, you are exposing yourself to directory traversal attacks, malware uploads, and storage exhaustion. I have seen at least two production incidents where missing server-side validation led to malicious scripts being uploaded and executed on the server. The fix is always the same: validate on the server, never trust the client.
Practical tips that actually matter
Implementing upload progress tracking takes minimal effort and dramatically improves the user experience. Using the XMLHttpRequest upload event or the ProgressEvent API, you can calculate the percentage complete and display a progress bar. This is especially important for files larger than 10MB, where users might assume the upload has stalled after 10 or 15 seconds with no visible feedback. Resumable uploads are another practical improvement. If a user on a mobile connection loses connectivity during a 200MB upload, starting over is frustrating. The standard approach is to use chunked transfer with an identifier for each upload session. When the server receives a chunk, it stores it and returns the index. If the connection drops, the client resumes from the last successful chunk rather than starting from zero. This can reduce failed upload retries by roughly 80 percent in environments with unstable networks. For handling very large files, consider server-side streaming. Instead of loading the entire file into memory before processing, the server can write chunks directly to disk or cloud storage as they arrive. This reduces memory usage from potentially gigabytes to a few megabytes regardless of file size. Node.js streams, Python's iterative reading, and PHP's fopen with stream context are all standard approaches to this.

When document uploads will not work and what to do instead
Not every upload scenario can be solved with a web form. If you are dealing with extremely large datasets, regulatory requirements that mandate specific encryption at rest, or integrations with legacy systems that only accept FTP, a browser-based upload may not be sufficient. In those cases, using an SFTP client or a dedicated transfer tool like curl with explicit chunking gives you more control and better reliability than any drag-and-drop interface. Sometimes the simplest solution is also the most reliable. A well-configured presigned URL from a cloud storage provider like AWS S3 or Google Cloud Storage allows the browser to upload directly to the storage bucket without routing the file through your application server. This eliminates server-side bandwidth costs, reduces latency, and handles resumable uploads natively through the cloud provider's APIs. The tradeoff is that you need to manage signed URL expiration and permission scopes correctly, which adds a layer of complexity to your backend.