ATLAS.ti Setup and Workflow Basics
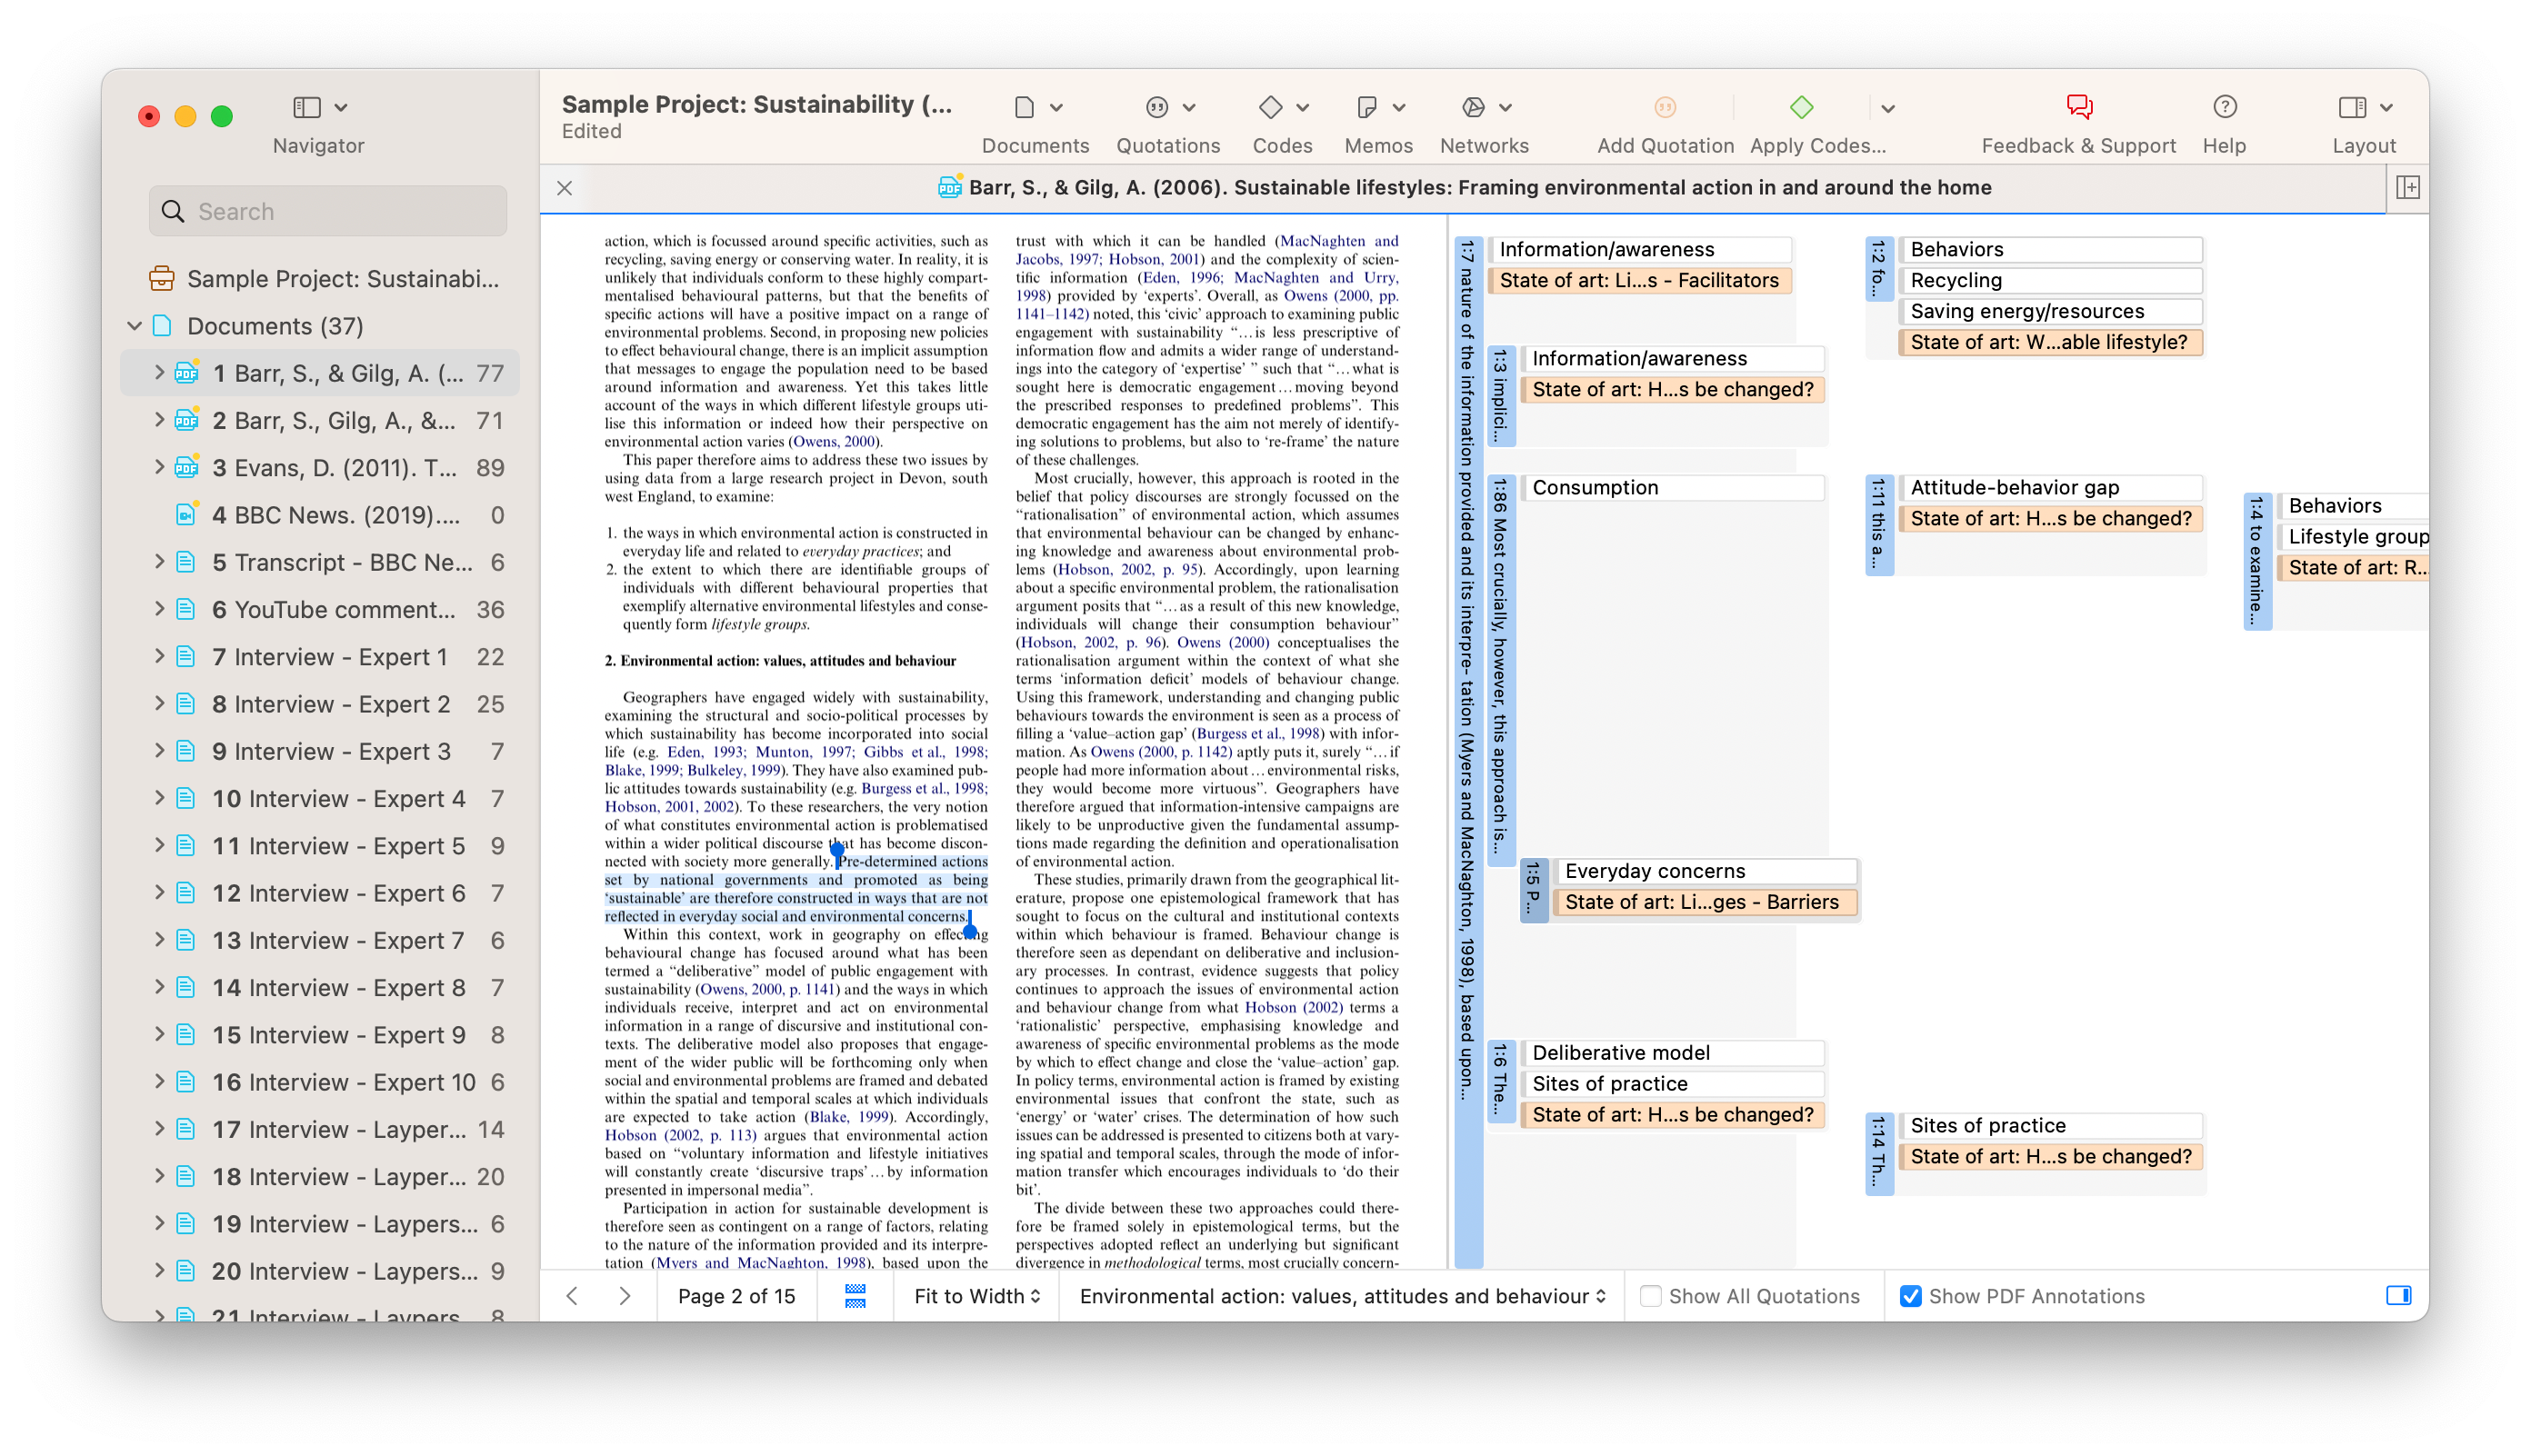
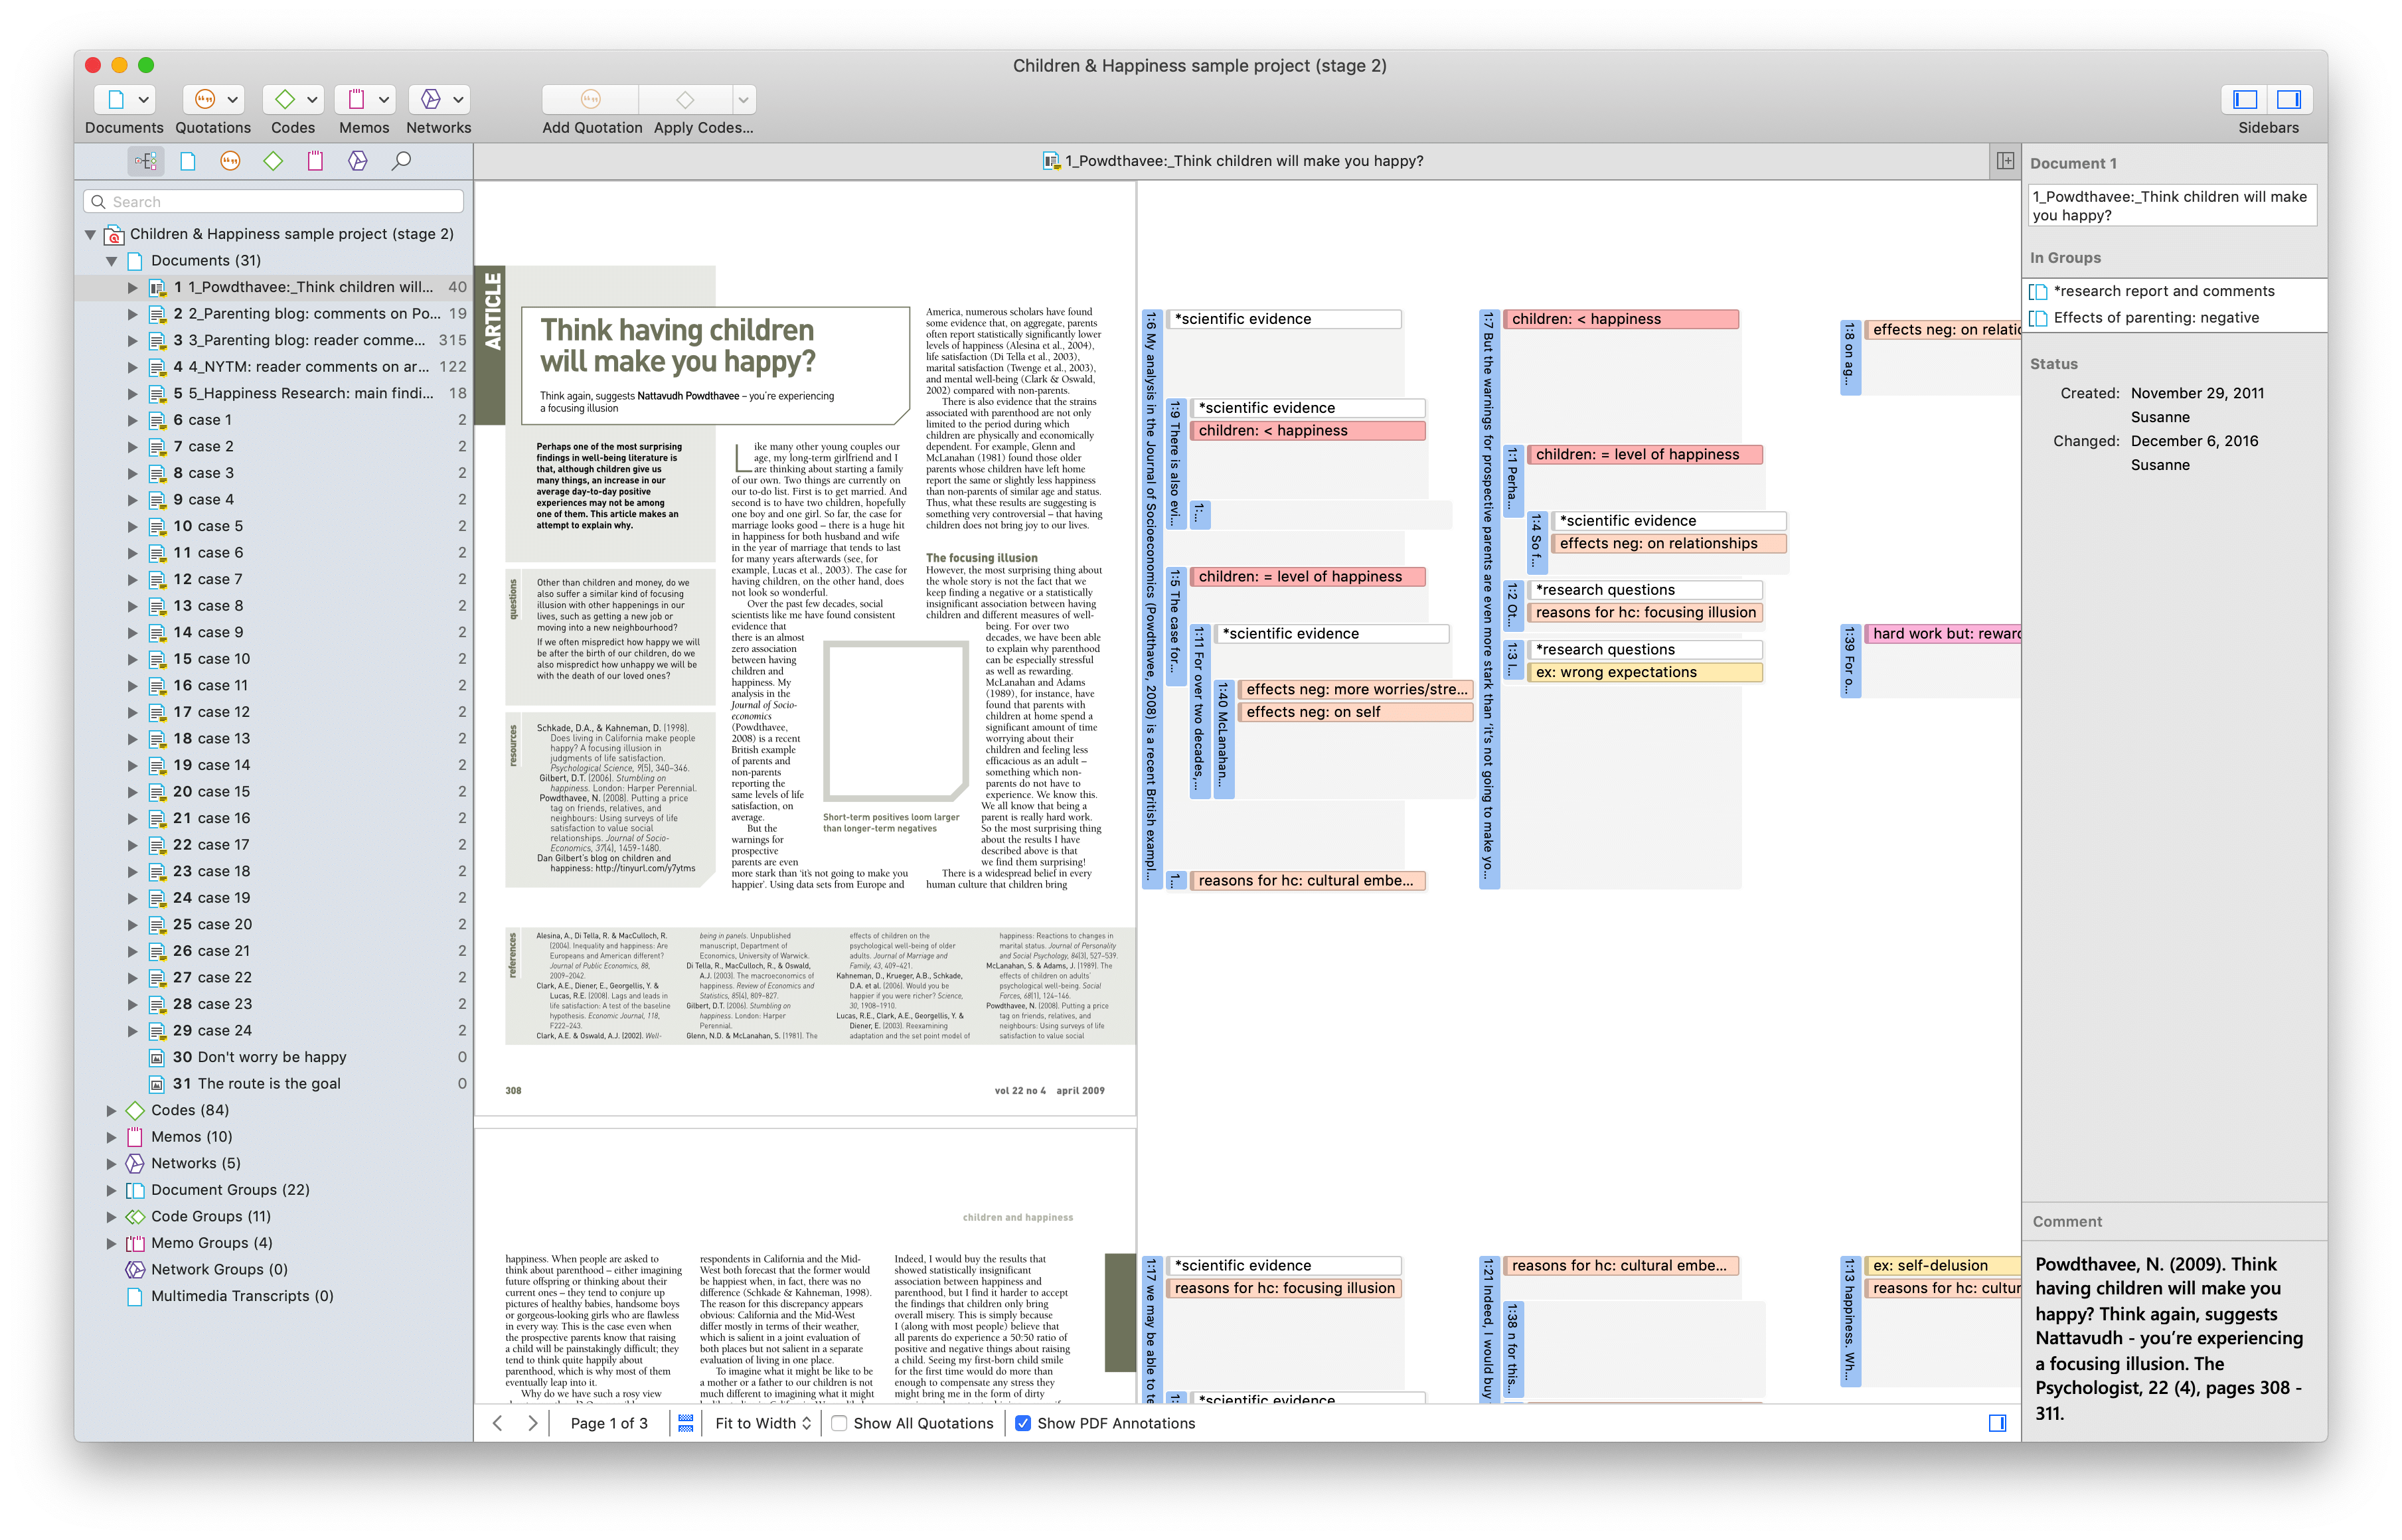
The first thing people get wrong is assuming ATLAS.ti is just a fancy highlighting tool. It is, but only after you understand how it actually handles data. You bring in PDFs, transcripts, images, social media posts, whatever your research requires, and the software treats everything as a document. Each document gets coded by attaching tags that represent concepts, themes, or categories. That is the entire workflow in its simplest form. I have been running qualitative projects with this for years. The interface will look intimidating when you first open it. The left sidebar has your project explorer, the center is your workspace, and the right side is where your code manager lives. The trick is ignoring everything except the document viewer and the code editor until you learn where the buttons are. Everything else can wait.
How To Use Atlas Ti for Basic Document Coding
Start by importing your documents. File, Import, and then drag whatever you have into the project window. ATLAS.ti will parse text documents automatically. For PDFs, it runs OCR if the files are scanned images. This is where I ran into an actual problem a while back. My client had digitized newspaper clippings from the 1990s. The OCR picked up about sixty percent of the text correctly and hallucinated words everywhere else. I caught it when I tried to code a quote and the highlighted text did not match what was on the page visually. The workaround was to import the images as raw visual documents instead of trying to extract text. I coded directly against the image files and annotated sections manually. It took longer but the coding was accurate. If you are working with low quality scans or handwritten materials, skip the automatic text extraction entirely. Your codes will be garbage otherwise and you will waste hours cleaning up false matches later. Once your documents are in, create your first code. The standard approach is deductive coding, where you start with a predefined list of codes based on your research questions. Open-ended qualitative work often uses inductive coding instead, letting patterns emerge from the data itself before you formalize anything. Both work. Most researchers mix them and end up with a hybrid framework that nobody really planned out at the start.
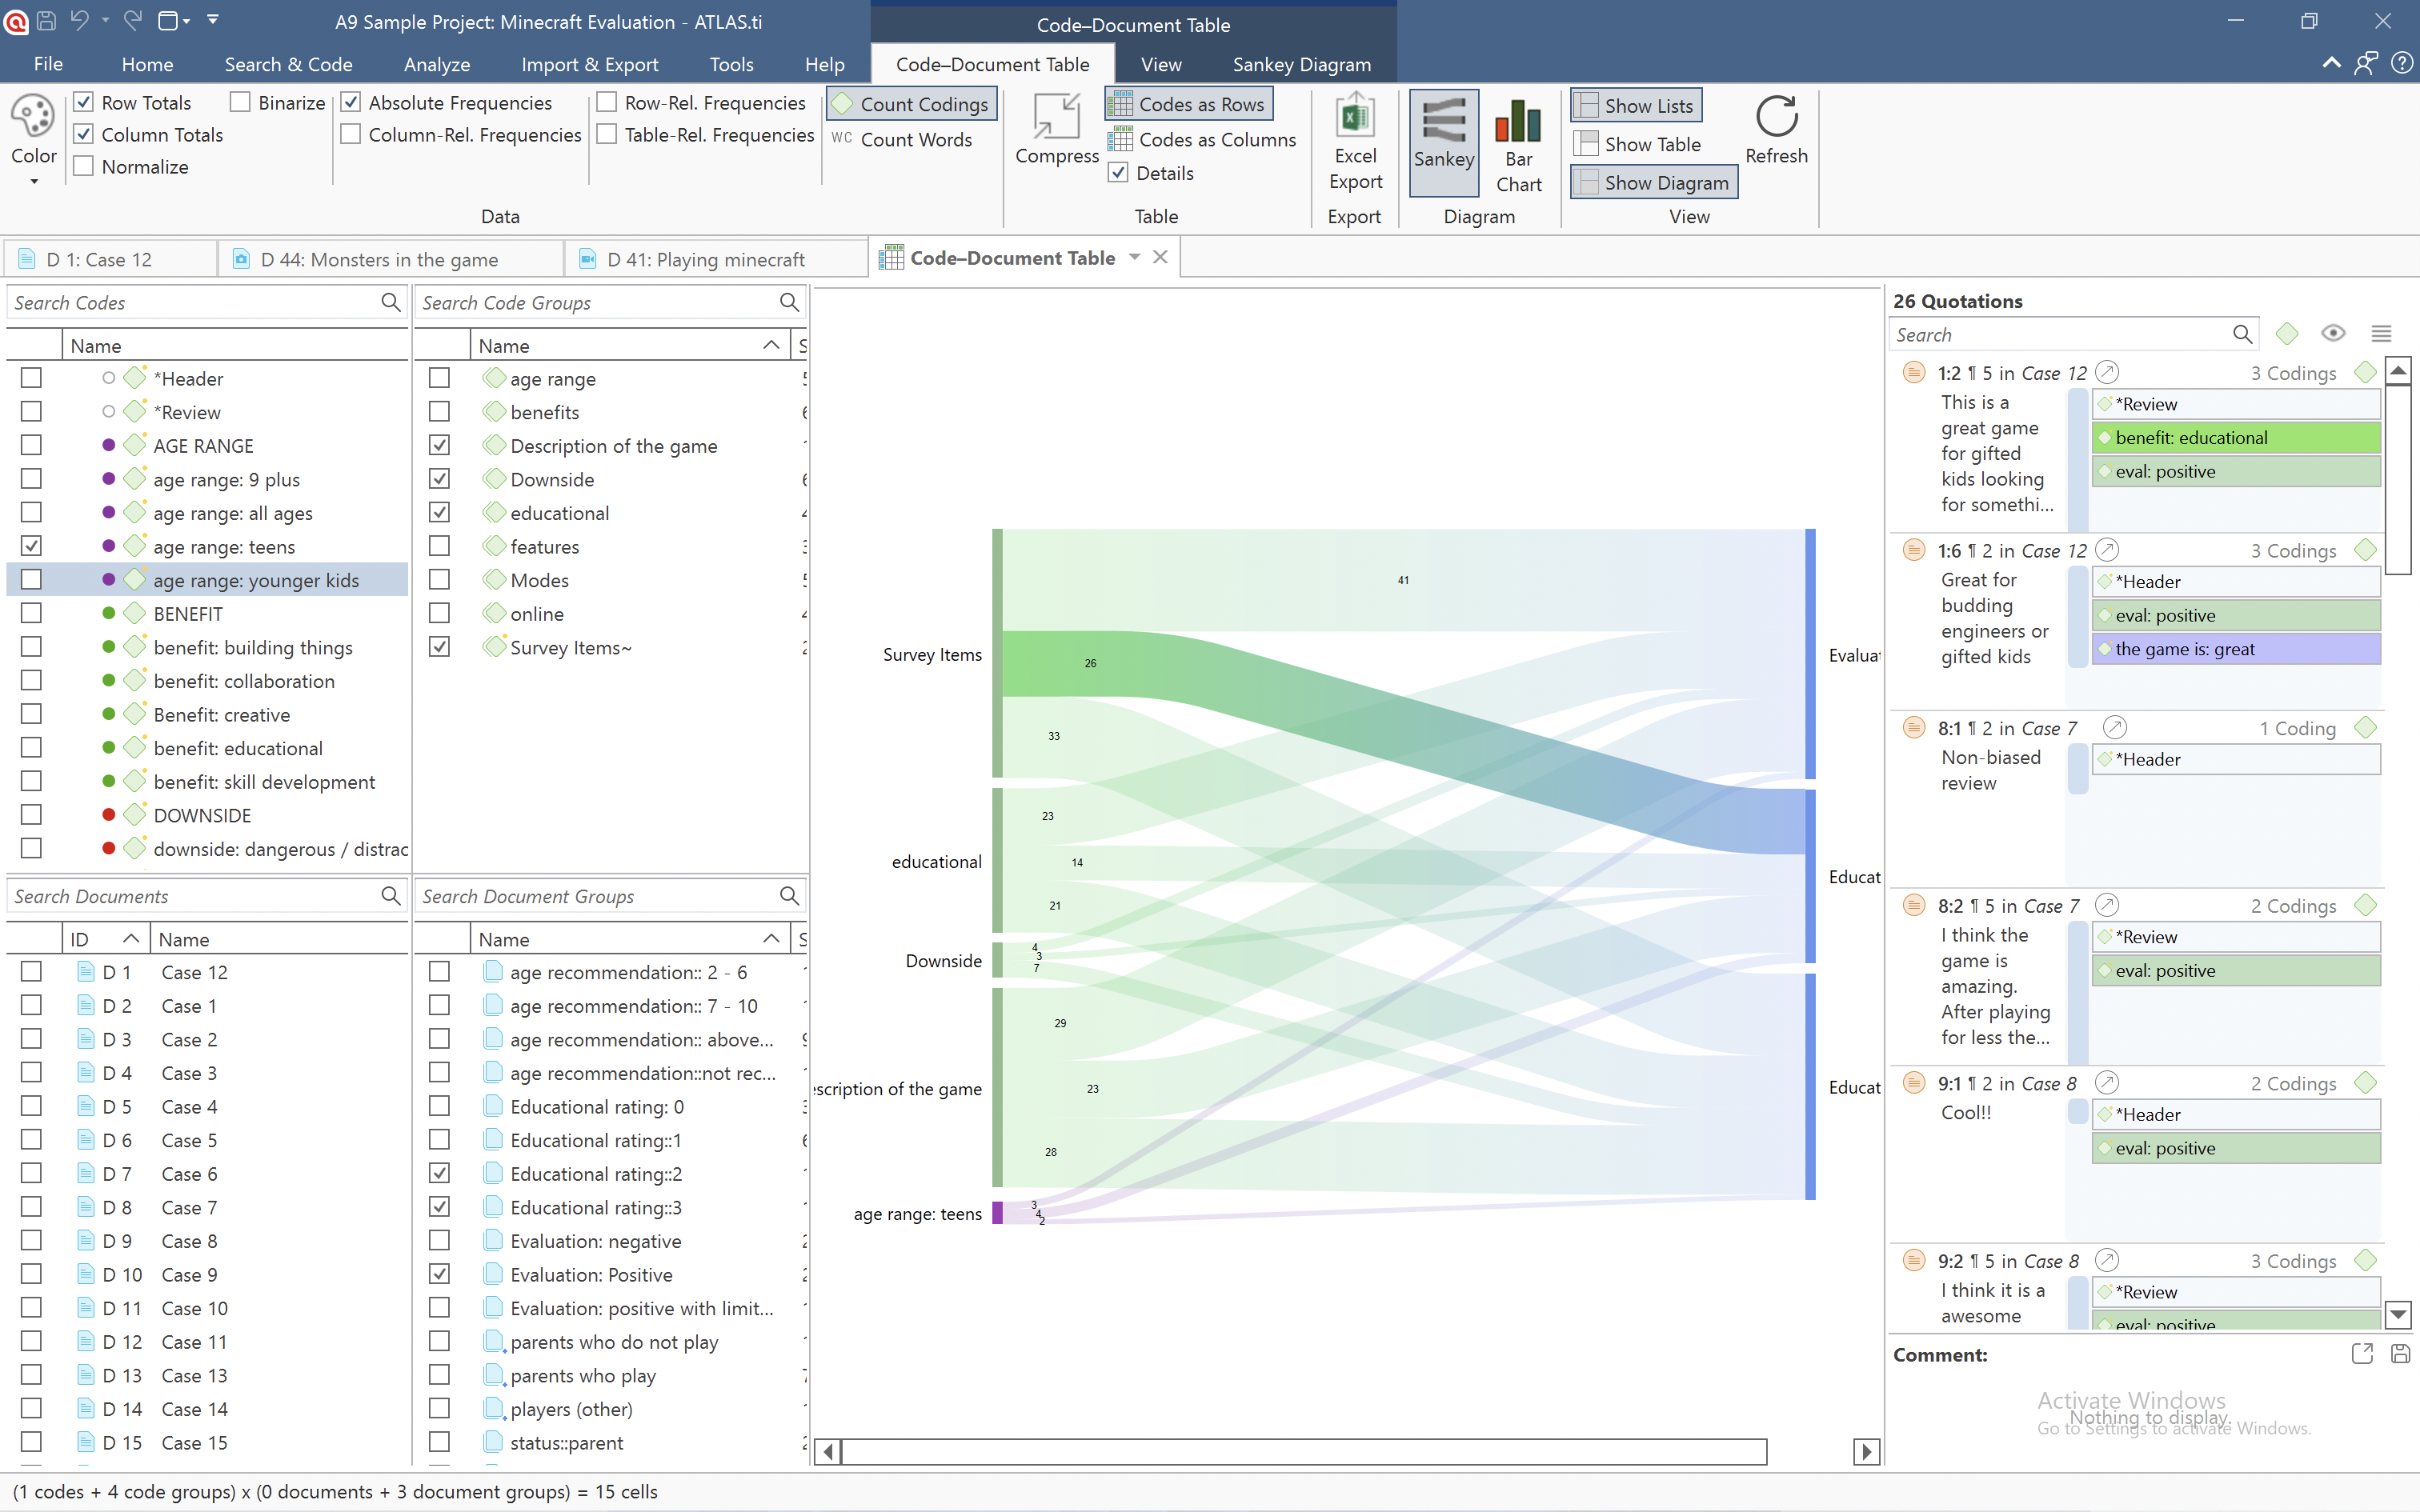
When you highlight a passage and assign a code, ATLAS.ti stores that relationship in a queryable database. This means you can run searches across your entire project later. I use the query builder constantly to check code frequencies, find co-occurrences between codes, and export segment data for reporting. The basic frequency count alone saves me from doing manual spot checks that used to take me an afternoon.
Get the Full Details
Advanced Features That Actually Matter
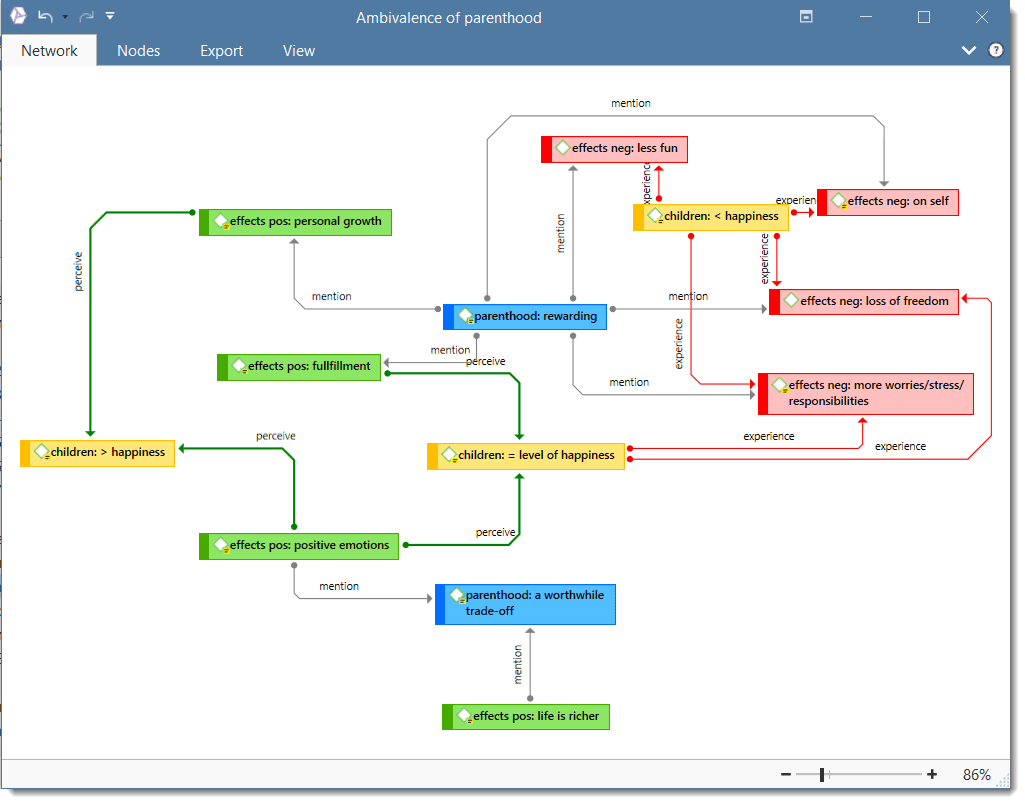
Most people never touch the network view, which is a mistake. ATLAS.ti can visually map how codes relate to each other. Drag a code onto the canvas and connect it to related codes. This becomes useful when you are checking for logical consistency in your coding scheme or presenting findings to a team. It also helps catch dead ends where a code has no connections and might not belong in the project at all. The document editor has a feature called the autocoder that applies codes automatically based on rules you set. A lot of users find this unreliable and turn it off immediately. It works fine for simple keyword matching but breaks down quickly with nuanced qualitative data. I recommend using it only as a first pass, then manually reviewing every match. It cuts initial coding time by roughly half but still requires thorough manual correction afterward. Another feature worth understanding is the quotation manager. When you code segments, they are stored as quotations within ATLAS.ti. The quotation manager lets you review, edit, merge, or delete coded segments across your entire project. This is how I clean up messy coding from early project phases. If you skip this step, your final code book becomes inflated with duplicate or fragmented quotations that make analysis confusing.
Export functionality is another area where ATLAS.ti falls short in places. You can export coded documents to CSV, Excel, or ATLAS.ti's own export format. But the layout of the exported data does not always preserve the original document structure cleanly. I usually build my own export templates using the built-in export wizard and define exactly which fields I need before I leave a project. This takes extra time upfront and prevents headaches during the write-up phase.
Common Pitfalls and Practical Limits
ATLAS.ti is not free. The academic license runs around four hundred dollars per year and the commercial license is significantly more. If you are a student or independent researcher on a tight budget, you should consider whether the cost is justified compared to free alternatives like QDAminer Lite or even Excel-based coding schemes for very small projects. For anything above fifty documents or complex multi-researcher work, the cost is usually worth it. Below that threshold, you are spending money on features you might not need. Collaboration within ATLAS.ti is possible through its team features but it is clunky. Multiple researchers can work on the same project simultaneously, but version conflicts happen frequently and resolving them is not intuitive. I once had two team members code the same document independently and their code sets conflicted in ways that required rebuilding the coding framework from scratch. The workaround was setting up a shared code book at the project start and requiring weekly syncs where we merged any divergent codes before moving forward. It added about three hours of overhead per week but prevented catastrophic data loss. The software does not handle longitudinal or temporal analysis well. If your research involves tracking how themes change over time across a series of documents, ATLAS.ti will not flag temporal patterns automatically. You have to create code structures or document groupings that reflect time periods yourself. This is a genuine limitation compared to some newer tools in the qualitative space that build in time-based visualization natively.
Learning curve is real. Expect a full week of slow, frustrating work before you stop fighting the interface. The toolbar placement changes depending on what document type is active. Right-click menus behave differently for codes versus documents versus projects. I still occasionally click the wrong area and lose a selected segment. It gets easier but do not expect to be productive on day one. If you are starting fresh, create a dummy project first. Import a handful of test documents and code them using the exact workflow you plan to use for your actual research. This reveals interface friction and workflow gaps before you commit real data to the system. I do this for every new project type and it usually saves me two or three days of rework later.