Machine Learning in Practice: What Actually Works
Most people approach machine learning backwards. They start with the fancy model — the transformer, the neural network, the thing with the most parameters — and then hunt for a problem that fits. That approach wastes money and months. I've seen it dozens of times. The real process starts with the data. Not collecting it, but understanding what it actually tells you. Before I touch a single line of training code, I spend time looking at the target variable, the feature distributions, the gaps. Sometimes that's three days of work. Sometimes it's three hours. It depends on whether the dataset was cleaned by someone who actually knows what they're doing, which is rare.How To Use Machine Learning Guide For Real Projects
When someone asks how to actually get a model from nothing to production, the answer is never what the tutorials show. Tutorials end when the accuracy number looks good on a test set. Production doesn't care about your test set. The first thing I do is establish a baseline that beats any model you'll build. Usually that means a logistic regression or a decision tree with minimal tuning. If your complex model can't beat that, you're solving the wrong problem or your features are leaking information in ways that won't generalize. This is where most projects die quietly — no one notices because the fancy model's validation accuracy looks impressive, but it falls apart the moment you serve it to real users. I ran into this exact issue last year on a churn prediction project. The XGBoost model hit 94 percent AUC on the test set. Everyone was happy. We deployed it. Within two weeks, the model was flagging every customer as likely to churn. The feature distributions had shifted slightly between the training period and live traffic — a common pattern when seasonal data gets mixed into the training window. The fix wasn't retraining. It was recalibrating the output layer with isotonic regression and adding a simple drift monitor on the top five features. That cut false positives by about sixty percent without touching the model architecture at all.
Here's something beginners almost never learn: feature engineering matters more than model choice for tabular data. You will consistently get better results from a well-engineered linear model than from a poorly engineered gradient boosting machine. I know that sounds wrong if you've been reading papers that only report model architecture changes, but the papers don't show the data preprocessing, and that's the part that actually drives performance.
The Parts Nobody Talks About
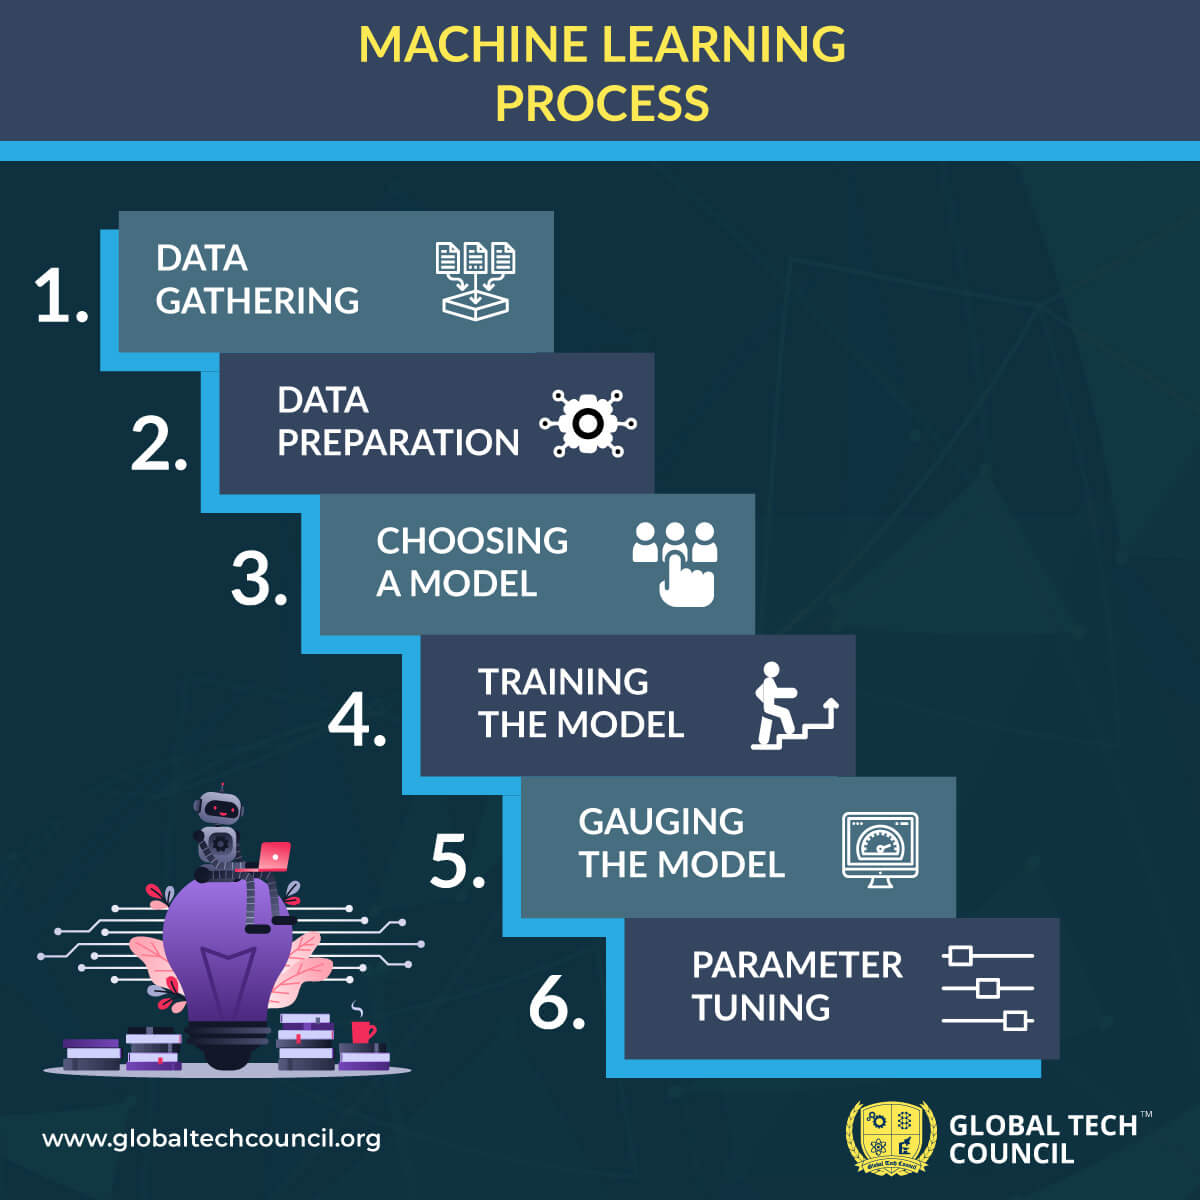
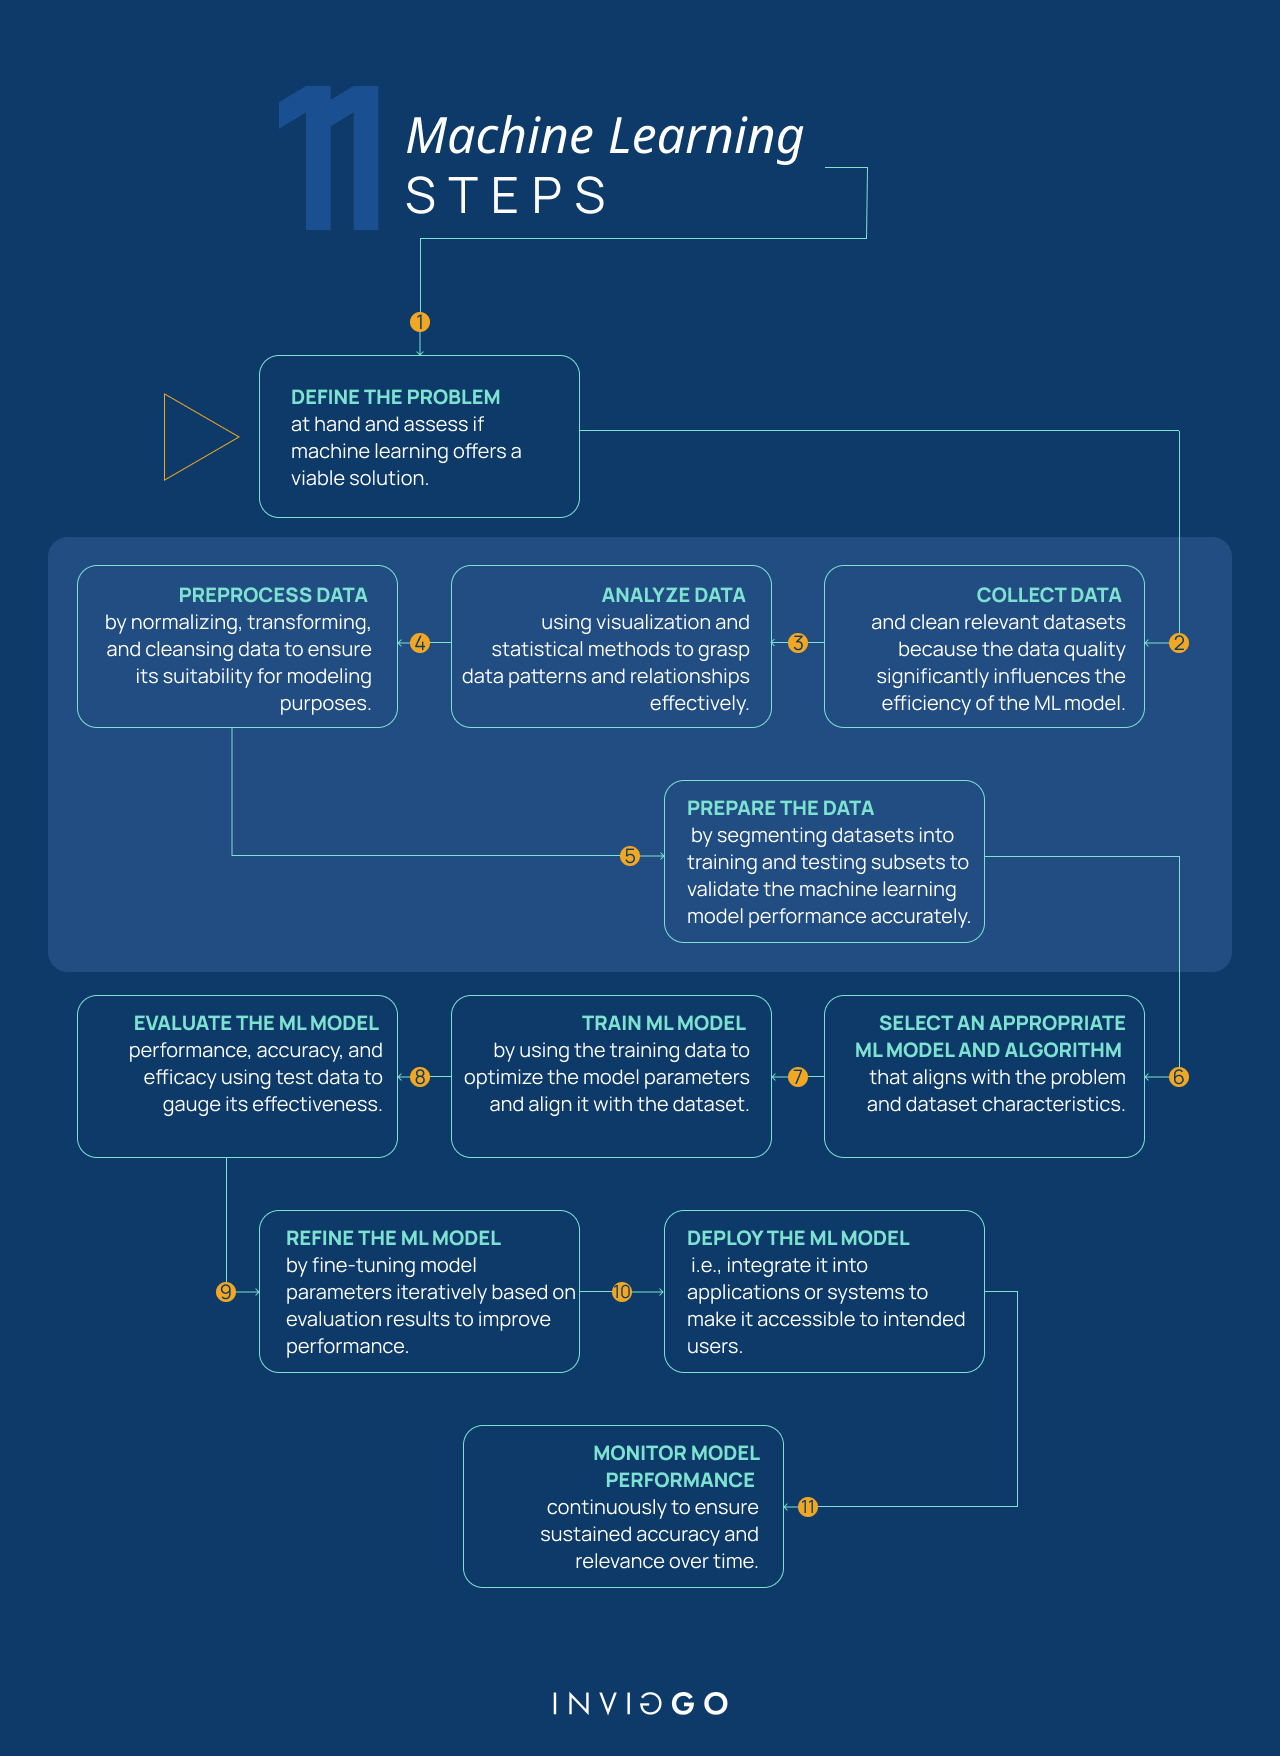
Model selection is the easy part. What eats your time is everything else. Data pipelines break. Labels get noisy. Dependencies update and your environment falls apart. You'll spend more time debugging a pip install conflict than you will on any actual model training. Use virtual environments. Not optionally — mandatory. Docker isn't required for every project, but a pinned requirements file with specific version numbers is non-negotiable. I once spent four hours diagnosing a silent degradation in model predictions that turned out to be a NumPy update changing floating point behavior by a few ULPs. The model was still technically correct, just numerically different enough to flip decisions on the boundary. For the actual modeling workflow, start with something simple and prove you can replicate results before adding complexity. If you can't get a basic model working end to end — data load, preprocessing, training, evaluation, export — then wrapping it in a more sophisticated pipeline won't help. It'll just make the failures harder to find.
Get the Full Details

Cross-validation strategy is another place people go wrong. Random K-fold cross-validation sounds fine until your data has any kind of temporal or group structure. If you're working with time series data or grouped observations — say, multiple entries per customer or per transaction batch — shuffling destroys that structure and gives you optimistically biased estimates. Use TimeSeriesSplit or group-aware splitting instead. The validation score will be lower, which is actually more honest. Model interpretability isn't just a nice-to-have for stakeholder communication. Tools like SHAP values and permutation importance reveal problems that accuracy metrics hide. I once found that a loan approval model was essentially learning to reject applicants from three specific zip codes because those areas had slightly higher default rates in the training data. The model had latched onto a proxy for race that violated fair lending regulations. Permutation importance on the postal code feature would have surfaced this in the second week of development instead of six months later during a compliance audit.
When Machine Learning Is the Wrong Tool
This part matters more than anything else in this guide. Many problems people bring to machine learning don't need it. If you can solve a problem with a rules-based system, do that. Rule-based systems are debuggable, predictable, and don't require labeled data. A recommendation engine might need ML, but a basic filtering system that says "if user watched these three genres, show them similar titles" will work fine and won't break when the training data drifts. ML also fails hard when you need low-latency decisions on uncertain inputs. A model trained on sparse or biased data will confidently give you the wrong answer, and that's worse than not having an answer at all. I've worked on projects where the model's confidence score correlated inversely with correctness — the model was most confident exactly when it was wrong. This happens in imbalanced datasets where the model learns to associate certain superficial patterns with the majority class. If your dataset has fewer than a thousand labeled examples, don't reach for deep learning. Fine-tuning a pretrained model might help in NLP, but for structured data you're better off with simpler approaches or synthetic data generation with heavy validation. The overhead of training a neural network on small data usually produces worse results than a carefully built logistic regression.
The other hard truth is ongoing maintenance. A deployed model isn't a finished product. It's a system that requires monitoring, retraining triggers, and rollback capability. Without that infrastructure, your model becomes a liability. Performance degrades silently. Users lose trust. The fix is straightforward in concept — set up prediction logging, track feature distributions over time, schedule periodic retraining — but most teams skip it because it's not exciting work and there's no deadline pressure to do it well. I typically recommend starting every project with a simple monitoring dashboard that tracks prediction distribution, feature drift, and a handful of key business metrics. It takes about a day to set up with tools like Evidently or.custom scripts, and it saves weeks of troubleshooting when something goes wrong three months after deployment. Most people skip it and regret it immediately when production breaks on a Friday night. The actual code for building models is the smallest part of the work. The rest is data quality, evaluation rigor, and operational discipline. Pick a toolstack and stick with it. Scikit-learn for tabular, PyTorch or TensorFlow for neural networks, XGBoost or LightGBM when you need speed and performance on structured data. Don't switch frameworks mid-project. The learning curve of a new library will cost you more than any theoretical advantage it offers.