Getting Data That Doesn't Lie to You
I spent three years building sentiment systems for mid-market brands before realizing most people do it wrong. The problem isn't the tool. It's that people feed generic social media scrapes into off-the-shelf NLP pipelines and call it insight. That gives you a dashboard full of vague green bars and no actual direction. Here is how I actually use sentiment analysis for brand building, not just reporting. First, stop pulling from everywhere. Pick two or three platforms and go deep. Twitter/X for public reaction, Reddit for unfiltered opinion, and review sites like Yelp or G2 depending on your category. I usually set up a daily pull using RapidAPI connectors or direct API access where available. The output goes into a SQLite database, not a spreadsheet. You will thank me later when you need to join conversation data with your own support tickets.
How To Use Sentiment Analysis For Brand Building
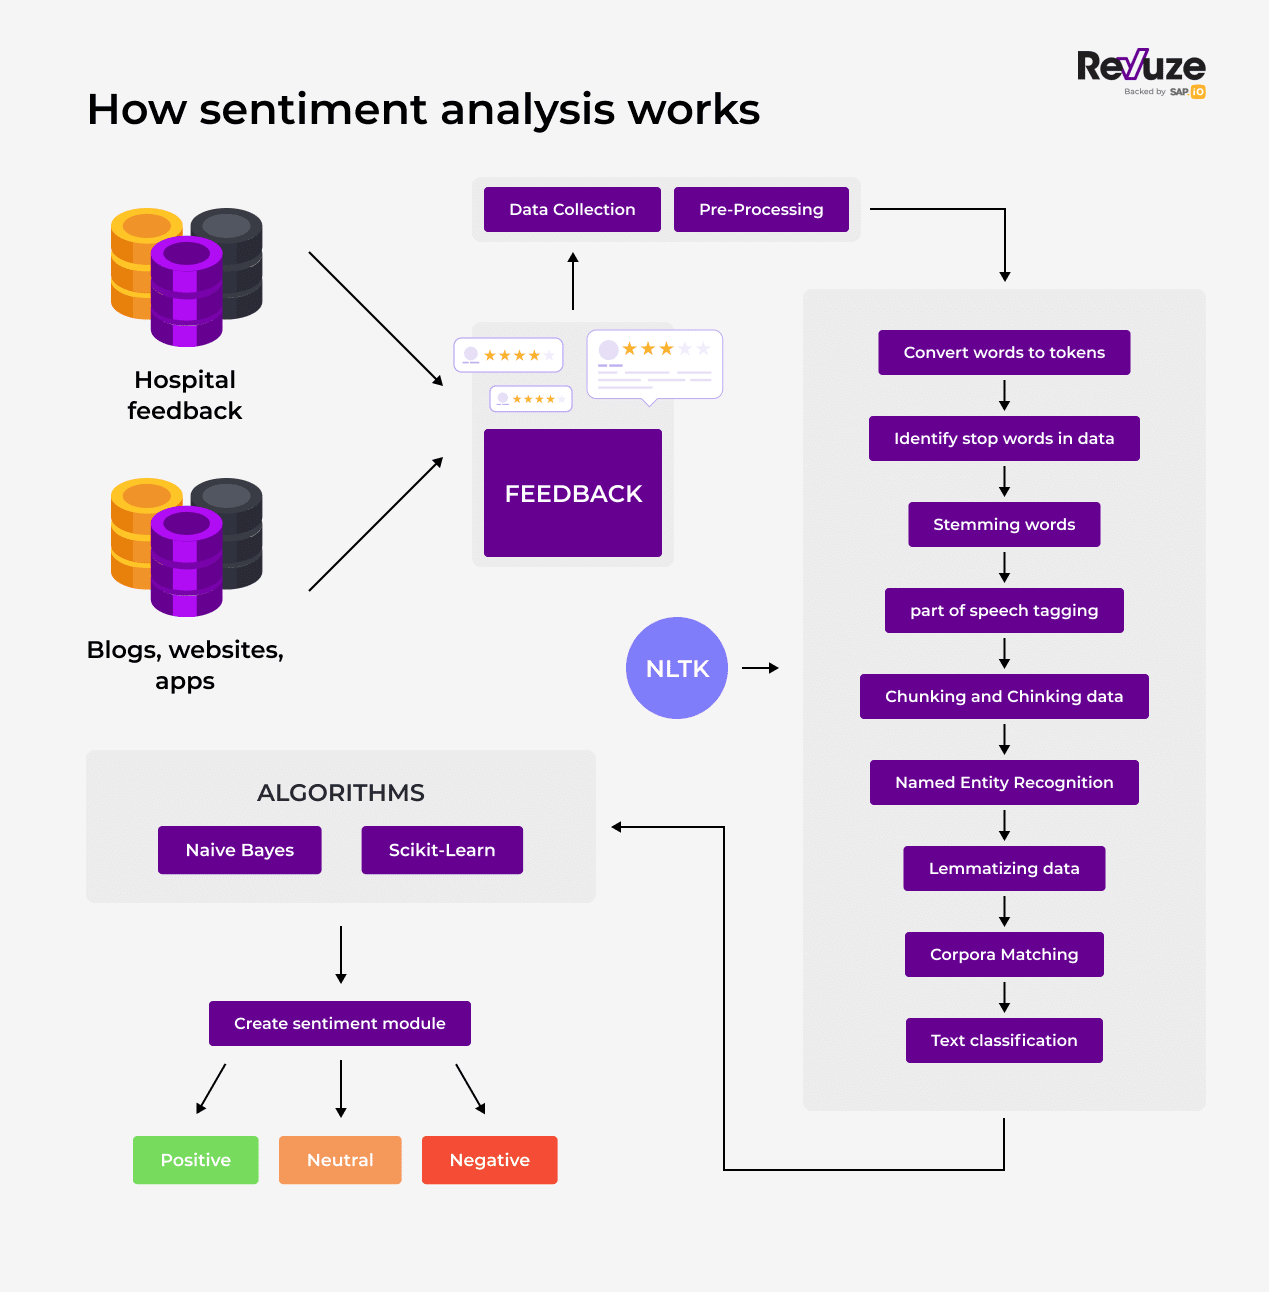
Start by tagging conversations, not just scoring them. Raw polarity (positive, negative, neutral) is useless for brand strategy. What matters is topic clustering around brand attributes. I run a simple BERT-based classifier fine-tuned on my own labeled data—maybe 500 annotated samples per quarter—and then use DBSCAN or HDBSCAN to group mentions into themes. "Shipping delay," "customer service attitude," "product quality," that kind of thing. Here is where most people waste money. They buy a SaaS tool that claims to do all of this out of the box. Those tools typically score at a 70 to 75 percent accuracy rate on real-world brand mentions because they were trained on movie reviews and product descriptions, not on people complaining about your actual customer support experience. I learned this the hard way when a client switched from their custom pipeline to a commercial platform and watched their sentiment trend reverse entirely. Negative spikes became positive. The tool was classifying sarcastic rants as praise because the word embeddings weren't calibrated for their industry. The workaround is straightforward. Keep a small held-out validation set of your own labeled mentions and recalibrate quarterly. Even a basic logistic regression layer on top of your transformer embeddings, trained on fresh samples, will tighten accuracy from 72 percent to roughly 84 or 85 percent. That difference separates actionable signals from noise.
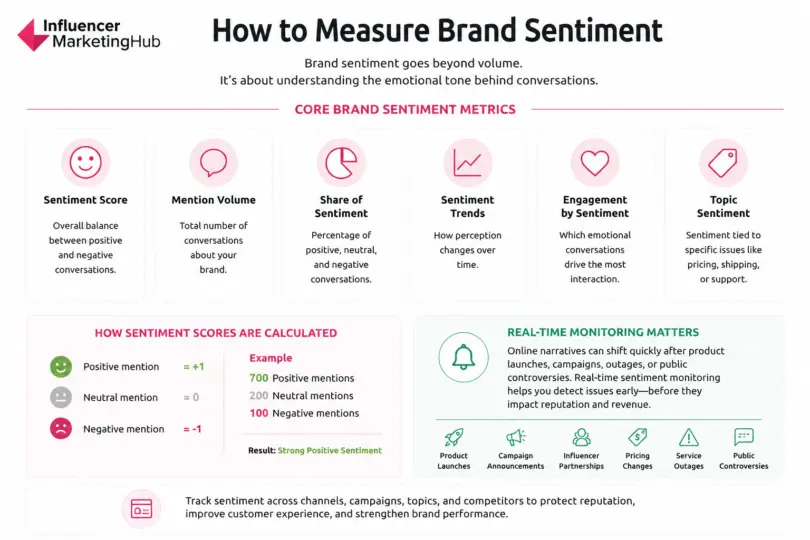
Once you have reliable tagged sentiment, map it against your brand positioning pillars. If you claim to be the most reliable option in your space, track mentions around reliability specifically. Look for shifts over time, not absolute numbers. A dip from 12 percent negative to 8 percent negative on shipping complaints means something. A flat 40 percent across every month means your signal is broken or nobody talks about that attribute anyway. I also layer in entity extraction. When someone writes "their new app is terrible but the support team saved it," the raw sentiment is mixed. If you only look at the overall score, you lose the nuance. Using spaCy or a similar NER pipeline, I break the sentence into entities and assign sentiment per entity. The brand gets a neutral overall mark, but the support team scores positive and the product scores negative. That tells the product team exactly where to focus without drowning in aggregate data. There are limitations worth stating plainly. Sentiment analysis fails on satire, regional slang, and highly domain-specific jargon. If you operate in fintech or healthcare, your customers will use terminology that general models misclassify constantly. I have seen "bullish" tagged as positive sentiment in a stock discussion thread when the actual context was a warning about a bubble. You need a domain adaptation step, and if you skip it, your dashboard looks clean while the underlying data drifts into nonsense.
Get the Full Details
Another thing nobody mentions: volume matters less than velocity. A brand might have 10,000 monthly mentions with mild positive sentiment, but 200 of those are from high-influence accounts driving the conversation. Weight your sentiment by follower count or engagement rate of the source. A negative post from someone with half a million followers carries more brand risk than hundreds of low-reach complaints. I apply a simple logarithmic weight based on account reach and adjust the aggregate score accordingly. If you want a practical starting point, here is what I deploy for smaller teams who can't build a custom stack. Pull mentions through the Reddit API and Twitter API, run them through a pre-trained transformer model like cardiffnlp/twitter-roberta-base-sentiment-latest, extract entities with spaCy, and push the results into a PostgreSQL database with a simple Flask dashboard. This takes roughly two days to set up if you already know Python. The maintenance cost is low. The model needs reweighting every few months, but that is a two-hour task. The main alternative is hiring a consultant or buying an enterprise tool like Brandwatch or Sprout Social. Those platforms are easier to adopt but cost between three and eight thousand dollars monthly and still suffer from the same training data limitations I described. They work fine for broad trend monitoring. They fail when you need precise, attribute-level sentiment tied to specific brand initiatives.
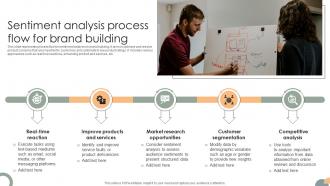
I track sentiment changes alongside campaign launches and product updates. When a brand releases a new feature, I compare the sentiment distribution in the ten days before and after, broken down by topic cluster. If "ease of use" sentiment drops while "price" sentiment rises, that is a signal worth investigating before the next quarterly review. Most brands miss these cross-attribute correlations because they only look at overall scores. The real value comes from connecting sentiment data to your actual business outcomes. I once helped a client correlate a sustained negative shift in "onboarding experience" mentions with a 14 percent drop in 30-day retention. The sentiment data preceded the retention drop by about three weeks. That gave the product team time to fix the issue before churn accelerated. Without that early signal, they would have been reacting to losses instead of preventing them. Keep your system simple enough that you actually use it. Over-engineered pipelines get abandoned within six months. Start with clean data from two platforms, reliable topic tagging, and a dashboard that answers one question: where is our brand perception moving, and in which direction? Then expand from there.