The Arithmetic Average Explained Plainly
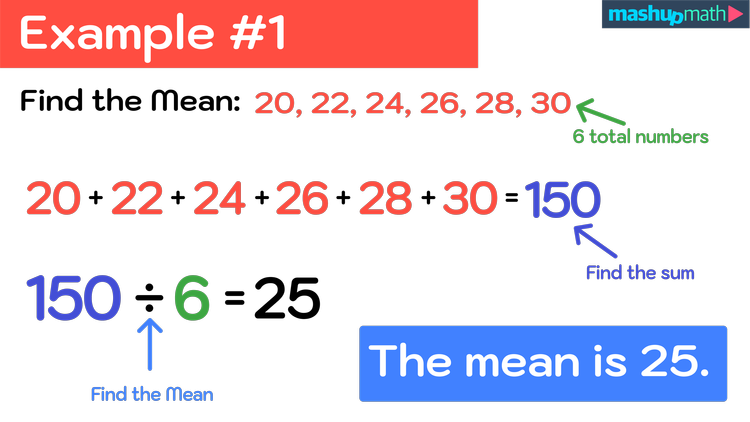
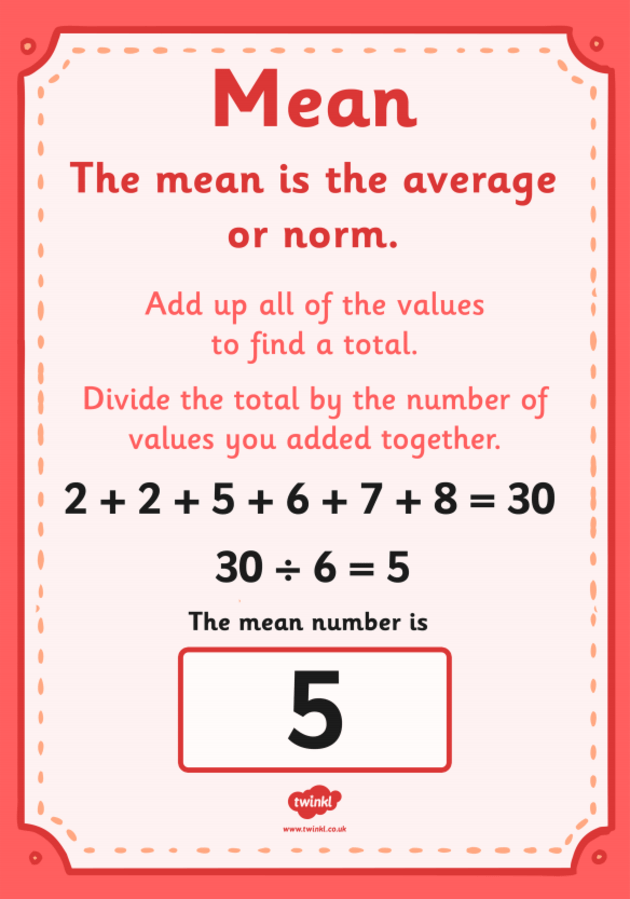
You add everything up and divide by how many things there are. That is the mean. That is the entire operation. People make it complicated because they memorise a formula before they understand what the formula is actually doing, and then they panic when the numbers get messy. I found this out years ago when I was helping someone analyse test scores from a class of thirty students. The raw data was a spreadsheet full of individual marks, and the task was to calculate the mean for a report that needed to go to the department head the next morning. I just added the scores and divided by thirty. It took about forty seconds in Excel using =AVERAGE(), but the person was convinced I was supposed to be doing something harder. They kept asking if I had accounted for weightings when I had not been asked to. There is a specific kind of confidence that comes from overthinking basic arithmetic.
How To Work Out The Mean In Maths
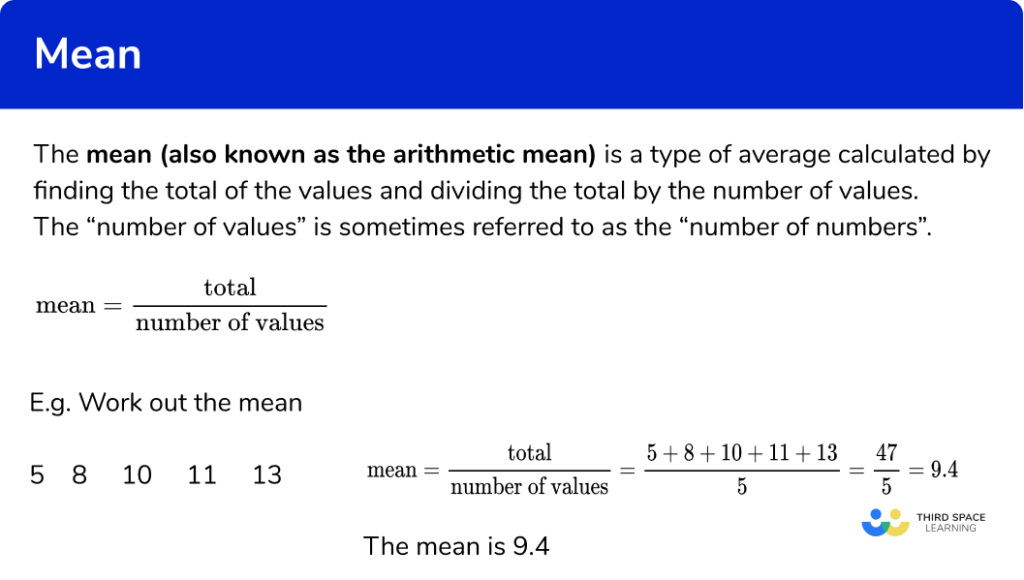
The formula is sum of all values divided by the count of values. Written out it looks like x-bar equals the sum of x_i divided by n. You do not need to write it on the board or memorise Greek letters to use it. Just add the numbers and divide by how many there are. If you have the numbers 4, 7, and 13 the sum is 24. Three numbers. Twenty-four divided by three is eight. The mean is eight. Done. Here is where it gets interesting though. The mean is sensitive to outliers in a way that most people do not appreciate until they see it happen to their own data. I had a dataset once where I was looking at monthly rainfall across a period of five years for a small coastal town. Most months fell between forty and one hundred millimetres. Then there was one month, November 2014, that recorded four hundred and twenty millimetres because a single weather system stalled over the area for six days straight. When I calculated the mean rainfall across all sixty months, that one outlier pulled the average up to one hundred and nine millimetres per month. The median came out to seventy-two millimetres. For anyone trying to understand what a typical month looks like in that town, the mean was lying to them by about forty percent. This is not a problem unique to rainfall data. It shows up in income figures, housing prices, response times for customer support tickets, the number of clicks users make before converting on a website. Anytime you have a distribution with a long tail the mean shifts towards that tail and stops representing the centre of your data well. If you are presenting a mean to a group of stakeholders and someone asks whether it is representative, you should know how to answer that question before you get to the meeting. Check the median alongside it. If the two numbers are close, the mean is probably fine. If they are far apart, your data has skew and you should probably mention it.
There is also the matter of grouped data, which is where most students hit their first real wall. You are not given individual values. Instead you are given ranges with frequencies. Like twenty people scored between fifty and sixty, fifteen scored between sixty and seventy, and ten scored between seventy and eight0. The mean here requires a midpoint assumption. You take the midpoint of each range, multiply it by the frequency, add those products together, and divide by the total frequency. The midpoint of fifty to sixty is fifty-five. You multiply by twenty. Fifty-five times twenty is eleven hundred. Sixty-five times fifteen is nine hundred and seventy-five. Seventy-five times ten is seven hundred and fifty. Add those up and you get two thousand eight hundred and fifty. Divide by forty-five and the estimated mean is approximately sixty-three point three. It is an estimate because you are assuming all the values in a range cluster at the midpoint. They rarely do. The actual distribution within any given range could be uniform, clustered towards the lower end, clustered towards the upper end, or completely random. The grouped mean is the best you can do with the information you have, but you should treat it as such. I once saw a quality assurance team use a grouped mean from bin widths of five hundred units to set a production target, and the bins were so wide that the estimate was useless for anything more than a back-of-envelope calculation. Narrower bins would have made a significant difference, but narrowing them required access to raw data they did not have at the time. Weighted means are another variation that trips people up more than it should. Not every value in your dataset deserves equal influence. A common example is calculating a student final grade where homework counts for twenty percent, quizzes for thirty percent, and the final exam for fifty percent. You multiply each score by its weight, add those products, and divide by the sum of the weights. If a student scores seventy on homework, eighty on quizzes, and sixty-five on the exam the weighted mean is zero point two times seventy plus zero point three times eighty plus zero point five times sixty-five, which gives you sixty-nine. The unweighted mean of those same three scores would be seventy-five. That difference matters when decisions are being made based on the number.
Get the Full Details

One thing beginners consistently get wrong is confusing the mean with the mode and the median and then picking the wrong one for the situation. The mean uses every value in the dataset. The median is the middle value when data is ordered. The mode is the most frequently occurring value. None of them are wrong. They just answer different questions. If you want to know what the typical value is in a skewed distribution the median is usually more honest. If you want to know what the average is in the strict arithmetic sense you use the mean. If you are dealing with categorical data like shoe sizes where you want to know the most common size the mode is the only one that makes sense. Using the mean for shoe sizes is technically possible but practically absurd. There are also edge cases in calculation where precision becomes an issue. If you are adding very large numbers and very small numbers together in a spreadsheet or a programming language you can run into floating point rounding errors. I worked on a project once where we were summing transaction amounts in the range of pennies across millions of records and the final total was off by a few dollars purely due to binary floating point representation. Switching to a decimal data type fixed it immediately. It is a niche problem but it is the kind of thing that looks like a mystery until you know what to look for. Hand calculations are another area where people lose confidence unnecessarily. Doing the mean of a long list of numbers by hand is tedious and error prone. I have done it in exam conditions where you cannot use a calculator and the list has twenty values. The trick is not speed, it is organisation. Write each number on a separate line, cross it off as you add it, and keep a running total in the margin. When you finish adding, divide. If your total looks wrong, check your division. Most mistakes happen at the addition stage, not the division stage.
Technology changes how you approach this problem but it does not change the problem itself. Excel and Google Sheets both have built-in AVERAGE functions that handle thousands of values instantly. Python users will reach for numpy.mean or statistics.mean. R has mean(). These tools are fast and reliable for routine calculations. The risk is that relying entirely on tools without understanding the underlying operation means you lose the ability to sanity-check the output. I have seen dashboards published with mean values that were clearly wrong because the person building them included null values in the calculation or filtered the data incorrectly. The tool returned a number, so they assumed the number was correct. It is worth manually verifying at least one calculation against the tool output before you trust an automated report. The mean is not a complete description of a dataset. Two datasets can have identical means but completely different distributions. I remember comparing two sets of daily temperature readings from different cities that had the same mean of eighteen degrees Celsius, but one city had very stable temperatures while the other swung between six and thirty degrees across the same period. The mean told you nothing about that difference. Always look at the spread. Standard deviation, variance, range, interquartile range. These give you context that the mean alone cannot provide. If you are learning this for the first time start with small numbers and build up. Calculate the mean of five random numbers by hand. Then ten. Then fifty using a spreadsheet. Notice where errors creep in and adjust your process. The method does not change as the numbers get bigger. Only the volume changes.