The Reality of Writing These Reports
You run the scan, you get the output, and now you have to turn thousands of findings into something a CISO will actually read. The tools hand you a CSV with severity ratings and CVE references. That is the starting point, not the finished product. A vulnerability assessment report is a translation exercise. You are translating machine-generated risk data into language that tells people which holes to patch first and which ones they can ignore until next quarter. I spent years doing this at two different companies, and the pattern never changes. Someone sends you an asset inventory, you run a combination of Nessus and manual verification, and then you have to produce a document that does not get routed straight to the trash. The ones that survive are the ones that show exactly what you found, why it matters, and what the attacker would need to do to exploit it. Everything else is noise.
How To Write A Vulnerability Assessment Report
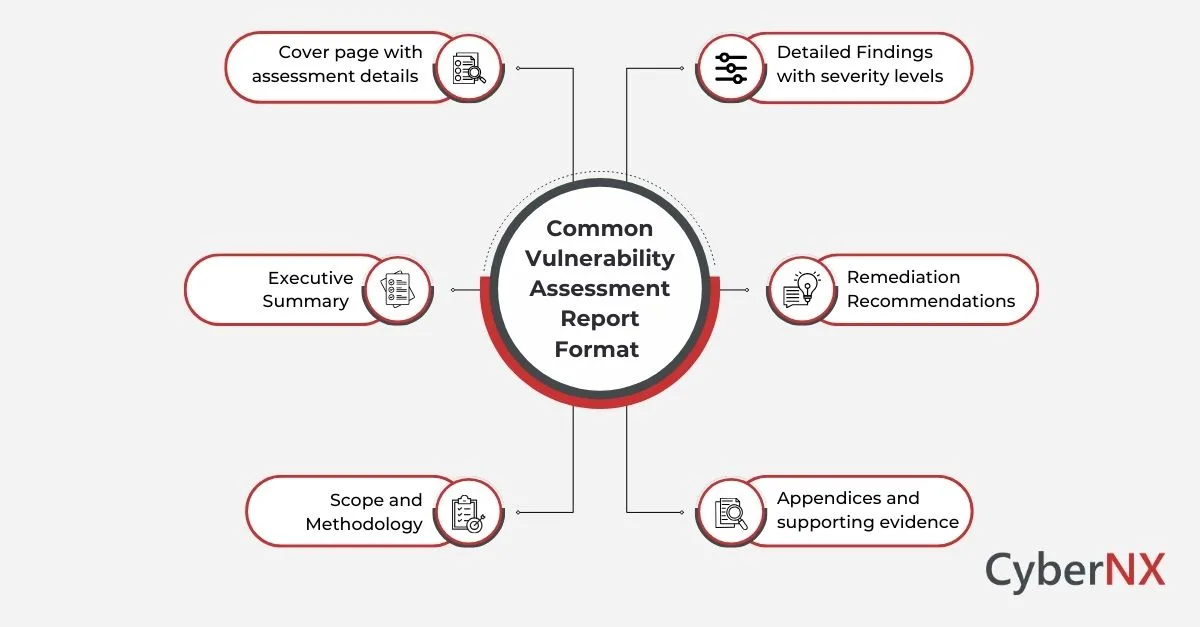
Start by getting the scope right. I see too many reports that claim to cover the perimeter when the scanner was only pointed at a single subnet. List every IP range, domain, and application you tested. List the tools used with version numbers. A scanner without a version stamp is useless for reproduction, and anyone reviewing your work later will assume you guessed the results. Next comes the finding itself. Each finding needs a title, a description, the affected asset, the evidence, the severity with rationale, and the remediation guidance. The description is where most people slack off. Do not paste the CVE text from NVD verbatim. Summarize what the flaw actually allows in one or two sentences. Then add the evidence - a screenshot, a request response, a version string. If you cannot prove the finding exists on that specific host, downgrade it to informational or remove it entirely. False positives destroy credibility faster than anything else. Here is the part beginners miss. Not every high-severity finding is equal. I once found a critical RCE on a legacy server that sat behind three firewalls, required authentication, and only accepted connections from the internal VLAN. The CVSS base score was 9.8. The actual risk was closer to 4.2. I wrote the report with both scores - the base score for the database, the environmental score for the decision-makers. That distinction alone prevented a panic-driven budget allocation that would have gone to the wrong problem.
The executive summary should be two pages maximum. One paragraph describing overall posture. One paragraph highlighting the top five findings with business impact. One table mapping each critical and high finding to a remediation owner and target date. If you give leadership more than that, they stop reading. Use CVSS v3.1 consistently. Do not mix versions. Do not use CVSS v2 for anything except documenting historical comparisons. If your organization has a vulnerability management policy, reference it by name and map your severity ratings to the thresholds it defines. A report that ignores existing policy gets ignored in return. One edge case I ran into that still bugs me: a scanner flagged a SQL injection on a login form that required valid credentials. I tested it manually and confirmed it was exploitable, but the payload only worked after a successful auth session. The scanner reported it as an unauthenticated remote code execution vector. I rewrote the finding to specify authenticated access was required and adjusted the attack complexity metric accordingly. The severity dropped from critical to high. It was the right call, but it meant someone had to question the automated result instead of blindly trusting the tool. Make sure you build in time for that verification step. It adds roughly half a day to a standard assessment cycle for anything beyond a trivial network sweep.
Get the Full Details
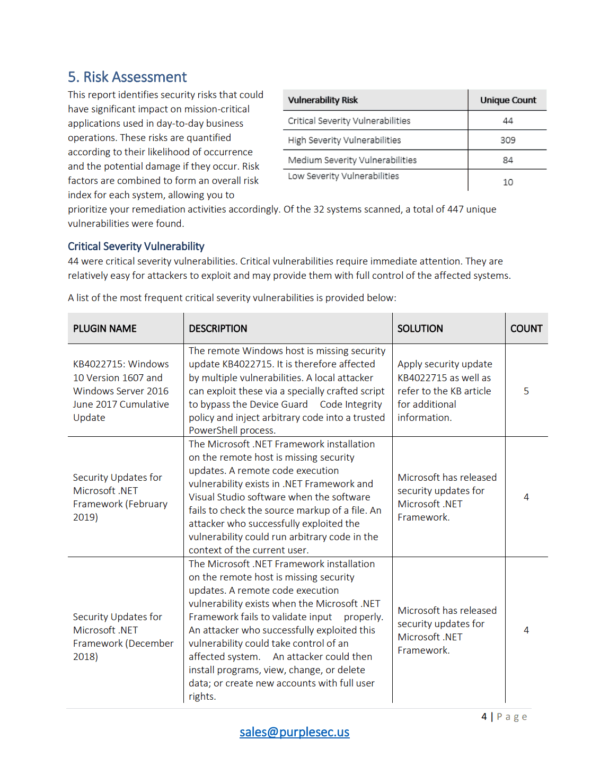
For remediation guidance, be specific. Do not write "update the software." Write the exact patch version, the vendor link, and the known workaround if the patch is not available. If the finding is a configuration issue, tell them which setting to change and what value to set. A recommendation that requires the reader to figure out the next step is not actionable guidance. Prioritization matters more than completeness. A report covering 2,000 findings with no prioritization is less useful than a report covering 50 findings with a clear action plan. I use a combination of exploit availability, asset criticality, and exposure to rank findings. Things that are actively exploited in the wild and sit on internet-facing assets with sensitive data go at the top. Internal-only misconfigurations with no known exploit chain go lower. Be honest about what you do not know. If exploit code exists on GitHub but you have not verified it works against your specific version, say so. Do not imply it works. The biggest limitation of this approach is that it depends entirely on the quality of your initial scan. No amount of careful writing will fix a scanner that missed a finding because it was blocked by a WAF rule or the service was running on a non-standard port. Supplement automated scanning with manual testing on at least a sample of critical assets. Even ten minutes of manual verification per application catches the things the tooling never will.
Another limitation is the time it takes to produce a thorough report. A proper assessment with manual verification, evidence collection, and executive summary typically requires two to three working days for a small-to-medium environment. If you are being asked to deliver this in two days, you are either going to cut corners on verification or the scope needs to shrink. There is no way around that trade-off. Keep the appendix clean. Raw scanner output goes in an appendix, not the main body. Label each appendix section by tool and date. Use consistent formatting. If someone needs to reproduce your work six months from now, they should be able to open the appendix and find exactly what you ran and when. That is the process. It is not elegant, and it does not scale well without good tooling and a template you have refined over multiple assessments. But it produces a document that actually gets read and acted on, which is the only measure that matters here.