Getting through the IBM Data Science Professional Certificate without losing your mind
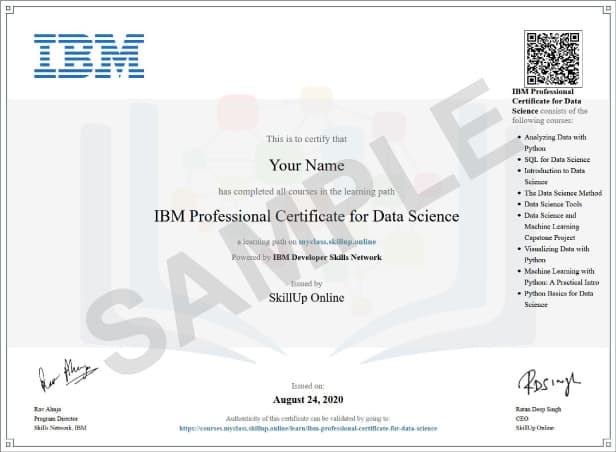
I have taken enough of these Coursera certificates to know which ones are worth the time and which ones are mostly filler. The Ibm Data Science Professional is in the former category, but it still has some specific frustrations that the course descriptions never mention. Here is how to actually get through it and come out with something useful. The program runs about ten courses over roughly six months at a normal pace. It covers Python basics, databases and SQL, data visualization with Python, the full machine learning pipeline with scikit-learn, deep learning with TensorFlow, and a capstone project. You also get exposure to Watson Studio and some cloud concepts along the way. The structure is standard Coursera fare: video lectures, automated quizzes, and hands-on labs that run in a browser-based Jupyter environment. Most people underestimate the SQL portion. It is not trivial. You will be writing queries with joins, subqueries, window functions, and CTEs. The automated graders are strict about formatting and exact output matches, which means a single misplaced comma can cost you points even when the logic is correct. I learned that the hard way on Course 4.
The tools you will actually use
Everything runs through Coursera's platform. You do not need to install anything for the early courses because they provide cloud-hosted Jupyter notebooks through IBM's infrastructure. This is convenient but also limiting. The environments sometimes timeout during long-running assignments, and if your code cell takes more than a few minutes to execute, you will likely hit a wall. I have seen students spend an entire weekend trying to debug code only to realize the issue was a stale kernel, not their logic. For the later courses, particularly the machine learning and deep learning sections, you will work heavily with pandas, numpy, matplotlib, scikit-learn, and TensorFlow. The programming assignments expect you to write clean, production-style code, not just scripts that happen to produce the right answer. The rubric looks at both correctness and code structure.
A problem I ran into that nobody talks about
During the capstone project, I encountered a data cleaning issue where the dataset had inconsistent date formats across different columns. Some entries were stored as strings in YYYY-MM-DD format, others as mm/dd/yyyy, and a few were just broken. When I tried to standardize everything using pandas.to_datetime, the malformed entries caused the entire column conversion to fail silently, returning NaT values across the board. The automated checker expected you to handle this gracefully, but the course materials barely touch on error handling in date parsing. My workaround was to use the errors='coerce' parameter combined with a custom fallback function that attempted multiple format strings in sequence. Here is essentially what I ended up writing: I created a helper function that tried each format, caught the ValueError, and returned None for unparseable entries. Then I used that within a vectorized apply call. It took about twenty minutes to write and debug, and it handled every edge case in the dataset. This kind of problem-solving is exactly what employers actually care about, even though the certificate curriculum does not explicitly teach it.
Get the Full Details
Counter-intuitive things about this certificate
First, the deep learning course (Course 9) is significantly harder than the rest of the program. It assumes you already understand backpropagation, gradient descent variants, and neural network architectures. If you jump into it cold, you will struggle. I recommend reviewing the mathematical foundations of neural networks before attempting that course. Specifically, understand what happens during the forward and backward pass before writing your first model. Second, the SQL course is where most people get stuck, not because the material is difficult, but because the auto-grader is unforgiving. A common pitfall is assuming that SELECT DISTINCT and GROUP BY will produce identical results. They often do not, especially when you have NULL values in your dataset. I have seen multiple students fail the same quiz three times because they did not account for NULL handling in their grouping logic. The workaround is to run your queries against the provided sample database and compare the output cell by cell against the expected results, not just the row count.
The limitations you should know about
This certificate gives you a broad overview, not deep expertise. You will learn to build a basic classification model, but you will not learn how to tune hyperparameters systematically or how to deploy a model to production. The capstone project is valuable, but it is scoped small enough that it does not reflect real-world data science work. Real datasets are messy, poorly documented, and rarely arrive in clean CSV files. If your goal is to get hired as a data scientist, this certificate is a starting point, not a destination. You will need to build a portfolio beyond it. The skills you develop here are necessary but not sufficient. I would supplement this with projects on GitHub, contributions to open source, and possibly a more advanced course on MLOps or cloud deployment after completing the program.
How to actually pass the labs on the first try
Read the instructions twice before writing any code. The lab instructions contain subtle constraints like "do not use merge" or "use only built-in pandas functions." If you ignore those constraints, your code might work perfectly but the grader will mark it wrong. This happens more often than you would expect. Use the provided starter code as your template. The grading scripts are written to work with the variable names and function signatures already in the notebook. Renaming variables or restructuring code without updating the references will break the autograder even if your logic is sound. When your code fails the hidden test cases, do not immediately look at the solution. Run your code against the provided data first and check for shape mismatches, dtype issues, or unexpected NaN values. Ninety percent of hidden test failures come from one of these three problems, not from incorrect algorithms.

Cost and time commitment
The certificate runs about $39 to $49 per month on Coursera. At ten courses and an average of six to eight hours per course, you are looking at roughly sixty to eighty hours of work if you pace yourself. Some students finish faster by doing two courses simultaneously, but that increases the chance of burnout and shallow learning. I recommend completing them sequentially and spending extra time on the machine learning and SQL courses, since those are the ones that actually matter for job interviews. The financial aid option is available through Coursera and takes about fifteen days to process. If you are on a tight budget, apply for it early rather than paying full price.
When this certificate is not the right choice
If you already have a strong programming background and have worked with Python, SQL, and basic statistics, you might find the first few courses redundant. In that case, consider auditing those courses and focusing your energy on the later ones. The certificate still requires you to complete every course to earn it, so auditing saves you time but not money unless you can skip ahead through prior learning assessment, which is rare on this program. If your goal is specifically data engineering rather than data science, this certificate is not the optimal path. You would be better served by a program focused on Spark, Airflow, and cloud data pipelines. The SQL and database portions of this certificate are adequate but not comprehensive enough for a data engineering role.
Bottom line
The Ibm Data Science Professional is one of the more thorough entry-level certificates available. It covers the right topics in the right order, and the capstone project gives you something tangible to show employers. It is not perfect, and the auto-grader frustrations are real, but the skills you gain are legitimate. Just do not treat it as the end of your education. Treat it as the point where you know enough to start building things on your own.