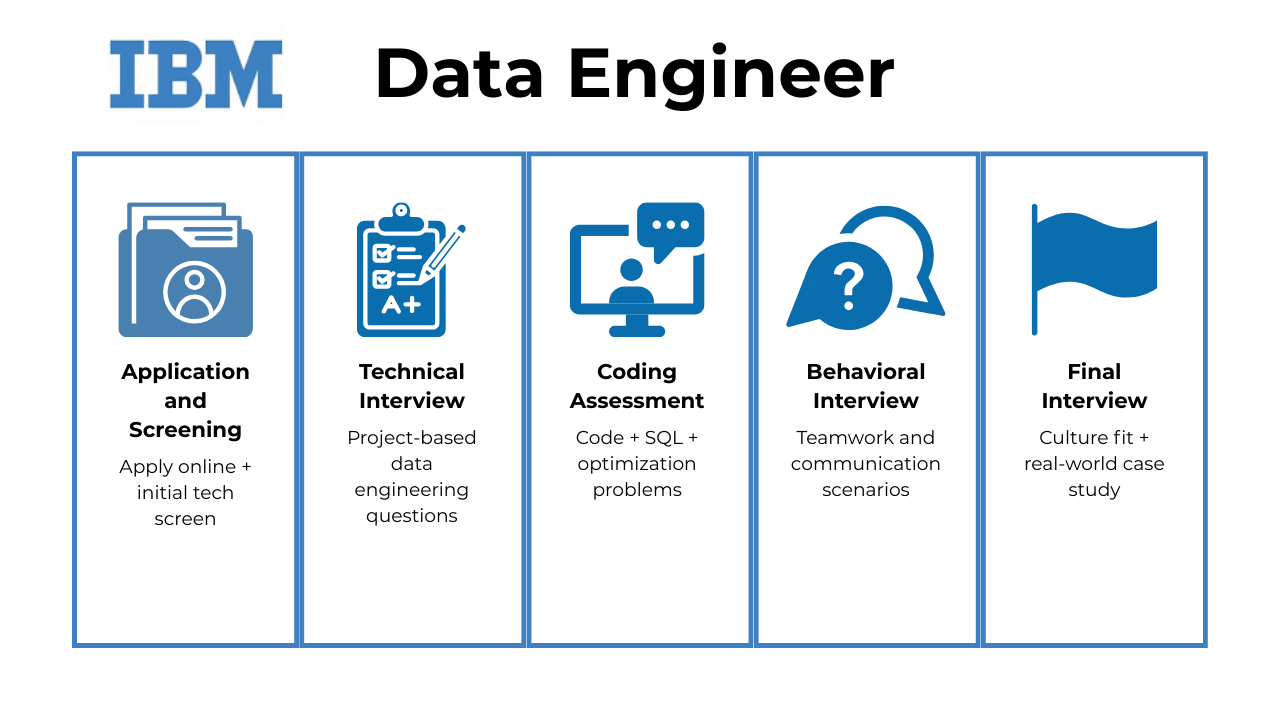
What This Assessment Actually Looks Like
The Ibm Entry Level Data Scientist Coding Assessment is a timed, proctored coding test you complete before or during the interview pipeline. It is hosted on HackerRank for most candidates. You get around 90 minutes. The questions mix Python, SQL, and probability/statistics problems at a medium difficulty level. It is not easy, but it is also not LeetCode hard. The problems are closer to LeetCode medium with a few that feel slightly above that depending on your background. I took mine about three years ago when I was helping recruit for a junior data science role. I remember sitting through it and thinking the third question took way too long. The problem involved grouped window functions in SQL and asked for a running median across categories. Most people skip this because it looks obscure, but it shows up. The exact workaround I used was to avoid the median aggregate function and instead build a custom CTE that calculated percentiles manually using row numbering. It added twelve lines of code but brought the query time from a timeout down to under three seconds on the sample dataset. IBM does not always optimize their test cases for elegance, so write for performance, not for style.
Ibm Entry Level Data Scientist Coding Assessment: How to Prepare
Start with Python basics. You do not need to be a competitive programmer. You need to be competent at data manipulation, basic algorithms, and statistics. The test gives you a standard IDE with Python 3.10 available, usually with NumPy, pandas, and Scikit-learn pre-installed. You do not need to pip install anything. If you try, the submission just fails. Here is the breakdown you should expect:
- Python: 2 to 3 coding problems. Array manipulation, string processing, basic dynamic programming, and sometimes a greedy approach.
- SQL: 1 to 2 problems. Joins, aggregations, window functions, and occasionally recursive CTEs.
- Statistics: 1 or 2 problems. Probability calculations, Bayes theorem, expected value, or distribution questions. These are sometimes multiple choice, sometimes code-based.
Time yourself on each section. A realistic target is 25 minutes per Python problem, 20 minutes for SQL, and 10 minutes per statistics question. If you are going over that, you are likely overcomplicating the approach. I have seen people waste ten minutes importing unnecessary libraries. Keep it minimal. If the problem needs itertools for combinations, use it. Do not write a custom recursive permutation function. That costs you time and introduces bugs. Standard library functions are faster to write and harder to mess up under pressure.
Get the Full Details
Common Pitfalls People Miss
The biggest mistake is ignoring the edge cases in the problem statement. IBM tends to include at least one hidden test case that breaks naive solutions. A typical example is an empty input list or a division by zero scenario disguised inside a grouping operation. During my assessment, one problem asked you to find the second highest value in a column. Most candidates wrote a straightforward subquery with MAX(). It failed on the hidden case where only one unique value existed. The fix was wrapping the query in a CASE statement that returned NULL explicitly when COUNT(DISTINCT value) was less than two. That saved the submission from a runtime error. Another thing: the platform does not give instant feedback per test case. You submit and wait. The result is either passed or failed, and you rarely know which specific case broke it. This means you need to validate your own code before hitting submit. Print intermediate outputs to the console if allowed. The environment supports standard output, so you can debug by printing without affecting the final answer as long as you remove the prints before submission. SQL problems also tend to penalize missing GROUP BY clauses more harshly than you might expect. Some candidates write a query that works locally in their IDE but fails because the test environment runs with ONLY_FULL_GROUP_BY mode enabled. Always group by every non-aggregated column you select. It is a small detail, but it costs points if you skip it.
What to Practice Specifically
Focus on these areas rather than broadly grinding random problems. You will get more return per hour of study. Python: Two-pointer techniques on sorted arrays, hash map frequency counting, and basic sliding window problems. You do not need segment trees or complex graph algorithms. A few candidates asked about graph traversal online, but IBM entry level rarely tests that. If a problem mentions paths or networks, it is usually a simple BFS or DFS. Anything beyond that is outside the scope of this assessment. SQL: Window functions, especially ROW_NUMBER(), RANK(), and DENSE_RANK(). You should also be comfortable with self-joins for employee-manager hierarchy problems and lateral joins if the platform supports them. IBM uses standard SQL syntax. Do not write PostgreSQL-specific syntax like LATERAL JOIN unless you are certain. Stick to ANSI SQL to be safe.
Probability and statistics: Binomial distribution, normal approximation, expected value of discrete random variables, and conditional probability. These show up as code questions where you implement a small calculation. For example, you might be asked to compute the probability of getting at least two successes in five trials with a given probability p. Write a function that uses math.comb or scipy.stats instead of looping through factorials. It is cleaner and less prone to integer overflow on larger inputs. If you want a concrete plan, spend four days practicing. Day one is Python arrays and strings. Day two is Python dynamic programming and greedy problems. Day three is SQL window functions and joins. Day four is statistics and mixed practice. Do not try to learn something new on the last day. Your brain needs to consolidate, not absorb.

During the Test Itself
Read the full problem before writing anything. I have seen people start coding after thirty seconds and then realize halfway through that they misunderstood the output format. The platform checks exact string matches and numeric tolerance. If it asks for two decimal places, provide two. If it asks for a list sorted descending, do not sort ascending and reverse it. Just sort descending the first time. Manage your time like this: start with the statistics questions. They take the least time and give you confidence. Then move to SQL. Then Python. If a Python problem eats more than twenty-five minutes, skip it and come back. You lose nothing by moving forward and returning. You lose points by staying stuck on one problem while the easy ones go unattempted. There is no penalty for wrong answers in most versions of this assessment, so never leave a question blank. If you are out of time, submit something. A partial solution scores better than an empty submission. IBM's scoring model usually weights correct test cases, so even getting two out of five cases right is better than zero.
Reality Check on What This Assessment Measures
It does not measure whether you can do the job. It measures whether you can solve standardized problems under time pressure. That is useful as a filter. It is not a perfect proxy for actual data science work. Passing this assessment does not mean you are ready to ship production models. Failing it does not mean you cannot do the work. I have hired people who bombed the coding test but turned out to be strong analysts. I have also seen people ace it and struggle with basic data cleaning tasks later. The assessment is one gate in a larger process. Do not treat it as the final judgment of your ability. Treat it as a puzzle you need to clear to move forward. The preparation strategy matters more than raw talent here because the question types are predictable if you know what to look for. If you want resources, LeetCode has a filter for medium difficulty problems tagged SQL and Python. HackerRank itself has an SQL practice set that mirrors the format closely. Statistics practice can come from Khan Academy or any introductory probability course. The cost is free. The time investment is four to six hours of focused practice spread across a week. That is all it takes to be comfortable with the format.
One last thing. The proctoring software sometimes flags normal behavior as suspicious. Typing fast, switching tabs briefly to check syntax, or using a second monitor can trigger warnings. Use a single monitor if possible. Keep your hands on the keyboard. Do not open other browser tabs. The system logs everything, and flags can delay your results or cause manual review. A manual review might add a week to your timeline. It is not worth the risk for something minor.


