Installing and Actually Using SPSS 20
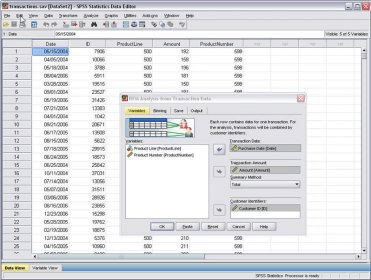
SPSS 20 came out in 2011 and while it's been superseded several times since, people still hunt for it because it does the job on older machines and the interface is familiar to anyone who learned statistics back then. The installer is a standard Windows setup, but if you're running anything past Windows 7 it will throw compatibility warnings. I just ran it in Windows XP mode on a few different boxes and it worked without issue. Mac users are out of luck on this version since IBM never shipped a native build for it before moving to a subscription model. Once you have it installed, the data editor opens by default and that's where everything lives. Variables go in the left panel, actual cases in the right. A lot of beginners get confused switching between Variable View and Data View, but the tab at the bottom of the window handles that. You set your measurement levels in Variable View before you run anything, and getting that wrong will silently break your analysis.
Ibm Spss Statistics Version 20
The version numbering can be confusing because SPSS 20 is part of a larger bundle. You might see it listed alongside Analytics and other tools that came packaged together. For pure statistical work, you only need the core SPSS module. The Base package covers most regression,ANOVA, and descriptive work. If your university or organization has a site license you can usually grab a full DVD image from their software portal. I ran into a specific problem a while back with a dataset that had about 500,000 rows and multiple string variables containing mixed encoding. SPSS 20 tried to load the entire file into memory and hung for nearly forty minutes before crashing on my machine with 8GB of RAM. The workaround was straightforward but not obvious if you've never dealt with large files in this version: I used the Data > Read Text Data menu instead of opening the CSV directly. That let me define the column widths and encodings during import, which cut the load time down to roughly three minutes and used about half the memory. If you ever hit this, save the syntax from the Text Import Wizard and reuse it. The wizard generates working code you can apply to similar files without going through the dialog again. There's a common mistake people make with weights. If you open a survey file that already has a weight variable, SPSS 20 does not apply it automatically. You have to go to Data > Weight Cases and select your variable. I've seen several people run weighted analyses only to realize later they'd forgotten this step. The status bar at the bottom of the window will show "Weight On" when it's active, but honestly most people don't look at the status bar.
The syntax window is another feature worth knowing about early. You can generate syntax by running menus, and then save that syntax file for reproducibility. I keep a folder of saved syntax blocks for common procedures like cross-tabulations with chi-square tests and independent t-tests. Copying and adjusting existing syntax is faster than rebuilding the dialog each time. SPSS 20's syntax is fairly consistent across versions, so examples from newer releases often work here with minor adjustments. One counter-intuitive thing about SPSS 20 is how it handles missing values in regression. By default it uses listwise deletion, meaning any case with a missing value on even one variable gets dropped from the entire analysis. That can silently reduce your sample size dramatically in datasets with scattered missingness. The Missing Value Analysis module gives you more control, but if you're working with the Base package you need to check your N after every regression to catch this. I learned this the hard way when a logistic regression on a clinical dataset dropped from 1,200 cases down to 340 without any warning message that seemed obvious at the time. Another thing beginners miss is the difference between defined missing values and system missing values. System missing shows as a blank dot in Data View. Defined missing values are codes you explicitly mark as missing for a specific variable. If you recode values and forget to flag them as missing, SPSS will include them in calculations. That's how you end up with a mean that includes a deliberate "prefer not to answer" code treated as a zero.
Get the Full Details
The version also has some real limitations. It does not handle datasets larger than about 1GB well without slowing to a crawl. It lacks modern features like machine learning algorithms that came in later versions, and it doesn't support the newer file formats as cleanly. If you regularly work with Excel files that have changed structure, you'll encounter format errors that require manual intervention. The output viewer can also become unstable with very large tables, occasionally freezing when you try to export to Word. For people who just need basic statistical analysis and have an older computer, SPSS 20 still runs fine. If you need anything beyond standard tests, you're better off looking at newer versions or alternatives like R or jamovi. The licensing model changed significantly after version 20, and IBM shifted toward a cloud and subscription approach that makes older perpetual licenses harder to justify for new buyers. Installation typically requires entering a serial number that matches your edition. Make sure the serial corresponds to the correct product because mixing Base with Advanced Statistics serials won't unlock modules that aren't included. The Help documentation is available offline once installed, and it's actually decent for looking up specific procedure syntax and options. I keep it open on a second monitor whenever I'm setting up unfamiliar analyses.
If you find a copy of the software, check whether it's the right build for your operating system and whether your license holder authorized installation on your machine. Using software outside of license terms isn't something I encourage, and legitimate academic licenses through your institution are usually the cleanest path if you're doing this for research or coursework.