Why YouTube Keeps Becoming The Real Data Science University
I stopped relying on traditional tutorials years ago. YouTube shifted first. Channels now publish full project walks — from dirty data ingestion through model deployment — in 40-minute videos that move faster than most blog posts. The problem is not finding them. The problem is separating actual signal from creators reading Medium articles aloud. The trend is real and it is messy. You will see a video titled something like "Build a Production-Grade ML Pipeline in 30 Minutes" and discover the speaker skipped preprocessing, ignored train-test leakage, and never bothered to version their dataset. This happens constantly. The workaround is simple: open the repo they link in the description, clone it, run it yourself before trusting anything they demonstrated on screen. If the code does not run in under 10 minutes on a standard machine, walk away from that tutorial immediately. What actually works for filtering signal from noise is checking the comment section for people posting their own errors. When five or more commenters hit the same dependency hell — usually around TensorFlow versus PyTorch version mismatches, or scikit-learn breaking changes between minor releases — you know the tutorial is outdated. The author probably filmed it six months ago and has zero intention of updating it. The video still gets pushed to your feed because engagement is up from people complaining in the comments.
I ran into a particularly frustrating edge case last year. A trending video on time-series forecasting claimed a custom LSTM architecture outperformed Prophet on a retail demand dataset. The author provided the full notebook, so I downloaded it. The dataset was a synthetic copy of something scraped from Kaggle, but the train-test split was done chronologically without any look-ahead bias check. More importantly, the video never mentioned that the model required 48 GB of GPU memory to even load the data. I spent three hours debugging a CUDA OOM error before realizing the entire walkthrough assumed access to a cloud instance nobody mentioned in the description. The workaround was switching to a simpler seasonal decomposition approach using statsmodels, which fit on my laptop and produced results within the same accuracy range. The trending video got 200,000 views. My solution got eight likes on a forum thread. This is the core problem with the current YouTube data science landscape. Virality rewards spectacle, not correctness. A flashy dashboard with animated graphs will consistently outrank a three-hour deep dive into proper cross-validation strategy. You have to learn to hunt deliberately rather than watch whatever the algorithm surfaces.
How to Actually Extract Useful Ideas From Trending Content
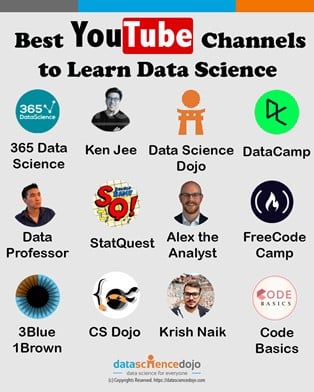
The first thing I do is mute the video and read the description. Any creator who cannot summarize their own methodology in two paragraphs is probably hoping you will not notice the gaps. Then I scan the pinned comment. That is where people post the most useful corrections, alternative implementations, and warnings about what went wrong. Sometimes the pinned comment alone is worth more than the entire video. I also track specific channels that consistently demonstrate reproducibility. People like StatQuest, Ken Jee, and Coding Train maintain an actual standard. Their videos include the raw data links, the exact package versions in requirements.txt files, and honest discussions of where each method fails. You will rarely see them hit a million views on a single upload, but their content does not rot after a software update. The rest of the trending space operates differently. A video about the latest open-source LLM framework will trend aggressively for exactly fourteen days, then become permanent misinformation as the ecosystem moves forward. Here is a practical workflow I use when I want to extract working ideas without wasting an afternoon. First, I search YouTube using specific technical queries rather than broad ones. "Pandas merge vs join performance benchmark" yields very different results than "data science tutorials." The former pulls from people who actually ran benchmarks. The latter pulls from people who read a headline. Second, I filter by upload date and sort by view count within the last thirty days. This captures what is trending right now without surfacing recycled content from two years ago that still ranks well in search.
Get the Full Details

Third, I open the top three results and watch only the first two minutes. If the speaker cannot clearly state the problem they are solving within that window, the rest of the video is almost certainly filler. People who know what they are doing say it upfront. People who do not spend three minutes building false credibility. I check the repository link if one exists. I look at the commit history. A repo with one commit from three weeks ago and zero issues is either freshly published or abandoned. Both states require caution. The most useful technique I discovered comes from watching how certain creators structure their project repositories. They include a README with setup instructions, a data folder with a sample subset, and a separate environment.yml file. This level of documentation takes genuine effort. Most trending data science videos skip it entirely. When you find someone who includes it, bookmark their channel. Those people are rare and they stay relevant longer.
Common Pitfalls That Waste More Time Than Anything Else
The biggest trap is copying code without understanding the data shape. I watched a creator build a recommendation engine using cosine similarity on a sparse matrix, then praise the results without ever checking whether the similarity scores were actually meaningful. The model produced outputs, which convinced most viewers that the approach worked. It did not. A proper evaluation would have required a held-out test set and a baseline comparison. Neither existed in the video. Another pitfall involves tool obsession. YouTube trends heavily favor whatever new library launched in the past quarter. LangChain had a massive run. LlamaIndex followed. Each one promised to solve problems that pandas and simple API calls already handled. The problem is that tutorials built around these tools often demonstrate a proof of concept rather than a production system. The difference matters enormously if you are actually trying to ship something. I spent about six weeks last year rebuilding a pipeline that originally used an overengineered framework, replacing it with straightforward requests calls and a SQLite database. The new version runs faster, costs less to maintain, and breaks fewer things. There is also the false signal of view counts. A video with 500,000 views and zero substantive comments is either entertainment or sponsored content. Check the description for sponsorship disclosures. Many data science channels now accept payments from cloud providers to feature specific platforms. This is not inherently bad, but it changes the incentive structure. The creator is no longer optimizing for accuracy. They are optimizing for platform exposure. You will notice patterns — sudden shifts in recommended tools, unfamiliar branding in screenshots, and methodologies that work only on the sponsored platform.
A Few Counter-Intuitive Truths About Learning Data Science From Video
Longer videos are not automatically better. A two-hour recorded workshop often contains more usable information than a tightly edited twenty-minute trend video, but most people cannot sit through the runtime. The signal density per minute is actually higher in shorter content when the creator respects your time. The problem is that shorter videos compress complexity to the point of inaccuracy. A ten-minute video on gradient boosting will show you the API call and the final metric. It will omit the feature engineering decisions, the hyperparameter search strategy, and the reason the model failed on the second dataset. Both formats have real limitations. Another truth that nobody wants to admit: watching data science content builds a false sense of competence. Your brain recognizes the solution pattern and mistakes familiarity for mastery. This is the most common failure mode I see among people who consume YouTube tutorials as their primary learning channel. The fix is uncomfortable but effective. Pause the video at every major decision point and implement the next step yourself without looking at the solution. If you get stuck, that is the exact moment you learn something. Skipping ahead to see how the creator solved it defeats the entire purpose. I also recommend keeping a separate notes document where you rewrite each tutorial in your own words after watching it. Not copy-paste the code. Rewrite the explanation. If you cannot explain why a particular preprocessing step matters in plain language, you did not understand it. This habit took me about four hours per video instead of the usual forty minutes, but it dramatically reduced the number of times I repeated the same mistakes in actual projects.
What to Do When Trending Content Is Wrong
Sometimes the trending video contains a fundamental error in the methodology itself. The creator might be using mean imputation on a dataset with heavy skew, applying standardization before a tree-based model, or evaluating classification performance with accuracy on an imbalanced dataset. These mistakes are so common in trending content that I have stopped being surprised by them. The workaround is to find the original paper or documentation that contradicts the video claim, read the relevant section, and form your own opinion. Academic papers on arXiv are often more reliable than the most popular YouTube explanation of the same concept. When the error is subtle — something like a data leakage issue that only appears under specific conditions — the video might still produce decent-looking results on the demonstrated example while failing catastrophically in production. This is the hardest category to identify. You usually only discover it after deploying the model and watching performance degrade over time. I learned this the hard way with a churn prediction model that looked solid in testing but collapsed once it encountered real user behavior patterns. The issue was that the training data included features that would not have been available at prediction time. The YouTube tutorial never mentioned this constraint. The best defense against all of these issues is building a small personal validation framework. Before adopting any technique from a trending video, run it against a dataset you already understand well enough to predict the correct outcome. If the new method produces obviously wrong results on familiar data, something is broken. This usually takes about twenty minutes and saves hours of downstream debugging. I keep a standard dataset — a cleaned version of the UCI Mushroom dataset — specifically for this purpose. It has clear class separation and well-documented features, making it easy to spot when a tutorial introduces an error.
YouTube is not going away as a learning resource. The volume of data science content being published daily is genuinely staggering. The quality variance is the real issue. Most of it is mediocre. A small fraction is excellent. Learning to navigate between those two extremes without wasting time on content that looks useful but delivers nothing is the actual skill here.


